home-ops lets Flux walk apps/ and stops at the topmost kustomization
Wife approved HomeOps driven by Kubernetes and GitOps using Flux
At a glance
- What is it?
- home-ops is a mono repository for one home Kubernetes cluster, running on Talos and reconciled by Flux, with Renovate opening the pull requests and GitHub Actions running inside the cluster itself. The reconciliation rule is one sentence long, the dependency graph lives in the manifests, and the network diagram is a collapsed block with nothing inside it.
- Who is it for?
- home-ops is worth reading if you run a cluster at home and want the reconciliation rule to be one sentence rather than a pipeline, and worth copying only if your storage layout matches the author's. Three things to check before adopting the shape.
- Can I use it commercially?
- Yes. WTFPL is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly YAML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 22, 2026, and from our analysis. They are not legal advice.
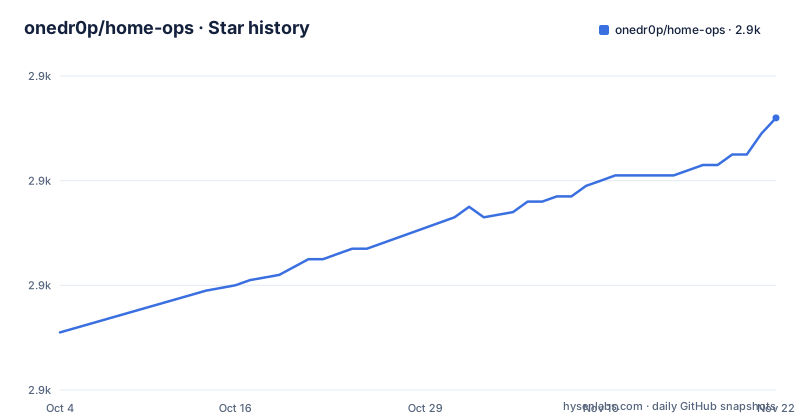
Star history
- onedr0p/home-ops2,932 ★ · +41
| Repository | 2026-10-04 | 2026-11-22 |
|---|---|---|
| onedr0p/home-ops | 2.9k | 2.9k |
41 Stars in the last 49 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Flux walks apps/ recursively and stops at the topmost file
The reconciliation rule is described in one sentence and it is the part worth memorising. Flux watches the kubernetes folder, recursively searches the apps folder until it finds the most top level kustomization.yaml per directory, and then applies all the resources listed in it.
So the directory tree is the deployment graph. A folder that contains its own kustomization.yaml is a boundary, and a folder without one inherits the boundary above it. Moving a manifest one directory up or down therefore changes what Flux applies, which is the kind of coupling worth knowing before reorganising a tree.
Inside each of those files the page says there will generally only be a namespace resource and one or many Flux kustomizations, the kind of file it abbreviates as ks.yaml. Under the control of those sit HelmRelease objects or other resources related to the application, which are what actually end up in the cluster.
The three-directory layout is short enough to read in one glance: apps for applications, components for re-usable kustomize components, and flux for the flux system configuration itself. The components directory is what makes the tree scale, since shared definitions live once and are referenced rather than copied into each app.
The deployment order lives in the manifests, not in a runbook
Dependencies between applications are expressed as depends-on relationships inside the manifests rather than as a documented install sequence. The page describes the three shapes that occur: in most cases a Helm release depends on other Helm releases, in other cases a Kustomization depends on other Kustomizations, and in rare situations an app depends on a Helm release and a Kustomization together.
The worked example is about storage. A Kustomization creates a Helm release for the Rook operator and another for the Ceph cluster itself, and the cluster release depends on the operator release. A second application, atuin, is created by its own Kustomization and depends on the Ceph cluster release being either installed or in a healthy state. The stated consequence is that atuin is neither deployed nor upgraded until that condition holds.
That is the difference between a home cluster configured by hand and one configured by Git. There is no ordering document to keep in sync with reality, because the ordering is itself a set of objects that get reconciled, and a broken dependency shows up as a resource that stays pending rather than as a mistake in a checklist.
A network diagram and four core components
The README includes a high-level network diagram inside an expandable details block. Its component list names four parts of the networking stack. Cilium provides eBPF based networking. Istio powers service to service communication with layer 7 proxying and traffic management. Cloudflared secures ingress traffic through Cloudflare. External DNS keeps DNS records in sync automatically.
Running a CNI and a service mesh at the same time is an unusual combination rather than a contradiction: one operates at the packet and connection level, the other adds proxies and routing policy for services. It also means two control planes with two sets of policies to reason about, which is exactly the sort of thing a network diagram would normally explain.
The ingress path is the part that reaches outside the cluster. Cloudflare sits in front of it, and the cloud dependency section says Cloudflare Tunnels could be swapped for many other options, naming one project as an example.
Cloud services are there for the bus factor, not for compute
Most of the infrastructure is self-hosted, and the page is explicit that the cloud is used deliberately for a few key parts rather than as a fallback. Three reasons are given, and they are worth reading in order.
The first is chicken and egg scenarios: the things needed to bootstrap a cluster cannot live only inside the cluster. The second is services that are critically needed whether the cluster is online or not. The third is the one phrased as a hit by a bus factor: what happens to the critical applications the family relies on, with email, a password manager and photos named as examples, when the person who runs it is no longer around.
The alternative considered is running a second Kubernetes cluster in the cloud and hosting the same applications there, with a HashiCorp vault, Vaultwarden, a notification service and a status page named as candidates. It was rejected on cost and effort grounds: maintaining another cluster and monitoring another group of workloads would be more work and probably come out to the same cost or more.
So the cloud bill buys continuity rather than capacity, and the named services are the ones that have to keep working when the hardware does not.
The cloud services and their stated costs
The cloud dependency section ends in a table of service, use and annual cost. The listed services include 1Password for secrets at about $65 per year, Cloudflare for the domain and object storage at about $50 per year, and Migadu email at about $20 per year. The table also lists GCP and GitHub as free, Pushover at a $5 one-time payment, and an approximate total of $10 per month. Costs and plans can change, so check current prices.
The two readable rows line up with the two things the rest of the page insists on. The password manager is the source the external secrets operator reads from, which is what makes secrets survive a cluster rebuild and be readable by someone who is not the owner. Cloudflare is the domain, the tunnel ingress and the object storage, which is also where the backup copies can live outside the house.
So the cost is buying two specific properties: a place secrets come from that is not the cluster, and a place to reach the cluster and to store data that is not the cluster.
A semi-hyper-converged cluster with a separate ZFS box
The cluster is deployed with Talos, and its shape is described as semi-hyper-converged: workloads and block storage share the same available resources on the nodes.
That single phrase describes both the appeal and the cost. One set of machines serves everything, which is what makes a home lab affordable, and the same machines serve the storage, which means a storage workload can compete with an application for the same memory, CPU and input output.
The escape hatch is a second machine. There is a separate server running ZFS, and it handles NFS and SMB shares, bulk file storage and backups. So the expensive-to-replace data lives on a different box from the workloads that read it, and the shared folder protocol is served by the filesystem the page names rather than by the storage operator running inside the cluster.
It is a deliberate split of roles: ephemeral and block workloads on the cluster, shared and bulk data plus backups on the ZFS server. The cost of that split is a second system to maintain, and the benefit is that restoring from backup does not require the cluster to be healthy first.
The CI runners run inside the cluster they build
One line in the component list is worth isolating: an actions runner controller runs self-hosted GitHub Actions runners directly in the cluster, for continuous integration workflows.
Put that next to the update loop and the shape of the whole system becomes visible. Renovate watches the entire repository for dependency updates and opens a pull request automatically. A human merges it. Flux then applies the change to the cluster. The workflow that validates those changes runs on a runner inside the same cluster those changes are being applied to.
The loop is short and everything in it is in one place, which is convenient until the cluster is the thing that is broken, at which point the continuous integration stops at the same moment as the thing it was checking. The page does not describe any off-cluster runner or a fallback, and the badge row links to the renovate workflow file rather than to a test workflow, which suggests the automated pull requests are the visible part of the automation.
Storage has the same shape. A distributed storage operator provides persistent volumes, a tool from the same community organisation handles backups and restores, and a stateless cluster-local mirror of container images is run to improve reliability.
A justfile, lefthook, mise and two formatters sit at the root
The dotfiles at the repository root describe a fairly complete toolchain for a cluster repository. There is a justfile, which is a command runner, and a lefthook configuration for git hooks. There is a mise directory, which is how tool versions are pinned per project. There is a shellcheck configuration and a YAML language server configuration, so both a shell linter and an editor understand the manifests.
Then there are two formatters and one linter that are not the usual choices in a Kubernetes repository: an oxfmt configuration for formatting and a kritika configuration for linting YAML, plus a minijinja configuration for templating. The Renovate configuration is written in JSON5 rather than plain JSON.
None of that is explained on the page. What it tells you is that this repository is not only manifests: there are shell scripts to check, templates to render and a formatter with opinions, and the tools to do each of those are pinned in the repository rather than assumed on the machine.
The content itself is three directories. bootstrap holds the first-run material, kubernetes holds the cluster definitions described above, and talos holds the machine configuration the cluster is built on. The description of the repository is a joke that names its own licence, and the licence is the WTFPL.
Editorial conclusion
home-ops is worth reading if you run a cluster at home and want the reconciliation rule to be one sentence rather than a pipeline, and worth copying only if your storage layout matches the author's. Three things to check before adopting the shape. The applications directory is walked recursively until the topmost kustomization.yaml in each branch, so directory nesting is meaningful and moving a file can change what is applied. The CI runners live inside the cluster they build, which means a cluster outage also stops its own continuous integration. And two dependencies are paid for and two are named as replaceable, so the monthly bill is part of the architecture rather than an afterthought. Read the licence file before reusing anything, since the repository is under the WTFPL and its description is a joke about that name.
Frequently asked questions
What is onedr0p's home-ops repository?
It is a mono repository for one home infrastructure and Kubernetes cluster, following infrastructure as code and GitOps practices with Ansible, Terraform, Kubernetes, Flux, Renovate and GitHub Actions. The cluster runs on Talos and the project is licensed under the WTFPL.
How does Flux decide what to apply in home-ops?
It recursively searches the apps folder under kubernetes until it finds the most top level kustomization.yaml per directory, then applies all resources listed in it. Those files generally contain a namespace resource and one or many Flux kustomizations, abbreviated ks.yaml, under which HelmRelease objects and other resources sit.
Why does this home-ops setup pay for cloud services?
For three stated reasons: avoiding chicken and egg bootstrap problems, keeping services that are needed whether or not the cluster is online, and covering the hit by a bus factor for apps the family relies on. The alternative of a second cloud cluster hosting a vault, a password manager, a notification service and a status page was rejected as more work at about the same cost.
Which components handle storage and backups in this cluster?
Rook provides distributed storage for persistent volumes, a tool from the same community handles backups and restores, and Spegel runs a stateless cluster-local mirror of container images. A separate server with ZFS handles NFS and SMB shares, bulk file storage and backups.
Where can I see the network diagram for this cluster?
Not on this page. The networking section is a collapsed block whose summary offers the high-level network diagram and whose body is empty. The components themselves are named instead: Cilium for eBPF based networking, Istio for layer 7 service communication, Cloudflared for ingress through Cloudflare, and external DNS for keeping records in sync.
How do I start a cluster following these practices?
The page points at a separate template repository, onedr0p/cluster-template, to follow along with the same practices. This repository is the author's own cluster, described as semi-hyper-converged with workloads and block storage sharing the same node resources.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/onedr0p-home-ops)Star history chart for your README
[](https://hysenlabs.com/projects/onedr0p-home-ops)Was this useful?