unblob extracts 78+ container formats, and its Python API and command line name the same options differently
Extract files from any kind of container formats. unblob Accurate, fast, and easy-to-use extraction suite for binary blobs. unblob parses unknown binary blobs for 78+ archive, compression, and file-system formats**, extracts their content recursively, and carves out unknown chunks.
At a glance
- What is it?
- A firmware analysis suite from ONEKEY that parses unknown binary blobs, recurses into containers and carves out unrecognised chunks. Two things the documentation does not smooth over: the pip install route leaves you without the external extractors it shells out to, and the option names in the Python API do not match the flags on the command line.
- Who is it for?
- unblob is the right tool when you have a firmware image of unknown composition and want a readable tree plus a JSON report instead of a guess at the format, and it earns its keep on formats where a single magic number would have sent you down the wrong path. Four checks before you commit to it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
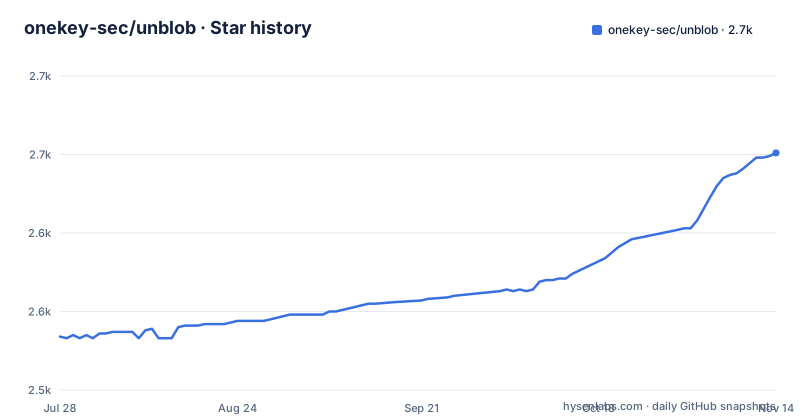
Star history
- onekey-sec/unblob2,651 ★ · +117
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| onekey-sec/unblob | 2.5k | 2.7k |
117 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository description repeats the name three times and leaves bold markers unclosed
The project blurb is three sentences that read like a summary field, a tagline and a feature list were concatenated without anyone trimming the joins. It opens with Extract files from any kind of container formats. It restates the same claim with the word unblob in front of a tagline about being an accurate, fast and easy-to-use extraction suite. It then begins a third time, saying that unblob parses unknown binary blobs for 78+ formats, and a pair of unclosed bold markers is left sitting in the middle of that last sentence, right after the words file-system formats.
So the description carries the project's name three times and an unpaired emphasis marker. That is what shows up in a search result, in a package listing and in any tooling that reads the field, which makes it worth knowing when you are the one looking for this tool rather than the one publishing it.
The rest of the metadata is conventional: MIT licensed, Python as the primary language, documentation at unblob.org, and a version series that reads as year, month and patch, with 26.6.4 the most recent release and the same string in `pyproject.toml`.
Five install routes, and the pip one leaves you without extractors
The pip route is described as recommended for most users and is a single line:
pip install unblobIt is immediately followed by the catch. On Ubuntu and Debian the external extractor tools have to be installed separately, and the list runs to nine packages:
sudo apt install android-sdk-libsparse-utils e2fsprogs p7zip-full unar zlib1g-dev liblzo2-dev lzop lziprecover libhyperscan-dev zstd lz4SquashFS needs one more, fetched as a Debian package from a release URL and then removed after installation:
curl -L -o sasquatch_1.0.deb "https://github.com/onekey-sec/sasquatch/releases/download/sasquatch-v4.5.1-6/sasquatch_1.0_$(dpkg --print-architecture).deb"
sudo dpkg -i sasquatch_1.0.deb && rm sasquatch_1.0.deb
There is a verification command for all of this, `unblob --show-external-dependencies`, which is also the last line of the source install route. The Docker image is the only one that bundles everything. Kali gets a single `sudo apt install unblob`, Nix users get `nix profile install nixpkgs#unblob`, and a source build needs Python 3.10 or newer, uv and a Rust toolchain.
The Python API renames nearly every option the command line exposes
The API is a two-function surface, and it reads like this:
from pathlib import Path
from unblob.processing import ExtractionConfig, process_file

config = ExtractionConfig(
    extract_root=Path("/tmp/output"),
    randomness_depth=1,
)

result = process_file(config, Path("firmware.bin"))
Compare that against the command line. `-e` or `--extract-dir` becomes `extract_root`. `-d` or `--depth` becomes `max_depth`. `-n` or `--entropy-depth` becomes `randomness_depth`, which is the one that will make you stop: the flag says entropy and the field says randomness. `-S` or `--skip-magic` becomes `skip_magic`, `-p` or `--process-num` becomes `process_num`, and `-f` or `--force` becomes `force_extract`.
The API also offers `keep_extracted_chunks`, which has no counterpart in the published flag list, so the two surfaces are not the same size either. Any code you write against one of them does not port to the other by renaming variables.
The Rust workspace is pinned at 0.0.0 and is explicitly never published
The repository is two build systems with two version identities. The Python side is `pyproject.toml` at version 26.6.4 with `requires-python = ">=3.10"` and a console script `unblob = "unblob.cli:main"`. The Rust side is a Cargo workspace whose only member is `rust`, and whose shared package metadata declares `version = "0.0.0"`, `publish = false`, `edition = "2021"` and `rust-version = "1.82.0"`.
A version of zero and a publish flag of false together say the compiled extensions are an implementation detail rather than a distribution. There is no crate to depend on and no crate version to report in a bug, so the version anyone quotes about the Rust half is the placeholder.
The supporting files follow from the same arrangement: `Cargo.lock`, `rust-toolchain.toml`, a `deny.toml` for dependency and licence admission on the Rust side, and a top-level `fuzzing/` directory. A hybrid tool with a Python front end and compiled extensions needs both a lock file and a toolchain pin, and this one has both.
The fuzzing dependency is excluded by a marker the Docker image cannot satisfy
In `pyproject.toml`, the fuzz group holds one entry, and it is conditional rather than plain:
`atheris>=2.3,<3.0; sys_platform == 'linux' and python_version < '3.12'`
The marker restricts it to Linux and to Python below 3.12. The published container starts from `python:3.14-slim-bookworm`, where that condition is false, so the fuzzing harness cannot be installed in the image the project ships. The `dev` group includes the `fuzz` group, so a developer syncing dev dependencies on Python 3.12 or newer gets everything except that, quietly.
The same file shows how precisely other things are pinned. `ruff==0.16.9` and `mkdocs-material==9.7.7` are pinned to an exact patch while almost everything else is a range, and one dependency carries a comment explaining its exclusion: `lz4>=4.3.2,!=4.4.3`, because that release has no aarch64 wheels. A toolchain with an architecture gap and a Python gap, both documented in place.
The image installs a compiler for lzfse, then purges it in the same layer
The Dockerfile starts from `python:3.14-slim-bookworm`, creates `/data/input` and `/data/output`, adds an `unblob` user and chowns the data directories to it. It then enables Debian backports, and the comment says why: required to get the upx package. Dependency installation is delegated entirely to `install-deps.sh`.
The most interesting layer is the wheel install. A comment records that a build must be done first to have the wheel available, since the CI action does it during the image build, which means a local `docker build` without a prior wheel fails here rather than earlier. Another comment explains that lzfse has no CPython 3.14 wheel, so pip has to compile it from source. The layer therefore installs gcc and libc6-dev, installs the wheel with `--prefix /usr/local`, then purges both packages with `--auto-remove` and deletes `/var/lib/apt/lists`.
The last two lines are `USER unblob` and an entrypoint of `unblob`. That non-root user is the reason the documentation warns that mounted directories must be owned by the same uid and gid, and suggests adding `-u $UID:$GID` on multi-user systems. Extracted files belong to the container user, and the host has to agree.
Six Nix files, a semgrep directory and a vulture whitelist sit beside the package
The top level is a good map of how the project is policed. Six files cover Nix: `flake.nix`, `flake.lock`, `default.nix`, `shell.nix`, `overlay.nix` and `package.nix`, which is a lot of surface for one tool and matches the four installation routes offered to Nix users. `mkdocs.yml` and `docs/` are the documentation site, `.pre-commit-config.yaml` and `renovate.json` are the automation, `.taplo.toml` formats TOML files, `.semgrep/` carries static analysis rules, and `vulture_whitelist.py` is the allowlist that keeps the dead-code checker quiet about names it cannot see used.
Two smaller signals are worth noting. `.envrc` means the repository expects direnv for shell setup, and the Python package itself lives in a top-level `python/` directory rather than the `src/` layout most tools default to. There is also a `NOTICE` file beside the `LICENSE`, plus `SECURITY.md` and `CODE_OF_CONDUCT.md`.
For a tool whose job is to open files that other software produced, having both a security policy and a semgrep ruleset in the repository is a reasonable posture to run it under.
Editorial conclusion
unblob is the right tool when you have a firmware image of unknown composition and want a readable tree plus a JSON report instead of a guess at the format, and it earns its keep on formats where a single magic number would have sent you down the wrong path. Four checks before you commit to it. Decide how you will install it early, because the pip route is not self-contained and the Docker image is the only one that arrives complete; on a workstation you will end up installing nine system packages and a Debian package pulled from a release URL. Read the CLI reference rather than the feature list before writing a script, and note that the Python API renames almost every option. Set the recursion depth deliberately instead of leaving it at ten levels, since the default is generous enough to be slow on a large image. And if you intend to fuzz your own handlers, do that outside the published container, because the fuzzing dependency is excluded there by a version marker. For archives you already know the format of, a plain extractor is less work.
Frequently asked questions
How do I install unblob?
Five routes are offered: `pip install unblob` followed by the external extractor packages, the Docker image which bundles everything, `sudo apt install unblob` on Kali, `nix profile install nixpkgs#unblob`, or a source build with `uv sync --no-dev`. The pip route alone leaves the extractors missing, and `unblob --show-external-dependencies` reports what is absent.
What is unblob actually used for?
It parses unknown binary blobs for 78+ archive, compression and file-system formats, extracts their contents recursively up to a configurable depth that defaults to 10 levels, and carves out data matching no known format while identifying null and `0xFF` padding. Unknown chunks additionally get Shannon entropy and chi-square analysis.
Does unblob need root privileges?
No. The feature list states that no elevated privileges are required and that it runs safely as a regular user. The Docker image follows the same rule, creating an `unblob` user and switching to it with `USER unblob`, which is why mounted directories must match the container's uid and gid.
What do the unblob -d and -n options control?
`-d` sets recursion depth and defaults to 10 levels, while `-n` sets entropy calculation depth, defaults to 1, and turns entropy analysis off at 0. Parallelism is `-p`, whose default is the machine's CPU count, and `-f` forces extraction even when outputs already exist.
How do I teach unblob a format it does not know?
Write a custom handler or extractor and load it at runtime with `-P ./myplugins/`, using the development guide for the interfaces. If you would rather not implement it, the contribution steps say to open an issue describing the format with hex dumps, spec links and sample files, and the maintainers state they will consider adding it.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/onekey-sec-unblob)Star history chart for your README
[](https://hysenlabs.com/projects/onekey-sec-unblob)Was this useful?