liboqs builds every algorithm by default, and one row says TBD
C library for prototyping and experimenting with quantum-resistant cryptography
At a glance
- What is it?
- liboqs is a C library of post-quantum key encapsulation and signature implementations behind one API, part of a project that also ships an OpenSSL provider for prototyping them in TLS. Its documentation is the most disciplined thing in this batch: a generated algorithm table with a support tier column, eleven policy files at the root, and hash-pinned Python for the test suite. It also builds everything by default, including the algorithms it marks experimental.
- Who is it for?
- liboqs fits a research or prototyping team that needs to try post-quantum algorithms against real protocols now, and that wants to know which upstream is actually maintaining each one. Two things to check before you build on it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
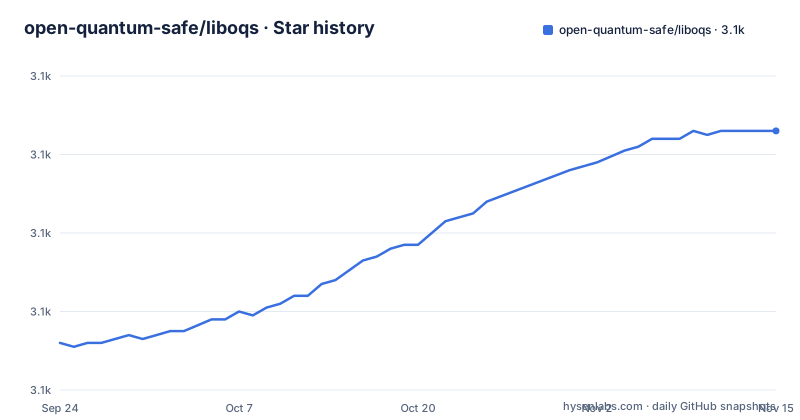
- open-quantum-safe/liboqs3,126 ★ · +54
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| open-quantum-safe/liboqs | 3.1k | 3.1k |
54 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The default build is everything, experimental included
The status section explains the stability policy and then tells you what you get.
Three algorithm names are stable, and the reason is given precisely: they are the ones standardised by NIST, and if NIST changes the implementation details the library will adjust so that users are protected from the change. Every other name is subject to change.
Then this: which algorithms are built can be controlled through a build variable, and by default the library is built supporting every algorithm in the table, including experimental ones.
So the default is the widest possible surface, and the way to narrow it is opt-in. For a library whose distinguishing feature is a table of algorithms under different maintenance regimes, defaulting to all of them means every consumer's build carries the code for schemes at the bottom of the tier list until someone passes a flag.
That is a reasonable default for a prototyping library, which is what the description says this is. It is the wrong default for anything shipping, and the file does say which flag changes it.
A generated table with a support tier column
The algorithm table is the centre of the document and it is not hand-written.
It sits between two comment markers that name it as a template fragment, which means it is generated and cannot silently rot out of date with the build. Each row has five columns: the algorithm family, its standardisation status, its primary implementation, the upstream maintenance state, and the project's own support tier.
That fourth column is the one that makes this table worth reading. Every algorithm here is vendored from somebody else's repository, pinned to a specific commit so that an upstream change cannot alter your build silently. And next to each pin, the table records who is actually maintaining that upstream.
The first row is a cycle candidate: an algorithm not selected by the standardisation body, implemented from a vendor's repository, with the upstream maintenance column reading TBD, and the support tier reading the lowest one, community.
So the honest summary of that row is that the library ships it, the default build compiles it, and nobody has said who will fix it when it breaks.
The rows say plainly what nobody is maintaining
Two more rows are worth reading for the same reason.
One is a code-based scheme under consideration by an international standards body. Its implementation is pinned to a commit in a widely used clean-room repository, and its upstream maintenance column reads, in full, no active maintenance. Its support tier is also the community one.
Another is under standards consideration, implemented from a vendor's repository, with the maintenance column reading best effort, and its tier one step higher: supported.
And a third row records that the scheme was selected by the standardisation body for upcoming standardisation, with its implementation pinned to a commit in the scheme authors' own repository.
Put those three together and you have a taxonomy that is unusual in open source: not just which algorithms are included, but who is on the hook for each one and whether that someone is a standards body, a company, a community or nobody. The tiers appear to be exactly that, with supported above community, and the file links the definition out to a separate document rather than inlining it.
That is the single most useful thing about this project and it costs one column.
Eleven policy files at the root of a C library
Count the documentation files at the top of this repository and you get a number you would not expect from a C library with one API.
There is a document listing every algorithm with its detail, one on how to build and what the build options mean, one on continuous integration, one on supported platforms, one on how to release, one on governance, a code of conduct, a contributing guide, a security policy, a change log, a release notes document and a licence file.
There is also a plain contributors file with no extension, a linter configuration for markdown formatting, a formatter configuration for the C and C++ sources, and a directory of git hooks.
That is the shape of an organisation that treats its documentation as a deliverable. The details are split out rather than merged: per-variant security level, constant-time status and formal verification live in the algorithms document, while upstream sources and advisories live in a directory of per-algorithm pages, so that a reader chasing a specific advisory does not have to read the table.
The markdown linter configuration is the detail I would point at. Eleven documents at the root of a C project is a lot of prose to keep tidy, and somebody installed a tool to keep it tidy.
Hash-pinned Python for a C library's test suite
There are three Python dependency files at the root, which is a surprise in a repository whose product is a compiled library.
The reason is in the header of the pinned one:
# Python dependencies for liboqs
# Install with: pip3 install --require-hashes -r requirements.txt
#
# Generated by: pip-compile --generate-hashes requirements.in
# These are required for running the test suite and build tooling.
So the test harness is installed from a fully hash-pinned list, generated by a compiler tool from a loose input file. Every package has its version fixed and two or three accepted hashes, so a mirror serving different bytes for the same version fails the install instead of being trusted.
That is the same discipline applied to a build most people would not think about. The project is a prototype library whose test suite drives the implementations, so the tests are load-bearing, and a suite that silently runs against different Python packages than the one it was written for is a library that reproduces its own bugs.
The third file is a separate pinned list for a linter, kept apart from the test dependencies so the two can move independently.
The build targets an embedded operating system
The navigation lists three build routes: Linux and Mac, Windows, and cross compilation. Past those, the visible part of the document stops inside the algorithm table, so the limitations section, the rest of the quickstart and the acknowledgements are not in front of me.
What the repository layout does show is the shape of the platform story. There is a C++ directory beside the C source, so language bindings ship in-tree for one ecosystem. There is a platform document at the root, separate from the readme. And there is a directory named after a well-known embedded real-time operating system, which tells you the build is expected to work inside a firmware image rather than only on a desktop.
That last one changes how you read the algorithm table. A library that builds for a microcontroller is not being asked to support a wide platform range for its own sake; the whole point of a post-quantum primitive is that it eventually has to run where the classical alternatives are cheap.
The named limitations sections are what I would want to see first, and their absence here is a gap in this snapshot rather than in the project.
A survey link in the overview, and bindings in one language
Two smaller things sit at opposite ends of the file.
The overview, after explaining what the library provides and which project it belongs to, asks the reader to fill in a community survey, hosted on a survey platform, on behalf of the foundation that supports the project. It frames the survey as wanting to understand the community better, and it asks for input from both organisations and individuals.
A link like that in an overview paragraph is unusual. It is also the clearest signal in the repository about where the project thinks it sits: this is infrastructure being offered to an ecosystem that has not decided whether it wants it yet, and the survey is how they are measuring that.
At the other end, the searches attached to this project are almost entirely for language bindings: Node, JavaScript, Go, Rust, Java, Python, C++. The repository ships C and a C++ directory. Everything else lives somewhere else, and the readme does not say where, which means a developer arriving from a search for a Python or Rust binding has to find the sibling repository themselves.
For a project whose purpose is to be integrated into other people's code, that is the gap worth closing first.
Editorial conclusion
liboqs fits a research or prototyping team that needs to try post-quantum algorithms against real protocols now, and that wants to know which upstream is actually maintaining each one. Two things to check before you build on it. Read the support tier column rather than the algorithm name, because the file is explicit that only the three NIST-standardised names are stable and that everything else may change, while the default build still compiles all of it including the experimental tier. And if you are reaching for a language binding, check which repository it lives in, because this one carries C and a C++ directory while the traffic around the name suggests most users arrive looking for something else.
Frequently asked questions
What is liboqs?
An open source C library of quantum-safe key encapsulation mechanisms and digital signature algorithms, presented behind one common API, together with a test harness and benchmarking routines. It is described as a library for prototyping and experimenting rather than as a production-ready implementation, and it is part of a wider project that also builds an OpenSSL provider.
liboqs vs openssl
They are not alternatives. The wider project builds an OpenSSL 3 provider that plugs post-quantum algorithms into OpenSSL, and prototypes integrations into TLS, X.509 and S/MIME through it. liboqs is the algorithm layer underneath, in C, with its own common API and a test harness.
how to install liboqs
The file has an install section with routes for Linux and Mac, for Windows, and for cross compilation, but its contents are not in the part of the document available here. What is visible is that the Python test dependencies are installed from a hash-pinned list, and that a platform document at the repository root covers supported platforms.
how to use liboqs
No usage example appears in the visible portion of the file. What it does describe is the shape of the library: one common API over many algorithms, a build variable that selects which of them are compiled, and per-algorithm detail in a separate document covering standardisation level, constant-time status, formal verification and available optimisations.
Is TLS 1.3 quantum-safe?
The repository does not answer questions about the transport protocol. What it describes is its own place in that work: an algorithm library, plus a provider that lets a post-quantum algorithm be prototyped inside OpenSSL and therefore inside TLS, X.509 and S/MIME.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/open-quantum-safe-liboqs)Star history chart for your README
[](https://hysenlabs.com/projects/open-quantum-safe-liboqs)Was this useful?