OpenObserve: one Rust binary holding logs, traces, metrics, RUM and LLM calls
Open source observability platform for logs, metrics, traces, frontend monitoring, pipelines and LLM observability. A sophisticated, simple and highly performant alternative to Datadog, Splunk, and Elasticsearch with 140x lower storage costs and single binary deployment.
At a glance
- What is it?
- OpenObserve is an AGPL-3.0 observability platform that puts every signal into Parquet on object storage behind a single binary. This looks at what the default build actually contains, what the Docker quick start hands you, and which claims belong to the project rather than to an independent test.
- Who is it for?
- Adopt OpenObserve if your team already speaks OpenTelemetry and wants one binary to hold logs, metrics, traces, browser sessions and model calls instead of four separate stacks. Do not adopt it expecting parity with the vendors it compares itself to, because the 140x storage figure and the hardware comparison are the project's own claims.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
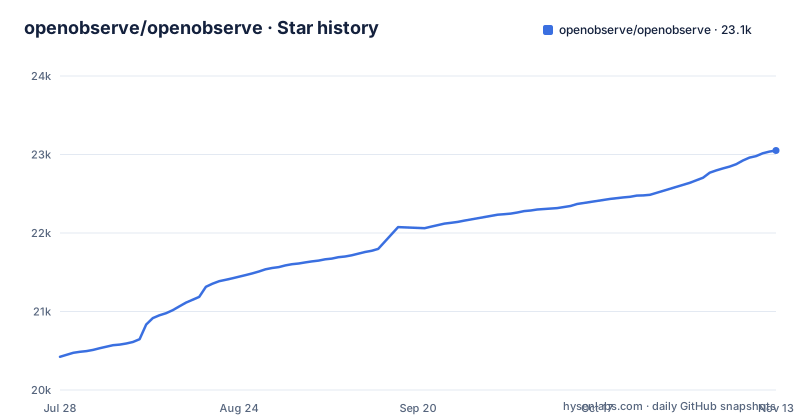
Star history
- openobserve/openobserve23,051 ★ · +2,628
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| openobserve/openobserve | 20.4k | 23.1k |
2,628 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Parquet plus an object store is where the 140x storage claim comes from
The storage argument is the core of the pitch. OpenObserve writes Parquet columnar files and treats object storage as the primary destination rather than a replica, which is what the project's own comparison against Elasticsearch rests on when it claims up to 140x lower storage cost and better query performance on a quarter of the hardware. Those two figures are the maintainers' claims from the README, not measurements you can verify from the source tree, so treat them as marketing that happens to have a mechanism behind it. The mechanism does carry obligations. Because data lands in an S3 bucket, the process on your machine is a query engine over remote objects, and the example environment file ships with ZO_LOCAL_MODE = true and a placeholder bucket name of zinc-dev. A local run and a production run are not the same system, and the local one is the one that makes the product feel fast.
The Docker one-liner publishes a root password in plain text
The fastest path is a container, and it is short enough to paste whole. After it starts, the docs tell you to open http://localhost:5080 and log in with the credentials above, which are also the two defaults in .env.example: ZO_ROOT_USER_EMAIL and ZO_ROOT_USER_PASSWORD set to [email protected] and Complexpass#123. Read the command before running it. The password is published in the project README and in the example env file, so copying it unchanged puts a known administrator credential on port 5080 on every interface Docker exposes. The volume flag mounts a data folder under the host's current directory as /data, so deleting that folder deletes the data, and the image tag is :latest, meaning a fresh pull after an upstream publish can give you a different build. Change the two env values before the first start.
docker run -d \
      --name openobserve \
      -v $PWD/data:/data \
      -p 5080:5080 \
      -e ZO_ROOT_USER_EMAIL="[email protected]" \
      -e ZO_ROOT_USER_PASSWORD="Complexpass#123" \
      public.ecr.aws/zinclabs/openobserve:latest
The example environment file adds four settings you will meet again in production: ZO_MAX_FILE_SIZE_ON_DISK is 32, ZO_FILE_PUSH_INTERVAL is 10, ZO_S3_BUCKET_NAME is the placeholder zinc-dev, and RUST_LOG is info.
Default cargo features are empty, so a source build is not the published build
The manifest is where the real configuration surface hides. Cargo.toml declares default = [], so a plain build enables nothing beyond the crate itself. Everything meaningful sits behind named feature flags. enterprise turns on audit, usage_reporting, super_cluster_queue, enrichment-data and the enterprise halves of the API, core and jobs crates. vectorscan adds the same vectorscan hook across the api-http, api-grpc, core, jobs, search_service and enrichment-data crates, which is the regex engine you want for log searching. cloud is a separate list from enterprise, not a superset. Two allocator choices, mimalloc and jemalloc, sit next to profiling and tokio-console. The consequence for an operator is concrete: a binary you compile from this manifest with no flags has none of these features compiled in, and there is no runtime setting that turns a missing feature on.
Cargo.toml still reads 0.93.0 while the release feed is at v1.1.0-rc1
Version identification is where this project is easiest to get wrong. The default branch manifest carries version = 0.93.0, while the release feed shows v1.1.0 on 2026-10-14, v1.1.1 on 2026-10-16, and v1.1.2 on 2026-10-20, with the last push to the branch on 2026-11-02. Those numbers do not reconcile, so the crate version in the source tree is not a usable way to identify what you are running. Record the release tag you downloaded, not the version string you find in a source checkout. One more detail from the same manifest matters for provenance. publish = false means the crate is never pushed to crates.io, so you get the project from its release artifacts or you build it yourself.
Pipelines transform at ingest, so a bad VRL rule discards data before storage
Pipelines are the most consequential feature for anyone handling logs with anything sensitive in them, because they run before anything is written. The visual editor wires together source, transform and destination nodes, where transform uses VRL functions and conditions, and the stated jobs are enrich, redact, reduce and normalize. The editor also converts logs into metrics as part of the same flow, with no external tooling. What that design implies is the problem. A reduce or redact rule takes effect at ingest, so data removed by a miswritten condition is not stored and therefore cannot be recovered by querying, and the product tour does not describe a dead-letter path or a replay for a flow that dropped events. If you rely on pipelines for compliance redaction, test the flow against a copy of real traffic first, because the failure mode is silent rather than loud.
Session replay and the AI assistant reach data the other signals never see
Two features break out of the usual observability perimeter. Real User Monitoring covers Core Web Vitals, error tracking, performance analytics and full session replay, which records what a user's browser actually did. The product tour lists that capability without describing masking rules, input masking or field redaction for the replay stream, so the redaction story that Pipelines offers for ingest data does not obviously extend to what the browser records. The same section adds an O2 AI Assistant that turns natural-language questions into SQL, VRL and PromQL, running against your logs, traces, metrics and incidents. That is convenient and it is also a new way to read production data, so it belongs in the same access-control conversation as the UI, not outside it. Decide who can query what before you turn either on.
Enterprise is a compile flag, and the license on the OSS path is AGPL-3.0
The repository separates products by feature flag rather than by a runtime license file, and that has consequences for anyone doing supply-chain review. The enterprise feature list names audit and usage_reporting among its members, plus super_cluster_queue and enrichment-data, all gated per crate, while cloud is its own list across the api-http, api-grpc, core and jobs crates. So the same public source tree produces an AGPL-3.0 build with nothing enabled and a build with audit trails and usage reporting compiled in. Alongside the manifest sit deny.toml for dependency policy, clippy.toml, rustfmt.toml and a pinned rust-toolchain.toml, which is the set you want before auditing a build. Read the license as written: AGPL-3.0 governs the code you compile, and the quick start also points at a hosted cloud tier with a free allowance of up to 50 GB per day of ingestion, which is a different arrangement from running the binary yourself.
Editorial conclusion
Adopt OpenObserve if your team already speaks OpenTelemetry and wants one binary to hold logs, metrics, traces, browser sessions and model calls instead of four separate stacks. Do not adopt it expecting parity with the vendors it compares itself to, because the 140x storage figure and the hardware comparison are the project's own claims. Before you commit, check three things: which cargo features your binary was compiled with, since the default set is empty and the enterprise and vectorscan flags are compile-time switches you will not find in a running container; which version you actually have, since Cargo.toml on the default branch still reads 0.93.0 while the release feed is at v1.1.2; and where your object store is, because ZO_LOCAL_MODE = true in the shipped example means the local run you test against is not the S3-backed path the cost argument depends on.
Frequently asked questions
What exactly is OpenObserve?
OpenObserve, abbreviated O2, is a cloud-native observability platform covering logs, metrics, traces, analytics, Real User Monitoring and AI/LLM observability, written with a Rust core and a TypeScript web UI, with Parquet columnar storage on object storage and a single binary deployment.
how to install openobserve
The quickest documented path is a container: run public.ecr.aws/zinclabs/openobserve:latest with a volume mounted at /data, port 5080 mapped to the host, and ZO_ROOT_USER_EMAIL and ZO_ROOT_USER_PASSWORD set, then open http://localhost:5080 and sign in. Other methods, including clustered deployment, are covered in the quickstart documentation.
is openobserve open source
Yes, the repository is licensed AGPL-3.0 and the source is in the open. The Cargo.toml sets publish = false, so the crate is not distributed through crates.io and the binary comes from the project's release artifacts or from a local build.
openobserve vs datadog
The project positions itself as a cheaper Datadog alternative and states up to 140x lower storage cost versus Elasticsearch, single binary deployment in under two minutes, OpenTelemetry-native ingestion with no vendor lock-in, and SQL plus PromQL instead of a proprietary query language. Those comparisons are the project's own claims.
is openobserve free
The self-hosted build is open source under AGPL-3.0 with no license fee stated. The hosted OpenObserve Cloud tier has a free allowance of up to 50 GB per day of ingestion, and the manifest also defines a separate enterprise feature set covering audit and usage reporting.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openobserve-openobserve)Star history chart for your README
[](https://hysenlabs.com/projects/openobserve-openobserve)Was this useful?