rewrite: an Apache badge over a three-tier licensing model
Automated mass refactoring of source code. It consists of an auto-refactoring engine that runs prepackaged, open source refactoring recipes for common framework migrations, security fixes, and stylistic consistency tasks-reducing your coding effort from hours or days to minutes.
At a glance
- What is it?
- OpenRewrite is a mass refactoring engine that runs prepackaged recipes for framework migrations, security fixes and stylistic work, and the repository holds about thirty modules because it parses several languages at several Java language levels. The detail a reader needs first is licensing: the badge says Apache, and the readme says the project is offered under tiers, with the parsers for non-Java languages under a source-available licence and some recipes proprietary.
- Who is it for?
- OpenRewrite fits a Java shop with a migration or a dependency upgrade ahead of it, since the plugin model runs one recipe at a time against one repository and every recipe is meant to be edited. Two things to settle before you plan around it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
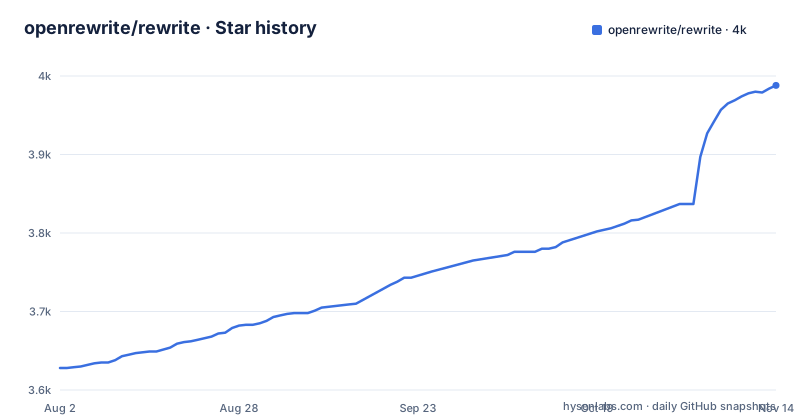
- openrewrite/rewrite3,988 ★ · +360
| Repository | 2026-08-02 | 2026-11-14 |
|---|---|---|
| openrewrite/rewrite | 3.6k | 4k |
360 Stars in the last 104 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One badge, three licence tiers
The licence story is the first thing to read, because the badge at the top only tells you part of it.
The badge links to the Apache licence. The licence file in the repository root is the Apache licence. And then a paragraph near the end of the readme says the project is maintained by a company and is offered under a tiered licensing model, with a documentation link for how the framework, the parsers and the recipes are each licensed.
The second paragraph of that section is more specific. The parsers and base recipes for languages beyond Java are provided under a source-available licence, which the readme says lets you run them against your own code at no cost. Separately, the company offers proprietary recipes for large-scale analysis, security remediation and tool-calling by agents, and those require a commercial licence.
So three tiers: the framework and the Java material under an Apache licence, the other language parsers under a source-available licence that still runs on your code, and a set of recipes you have to buy.
The practical consequence is that "is this free to use" has no single answer. It depends on whether you want the Java engine, a parser for another language, or one of the analysis recipes.
Five Java language levels, and five modules for them
The module list at the repository root is the clearest statement of the engine's design, and one pattern in it explains most of the others.
There are separate modules for Java at language levels eight, eleven, seventeen, twenty-one and twenty-five. Five modules for one language.
That is what you would expect from a parser that claims to be lossless and type-aware: the type model of a codebase changes between language levels, so a parser that pretends otherwise is a parser that gets generics and default methods wrong on some builds.
Around those sit the language modules for Kotlin, Groovy, JavaScript, Python, C#, Go, Ruby, Scala, plus format modules for JSON, YAML, TOML, XML, properties, protobuf and hashicorp configuration language. Then the build-tool and integration modules: a Gradle plugin, a Maven plugin, a Gradle tooling model module, a core module, a test kit, a benchmark module, an Android module, a dependency-management module, and a module for containers.
Thirty-plus modules, and the count is not bloat. It is one module per thing the engine has to model precisely, which is the same reason the recipe catalogue is organised by framework rather than by language.
The core idea is a type-aware tree, rebuilt on every run
One paragraph in the readme explains the architecture, and it explains the pricing model too.
The engine's central structure is a lossless semantic tree: a type-aware model of your source code that is built in memory each time a recipe runs. Recipes operate on that model rather than on text, which is what lets a migration change a call and its imports and its configuration together.
The cost is the same sentence. It is rebuilt every time.
So a single recipe against a single repository pays for a full parse, and a thousand repositories pay for a thousand parses. That is the honest shape of the tool, and the readme is unusually direct about it.
It also frames what the commercial platform does. The company's service builds those trees in bulk, once, and serialises them so they can be reused across repositories and across teams without being rebuilt.
That is the whole argument in two sentences: the open engine is honest about being per-run, and the hosted product is the same engine with the per-run cost amortised.
The local path is one recipe at a time, through a build plugin
How you actually run something is short, and it goes through the build tool you already have.
There is a Gradle plugin and a Maven plugin. Either lets you run one recipe at a time against a single repository, which is the smallest useful unit: a migration you can review as a diff, on a branch, before it meets anybody else's code.
The readme also says recipes are easy to customise, and that you can adapt any of them or write your own. That is the load-bearing claim for adoption. A migration catalogue is only half the value; the other half is that the catalogue is source you own.
The recipes themselves are described as prepackaged and open source, covering common framework migrations, security fixes and stylistic consistency. Three categories, and the middle one is the interesting one for anyone with a dependency advisory: a fix applied consistently across every call site is not something you can do reliably by hand.
The starting point named in the readme is a quickstart guide in the documentation, and the documentation also has a reference page listing supported languages.
Agents get the parsed model instead of the files
The readme devotes a paragraph to coding agents, and it is the same architecture seen from the other side.
The argument runs like this. Because the engine already produces a type-aware model of the code, an agent does not need to reconstruct one by reading files. The same structure gives agents pre-computed context, type-aware search, and direct access to recipes as tool calls that are deterministic rather than guessed.
Three of those tools are named: one for pre-computing context, one for type-aware search, and a local model-context-protocol server so an agent can reach them.
The claim attached is that an agent working this way uses fewer tokens and is more accurate than one reading a codebase file by file. That is a vendor claim in a vendor's readme, and there is no measurement in the document to check it against.
What is checkable is the shape. If the agent calls a search tool that understands types, it will find call sites that a text search cannot, and if it invokes a recipe rather than editing files, the change is the one the engine would have made.
The commercial platform is the same recipes at a different scale
The readme is careful to describe the hosted product as the same engine rather than a different one.
The commercial platform runs the same recipes, across hundreds or thousands of repositories at once. Migrations are described as the common starting point, and the platform expands on that with large-scale impact analysis, security remediation, and the tooling agents use across a whole organisation.
There is also a command line interface for the multi-repository case, described as covering three things: building those trees, running recipes locally, and developing custom recipes across many repositories.
And there is a free public service, offered for the benefit of tens of thousands of open source projects.
So there are three tiers of usage as well as three tiers of licence. A single developer with a build plugin, a team running the command line interface across repositories, and an organisation on the hosted platform are the three shapes the same engine is used in.
The one thing the readme does not offer is a comparison against running the engine yourself at scale, which is the question a team of fifty engineers will actually be asking.
The repository commits IDE settings, vendor configuration and analysis suppressions
The root directory contains a few files that tell you how the project is developed and who configures it.
There is an editor configuration file for whitespace, an IDE properties template, an editor directory, and a directory of run configurations. Committing run configurations is normal for a project with a large integration suite; committing an IDE template is less common.
There is a directory named for the vendor company, which means build configuration for the commercial platform lives in the open repository. For anyone forking, that is a file to look at before wondering why a build does not behave.
There is a file of static-analysis suppressions, a configuration file for a Lombok-based Java tool, a build logic directory for shared Gradle conventions, a workflow definition for continuous integration, and a root configuration file in the engine's own YAML format.
And there is an agent instruction file plus a directory for agent configuration, which is the newest of these and the one that suggests the project expects agents to be contributors as well as users.
An image file at the root is the remaining oddity: nothing in a Gradle build needs a site icon.
Three patch releases in four days
The release line moves fast, and the numbers say by how much.
Three patch releases in four days: the fifteenth of the line on the first of October, the sixteenth on the second, the seventeenth on the fourth. All in the eighty-second minor series of the eighth major version.
That is a daily cadence on a single maintenance line, which tells you two things. The project is actively shipping fixes, and it is doing so without cutting a new minor series, so the version number in your dependency is not going to tell you much about what changed.
The last recorded push to the default branch is dated the first of October, which is the same day as the first of those three tags. So the working tree is above the newest tag, which for a build that consumes this project as a plugin means the version you pin and the code you would get from the branch are not the same thing.
For a tool whose job is to change your code in a way a human then reviews, a daily release line is defensible. It also means the changelog is the only record of what a given pin contains.
Editorial conclusion
OpenRewrite fits a Java shop with a migration or a dependency upgrade ahead of it, since the plugin model runs one recipe at a time against one repository and every recipe is meant to be edited. Two things to settle before you plan around it. Licensing is not one thing: the readme points at a tiered model, so the answer to whether you may use a given parser or recipe in your build depends on which artefact you want, and the non-Java parsers are not on the same footing as the framework. And the engine's core cost is visible in the design: it rebuilds a type-aware model of your code in memory on every run, which is what makes a recipe type-aware and what makes a large run expensive. The commercial platform exists precisely to amortise that, which tells you where the pain is.
Frequently asked questions
What is OpenRewrite?
An open-source automated refactoring engine that runs prepackaged recipes for framework migrations, security fixes and stylistic consistency, with parsers and base recipes for Java, Kotlin, Groovy, JavaScript and TypeScript, Python and C#, plus Gradle and Maven plugins for running one recipe at a time against a single repository.
Is OpenRewrite free to use?
The repository carries the Apache licence, but the readme says the project is offered under a tiered licensing model and points at a page explaining how the framework, the parsers and the recipes are licensed. Parsers and base recipes for languages beyond Java are under a source-available licence that runs against your own code at no cost, and some proprietary recipes require a commercial licence.
Which languages does OpenRewrite support?
The readme names Java, Kotlin, Groovy, JavaScript and TypeScript, Python and C#, and the repository carries a module per language plus separate modules for each supported Java language level from eight through twenty-five.
What is the Lossless Semantic Tree in OpenRewrite?
It is the engine's type-aware model of your source code, built in memory each time a recipe runs. The readme explains that the commercial platform builds those trees in bulk and serialises them so they can be reused across repositories and across teams without rebuilding.
How do I run a recipe with OpenRewrite?
Add the Gradle plugin or the Maven plugin to the project, then run one recipe at a time against a single repository. The readme says recipes are easy to customise, that you can adapt any of them or write your own, and points at a quickstart guide as the starting point.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openrewrite-rewrite)Star history chart for your README
[](https://hysenlabs.com/projects/openrewrite-rewrite)Was this useful?