Ory Keto's code is Apache-2.0 and its CVE patches are behind a commercial licence
The most scalable and customizable permission server on the market. Fix your slow or broken permission system with Google's proven "Zanzibar" approach. Supports ACL, RBAC, and more. Written in Go, cloud native, headless, API-first. Available as a service on Ory Network and for self-hosters.
At a glance
- What is it?
- An authorization server implementing Google's Zanzibar model: a section of the README reserves security releases, service-level agreements and a private registry for paid customers, the quickstart begins by creating an account on the vendor's cloud, access-control policy is written as a TypeScript class, and the module replaces two of its own dependencies with directories in the same tree.
- Who is it for?
- Ory Keto fits a team that wants relationship-based authorization with a policy language rather than a table of roles, and that is willing to read a documentation site rather than a README. Four things to know before you commit.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 72 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
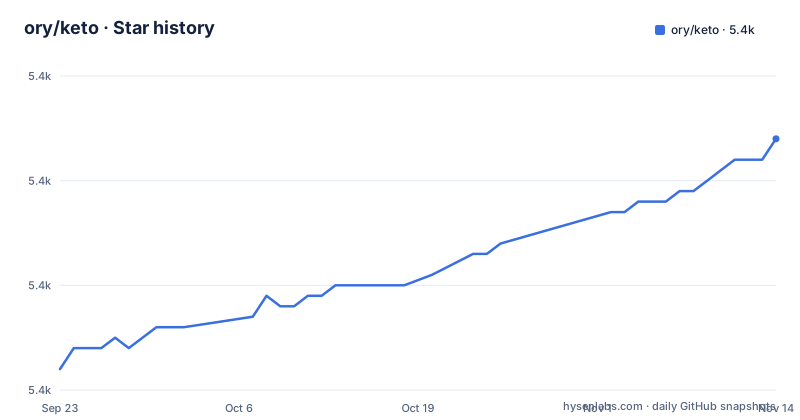
- ory/keto5,424 ★ · +22
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| ory/keto | 5.4k | 5.4k |
22 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The licence is permissive and the security fixes are not
The repository is Apache-2.0. A section of the README is about who gets the patches.
The self-hosting section splits the product in two. The open-source distribution is described as suitable for individuals, researchers and companies running unimportant workloads without service-level agreements, and it says you get the full core engine and are free to inspect, extend and build from source. Then it says that if you run it as part of a business-critical system you should use a commercial agreement to reduce operational and security risk.
Five things are listed as coming with the commercial agreement. Additional enterprise features absent from the open-source version. Regular security releases including CVE patches, with service-level agreements. Support for advanced scaling, multi-tenancy and complex deployments. Premium support with direct access to engineers. And access to a private image registry with frequently vetted, up-to-date builds.
So the open-source build is a complete engine, while guaranteed CVE fixes and current enterprise builds require a valid Ory Enterprise License and access to the Ory Enterprise Docker registry. The tree has a vulnerability scanner configuration and a security policy.
This is a legitimate commercial arrangement and it is stated in plain language rather than buried. It is also the single most important thing to know before running this in production, and it is four paragraphs long in a document whose opening paragraphs are about Google's design.
The hosted service is presented the same way, with a note that the managed offering is powered by the open-source server and is API compatible.
The five-minute quickstart begins by creating an account on the vendor's cloud
The quickstart section has four steps and the first two are about the vendor's hosted product.
The instructions say to install a command-line tool, and the install itself is a piped script followed by a privileged copy:
bash <(curl https://raw.githubusercontent.com/ory/meta/master/install.sh) -b . ory
sudo mv ./ory /usr/local/bin/
Note where the script comes from. It is fetched from a different repository, the organisation's shared tooling repository, not from the one you are reading. And the last step writes into a system directory as root.
The next step is to sign in or sign up, and the one after that creates a project on the hosted service, with a flag that creates a workspace and another that marks the project as the one to use:
ory auth

ory create project --create-workspace "Ory Open Source" --name "GitHub Quickstart" --use-project
So the fast path through the documentation requires an account on somebody's cloud before it writes a single permission. Everything after that point operates on the engine, and the engine is self-hostable, but the tutorial is written for the hosted offering.
The remaining steps are genuinely good. A namespace is written to a file, applied with a patch command, and then relationships are created by piping a compact string through a parser into a create command:
echo "Document:secret#read@tom" \
  | ory parse relation-tuples --format=json - \
  | ory create relation-tuples -
That relationship syntax is the clearest thing in the README: a subject, a relation and an object in one line, with the resource name, the relation and the user separated by punctuation that reads like a URI fragment.
Access-control policy is a TypeScript class
The policy language is not a configuration format, and the minimal example is a source file.
class Document implements Namespace {}One line, written to a file with a TypeScript extension, applied by handing the file to a patch command. The class implements an interface named for a namespace, and an empty implementation is a valid starting point.
So the object that defines what is permitted is a source file rather than a configuration document. That is a real architectural choice rather than a naming convention: namespaces, their types and the relationships between them are expressed in a language the project already uses for a different purpose, and the file is uploaded to a running server.
It also means the policy is a build artefact. A change to a policy is a change to a source file, and the tree reflects that: there is a directory for a namespace type library, a `file:` dependency in the Node manifest pointing at it, and code generation plugins for the protocol buffer toolchain. The README's own feature list calls the language out as one of six things the project focuses on, alongside scalable checks, relationship-based access control, low latency, horizontal scaling and availability.
The numbers in that list are the maintainer's own claims: checks under ten milliseconds, and horizontal scaling to billions of relationships. The repository description goes further and calls it the most scalable and customisable permission server on the market. Nothing here is a measurement, and this overview contains no benchmark to check any of it against.
Two of the module's dependencies are this repository, and two are unmaintained
The module file has two features a reader can only understand by looking closely.
First, there are two replacement directives pointing at directories inside the same tree: one for the project's own generated Go code and one for a shared library from the same organisation. The dependency list then includes both of them, at the all-zeros version that a locally replaced module carries. So two of the module's direct requirements are this repository, and a reader scanning a dependency report for unusual versions will find them.
Second, two of the other direct requirements are early versions: a YAML package pinned at v1.0.0 and an error-wrapping package pinned at v0.9.1, in a module that declares Go 1.26.
For an authorization service, that is worth knowing, and it is the kind of thing a supply-chain scanner is built to find. The tree does contain such a scanner: a vulnerability scanner configuration, a licence-checking tool in the Node manifest, and a security policy.
Two more entries are worth a note rather than a concern. A goroutine leak detector is a direct requirement rather than a test-only one, and a health-check protocol library is pinned to a pseudo-version, which is what an untagged commit produces. The rest of the list is what the description implies: two SQL drivers and a query helper, a cache, HTTP and command-line plumbing, a structured logger, metrics, tracing, and the protocol buffer runtime.
Three scripts are piped out of other repositories during development
One build-adjacent target in this repository fetches a shell script over the network and pipes it into a shell, and another downloads a package at run time.
One regenerates the authors file. The recipe is a curl with seven retries and a retry on refused connections, pointed at a raw file in a third repository, piped into a shell with one environment variable set:
curl --retry 7 --retry-connrefused https://raw.githubusercontent.com/ory/ci/master/authors/authors.sh | env PRODUCT="Ory Keto" bashSo the contributors list is not maintained in this repository. It is produced by a script owned by a different repository, executed over the network, with a retry policy, and the output is committed here.
The second is the formatter. The target reads a version number out of the package manifest with a JSON query tool at parse time, echoes it, and then invokes the formatter through a package runner pinned to that version, which means formatting downloads a package from the registry every time it is not cached.
The third is the installer, covered in the quickstart section above, which comes from a third repository, ory/meta.
The container build is the counter-example: it sets buildkit and content-trust variables and runs from a file in this tree.
One API described three ways, and four alternative stacks beside the default one
The repository answers the same API in three representations, and the tree shows the cost.
There is a protocol buffer definition directory, a generated code directory with its own module, a specification directory, a generated HTTP client directory, and an OpenAPI tooling configuration. The build target for the generated clients runs a specification generator, then a sanitiser from the project's own tool, then a validator, then a second generator step, and it does so with the project name and repository name passed as environment variables.
The server side speaks the protocol buffer protocol directly and also speaks a higher-level RPC framework built on it, with health checking and reflection as separate modules. So a client can use three toolchains against one service.
The deployment side is similarly layered. There are five compose files at the root: the default one, and four more named for a build, for one database, for another database, and for tracing. The default is the one worth reading, because it pins an exact image tag, publishes two ports, binds a configuration file into the container, and passes its path to the serve command. Two published ports for one service is a detail worth noting; a health endpoint and an RPC endpoint on separate ports is a common arrangement and also a second thing listening.
The Node manifest, meanwhile, is a build tool manifest: private, versioned at zero, holding code generators, the table-of-contents generator, a licence checker and a formatter. Its override block is the odd part. Three of the seven entries are floors rather than pins, written as greater-than-or-equal, in a field whose purpose is to force a version.
Three sibling servers, a fuzzer directory, and a telemetry section in the contents
The table of contents in this README is generated, and it has its own instructions above it telling you not to edit it by hand. That is a small thing and it is the only part of the file that says how the file is made.
The contents list has a telemetry section under the security section, so telemetry is a documented feature of the server rather than an afterthought, and the module carries the organisation's own analytics library as a direct dependency.
The ecosystem section is three other servers, each with a one-line description. One handles identity and user management, one is an OAuth2 and OpenID Connect server, and one is an identity and access proxy. This one is the fourth of the four, described as access control policies as a server. The point of listing them is that a deployment can be assembled from the set: the proxy in front, the identity server behind, and this one answering permission questions.
The root is unusually long for a single service, and the entries fall into three groups. There is a fuzzing directory and a benchmark output file, so the project treats input parsing as untrusted and measures something. There is a generated code directory, a shared library directory copied in from elsewhere, an HTTP client generator directory, and a licence file directory. And there are six documents beyond the readme: a change log, a code of conduct, a contributing guide, a development guide, a security policy, and an upgrade guide, plus an authors file that the makefile regenerates from a script in another repository.
One root entry is easy to misread. There is an install script at the top level as well as the piped one in the quickstart, and the quickstart does not use it.
Editorial conclusion
Ory Keto fits a team that wants relationship-based authorization with a policy language rather than a table of roles, and that is willing to read a documentation site rather than a README. Four things to know before you commit. Guaranteed security patches are not part of the open-source build: the README places regular security releases, CVE fixes, service-level agreements and a private image registry behind a commercial licence, and recommends exactly that for a business-critical deployment. The quickstart requires an account on the vendor's cloud, so measure your own path separately. Policy is written as TypeScript and applied through a command-line tool. And the module pins a YAML package at v1.0.0 and an error-wrapping package at v0.9.1, which a dependency review should look at.
Frequently asked questions
what is ory keto
An open source authorization server implementing Google's Zanzibar consistent global authorization model, written in Go, cloud native and API-first. It provides relationship-based access control, a policy language for defining permissions, and claims low latency checks and horizontal scaling to billions of relationships. The code is Apache-2.0 licensed.
Is Ory Keto fully open source?
The code is, and you can self-host the full core engine. The README states that regular security releases including CVE patches, service-level agreements, additional enterprise features and access to a private image registry all come from a commercial licence, and recommends a commercial agreement for a business-critical deployment.
What is the Ory Permission Language?
The language used to define access-control policies. A namespace is written as a class implementing a namespace interface, in a TypeScript file, and applied by handing the file to a patch command. The minimal example in the README is a single class with an empty body.
What can Ory Keto run on?
The install guide covers Linux, macOS, Windows and Docker, with PostgreSQL, MySQL and CockroachDB as databases and Kubernetes as an orchestrator. The repository root ships four compose files beside the default one, for a build, for each of two databases, and for tracing.
How does Ory Keto compare with other authorization systems?
This repository does not answer that. The README recommends its own hosted introduction documentation, which covers a comparison, and its overview does not name a competitor or state a difference. The project's own positioning is a claim about scalability and flexibility with no measurement attached.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ory-keto)Star history chart for your README
[](https://hysenlabs.com/projects/ory-keto)Was this useful?