The Prometheus MCP container binds to every interface while the documented default is localhost
A Model Context Protocol (MCP) server that enables AI agents and LLMs to query and analyze Prometheus metrics through standardized interfaces.
At a glance
- What is it?
- This is a Model Context Protocol server that exposes six tools for querying and discovering metrics in a Prometheus instance, installable six ways including a Helm chart and a container image. The configuration surface is thorough, with four authentication mechanisms and three transports. The one thing worth reading twice is a divergence: the documented bind host default is loopback only, and the container image overrides it to listen on every interface.
- Who is it for?
- This server suits an operator who already runs Prometheus and wants an assistant to query it, and the tool selection is deliberately narrow, six tools rather than a general HTTP escape hatch, which is the right shape for something pointed at a production metrics endpoint. Three things to check before you deploy it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
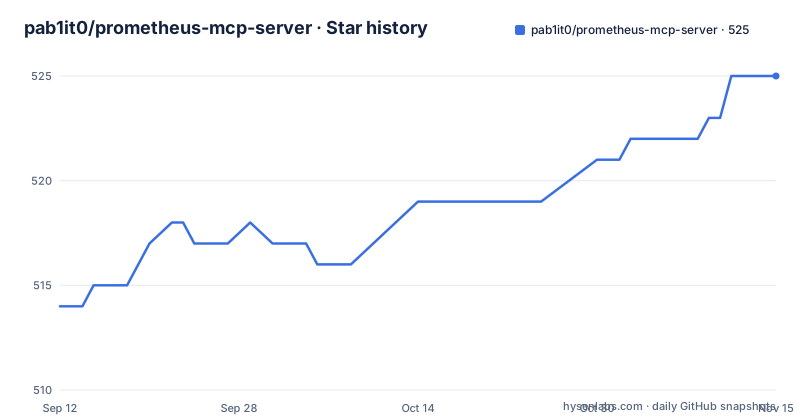
- pab1it0/prometheus-mcp-server525 ★ · +11
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| pab1it0/prometheus-mcp-server | 514 | 525 |
11 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The image overrides the loopback default
There is one configuration value where the documentation and the container image disagree, and it is the one that matters.
The configuration table lists the bind host for the HTTP transport with a default of the loopback address, meaning the server listens on one interface only unless you tell it otherwise. That is the correct default for a local process.
The container image sets the same variable to all interfaces as an image level environment default. So the moment you run the documented docker command, the behaviour is not the documented default.
That is a defensible choice, because a container that binds to loopback inside its own network namespace is unreachable from outside and the image would appear broken. But the two facts have to be read together. The port is exposed in the image, and the transport has a mode where stateless operation is available for running several replicas behind a load balancer, which is precisely the deployment where an unauthenticated PromQL endpoint on every interface becomes interesting to someone else.
The server does not ship an authentication requirement of its own. Basic auth, a bearer token, and mutual TLS are all optional configuration for talking to Prometheus, and nothing in the tool table requires the assistant to present anything at all.
So the posture is: the local default is safe, the container default is not, and the mitigation is a proxy or a network policy rather than a setting.
Six install paths, and only the chart pins a version
The installation section is six collapsed blocks, and comparing them shows an inconsistency in how versions are handled.
Four of the six are client configurations for specific assistants: the desktop client, the terminal client's command line add subcommand, the family of editors that use a flat settings object rather than a nested one, and a desktop container tool with both a catalogue button and a toolkit extension.
The remaining two are direct container invocations, one plain and one with credentials added as environment variables.
Every one of the container-based blocks ends in the same image reference with the floating latest tag. Not a version, not a digest. A reader copying any of them gets whatever was published most recently at the moment they ran it.
And then there is the Helm block, which is the odd one out in the other direction. It pins a chart version explicitly, and that number is 1.1.1 while the server release line is well past 1.6.
Both of those numbers are correct in their own context. The chart has its own independent version, and a chart pinning its own version is the reproducible behaviour. But placed beside five blocks that pin nothing, it reads as an inconsistency rather than a decision.
There is also a chart values file referenced for the full configuration surface, which is the right place to look if you are deploying to Kubernetes and want the settings in version control rather than on a command line.
The plain container invocation, which is the shortest of the six, is two lines of flags and the image reference:
docker run -i --rm \
  -e PROMETHEUS_URL="http://your-prometheus:9090" \
  ghcr.io/pab1it0/prometheus-mcp-server:latest
Four ways to authenticate, plus a way to switch verification off
The authentication configuration is the most complete part of the table, and it covers the cases a metrics endpoint actually faces.
There is username and password for basic authentication. There is a bearer token for token based access. There is a client certificate and a client key, for mutual TLS, which is what a service mesh or an internal certificate authority gives you. And there is a separate variable pointing at a certificate authority bundle, which is the standard environment variable the HTTP library already reads, so a private certificate authority needs no code change.
All four are optional, and the one required variable is the server URL.
Alongside them sits a switch to disable SSL verification on the server connection. That is a legitimate escape hatch for a self signed internal endpoint, and it is also the setting you want to be certain you are not leaving on in a deployment where the traffic leaves the cluster.
Two more variables are about the relationship between the assistant and the server rather than about Prometheus. One is an organisation identifier described as being for multi tenant setups, which tells you there is a tenancy concept behind it. The other lets you supply arbitrary additional headers as a JSON string, which is how you add whatever your gateway insists on without waiting for the server to add support for it.
There is also a request timeout, and its stated purpose is to prevent hanging requests, described as protection against denial of service. Thirty seconds by default, which is a generous amount of time to hold a connection against a metrics endpoint.
Six tools, and you are expected to switch some off
The tool surface is small on purpose, and the documentation says why.
There is one system tool, a health check, described as being for container monitoring and status verification. There are two query tools: an instant query and a range query with start, end, and step. And there are three discovery tools: list metrics with pagination and filtering, get metadata for one metric or in bulk with optional filtering, and get scrape targets with server side state and pool filtering plus optional pagination.
Notice what is absent. There is no generic HTTP request tool, and no arbitrary query endpoint beyond the two PromQL forms. An assistant connected to this server cannot reach anything on the Prometheus host that Prometheus itself does not expose.
That boundary is the security model, and it is a better one than giving a model a curl equivalent.
The other thing worth saying is that the list is configurable, and the reason given is not elegance but context. If you do not use part of the functionality, or you do not want it taking up too much of the context window, you can leave those tools out.
That is an unusual and correct framing. Every tool exposed costs tokens in the calling assistant's system prompt and in every result, so the tool list is a budget decision rather than a feature list. Two of the discovery tools carry their own pagination specifically so a large result set can be walked in pieces.
Three transports, and the healthcheck branches on which one you picked
The transport variable selects between three modes, and the default is the one that matches how the server is launched in every single client configuration.
The default is standard input and output. That is the mode where the client spawns the server as a child process and speaks the protocol over its pipes. It is why every container invocation in the documentation passes the interactive flag and the remove flag, and why the process is removed when the client disconnects.
The other two are network transports: HTTP, and server-sent events. Both require a bind address, which is where the two variables with the defaults discussed earlier come in.
There is also a switch for stateless HTTP operation, described as being for multi replica support. That is a specific and sensible thing to expose: a stateful server cannot be load balanced across replicas, so a switch that removes the state is what lets you run more than one behind a balancer.
The container healthcheck is the detail that ties this together, and it has two implementations. If the transport is one of the two network modes, the check makes an HTTP request to a health endpoint on the configured port using curl. Otherwise it uses a process matching tool to confirm the server process is alive.
So the same image is healthy under either mode, and the check knows which mode it is in. That also explains the runtime image's package list, which is where the two tools come from.
curl and procps are installed so the healthcheck can work
The container image is worth reading as a piece of engineering rather than as packaging boilerplate, and there are four details that are not default.
The build is two stages. The first stage copies the package manager binary out of another published image, then copies only the manifest and the lock file before the source, so the dependency layer is cached independently of code changes. The lock file is applied in frozen mode with development dependencies excluded, and the project is then installed in editable mode with dependency resolution disabled, so the resolver never runs against a manifest that has already been satisfied by the frozen lock.
The second stage installs two packages that exist for the healthcheck and nothing else: curl for the network transports, and the process utilities for the standard input mode. Then it creates a non root user with a fixed numeric identifier and a home directory that is the application directory, with a shell that cannot be run, and it removes write permission from the whole application tree after copying.
The environment sets five Python behaviour flags, of which the fault handler is the one worth knowing: it makes the interpreter dump a traceback on a crash rather than dying silently, which matters in a container where the logs are the only evidence.
The image also carries standard open container metadata labels, which is what makes it discoverable in a registry's search.
Coverage fails the build under eighty percent, with branch coverage on
The project configuration states its quality bar, and it is a real one.
Coverage is configured with branch coverage enabled rather than line coverage alone, so an untaken branch counts against the total. The threshold is eighty percent, and it is a hard failure rather than a report. Missing lines are shown rather than summarised, coverage is written at one decimal place of precision, and covered files are not collapsed into a single line, so you see the full picture rather than the worst offenders.
Lines that are legitimately untestable are excluded by pattern: debug branches, representations, unimplemented methods, import guards, and pass statements. That is a short and conventional list and it does not include the broad exclusions that would make a threshold meaningless.
The test configuration matches it. Tests are collected by a filename and a function name convention, and a pytest option runs coverage as part of every invocation rather than as a separate step.
The runtime dependencies are five, and two of them are worth noting. The MCP framework itself is one, at a version floor rather than an exact pin. And the ASGI web framework is listed alongside it, which is what the network transports are built on.
The rest are small: environment loading, the synchronous HTTP client that talks to Prometheus, a structured logging library, and nothing else. There is no database, no queue, and no framework for state, which matches a server whose only state is what Prometheus already holds.
A lock file, a frozen sync, and one unpinned build input
The reproducibility story has one hole in it, and it is worth finding.
The dependency side is disciplined. A lock file is committed, the container build applies it in frozen mode with development dependencies excluded, and the development extras are exact-ish rather than floating for the parts that matter. The project manifest requires a specific Python floor and declares its version.
The hole is at the very first instruction. The build stage copies the package manager out of another container image, and that image reference uses the floating latest tag. So the binary that installs your dependencies is whatever that image published most recently.
That is a genuine supply chain consideration for a server whose whole job is to read production metrics, and it is worth noting that the project links to a container image of its own in exactly the same floating form. Consistency at least.
Two other root files are worth knowing about. There is a server manifest file, which is the format registries use to describe an MCP server, so this project is listable rather than being something you have to know about. And there is an environment template file, which is the counterpart to the seventeen configuration variables and is the right starting point rather than constructing a command line by hand.
The last release predates the last push by about seven weeks, so the branch is ahead of the newest tag.
Editorial conclusion
This server suits an operator who already runs Prometheus and wants an assistant to query it, and the tool selection is deliberately narrow, six tools rather than a general HTTP escape hatch, which is the right shape for something pointed at a production metrics endpoint. Three things to check before you deploy it. The container image overrides the documented loopback bind address with a listen on every interface, so if you expose that port you are exposing unauthenticated PromQL execution unless you put authentication in front of it. The tool list is configurable and can be trimmed, which matters because every tool description and result consumes context in the calling assistant. And the Helm chart carries its own version line pinned in the documentation at a much lower number than the server release, so pin deliberately rather than copying the install command.
Frequently asked questions
How do I use the prometheus mcp server?
Point an MCP client at it. There are configurations for the desktop client, a command line add subcommand for the terminal client, the family of editors that use a flat settings object, and a desktop container tool with a catalogue entry. Every container based configuration passes an interactive flag and a remove flag and supplies the Prometheus server URL as an environment variable.
What tools does the Prometheus MCP server expose?
Six: a health check for container monitoring, an instant query, a range query with start, end and step, a metric lister with pagination and filtering, a metadata getter for one metric or in bulk, and a scrape target getter with server side state and pool filtering. There is no generic request tool, so the assistant cannot reach anything Prometheus does not expose.
How do I authenticate the Prometheus MCP server to Prometheus?
Four optional mechanisms: username and password for basic authentication, a bearer token, a client certificate and key for mutual TLS, and a certificate authority bundle path for verifying the server, which uses the standard environment variable the HTTP library already reads. A separate switch disables server certificate verification.
Does the Prometheus MCP container listen on localhost?
No, not inside the container. The configuration table documents the bind host default as 127.0.0.1, but the image sets the same variable to 0.0.0.0, because a loopback bind inside the container network namespace would be unreachable. The port is exposed in the image, so restrict it at the network layer.
Can I deploy the Prometheus MCP server to Kubernetes?
Yes, with a Helm chart pulled from an OCI registry. The documentation pins chart version 1.1.1 while the server release line is past 1.6, since the chart carries its own version. You set the Prometheus URL on the command line or supply a values file, and the chart values file is the reference for every option.
Which transports does the Prometheus MCP server support?
Standard input and output by default, plus HTTP and server-sent events, with a separate bind host and port for the network modes. There is also a stateless HTTP switch described as being for multi replica support. The container healthcheck branches on the chosen mode, using an HTTP health request for the network transports and a process check otherwise.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pab1it0-prometheus-mcp-server)Star history chart for your README
[](https://hysenlabs.com/projects/pab1it0-prometheus-mcp-server)Was this useful?