PaddleScience: three ways to solve a PDE, and a case table for each
PaddleScience is SDK and library for developing AI-driven scientific computing applications based on PaddlePaddle.
At a glance
- What is it?
- A scientific computing suite on PaddlePaddle that organises every example by how the physics enters the model, physics-driven, data-driven, or both, and publishes the paper behind each row so you can read the method before you run the code.
- Who is it for?
- PaddleScience fits a computational science group that wants a PINN and operator-learning baseline on PaddlePaddle with the reference paper attached to each example, since the case tables carry the model type, training mode and citation in one row. It does not fit a project that needs recent Python support declared up front, because the classifiers stop at Python 3.10 while the dependency file still holds numpy below 2.0, and meshio is pinned to an exact 5.3.4.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
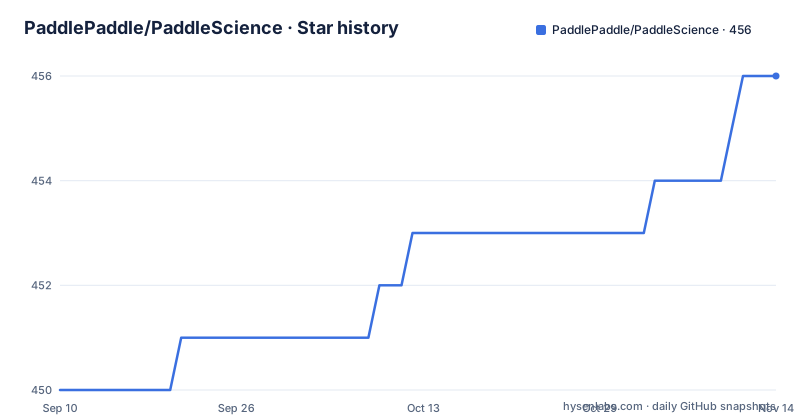
- PaddlePaddle/PaddleScience456 ★ · +6
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| PaddlePaddle/PaddleScience | 450 | 456 |
6 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The case table sorts by how the physics enters
Every example in the README sits in a table with the same columns: problem type, case name, optimisation algorithm, model type, training mode, dataset and reference. Those columns are where the design shows. The mathematics group is mostly physics-mechanism-driven with unsupervised training and no dataset at all, which is the physics-informed signature: Allen-Cahn, the Laplace equation, Burgers, a nonlinear PDE through PIRBN, a Volterra integral equation, a fractional Poisson equation, optical solitons and rogue waves, XPINN for domain decomposition, and a gradient-enhanced PINN. The data-driven rows are the opposite: the Lorenz and Rossler systems through Transformer-Physx, DeepONet for operator learning, Transformer4SR for symbolic regression, and a latent neural operator, all trained with supervision and all carrying a dataset link.
Three modes, twenty cases, two application areas
The stated scope is physics, chemistry and meteorology, solved in three ways: physics-mechanism-driven, data-driven, and a fusion of mechanism and mathematics, with the README counting more than 20 cases across fluid, structure and meteorology. The fusion mode is what the gradient-enhanced physics-knowledge PDE solver demonstrates. The engineering table that follows the mathematics one moves into applied problems and is where the more recent work sits: car surface drag prediction through Transolver and DrivAerNet with a RegDGCNN model, a one-dimensional linear advection problem and a two-dimensional buoyancy-driven cavity flow both solved with vision transformers, plus steady incompressible cases such as a Re3200 cavity flow, a two-dimensional Darcy flow and a two-dimensional pipe flow. The examples directory names more than two dozen of these directly, including CFD and graph-network work such as cfdgcn, deepcfd and cgcnn.
Geometry is an object, not a mesh file
Geometry handling is listed as a feature rather than assumed. The framework supports sampling and boolean operations on both simple geometry and complex STL geometry, which is what lets a case define a shape in code and derive its own point cloud, and the boundary conditions are enumerated as a set: Dirichlet, Neumann, Robin, and custom conditions you define. That combination is why install_mesh.sh sits at the repository root, and why .gitmodules is tracked, since mesh processing is not a pip dependency in requirements.txt but something fetched separately. The packaging configuration reflects the same split: pyproject.toml excludes ppsci/externals and ppsci/externals/* from the wheel, so those vendored components stay out of the installed package and come from the source tree instead.
Experiment tracking and Hydra are part of the deal
Two features are about research process rather than mathematics. The first is experiment source tracking with one-click launch of parallel experiments, which is the difference between a script that runs once and a study you can reproduce. Hydra is how that is wired: hydra-core is a hard requirement in requirements.txt and the project carries a Hydra badge beside the Black one, so configurations are composed rather than passed as a wall of flags. The second feature area is output: result visualisation and structured log saving, backed by h5py, imageio, pyevtk, matplotlib and seaborn. Equation handling is symbolic, using sympy for representing equations and solving systems of equations algebraically before any training starts, and the public surface is typed, with typing-extensions and pydantic at 2.5.0 or newer in the requirements.
Two build files describe the same package
Both pyproject.toml and setup.py ship, and the reason is visible in the metadata. pyproject.toml declares version and dependencies as dynamic, so the build cannot read them from the file itself. The version comes from setuptools_scm, which is a build requirement, writes into ppsci/_version.py and matches tags with the pattern v followed by three numbers, with a fallback for a tree with no tag at all. The dependencies come from requirements.txt, which setup.py reads line by line. Everything else is duplicated between the two files on purpose: the package name paddlesci, the author PaddlePaddle, the same classifier list and the same exclusion tuple covering docs, examples, jointContribution, test_tipc, test, tools and the externals directory. The lint configuration lives only in pyproject.toml, with Ruff at a line length of 88, E501, E741 and E731 ignored, and two files excluded outright for style reasons.
Pins that have not moved with the ecosystem
requirements.txt is short and opinionated. numpy is held at 1.20.0 or newer and below 2.0.0, scikit-learn is held below 1.5.0, and meshio is pinned to an exact version, 5.3.4, with no range at all. Against that, pydantic requires 2.5.0 or newer, which is the modern major version of a validation library, so the file mixes a current validation dependency with a numeric stack frozen before NumPy 2. The rest is ordinary scientific Python: scipy, sympy, scikit-learn's optimisation sibling scikit-optimize, einops, h5py, matplotlib, seaborn, imageio, pyevtk, psutil, colorlog, pyyaml, requests, tqdm, typing-extensions and wget, with hydra-core doing the configuration work. Nothing here installs a deep learning framework, because PaddlePaddle itself is expected to be present already.
Classifiers say Production/Stable, releases say 2025
The metadata makes a confident claim. The classifier Development Status is set to 5, Production/Stable, the audience is Science/Research, and requires-python is >=3.8, yet the per-version classifiers stop at 3.8, 3.9 and 3.10, so nothing declares 3.11 or newer even though nothing blocks it. The release history is slower than the commit history: v1.2.0 on 27 November 2023, v1.3.0 on 22 July 2024, v1.4.0 on 8 April 2025, and after that no tag, while the default branch, develop, took its last push on 22 July 2026 and the repository is not archived. Around the package sit the usual research scaffolding: competition/, recipe/, deploy/, docker/, jointContribution/, test/, test_tipc/, CITATION.cff, mkdocs.yml with .readthedocs.yaml, and a pre-commit configuration that includes a .clang-format hook for whatever C++ sits in the externals.
Editorial conclusion
PaddleScience fits a computational science group that wants a PINN and operator-learning baseline on PaddlePaddle with the reference paper attached to each example, since the case tables carry the model type, training mode and citation in one row. It does not fit a project that needs recent Python support declared up front, because the classifiers stop at Python 3.10 while the dependency file still holds numpy below 2.0, and meshio is pinned to an exact 5.3.4. Before you build on it, check which of the three solving modes your problem belongs in, because physics-driven cases train without a dataset at all, and note that develop is the default branch and has moved well past the last release, v1.4.0 from 8 April 2025.
Frequently asked questions
What is PaddleScience used for?
It is a scientific computing suite built on PaddlePaddle, using neural networks and PaddlePaddle's automatic higher-order differentiation to solve problems in physics, chemistry and meteorology. It offers three solving modes, physics-mechanism-driven, data-driven and a fusion of the two, across more than 20 cases in fluid, structure and meteorology.
How do I install PaddleScience?
Two distributions are linked from the project: the paddlesci package on PyPI and PaddleScience/paddlescience on Anaconda. The project requires Python 3.8 or newer, and the installation instructions live in the Chinese documentation at paddlescience-docs.readthedocs.io, not on the README itself.
What does PaddleScience pin in requirements.txt?
numpy is held at 1.20.0 or newer and below 2.0.0, meshio is pinned exactly at 5.3.4, and scikit-learn below 1.5.0, while pydantic needs 2.5.0 or newer. Hydra comes in as hydra-core, and sympy, einops and scikit-optimize cover symbolic equations and hyperparameter tuning.
Why does PaddleScience ship both pyproject.toml and setup.py?
Because the version and the dependencies are dynamic rather than written down. pyproject.toml declares both as dynamic, setuptools_scm writes the version into ppsci/_version.py from a v-prefixed tag, and setup.py reads requirements.txt, repeating the package name, author, classifiers and the exclusion list in both files.
How current is PaddleScience?
The repository is not archived and the last push to the develop branch, which is the default, is dated 22 July 2026. The newest release tag is v1.4.0 from 8 April 2025, after v1.3.0 in July 2024 and v1.2.0 in November 2023, so the default branch has run well past the last release for over a year.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paddlepaddle-paddlescience)Star history chart for your README
[](https://hysenlabs.com/projects/paddlepaddle-paddlescience)Was this useful?