PANDA records whole-system execution but replays it at one address length
Platform for Architecture-Neutral Dynamic Analysis
At a glance
- What is it?
- A QEMU-based platform for architecture-neutral dynamic analysis, with record and replay of guest execution and a plugin system for taint-style analyses. The branches, the containers and the licensing all need reading carefully: releases are tagged from dev, the developer container example changes the binary path between pull and build, and the macOS path is documented as expected to be broken.
- Who is it for?
- PANDA suits research work where a whole-system trace has to be replayed repeatedly, and the recording format is treated as a compatibility surface worth trusting within one address width. Plan the install around its own advice: the README recommends the stable branch for anyone who intends to fork and pull updates, even though the published releases are tagged from dev.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
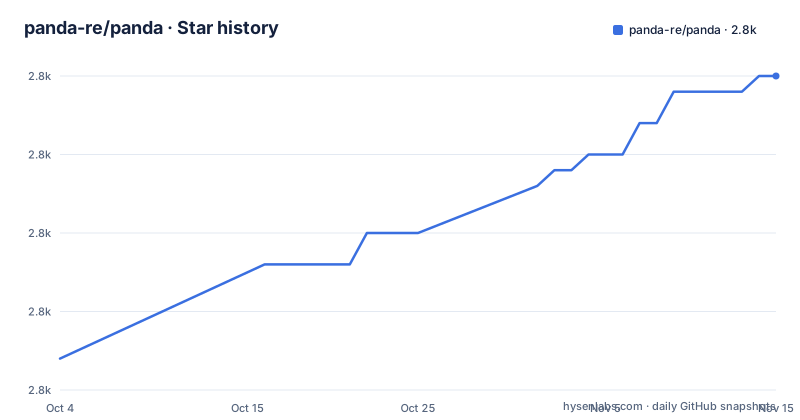
- panda-re/panda2,800 ★ · +18
| Repository | 2026-10-04 | 2026-11-15 |
|---|---|---|
| panda-re/panda | 2.8k | 2.8k |
18 Stars in the last 42 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Releases are tagged from dev, the branch meant for work in progress
The branching scheme is two branches with different jobs. dev is for development, stable is for stable and versioned releases, and the README says PANDA resources such as Docker containers and documentation are based off dev. It also recommends using stable if you plan to fork the project and pull in updates later.
The release record does not follow that split. The three most recent releases are v1.8.85, v1.8.84 and v1.8.83, and each one carries a branch reference in its title pointing at refs/heads/dev rather than refs/heads/stable. The default branch on the repository is dev as well.
So the branch recommended for forkers is not the branch the versioned releases are cut from, and the documentation and images a new user meets first come from the same development line. The dates are also uneven: v1.8.85 and v1.8.84 were both published on 2026-06-09 fifteen minutes apart, while v1.8.83 goes back to 2026-02-03.
The developer container example changes the binary path between pull and build
There are two images, and the distinction is size versus source. The panda image carries PANDA and PyPANDA with their runtime dependencies and no build artefacts or source code. The pandadev image carries PANDA and PyPANDA, build and runtime dependencies for both, all build artefacts, the source, and the contents of the repository mounted at /panda.
The two pandadev examples then disagree about where the binary lives. Pulling from Docker Hub and running it:
$ docker pull pandare/pandadev
$ docker run --rm pandare/pandadev /panda/build/panda-system-i386 --help
Building the same image from the repository and running it:
$ DOCKER_BUILDKIT=1 docker build --target=developer -t pandadev .
$ docker run --rm pandadev panda-system-i386 --help
The first needs the absolute /panda/build prefix and the second does not, for what is nominally the same container. The build target is named developer while the image is named pandadev, which is the other half of the mismatch.
The image builds nine softmmu targets while the README counts thirteen architectures
The architecture claim is one of the project's headline features: PANDA leverages QEMU's support of thirteen different CPU architectures to make analyses of diverse instruction sets possible within the LLVM IR, so a single dynamic taint analysis can support many CPUs.
The Dockerfile at the repository root does not agree with the number. Its TARGET_LIST argument reads x86_64-softmmu, i386-softmmu, arm-softmmu, aarch64-softmmu, ppc-softmmu, mips-softmmu, mipsel-softmmu, mips64-softmmu and mips64el-softmmu, which is nine targets. The count of architectures QEMU can emulate and the count of targets a given image is built for are different questions, but nothing in the repository explains how thirteen becomes nine, and someone sizing a container build will be counting the Dockerfile.
The same argument block pins Capstone at 5.0.5 and a package version at 3.1.0, with the registry and base image as overridable arguments.
The build assumes your checkout directory is named panda
Reading the Dockerfile closely shows a naming assumption. Dependency manifests are copied from ./panda/dependencies/, with the base image name rewritten into a filename, producing paths like ubuntu_22.04_base.txt. Those files are consumed with grep and handed to apt-get. If you clone the repository into a directory with any other name, the COPY at the top of the build fails before anything compiles.
That convention matches the developer container, which is described as carrying the contents of the repository in the /panda directory, and the pip route, which tells you to run pip install . from the directory panda/panda/python/core. Three separate instructions all assume the same path shape.
The Python route itself is the shortest install: pip3 install pandare from PyPI, named after the project domain rather than the repository, which brings in everything needed for Python-based analyses but not the stand-alone binaries. Those binaries are tested only on 64-bit Ubuntu 22.04.
Replay is only guaranteed between builds of the same address length
The record and replay feature is the reason the project exists, and its limitation is stated precisely. A great deal of effort goes into keeping the trace format stable so existing traces stay replayable, and changes that would break them are avoided. Even so, record and replay is only guaranteed between PANDA builds of the same address length, with the example cut off mid-sentence at the point where a trace captured on a 32-bit build is used on a 64-bit one.
That boundary is the one to plan around. The same document strongly recommends building PANDA only as a 64-bit binary, saying a 32-bit build should be possible but is best avoided. Taken together, the two statements mean a trace is portable across time but not across address width, so a corpus collected on one architecture of guest is tied to it.
The LLVM side has its own version floor. The taint system needs LLVM 14 from OS packages or compiled from source, the S2E-derived files have been updated to work with LLVM 14, and on Ubuntu the install script is supposed to handle it.
The macOS build path is documented as expected to be broken
Three platform scripts exist, and the confidence levels differ sharply. The Ubuntu one, install_ubuntu.sh, is the recommended route and has encoded the build instructions because PANDA has a few dependencies; the Arch one, install_arch.sh, was contributed and has only been tested on a single configuration whose string names Manjaro rather than Arch Linux. The macOS one, install_osx.sh, uses Homebrew to pull the dependencies.
What makes the macOS entry unusual is the warning attached to it. Building on Mac is described as less well-tested but known to work, and then the documentation says that since Homebrew is very fast in deprecating support for older versions of the OS and of supported packages, you should expect this to be broken. The project states its own most likely failure mode rather than leaving it to be discovered.
Installation after a successful build is short: make install, a default path of /usr/local, an alternate location through the prefix option such as --prefix=/opt/panda, and a requirement that chrpath be installed for the install step to succeed.
The repository root is QEMU's own source tree with PANDA grafted on
The top level explains what this project is built on. Alongside the PANDA-specific pieces, Makefile.objs, Makefile.target, VERSION, CODING_STYLE, HACKING, MAINTAINERS, contrib/, docs/, dtc, flake.nix and build.sh, the root holds QEMU's files by name: accel.c, block.c, balloon.c, blockdev.c, bootdevice.c, chardev/, cpus-common.c, cputlb.c, crypto/, device_tree.c, disas.c, dma-helpers.c, dump.c and exec.c.
The root Makefile says so in its own first line, with the comment Makefile for QEMU. It also carries QEMU-specific machinery that has nothing to do with analysis: unchecked goals for TAGS, cscope, ctags and docker targets, metadata harvested from git describe with a dirty flag and the build date, submodule update handling, and a guard that refuses to mix an out-of-tree build with a source tree previously used for an in-tree one.
Two naming collisions come with that arrangement. Both README and README.md sit at the root, and both Changelog and the release tag scheme are present alongside a .shippable.yml CI configuration. .gitmodules is there too, so parts of the build arrive from outside the repository.
The README says GPLv2 while the tree carries three licence files
The licensing picture needs care rather than a single answer. The README states that PANDA is released under the GPLv2 licence and links a LICENSE file. The tree contains LICENSE, COPYING and COPYING.LIB, which is the combination you would expect from a project that carries more than one grant, and nothing in the root explains which one applies to which files. The repository metadata itself records no licence value at all.
So there is no contradiction between the README and the tree, but there is no single answer either. If the LGPL text in COPYING.LIB covers some subset of the code, that is not spelled out anywhere in the repository, and picking one on a reader's behalf would be a guess.
The collaboration arrangement is at least unambiguous: development is in collaboration with MIT Lincoln Laboratory, NYU and Northeastern University. The plugin architecture, which is where most analysis code lands, is described as a simple mechanism with a way to share functionality between plugins, aimed at reusing analysis code and simplifying complex analyses.
Editorial conclusion
PANDA suits research work where a whole-system trace has to be replayed repeatedly, and the recording format is treated as a compatibility surface worth trusting within one address width. Plan the install around its own advice: the README recommends the stable branch for anyone who intends to fork and pull updates, even though the published releases are tagged from dev. If you build the developer container yourself, expect the binary to sit on the path rather than under /panda/build, because the two examples disagree. Build 64-bit only, and install LLVM 14 from packages if you want the taint system, since that is the dependency with the narrowest requirement. The last push was on 2026-09-24.
Frequently asked questions
What is PANDA and what does it add to QEMU?
PANDA is a platform for architecture-neutral dynamic analysis built on the QEMU whole system emulator. It adds the ability to record and replay executions, so analyses get access to all code and data in the guest, and the replay logs are compact and shareable for repeatable experiments.
Can a PANDA recording be replayed on a different machine?
Between PANDA builds of the same address length, yes, and the trace format is deliberately kept stable so old traces stay replayable. Across address widths it is not guaranteed, which is why 64-bit-only builds are strongly recommended.
How do you install the Python interface to PANDA?
Run pip3 install pandare from PyPI. That covers Python-based analyses but not the stand-alone binaries, which are tested only on 64-bit Ubuntu 22.04. Alternatively build PANDA and run pip install . from the directory panda/panda/python/core.
What is the difference between the panda and pandadev containers?
The panda image carries PANDA and PyPANDA with runtime dependencies only, with no build artefacts or source. The pandadev image adds build and runtime dependencies for both, all build artefacts, the source code, and the contents of the repository under /panda.
Which branch of PANDA should I use?
dev is for development and is what the Docker images and documentation are built from, while stable is for stable and versioned releases. The README recommends stable if you intend to fork the project and pull in updates later.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/panda-re-panda)Star history chart for your README
[](https://hysenlabs.com/projects/panda-re-panda)Was this useful?