pandas builds with meson-python and excludes numpy 2.5.0 on purpose
Flexible and powerful data analysis / manipulation library for Python, providing labeled data structures similar to R data.frame objects, statistical functions, and much more.
At a glance
- What is it?
- The Python data analysis library, now on a meson-python build backend with Cython compiled extensions and a vendored fast_float. The build metadata pins a numpy range that deliberately leaves one release out, 2.5.0, because wheels built against it segfault on older numpy.
- Who is it for?
- Adopt pandas if your work is tabular or time series data in Python, because the alignment and groupby semantics are the reason the library is hard to replace, and because releases keep coming: v3.1.0 shipped on 2026-10-22, after v3.1.0rc0 and v3.0.6, with the last push on 2026-11-02. Do not adopt it expecting a pure-Python install to be equivalent, because the build compiles Cython extensions through meson and needs a compiler toolchain plus Cython even for a source install.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
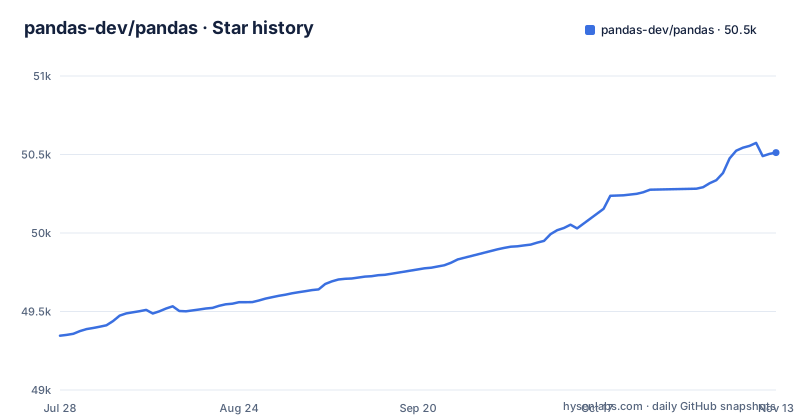
- pandas-dev/pandas50,512 ★ · +1,166
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| pandas-dev/pandas | 49.3k | 50.5k |
1,166 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The build backend is meson-python, and Cython is not optional
The build-system table in pyproject.toml is the part of the repository that changed the installation story. The backend is mesonpy, and the requirements are a meson-python between 0.19.0 and 1, meson between 1.2.3 and 2, Cython above 3.1.0 and below 4, and versioneer. A source install therefore needs a build system, a compiler and Cython before pandas itself is involved.
The README's Installation from sources section only links to the full instructions for installing from source. The practical consequence for a reader is that `pip install pandas` from PyPI and `pip install .` from a clone are not the same operation. The first generally uses a compatible wheel when available, while the second builds the extension modules locally, which is where a missing toolchain shows up.
The version itself is not in pyproject.toml at all. The name is declared with dynamic = ['version'], the build wiring around it is versioneer, and the repository carries both generate_version.py and generate_pxi.py for code generation at build time.
Wheels are built against numpy 2 to stay compatible with numpy 1
The numpy bound in the build requirements carries a one-line comment explaining itself: 2.5.0 is excluded on purpose because wheels built against 2.5.0 segfault on older numpy, citing GH#66086 and numpy GH#31804.
The written requirement is `numpy>=2.0.0,!=2.5.0`. A reader pinning dependencies by hand will not find that exclusion anywhere else, and an environment that happens to have 2.5.0 installed satisfies a naive `>=2.0.0` check. This is a build-time constraint for that source revision, not automatically a restriction on the NumPy version used to run an already-built pandas wheel. Check the selected release's runtime requirements separately.
There is a second, quieter bound next to it. The Cython constraint is written as Cython>3.1.0,<4, with a comment saying not to include alpha specifiers in Cython version pins. A second comment asks that the bound be kept in sync with environment.yml and asv.conf.json, which tells you this is a value maintained in three files by hand.
Alignment is the behaviour that leaks into everything else
The feature list leads with missing data handling, represented as NaN, NA or NaT in floating point and non-floating point data, then with size mutability, where columns can be inserted and deleted from DataFrame and higher dimensional objects. The third entry is the one that shapes the rest: automatic and explicit data alignment, where objects can be aligned to a set of labels or the labels can be ignored and Series, DataFrame and the rest align the data for you in computations.
That single decision is why combining two frames of different shape does not raise, and why it occasionally produces NaN where you expected a row. It is also why group by is described as split-apply-combine rather than as a single operation, and why merging, joining, reshaping and pivoting all read as variations on the same idea of labels meeting.
The rest of the list is a catalogue of consequences of that model: hierarchical labelling of axes so a tick can carry multiple labels, label-based slicing with fancy indexing and subsetting, and conversion of ragged, differently indexed data from other Python and NumPy structures into DataFrame objects. Time series support is separate rather than derived, covering date range generation, frequency conversion, moving window statistics, and date shifting and lagging. I/O is described as robust for flat files, Excel, databases, and the HDF5 format.
asv_bench, ci/ and pixi.lock are three different answers to reproducibility
The top level of the repository shows how the project is kept honest, and there are three distinct mechanisms doing it.
asv_bench/ is the performance benchmark suite, which is the project's way of detecting performance regressions. ci/ holds the continuous integration definitions. pixi.toml with pixi.lock is a separate environment definition from a lock file, and environment.yml is the Conda-side equivalent, which is the third place the Cython bound has to be kept in step.
Around those, .pre-commit-config.yaml gates commits, codecov.yml tracks coverage, pyright_reportGeneralTypeIssues.json records a static typing report, and LICENSES/ holds the vendored licence texts. A contributor therefore has to satisfy a formatter, a type report, a coverage number and a benchmark comparison before a change lands.
The licence is BSD-3-Clause plus fourteen vendored licence texts
pandas itself is BSD-3-Clause, stated in pyproject.toml with license = 'BSD-3-Clause' and a LICENSE file at the root. The licensing section then lists every other licence that ships inside the distribution, each with the file that carries it:
license-files = [
    "LICENSE", # BSD-3-Clause
    "LICENSES/BOTTLENECK_LICENCE", # BSD-2-Clause
    "LICENSES/DATEUTIL_LICENSE", # Apache-2.0
    "LICENSES/HAVEN_LICENSE", # MIT
    "LICENSES/KLIB_LICENSE", # MIT
    "LICENSES/MUSL_LICENSE", # MIT
    "LICENSES/NUMPY_LICENSE", # BSD-3-Clause
]
The full list runs to nineteen entries when LICENSE and the bundled subprojects are counted: fifteen files under LICENSES/ plus three fast_float files, including a fast_float subproject that ships its own LICENSE-APACHE, LICENSE-BOOST and LICENSE-MIT files. The licences range across BSD-2-Clause, BSD-3-Clause, Apache-2.0, MIT, PSF-2.0, BSL and one entry marked BSD-3-Clause AND TCL for ultrajson.
This is ordinary practice for a scientific Python package and it is still worth reading if you redistribute. The permissive licences dominate, but the list is the authoritative statement of what you are shipping, and the vendored files are in the repository rather than only on a website.
Getting pandas is a wheel, not a build, unless you clone
The supported install routes are two commands:
# conda
conda install -c conda-forge pandas# or PyPI
pip install pandasBinary installers for the latest released version come from the Python Package Index and from Conda, and the source is on GitHub. Which route you take decides what you get: a conda package or, when available for your platform, a PyPI wheel. Pip can also build from source when no compatible wheel is available.
The runtime dependencies are short by design. NumPy supplies the large, multi-dimensional arrays and the mathematical functions that operate on them. python-dateutil extends the standard datetime module. tzdata provides the IANA time zone database and is required only on Windows and Emscripten, which is the one platform-specific dependency in the list. The minimum supported versions of required, recommended and optional dependencies are documented separately, and the optional set is where Excel, SQL and HDF5 support live, so a minimal install gives you less than the feature list implies.
Patch releases are frequent, and the major version is the risk boundary
The last push to the default branch main is dated 2026-11-02, and the release list shows v3.1.0 on 2026-10-22, v3.1.0rc0 on 2026-09-30 and v3.0.6 on 2026-09-17. Recent releases and a push within the last few days are a healthy maintenance signal.
The repository carries the migration paperwork in the usual place: the list of changes between each release lives in the documentation's whatsnew pages, and the commit logs are on GitHub for anyone who needs the detail the release notes leave out. AGENTS.md at the root, AUTHORS.md, CITATION.cff for citation metadata, and a Zenodo DOI badge are all in the tree.
What the repository does not do is tell you which of your own code will break. Read the release notes for the version you are moving to against your own usage before upgrading, not after.
Editorial conclusion
Adopt pandas if your work is tabular or time series data in Python, because the alignment and groupby semantics are the reason the library is hard to replace, and because releases keep coming: v3.1.0 shipped on 2026-10-22, after v3.1.0rc0 and v3.0.6, with the last push on 2026-11-02. Do not adopt it expecting a pure-Python install to be equivalent, because the build compiles Cython extensions through meson and needs a compiler toolchain plus Cython even for a source install. Two things to check before you pin a version. Read the build requirements in pyproject.toml rather than trusting a wheel, and note the comment next to the numpy bound: 2.5.0 is excluded because wheels built against it segfault on older numpy. And check the licence set, which is BSD-3-Clause for pandas itself and then fifteen vendored licence files under LICENSES/ (Bottleneck, dateutil, NumPy and others) plus the bundled fast_float subproject.
Frequently asked questions
How do I install pandas in Python?
Use pip install pandas from PyPI, or conda install -c conda-forge pandas. Both give you a binary installer for the latest release, so no compiler is needed.
How do I use pandas to read a CSV file?
pandas I/O tools cover flat files including CSV and other delimited formats, along with Excel files, databases and the HDF5 format. The documentation links each of these from the main feature list.
What is pandas used for in Python?
It provides data structures for relational or labeled data, with group by for split-apply-combine operations, merging and joining, reshaping and pivoting, hierarchical axis labels, and time series functions such as frequency conversion and moving window statistics.
How does pandas groupby work?
Group by is described as powerful, flexible functionality for split-apply-combine operations, for both aggregating and transforming data. Columns can also be inserted and deleted from DataFrame and higher dimensional objects.
How do I use a pandas DataFrame?
A DataFrame supports label-based slicing, fancy indexing and subsetting, automatic and explicit data alignment, and conversion of ragged, differently-indexed data from other Python and NumPy structures into DataFrame objects.
How do I use pandas and NumPy together in Python?
NumPy is the required dependency that adds support for large, multi-dimensional arrays, matrices and high-level mathematical functions, and pandas converts ragged, differently-indexed data from other Python and NumPy structures into DataFrame objects.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pandas-dev-pandas)Star history chart for your README
[](https://hysenlabs.com/projects/pandas-dev-pandas)Was this useful?