cuid: deprecated for leaking timestamps, and it also puts the process id inside every id
Deprecated collision-resistant id spec. Insecure because it leaks timestamps. Use cuid2 instead.
At a glance
- What is it?
- The cuid package is a short, roughly sortable identifier that its own authors have deprecated for security reasons. The reason is stated in the description and then demonstrated: the timestamp is guessable, and so is a fingerprint derived from the user agent string in a browser or from the process id and hostname on a server. The README is two documents, a short notice and the original specification preserved underneath a heading that says so.
- Who is it for?
- Do not start anything new on this package. If you have it in an existing system, the migration is the work, and the readme tells you the reason: the ids disclose when they were made and, depending on the platform, who made them.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
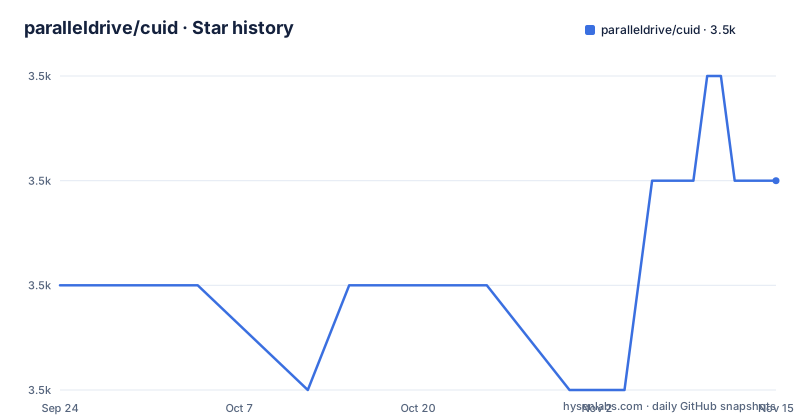
- paralleldrive/cuid3,503 ★ · +1
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| paralleldrive/cuid | 3.5k | 3.5k |
1 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The readme is two documents and it says which one is historical
The structure of this readme is the first thing to notice, because it explains why the file still contains a complete specification for something the project no longer recommends.
The top is short. A status line says the project is deprecated due to security and points to a successor under the same account. Then there is a note about which other identifier schemes share the problem.
Then a heading that reads, in substance, that the original documentation follows. Everything below it, the examples, the install command, the breakdown of the identifier into groups, the fingerprint description, the motivation, the performance argument, the notes on monotonicity and size, is that preserved original document.
So this is a project that published a security advisory by editing its own front page and then leaving the rest intact. That is worth knowing as a reader, because a search result that lands in the middle of the file will give you a confident specification for an identifier scheme with a known problem, and no hint that it has one.
The status line and the deprecated marker are both above that boundary, which means anyone reading top to bottom gets warned. Anyone deep-linking does not.
The deprecation notice condemns four other schemes as well
The note above the historical documentation is the most useful text in the repository, and it does not stop at this package.
It says that all monotonically increasing identifiers, which it names as auto-increment and k-sortable ones, and all timestamp-based identifiers, share the security issues being complained about.
It then extends the problem to version 4 UUIDs and GUIDs, on two grounds: it is possible to predict future values of many random algorithms, and many of those algorithms are biased, which raises the chance of collision.
And it extends it again to version 6 through 8, not for predictability but for the same reason this package is deprecated: those versions leak information that could be used to exploit systems or violate user privacy.
Three published write-ups are linked as evidence, and all three are the same class of bug: a password reset reachable with a guessable identifier, access to private issue tracker data through guessable identifiers, and a password reset driven by a different widely used identifier format.
So the successor is not the only safe option the project believes in. If you were about to replace this with one of those, the note is telling you not to.
The fingerprint embeds the process id and the hostname in every id
The original specification explains the identifier's five groups, and one of them is where the real disclosure lives.
The first group is a single character identifying the format, so ids are usable as HTML element identifiers. The second is a timestamp. The third is a counter. The fourth is a client fingerprint. The fifth is random data from a cryptographically secure source where one is available.
The fingerprint is the problem, and the specification describes how it is built on each platform without treating it as sensitive.
In a browser, the first characters are derived from the user agent string and from the list of supported media types, with an acknowledgement that one old browser always returns zero for the latter. Those are concatenated with a count of variables in the global scope, and the result is trimmed to four characters.
On a server, the first two characters come from the process id and the next two from the hostname.
So every id ever issued by a Node process carries four characters derived from that machine's identifier and name, and every id issued by a browser carries four characters derived from a digest of the user agent. That is not a theoretical weakness in the random component. It is a stable, low-entropy, machine-identifying field in the one field everyone assumes is opaque.
Monotonicity is documented with two hard numbers and both of them are old
The performance argument is the part of this design that still holds up, and the specification states its limits precisely.
Ids generated by the same process are monotonically increasing, but only when fewer than ten thousand are generated within the same millisecond. Across processes, ids are still increasing in time only if the clocks are synchronised.
Two conditions, one on throughput and one on infrastructure, and the second is a property of the deployment rather than of the code.
The reason monotonicity matters is given directly: these identifiers are suitable as high-performance database primary keys because they can be binary searched, and purely pseudo-random variants do not meet that requirement.
That is the trade the package made, and it is a defensible one. Ordering and index locality against unpredictability.
The counter's own weakness is acknowledged in the breakdown too: a single process might generate the same random string, the weaker the pseudo-random source the higher the probability, and the problem gets worse as processors get faster. That sentence was written about hardware an order of magnitude slower than what runs this code now.
Two platform maps, and they cover exactly the two files that leak
The manifest is more revealing about the design than the readme is.
There are exactly two platform override blocks. One maps two files for a browser environment, and one maps the same two files for a React Native environment. The files are the fingerprint module and the module that supplies random values.
So the package ships three variants of the fingerprint implementation and three of the random source, and those two modules are the only things that vary by platform. Everything else, including the timestamp, the counter, the character layout, and the ordering property, is shared.
That is a tidy architecture and it isolates the risk cleanly. The moment you stop treating the fingerprint as opaque, the platform split stops being a build convenience and becomes the list of places the leak can occur.
It also means a consumer who wants to check what a library does cannot reason from the shared code, because the code that runs is always one of the three overridden files, chosen by the packaging tool rather than by anything in the library's own logic.
The manifest says 3.0.0, the newest tag says 2.0.1, and that tag order is inverted
Three version facts, and they do not agree with each other.
The manifest declares a version one whole major ahead of anything ever tagged. The two releases in the repository's history are both from January 2018, and one of them is titled with the words modular build and broken release in its own release note.
The timestamps are also out of order. The newer version number was pushed about three minutes before the older one, which means the tags do not even sort chronologically in the intuitive direction.
And the most recent commit is from three days ago, on a project whose readme has told people not to use it for years. The repository is still receiving commits that are not releases.
The repository field inside the manifest also points at the original author's repository rather than the account that now owns it, and the readme's build badge points at a continuous integration service under that same older path. So the metadata still describes where this code came from, and the ownership has moved.
A build toolchain from 2017, two assertion libraries, and a CDN entry into an uncommitted directory
The development dependencies tell you when this was last touched as a working package rather than an archived one.
There are nineteen of them. Six are from the Babel 6 era, including a polyfill and a register helper. The bundler is current-ish for its time. The linter is a much later major than anything else in the file.
Two assertion libraries are declared rather than one, and there is a browser test runner plus a static file server for serving the built bundle to it. The install command itself is one line:
npm install --save cuidThe default test command chains linting and four suites, one of which drives a real browser and one of which bundles a Web Worker test before running it. For a library whose whole implementation is a string builder, that is a serious test setup.
Two details are quietly broken. One dependency is a version manager for dependencies that no longer has a reason to exist in this file. And the published file list includes a build output directory that is not in the repository, while the CDN entry points into that same directory, so the copy a browser fetches is an artefact of the publish step rather than anything committed.
None of that affects the security problem. All of it affects whether you could have maintained a fork.
Editorial conclusion
Do not start anything new on this package. If you have it in an existing system, the migration is the work, and the readme tells you the reason: the ids disclose when they were made and, depending on the platform, who made them. Read the compatibility note in the deprecation message before you plan the replacement, because it condemns four other schemes you were probably about to reach for instead. And note the state of the repository, because it affects whether you can patch around it yourself.
Frequently asked questions
What is a CUID?
It is a short identifier made of five groups: a one-character format marker so the value can be used as a HTML element id, a timestamp, a counter, a four-character client fingerprint, and random data from a cryptographically secure source where one is available. Ids from one process sort in time, which is what makes them usable as database primary keys.
What is the difference between a UUID and a Cuid?
The repository argues there is less difference than expected. It says version 4 UUIDs and GUIDs are also insecure because future values of many random algorithms can be predicted and many are biased, and that versions 6 through 8 are insecure because they leak information, which is the same objection it raises against its own format.
Why was cuid deprecated?
Its own notice says the ids are insecure and points to a successor. The note above the documentation extends the same objection to auto-increment and k-sortable ids, to timestamp-based ids, to version 4 UUIDs for predictability and bias, and to versions 6 through 8 for leaking information, with three linked write-ups describing a password reset and private repository access achieved through guessable identifiers.
Does cuid expose information about the machine that created it?
Its documentation describes how. In a browser the fingerprint is derived from the user agent string, the supported media types, and a count of global variables, trimmed to four characters. On a server the first four characters come from the process id and the hostname, so those values sit inside every id the library returns.
Is cuid still maintained and what should I use instead?
The readme's status line says it is deprecated for security and names a successor hosted under the same account. There is no release newer than January 2018, the manifest declares a version above any tag, and the most recent commit arrived in October 2026, so the repository is still being touched without being released.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paralleldrive-cuid)Star history chart for your README
[](https://hysenlabs.com/projects/paralleldrive-cuid)Was this useful?