cuid2 trades speed for unguessability and says so in its own documentation
The most secure, collision-resistant ids optimized for horizontal scaling and performance.
At a glance
- What is it?
- paralleldrive/cuid2 generates identifiers by combining several independent entropy sources and hashing them with Sha3, rather than trusting one random function. The consequences ripple outward: the library is small but not fast, ids are not sortable, and the test suite is two Node scripts rather than a framework.
- Who is it for?
- cuid2 fits a system where an identifier is exposed to a user and must not leak its size, its creation time or its neighbours, such as anything with a sequential public id. It does not fit a render loop or a database that wants monotonic keys, and the documentation names both alternatives for those cases.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 95 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
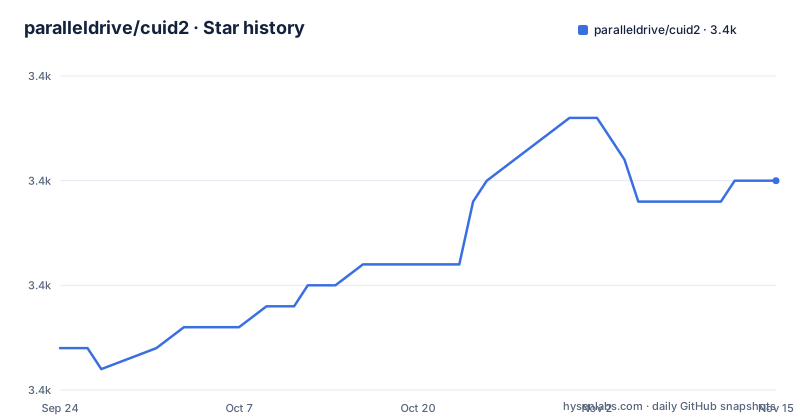
- paralleldrive/cuid23,410 ★ · +8
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| paralleldrive/cuid2 | 3.4k | 3.4k |
8 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four files are published from a much larger tree
The manifest lists four files as the published surface: the main source module, a root entry file, a declaration file, and the command line entry point. Everything else in the repository is development material. The package is a module by type, exposes a single root export alongside the manifest itself, and declares a binary whose name is cuid2. The repository, though, is far larger than the package and contains a Next.js site, since there is a Next configuration, a pages directory, a styles directory, a design system file and a public directory. So the same tree serves as a playground or documentation site and as the library source, and the packaging step is what separates them. That split is why the published files are listed individually rather than being covered by a broad glob.
npm install --save @paralleldrive/cuid2import { createId } from "@paralleldrive/cuid2";
const ids = [
createId(), // 'tz4a98xxat96iws9zmbrgj3a'
createId(), // 'pfh0haxfpzowht3oi213cqos'
createId(), // 'nc6bzmkmd014706rfda898to'
];A fingerprint is the only defence against cross-host collision
The scalability claim is that ids can be generated on multiple machines without coordination. That only holds if two hosts cannot produce the same id, and the mechanism offered is a host fingerprint. The configuration function takes a fingerprint described as identifying the host environment, used to help prevent collisions when generating ids in a distributed system, and it is optional, since every property of that function is optional. The same function also accepts a custom random function with the same interface as the built-in one, which is the documented way to supply a cryptographically secure source, and a length. It returns a configured factory rather than mutating global state, so two subsystems in one process can hold different configurations without interfering.
import { init } from "@paralleldrive/cuid2";

// The init function returns a custom createId function with the specified
// configuration. All configuration properties are optional.
const createId = init({
  // A custom random function with the same API as Math.random.
  // You can use this to pass a cryptographically secure random function.
  random: Math.random,
  // the length of the id
  length: 10,
  // A custom fingerprint for the host environment. This is used to help
  // prevent collisions when generating ids in a distributed system.
  fingerprint: "a-custom-host-fingerprint",
}
The collision figure is arithmetic, not a benchmark
The documentation does not say ids are unlikely to collide. It says how unlikely, and shows the working. Reaching a fifty percent chance of a collision takes roughly four quintillion generated ids at the default length, and the figure is given as the square root of thirty-six to the power of twenty-four minus one, multiplied by twenty-six. That is a birthday-problem calculation over the default length of twenty-four characters, which is also why the length is configurable and why the arithmetic changes when you change it. The point of publishing the formula rather than a promise is that a reader can check the claim for their own id space instead of trusting a slogan.
cuid2 [count] [options]

Arguments:
  count              Number of IDs to generate (default: 1)

Options:
  --slug             Generate a short 5-character ID
  --length <n>       Custom ID length (default: 24)
  --fingerprint <s>  Custom fingerprint for ID generation
  --install          Install shell alias 'cuid' → 'npx @paralleldrive/cuid2'
  --help, -h         Show help message
Being slow on purpose is written into the feature list
The seventh bullet in the feature list is a warning rather than a benefit, and it is the most revealing line in the documentation. If you can hash too quickly, you can launch parallel attacks to find duplicates or to break entropy-hiding. For unique ids, the documentation says the fastest runner loses the security race. That is a direct rejection of the usual optimisation instinct: a faster id generator is a less safe one, because throughput is exactly what an attacker needs to search the space. The same bullet sits next to the size claim, which is that the whole library is less than five kilobytes gzipped with no asynchronous operations and no user-noticeable delay, so the deliberate cost is bounded and stated. Two other features sit in the same list and constrain where this belongs. Ids are URL and name friendly because they contain no special characters, and they can be generated without a network connection, which is what lets a client create a record identifier before it has any connectivity at all.
The CLI installs an alias into your shell profile
The command line tool has a recommended setup step and it is not trivial. An install flag adds a shell alias to your zsh profile, and the documentation tells you to source that file afterwards, at which point a short command stands in for the long one. Note the two names: the binary in the manifest is cuid2, while the alias it writes is cuid, so the help text is displayed under a name the package does not register. Beyond that the tool is a count plus flags. A count generates that many ids. A slug flag switches to a five character id. A length flag overrides the default of twenty-four, and a fingerprint flag tags output with a host value so you can confirm the distributed setup is doing what you think. Two flags can be combined, which the examples show with a length and a fingerprint together.
npm test runs two node scripts rather than a framework
The test script sets a test environment variable and runs two JavaScript files directly with node, one covering the library and one covering the binary, with no test runner in the command line at all. A second script, for colour output, has a command body identical to the first, so it is a duplicate entry rather than a variant. Two further scripts exist as separate entry points: one for a collision test and one for a histogram, both of which look like analysis tools rather than assertions. The watch script chains three tasks, running the tests, then the linter, then a type check, over the source directory. That type check is unusual: it invokes the compiler through a package runner, points it at the test file itself with flags that allow and check JavaScript, and prints a completion line when it succeeds.
The manifest still addresses the pre-organisation repository
The package is scoped to one organisation and the repository lives under that same organisation, but the repository url, the bug tracker url and the homepage in the manifest all address a different account entirely, an earlier home of the project. That is not a broken link so much as a record of the move, and it means a reader who clicks through from the manifest lands on a mirror of the history rather than the current tree. The rest of the root is unconventional for a library. There is a git hooks directory wired up as a prepare step, a release script, a release configuration, and a set of planning and activity files at the top level together with a directory named for an assistant and a Cursor rules file. The repository is not archived, its recorded last push is 2026-08-12, and it has no tagged releases despite publishing to a registry.
Editorial conclusion
cuid2 fits a system where an identifier is exposed to a user and must not leak its size, its creation time or its neighbours, such as anything with a sequential public id. It does not fit a render loop or a database that wants monotonic keys, and the documentation names both alternatives for those cases. Before adopting it, read the collision arithmetic rather than the adjective, decide whether your machine's random source is the one you want, and note that the manifest's repository links still address the pre-organisation location of the project.
Frequently asked questions
What is the difference between a UUID and a Cuid?
The project's stated aim is stronger uniqueness guarantees than any existing GUID or UUID implementation, plus protection against leaking anything about the referenced data or the system that generated the id. Mechanically it differs by combining several independent entropy sources and hashing them with Sha3 rather than relying on one random source, and by refusing to be fast enough to attack in parallel.
cuid2 vs cuid
Cuid2 is a separate package and a separate id standard rather than a drop-in replacement. The documentation says the changes are significant and could disrupt projects relying on the previous generation, which is why a replacement library was created, while noting the original was used in thousands of applications for over a decade with no confirmed collision reports.
How do I generate ids with cuid2 in code?
Import the factory function and call it. For custom behaviour, pass a configuration object to the init function, which returns a configured factory; its properties are a random function with the same interface as the built-in one, an id length, and a host fingerprint. A validation helper checks whether a string is one of these ids.
What does the cuid2 command line tool do?
It generates ids from a shell. It takes an optional count, a flag for a five character slug id, a length flag whose default is twenty-four, a fingerprint flag, and a flag that installs a shell alias into your profile pointing at the long invocation. Without the alias you can call the package with a package runner.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paralleldrive-cuid2)Star history chart for your README
[](https://hysenlabs.com/projects/paralleldrive-cuid2)Was this useful?