lollms_hub: a gateway where the manifest and the requirements file disagree
A proxy server for multiple ollama instances with Key security
At a glance
- What is it?
- LoLLMs Hub is a FastAPI gateway that puts Ollama, vLLM, llama.cpp and OpenAI-compatible APIs behind one key-secured interface, with routers, ensembles and a master hub pattern for chaining instances. The packaging is where the surprises are: three release lines running 17, 8 and 9 while the manifest says 10.0.0, and a requirements.txt that pins numpy 1.26.4 and cryptography 42.0.8 against a pyproject.toml asking for numpy 2.x and cryptography 46.
- Who is it for?
- Use this if you run several inference backends and want one authenticated entry point with routing in front of them, since the Ollama and OpenAI compatible API is what lets hubs chain. Skip it if you need a reproducible environment, because the two dependency manifests disagree by a major version on numpy and cryptography and the Docker build resolves fresh rather than from the lock file.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
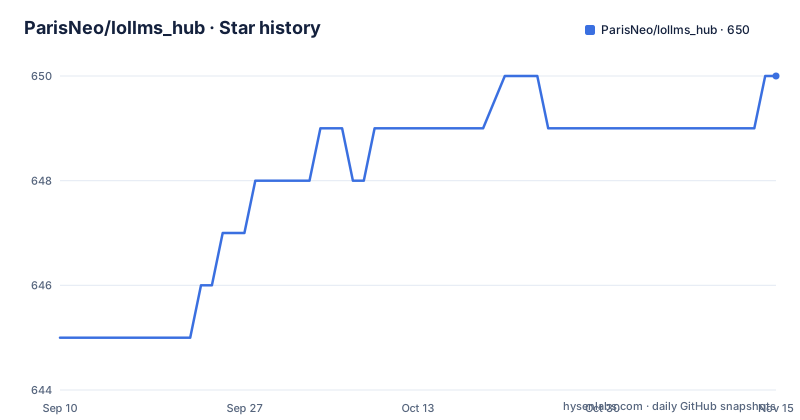
- ParisNeo/lollms_hub650 ★ · +5
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| ParisNeo/lollms_hub | 645 | 650 |
5 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three release lines, and the manifest says 10.0.0 while the last tag is v9.0.0
The version history is not a single line. The oldest of the three recorded releases is v17.1.0 from 2025-09-04, named as the last stable version before the full revamp. Two days later comes v8.0.0. A month after that comes v9.0.0 on 2025-10-31, and the latest.
So the numbering went from 17 to 8 to 9, and the pyproject.toml in the repository root declares version 10.0.0, which has never been tagged. A version-sorting tool looking at this repository sees three major lines and a fourth that exists only in the manifest.
The manifest version is also not the manifest name. The package is called lollms-hub while the distribution directory is lollms_hub, so the hyphenated and the plain form each appear in a different place.
The last recorded push is 2026-04-23 and the repository is not archived, so the gap between the newest tag and the newest commit is about six months. Nothing in the release list explains what happened after v9.0.0.
requirements.txt and pyproject.toml disagree on numpy and cryptography by a major version
The project ships two dependency manifests and they are not in agreement. The Poetry block in pyproject.toml requires numpy at 2.3.4 or newer within the 2.x line and cryptography at 46.0.5 or newer. The requirements.txt pins numpy 1.26.4 and cryptography 42.0.8.
Neither of those is a patch-level drift. Both are different major versions of the same two packages, and an environment built from the two files in sequence resolves to whatever it resolves to rather than to what either author intended.
Two more of the same kind are milder. python-multipart is 0.0.22 or newer in the manifest and 0.0.18 in the file, and safe-store is at least 0.2.1 in the manifest and at least 3.4.2 in the file, which is a large gap on the same 0.x-to-3.x axis.
The four lines that disagree, exactly as the file has them:
cryptography==42.0.8
numpy==1.26.4
python-multipart==0.0.18
safe-store>=3.4.2
Because the Docker image installs from pyproject.toml and never reads requirements.txt, the container runs the newer set while a local setup from the file runs the older one. That is a reproducible way to get different behaviour from the same commit.
scikit-learn appears twice in both manifests, under two spellings
One dependency is listed in duplicate. The Poetry block has scikit-learn at 1.5.0 or newer and then scikit_learn at 1.5.0 or newer, with the plain name written out as a separate entry. The requirements.txt file has scikit-learn pinned to 1.5.0 and then scikit-learn unpinned further down the list.
The two names normalise to the same distribution, so this is not two packages competing. It is one package requested twice, once constrained and once not, in both files.
The unpinned second entry is the part that costs something. Whichever resolver reads the file top to bottom, a later unpinned requirement can widen the set the earlier exact pin established, which is why the effective version is not necessarily 1.5.0.
The same pattern of duplication appears in how the file ends. Several packages at the bottom are listed with no version constraint at all, including requests, pandas and matplotlib, so the lower half of requirements.txt is looser than the upper half even though both were written as the same file.
Four linters are all configured to let a 180-character line through
The development dependency group is long and the tooling configuration is where the project's actual conventions live. It pulls black, flake8 with three plugins, pylint and ruff, plus tox with a GitHub Actions bridge, bandit and safety.
All four formatters and linters are set to the same line length. black has line-length 180, ruff has line-length 180, pylint has max-line-length 180, and pylint additionally has C0301 through C0305 in its disable list, which are the line length messages themselves.
Disabling the pylint line length checks while setting a line length for pylint anyway is belt and braces rather than a contradiction, but it does mean no tool in the chain will complain about a long line. flake8 has no configuration visible in either manifest, so its effective limit is the default unless something is passing a flag.
The security side is two tools. bandit looks for Python security issues in the source and safety checks the installed dependencies, which matters here because the project proxies model traffic and handles admin credentials.
The image builds with poetry, ships no dev dependencies, and runs gunicorn on 8080
The Dockerfile is a two-stage build on python:3.13-slim. The builder installs build-essential, pkg-config, libcairo2-dev and python3-dev, then installs poetry itself, copies only pyproject.toml, and runs poetry install with the dev group excluded and the root package skipped.
Copying only the manifest and not poetry.lock is the notable decision. It means the image resolves dependencies fresh at build time rather than reproducing the locked set, so two builds of the same commit can install different versions of an unpinned package.
The runtime stage copies the builder's Python 3.13 library directory and bin directory across, installs libcairo2 as a runtime library rather than the development package, and installs gunicorn separately. It creates ./app/static/uploads, ./.ssl and ./benchmarks, drops to a system user called app, exposes port 8080, and starts gunicorn against app.main:app with gunicorn_conf.py supplying the configuration.
There is no compose file at the root, so the port mapping and any database are left to whatever is orchestrating it.
A slave hub exists so the master sees one entry instead of dozens
The architecture treats inference engines as swappable compute nodes, and the supported backends are Ollama, vLLM, llama.cpp through an internal binary hub, and any OpenAI-compatible API. Because the API is fully compatible with both Ollama and OpenAI, hubs can be chained into a master and slave arrangement.
Three reasons are given for putting a hub on the worker rather than pointing the master straight at the instances. The slave handles spawning local processes on that machine. The master then sees a single Remote Server entry instead of dozens of raw instances. And only the master needs public access, because slaves can stay on a private VPN or VLAN.
The second reason is the operational one. A master that registers each GPU instance separately needs to know how to start, stop and health check each of them remotely, which a hub on the worker already knows how to do locally.
The example topology in the README mixes form factors deliberately: a Windows gaming PC with two GPU-backed Ollama instances, a Linux server running Ollama as a service, and a cloud node running vLLM or an OpenAI API, all behind one master.
Five reset scripts sit at the root next to a purge utility
The repository root has an unusual cluster of recovery scripts. There are reset.bat and reset.sh, reset_admin_password.bat and reset_admin_password.sh, and reset_admin_password.py, plus purge_bloat.py. That is five files whose only job is putting state back.
Having both .bat and .sh for the same operation is consistent with the Windows and macOS or Linux installer split, where run_windows.bat and run.sh cover the two platforms. The odd one out is the .py variant, which suggests the password reset is also reachable from inside the application rather than only from a shell.
purge_bloat.py is the exception and the name is doing the work. It is not a reset, it is a cleanup, and a project that ships one usually has a reason: models, uploads and logs accumulate in the volume the container mounts, and the static uploads directory created in the Dockerfile is where that happens.
The rest of the root is ordinary project furniture: an .env.example alongside pydantic-settings, a tox.ini, tests/, docs/, benchmarks/, a package.json for the frontend, useful_scripts/, and both a .github directory and a .gitlab-ci.yml, so CI is defined for two different platforms.
Step 6 of the setup walkthrough appears twice, word for word
The setup walkthrough at the end of the README goes through seven steps, and step six is printed twice in full. Both copies carry the same heading about creating intelligent model orchestration and the same two paragraphs about Smart Routers and Ensembles, with nothing between them.
This is a small defect but it is the kind that signals the page was assembled from sections rather than edited as a whole. The other steps are numbered one through seven correctly apart from the repeat, so the numbering still reaches seven.
The duplicated step covers the two orchestration features. Smart Routers build hierarchical routing logic with three strategies, priority, random and least loaded, and decision rules evaluated from the top down. Fast rules match on keywords, regex patterns, message length, image detection and specific users; semantic rules fall back to a small LLM classifying intent when patterns are not enough. Ensembles run several agents in parallel and hand the results to a master model that synthesises them.
A vision router is described as a four-step operation: pick a text model, pick a vision model, give it a name, and then use that name like any other model.
Editorial conclusion
Use this if you run several inference backends and want one authenticated entry point with routing in front of them, since the Ollama and OpenAI compatible API is what lets hubs chain. Skip it if you need a reproducible environment, because the two dependency manifests disagree by a major version on numpy and cryptography and the Docker build resolves fresh rather than from the lock file. Before you deploy, decide which manifest is authoritative for you, and note that the release numbering restarted, so the newest tag is not the highest number.
Frequently asked questions
How do I install LoLLMs Hub?
Clone the repository, change into the lollms_hub directory, and run the installer for your platform. On Windows you double-click run_windows.bat. On macOS or Linux you make run.sh executable with chmod +x and run ./run.sh. The first run takes you through a setup wizard where you create the admin credentials. To stop the hub, close the terminal window or press Ctrl+C.
How does LoLLMs Hub secure its traffic?
In the Settings then HTTPS/SSL menu there are two options. You can upload key.pem and cert.pem directly through the UI and the hub handles the rest, or provide the full file paths if the certificates are already on the server, for example managed by Certbot. Either way a server restart is required to apply the change.
Can I run several LoLLMs Hub instances together?
Yes, and that is the master hub pattern. The API is fully compatible with both Ollama and OpenAI, so hubs can be chained. A slave hub spawns local processes on the worker machine, the master then sees one Remote Server entry instead of dozens of raw instances, and only the master needs public access because slaves can stay on a private VPN or VLAN.
What routing strategies does LoLLMs Hub support?
Three. Priority always tries the first model and falls back to the second if unavailable. Random gives even distribution across large clusters. Least Loaded routes to the backend with the lowest active request count. Decision rules are evaluated from the top down, with fast pattern rules first and semantic rules using a small LLM when pattern matching is not enough.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/parisneo-lollms-hub)Star history chart for your README
[](https://hysenlabs.com/projects/parisneo-lollms-hub)Was this useful?