patroni's REST API can go deaf while everything else reports healthy
A template for PostgreSQL High Availability with Etcd, Consul, ZooKeeper, or Kubernetes
At a glance
- What is it?
- patroni is a Python template for running PostgreSQL in a high-availability cluster, driven by a distributed configuration store. Its documentation is unusually forthcoming about a failure mode that would otherwise be baffling: on a recent Python with strict memory limits, the control plane's HTTP interface stops answering while the process looks fine, the database keeps running, and the logs stay clean. The fix spans a binary upgrade, two environment variables and three settings, and one of those settings cannot do what its name suggests.
- Who is it for?
- patroni fits a team that wants a quorum-based orchestrator with the design left open, rather than a distributed database that makes the decisions for them, and that is prepared to read its documentation rather than just its examples. It does not fit an environment where you cannot set allocator environment variables on the process, because part of the documented remedy requires exactly that.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
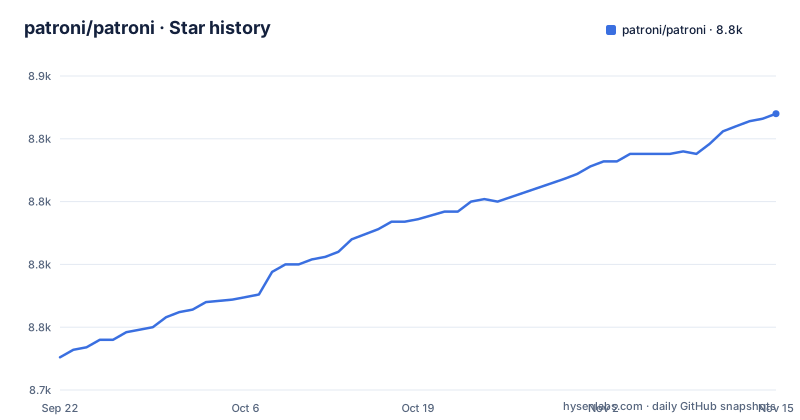
- patroni/patroni8,835 ★ · +97
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| patroni/patroni | 8.7k | 8.8k |
97 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The REST interface can stop answering while nothing looks wrong
There is a section on a memory issue, and it lists the symptoms rather than the cause first. The orchestrator appears healthy. The database continues to run. The interface becomes unresponsive. The operating system reports that the port is being listened on. The logs look normal, except that a line about an ignored exception in a thread may appear once. Consequence: four of the five signals are reassuring, so the only way to notice is to have read this section or to go looking in the kernel log, which the documentation also points at. That is a genuinely useful piece of writing, and it is also an admission that the failure presents as a hang rather than as an error. The cause is given as a known interpreter issue rather than a project defect: under strict memory conditions, starting a new thread may hang indefinitely when there is not enough free memory. That matters for how you read the section, because it means the orchestrator is not failing to do its job. It is failing to accept work, which is why the database keeps serving while the process that decides who may serve stays silent.
The documented fix is a binary, two variables and three settings
The remedy comes in three layers. Recent releases on both maintained lines reduce the impact by starting the threads they need early, before memory pressure builds. Then, for the allocator, two environment variables are recommended. Then three configuration parameters, each with its default stated: a thread stack size whose default is stated as sufficient unless you are seeing stack-related crashes, a pool size stated as sufficient for a three-node cluster, and a pool size for the HTTP interface that allows five parallel requests. Consequence: the fix is not one action, and the defaults are given as sufficient for a specific cluster size rather than as generally correct. Anyone running a larger cluster is extrapolating from numbers the documentation scopes to three nodes.
One concurrency setting cannot parallelise the requests that matter
The last of those three settings is the size of the pool used to process interface requests, and its default allows five in parallel. The documentation then qualifies it: requests involving SQL queries are effectively serialised because a single database connection is used. Consequence: a setting that reads like adding capacity cannot add it for requests involving SQL queries. The note is honest, and it limits how far that setting can help those requests.
The bootstrap and replica tools are not part of the install
The dependency section is thorough, listing an extra for each supported configuration store and a set of extras for the database driver. At the end there is a single sentence that undoes some of that confidence: external tools used by the bootstrap or replica-creation scripts, naming one example, must be installed separately. Consequence: a base install gives you the orchestrator and none of the external binaries its own scripts invoke. That failure lands at the moment you create a replica or restore a backup, which is the worst possible moment, and only one of the tools is named so the rest are yours to discover by reading scripts.
The two lists of extras do not match each other
The readme lists dependency groups: one or two names for each of four configuration stores, one for a Raft implementation, one for cloud callbacks, one for a notification mechanism, one that pulls in all of them except the driver family, and three for the driver itself. The packaging script has its own mapping. In that one the Kubernetes group is an empty list, the Raft group also pulls in a cryptography library, and there is a JSON logging group the readme's extras list does not include. Consequence: the extras you install by name depend on which of the two documents you read. In the packaging script the Kubernetes group installs nothing, while the readme says it installs the kubernetes library.
Which Consul client you get depends on your interpreter
The requirement file lists one dependency three times, each with a different version range and a different interpreter marker. Consequence: two operators running the same build of the orchestrator on different interpreter versions install different versions of the configuration-store client, and the difference is invisible until that client breaks against a server change. It is the only place in the file where the dependency set is a function of the environment rather than of the project, and it is the kind of thing that makes a build matrix worth writing down.
The example cluster configuration sits at the repository root
The quick start tells you to open three terminals, start the configuration store with a data directory flag, and then run the orchestrator twice against two files whose names are a node index and a configuration extension. Those three files are committed at the top level of the repository, alongside a compose file and a matching set for the distributed-database variant, plus a second container definition. Consequence: the files are an example, but they sit where a reader assumes a project's own configuration lives, and they are complete enough to run. That combination is how example configuration ends up in production with the demo node names and the tutorial token still in it. The compose file that runs all of this in containers needs an image built first, which is stated in a comment at the top of it, and it configures three store nodes with an explicit initial token. Reading the example as a template rather than as something to copy is the safer default here.
The project changed hands without being re-initialised
The readme says the project was formerly known by its original sponsor's name and that it started as a fork of an earlier orchestrator. The packaging script lists two authors, one with an address at one employer and one at the original sponsor, and its keyword list still contains the name of the project it was forked from alongside the current one. Consequence: none of that is wrong and all of it is a signal. The keyword list is what a package index matches a search against, so a fork's former name is still doing work, and the author addresses still include one at the original sponsor. Worth knowing before you assume a question will reach whoever now owns it.
Editorial conclusion
patroni fits a team that wants a quorum-based orchestrator with the design left open, rather than a distributed database that makes the decisions for them, and that is prepared to read its documentation rather than just its examples. It does not fit an environment where you cannot set allocator environment variables on the process, because part of the documented remedy requires exactly that. It also does not fit a plan that treats the REST interface as a scalable control plane, because one of its documented concurrency knobs cannot parallelise the requests that matter. Before deploying, read the memory section before the tuning section, install the bootstrap and replica tools by hand, and check which of the two extras lists you were reading when you chose your extras.
Frequently asked questions
What is a patroni?
A Python template for building PostgreSQL high-availability clusters. It orchestrates a set of database nodes using a distributed configuration store to decide who leads, supporting ZooKeeper, etcd, Consul and Kubernetes, and it describes itself as a template rather than a finished distributed database, so the design decisions stay with the operator.
how to install patroni
Through the package index, with a dependency group chosen by name, for example a group covering a driver plus one configuration store plus cloud callbacks. The driver itself is a separate choice because recent versions of one driver no longer ship a binary package by default, which means installing it can require a C compiler. External tools used by the bootstrap and replica scripts must also be installed by hand.
what is patroni in postgresql
It is an external orchestrator, not a PostgreSQL extension. A separate process watches the nodes and keeps one of them as the writable leader using a distributed configuration store, restarting and promoting as needed. There is a companion integration for a distributed database extension that has been part of the project since version three.
how to setup patroni cluster
The minimal form is three terminals: start the configuration store with a data directory, then run the orchestrator against two configuration files. The documentation ships three such files at the repository root so you can add more nodes by adding files. A container-based three-node cluster with a three-node store and a load balancer is also provided, and requires building an image first.
patroni vs pgbouncer
The repository does not compare them, because they solve different problems: one is a connection pooler and the other an orchestrator that decides which database node is writable. What the readme does say is that the orchestrator exposes an HTTP interface whose request pool is effectively serialised for anything touching SQL, because a single database connection is used, which is the opposite of what a pooler is for.
patroni vs repmgr
There is no comparison in the repository. What it does record is its own history, that it began as a fork of an earlier orchestrator and adds support for more modern availability patterns, and that it supports PostgreSQL versions from 9.3 through 18 with a distributed configuration store doing the leader decision.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/patroni-patroni)Star history chart for your README
[](https://hysenlabs.com/projects/patroni-patroni)Was this useful?