openTSNE ships two t-SNE algorithms behind one API, and the newest release predates two years of commits
Extensible, parallel implementations of t-SNE
At a glance
- What is it?
- pavlin-policar/openTSNE compiles Cython extensions, defaults to FIt-SNE over Barnes-Hut, treats FFTW3 as an optional accelerator, and last published a release in August 2024 while its master branch has been pushed to since September 2026.
- Who is it for?
- openTSNE is the right shape of tool when you need t-SNE beyond a single embedding, because it separates the neighbour approximation, the optimization and the embedding of new points instead of hiding them behind one fit call, and it can place new data into an existing embedding. Before you commit to it, check three things against your own environment.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
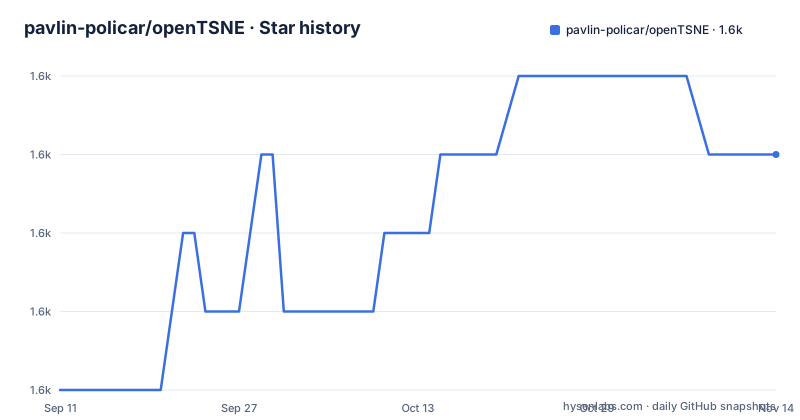
- pavlin-policar/openTSNE1,625 ★ · +3
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| pavlin-policar/openTSNE | 1.6k | 1.6k |
3 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two algorithms sit behind one import, and the default decides which paper you cite
The package exposes a single `TSNE` class and, behind it, two different implementations of neighbour embedding. FIt-SNE, interpolation based, is the default. Barnes-Hut, the tree based approximation from 2014, is the alternative. The citation note treats this as a real choice rather than an implementation detail: it asks you to cite the original authors of whichever algorithm you use, so FIt-SNE points at Linderman and colleagues in Nature Methods, while Barnes-Hut points at van der Maaten and at Yang and colleagues. The library's own citation is separate, a Journal of Statistical Software article from 2024.
The interface stays small. Loading a data set through scikit-learn and fitting it is three lines:
from sklearn import datasets

iris = datasets.load_iris()
x, y = iris["data"], iris["target"]

from openTSNE import TSNE

embedding = TSNE().fit(x)
What the algorithm choice buys you is scale and the ability to add points to an embedding that already exists, which is the improvement the project credits to a 2021 paper on embedding into a reference t-SNE space to address batch effects. The global alignment tricks it lists, credited to Kobak and Berens, are what the mouse retina example uses.
The last release is v1.0.2 from August 2024 and the branch moved on in 2026
Three releases are visible: v1.0.0 on 2023-05-24, v1.0.1 on 2023-11-29 and v1.0.2 on 2024-08-13. The default branch is `master`, the repository is not archived, and its most recent push is dated 2026-09-08. That leaves more than two years of commits with no release attached to them, and the README carries no changelog or unreleased section to say what those commits contain. Nothing in the project page states a minimum or maximum version, so a `pip install opentsne` gives you v1.0.2 and the branch you would get from a source install is something else entirely.
The README itself is a reStructuredText file, `README.rst`, not Markdown, and it carries two typos in its opening description: the algorithm's name is written with a missing letter in Stochasitc, and the figure caption under the mouse retina embedding misspells alignment as aligment. Small things, but they are a fair signal about how much editorial attention the text has had relative to the code. The build badge points at Azure DevOps under the account `pavlingp`, while the repository lives under `pavlin-policar`, so the two hosting identities do not match.
FFTW3 is optional, and its absence costs you speed without telling you
The install notes call FFTW3 something you may also consider installing before you build. It implements the Fast Fourier Transform, which the project says is heavily used inside openTSNE. The fallback is numpy's own FFT implementation, which the notes describe as slightly slower than FFTW, and they add that the difference is only noticeable with large data sets containing millions of data points.
What makes this worth knowing is the shape of the degradation rather than its size. There is no error, no warning and no message in the output: on a data set of a few thousand points the two paths produce the same picture and the same wall clock, so nothing tells you which one you are on. By the time the difference is visible you are already in the millions of points regime the notes describe, and installing FFTW3 then means rebuilding. The three installation routes are otherwise equivalent in effort, conda from conda-forge, pip, or a source build from the root directory.
conda install --channel conda-forge opentsne
pip install opentsne
pip install .
The third one is the source route and it is the only one that compiles anything.
Threading needs OpenMP, and older clang on OSX is the named exception
Running openTSNE on more than one thread depends on the compiler, not on a setting you pass at runtime. The install notes say the C/C++ compiler must support OpenMP for the library to use multiple threads, and they add that in practice almost all compilers implement it, with the exception of older versions of clang on OSX systems. So the performance claim and the threading behaviour are properties of the machine you built the extension on, and a wheel built by one compiler can behave differently from a local build on another.
That is also why a compiler is a hard requirement rather than a recommendation. The source route is documented as running `pip install .` in the root directory, which installs the appropriate dependencies and compiles the necessary binary files, and the project asks for a C/C++ compiler to be available on the system first. The build system declaration is short:
requires = ["setuptools", "wheel", "cython", "numpy"]
build-backend = "setuptools.build_meta"
Cython in that list is the reason a plain Python environment is not enough. The extensions are generated at build time, so an install that cannot compile produces no working package rather than a slow one, and the difference between a source install and an index install is exactly this step.
setup.py reaches into distutils for the compiler configuration
The build script imports the compiler machinery from the standard library and Cython's own layer on top of it.
import distutils
from distutils import ccompiler
from distutils.sysconfig import customize_compiler
from distutils.errors import CompileError, LinkError
from Cython.Distutils.build_ext import new_build_ext as build_ext
`new_build_ext` is Cython's replacement build extension, so the binary modules are Cython sources compiled at install time rather than prebuilt objects shipped in the package. The custom compiler object is then customised through `customize_compiler` from `distutils.sysconfig`, and the two exception types it imports are the ones the build catches. The include search is built from `sys.prefix` and probes two layouts:
return (
    os.path.join(sys.prefix, "include"),
    os.path.join(sys.prefix, "Library", "include"),
)
The second path is the Windows arrangement of a prefix, the first the Unix one, so the same build covers both. Worth pairing with the install section's claim that openTSNE works on all supported Python versions: that claim rests on this script working on each of them, and the script's first import is `distutils`.
The notebook conversion step covers four examples and pulls in nbconvert at run time
`setup.py` defines its own distutils command, `ConvertNotebooksToDocs`, whose only job is turning the example notebooks into reStructuredText for the documentation. It imports nbconvert inside the command's `run` method rather than at module level, then walks a hardcoded list of four notebooks.
files = [
    join("examples", "01_simple_usage.ipynb"),
    join("examples", "02_advanced_usage.ipynb"),
    join("examples", "03_preserving_global_structure.ipynb"),
    join("examples", "04_large_data_sets.ipynb"),
]
target_dir = join("docs", "source", "examples")
Two things follow from that. The `examples/` directory holds more notebooks than the list: there is a fifth on animation plus two preparation notebooks for the 10x and Macosko data sets, and none of those three are converted. And nbconvert is imported lazily, which means it is not in the build requirements declared in `pyproject.toml`, so running this command on a clean checkout fails at the import unless you installed nbconvert yourself. The output goes to `docs/source/examples` with a directory per notebook name.
The examples tree also carries its own `.gitignore`, a `utils.py` and `__init__.py`, and separate `data/`, `docs/` and `figures/` directories, so the examples are treated as a small package with generated artefacts kept out of version control.
Continuous integration runs on Azure Pipelines, not on the forge that hosts the code
The build status badge resolves to Azure DevOps, and the repository carries two pipeline definitions rather than one, `azure-pipelines.yml` and `azure-pipelines-release.yml`, with a separate `azure-pipelines-release.yml` handling the publishing side. The badge URL pins `branchName=master`, matching the default branch, and the account in the path is `pavlingp` rather than the `pavlin-policar` that owns the repository.
The tree also separates concerns in a way that is worth knowing about when you file an issue. `benchmarks/` holds the performance work that the documentation links to as a speed benchmarks page, and `notes/` sits alongside it as a separate directory for working material. `tests/` is the test suite, `docs/` is built by readthedocs through `readthedocs.yml`, and `MANIFEST.in` sits next to `setup.py` and `pyproject.toml`, where the latter carries only the build system table and every packaging decision lives in the former.
The licence is BSD-3-Clause, matching the badge, and the project asks for two citations rather than one: the library article and the paper for the algorithm you actually used. Both requests are worth honouring, since the algorithm choice is a genuine fork in how the result was computed.
Editorial conclusion
openTSNE is the right shape of tool when you need t-SNE beyond a single embedding, because it separates the neighbour approximation, the optimization and the embedding of new points instead of hiding them behind one fit call, and it can place new data into an existing embedding. Before you commit to it, check three things against your own environment. The build is compiled from source and pulls in Cython, so a working C or C++ compiler and, for threading, OpenMP support are part of the cost. FFTW3 is optional and its absence is silent, so a small data set will look fine either way. And the newest release is v1.0.2 from 2024-08-13, well behind the current state of the branch, so pin a commit if you care about reproducibility.
Frequently asked questions
Which t-SNE algorithms does openTSNE implement?
Two: FIt-SNE, which is the default, and Barnes-Hut. The citation guidance asks you to cite the original authors of whichever you use, so FIt-SNE points at Linderman and colleagues in Nature Methods 16.3 (2019), while Barnes-Hut points at van der Maaten (2014) and Yang and colleagues (2013).
What does openTSNE need in order to install from source?
A C/C++ compiler on the system. Running pip install . in the root directory installs the dependencies and compiles the binary files, and the declared build system requires setuptools, wheel, cython and numpy, so the extensions are generated during the install.
Is FFTW3 required to run openTSNE?
No. The install notes present it as optional and say that without it openTSNE falls back to numpy's FFT implementation, which is slightly slower, with the difference only noticeable on data sets containing millions of points.
Will openTSNE use multiple threads on my machine?
Only if the compiler that built it supports OpenMP. The install notes say almost all compilers implement this, with the exception of older versions of clang on OSX systems, so the threading behaviour is fixed at build time rather than at run time.
How should I cite openTSNE in a paper?
The README carries a BibTeX entry for Policar2024 in the Journal of Statistical Software, volume 109, number 3, pages 1 to 30, with doi 10.18637/jss.v109.i03. It also asks you to cite the original authors of the algorithm you use.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pavlin-policar-opentsne)Star history chart for your README
[](https://hysenlabs.com/projects/pavlin-policar-opentsne)Was this useful?