pdfcpu: two reference readers decide what it can parse
PDF tooling for Go and the command line.
At a glance
- What is it?
- A Go library and command line tool covering about forty PDF operations, whose compatibility boundary is defined by whether a file opens in two well-known readers, whose validation support for the newest PDF version is described as basic, and whose container image installs the released binary rather than the checkout it was built from.
- Who is it for?
- pdfcpu suits a Go project that wants PDF validation, merging, page geometry and encryption in a library with few external dependencies, or a command line pipeline that batches those operations across files. It does not suit you as an authority on documents using the newest PDF version, since validation support there is described as basic and still improving.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
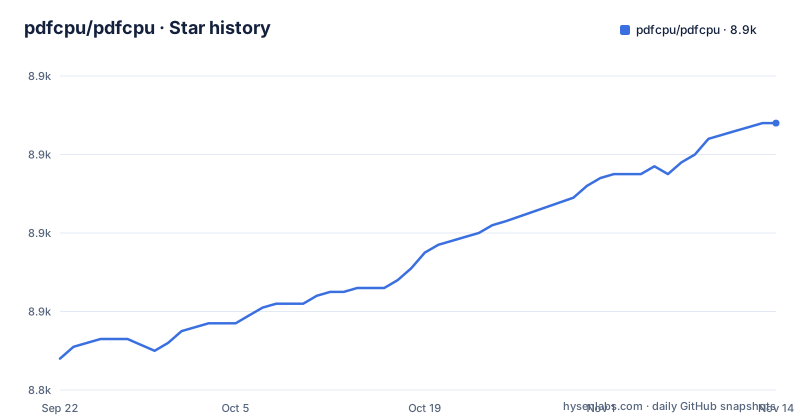
- pdfcpu/pdfcpu8,908 ★ · +60
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| pdfcpu/pdfcpu | 8.8k | 8.9k |
60 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two reference readers define the support boundary
The contributing section contains the most operationally useful paragraph in the project, and it is about triage rather than code. For deciding what counts as a defect, two applications are named as practical compatibility references: a commercial reader and the system preview tool. Reports are said to be most helpful when a file opens in one of those two but cannot be processed by this tool, because such cases point at gaps in validation or parser compatibility. And the corollary is stated just as plainly: if neither application can open the PDF, it is unlikely this tool will process it reliably. Consequence: you have a free way to decide whether a document is worth feeding to it, before you file a report or build a pipeline around the assumption that it will work.
The recommended first move is validation with verbose output:
pdfcpu validate -vv <file.pdf>which is the command the contributing section asks you to run before filing anything, alongside the command itself, its verbose output and a sample file.
Validation for the newest PDF version is called basic
The project states that it supports PDF versions through version 2.0 of the specification, then immediately qualifies that 2.0 validation support is basic and continuously improving. It is worth reading as a scope statement rather than a footnote. Consequence: for documents produced against the newer standard, this tool's validation verdict is the least reliable thing it can tell you. Validate before assuming a file is malformed, and if validation passes but a downstream consumer still complains, suspect the version gap rather than the file.
The plain form of the same command is the one-line example the usage section gives:
pdfcpu validate input.pdfso the two documented invocations are the quiet check and the diagnostic one, and you can use the second whenever a file behaves oddly.
Nine dependencies, and one of them belongs to the maintainer
The stated design goal is correctness and independence from external dependencies, and the manifest is consistent with that at first glance: nine direct requirements, three of them Go extended-library packages for cryptography, images and text, plus a terminal width helper, a command line framework, a YAML parser, a JSON schema library and a string preparation package. One entry is different. The TIFF library in the list is authored by the same person who maintains this project. Consequence: the independence claim holds well for the PDF core, since almost nothing here is a general purpose PDF library you did not choose. But the image handling path depends on code one person maintains, which is a different risk profile from a third-party dependency and worth naming rather than waving through. It is also not a criticism of the practice, just a different thing from a supply-chain risk you delegate.
The container installs the release, not your build
The image definition is short and has one detail that surprises people. The build stage starts from the current Go base image and installs the command from its module path at the latest tag. Only that binary is copied forward into a small runtime stage, with certificates and a C library compatibility package added, the working directory set, a volume declared, and the binary as the entry point. Consequence: an image built from your checkout exercises the upstream release, not your changes, which is the opposite of what someone building a container from a fork expects. It also means the image tracks the latest published tag at build time rather than a commit, so two images built a day apart can differ without any source change on your side.
The install line inside the build stage is where the surprise lives:
RUN go install github.com/pdfcpu/pdfcpu/cmd/pdfcpu@latestand the runtime stage then declares the binary as the entry point:
ENTRYPOINT ["pdfcpu"]The header comments show the intended invocations, including binding the current directory and passing a subcommand through to it.
Two coverage scripts, one named for running without a network
The repository root is small and the filenames carry information. There are two scripts for coverage, coverage.sh and offline_coverage.sh. There is an internal directory and a public package directory, so the split between what you may depend on and what you may not is enforced by the tree layout rather than by documentation. There is also no changelog file in the repository, even though a changelog is published on the project site. Consequence: the public surface is deliberately narrow, which is the right shape for a library, and the release history lives somewhere your tooling cannot diff, so tracking what changed between versions means reading a web page.
Password handling is two commands, not one
The command index runs to roughly forty entries and covers validation, page geometry, splitting and trimming, encryption, form handling, portfolios, annotations, stamps, watermarks, and a family of generation helpers for grids, booklets, posters and imposition. Within that, encryption is not one command: changing the owner password and changing the user password are separate entries with separate documentation. The signature area is worth reading carefully too, since the summary mentions signing among the supported operations while the feature list is narrower, describing validation of signature integrity, reporting of signature evidence, and removal of signatures. Consequence: the encryption surface is explicit rather than hidden behind a single verb, which is what you want from a tool that ends up in front of a compliance requirement, and the signature wording is a place to check the current documentation rather than assume.
Merging is the other usage example on the page, and it shows the argument order:
pdfcpu merge merged.pdf in1.pdf in2.pdfwith the destination first and the inputs after it.
The maintainer sits inside the standards body
One line of context sits directly under the description, and it explains a lot about the project's behaviour: the page notes that the maintainer is a member of the PDF Association, with a link to the association. Alongside it, the documentation links a security policy (SECURITY.md), and the contributing section restricts which sample PDFs you should submit with a report. Consequence: the maintainer's membership is context for the stated focus on correctness, and a published security policy suits a tool that reads untrusted files, which is the part that matters if you plan to feed it documents from outside your organisation.
Editorial conclusion
pdfcpu suits a Go project that wants PDF validation, merging, page geometry and encryption in a library with few external dependencies, or a command line pipeline that batches those operations across files. It does not suit you as an authority on documents using the newest PDF version, since validation support there is described as basic and still improving. Before adopting, run the verbose validation command against your real files to see where it stands, remember that the container pulls the released binary rather than your checkout, and decide whether depending on the maintainer's own imaging library is acceptable for you.
Frequently asked questions
How do you install pdfcpu?
Two separate routes are documented, one for the command line interface and one for using it as a Go API, each with its own installation page on the project site. The tool is a Go module, and the repository ships a container definition as a third option for running it without installing anything on the host.
How do you use pdfcpu?
From a shell you run subcommands, and the page gives two examples: validating a file by passing it to the validate command, and merging with the merge command taking the output path followed by the inputs. Every command has its own help, reachable by passing the command name with a help flag, and the fuller guides live on the project site.
How can I merge PDF files in Go?
Import this project as a Go module and use its API, whose documentation and examples are published both on the package site and as sample and test packages in the repository. From the command line the equivalent is the merge command, which takes the output path first and then the files to combine.
How can I parse a PDF file?
This project is the parsing and processing layer: it validates, optimizes and processes documents, with a Go API alongside the command line tool. For triage, the recommended first step is the validate command with verbose output, which prints what the parser found.
Is PDF Lib still maintained?
That question is about a different library, so it is worth being clear about which project this repository is. This one is written in Go, distributed as a module and a command line tool, licensed under Apache 2.0, and its most recent tagged release is v0.16.4.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pdfcpu-pdfcpu)Star history chart for your README
[](https://hysenlabs.com/projects/pdfcpu-pdfcpu)Was this useful?