destroylist recommends a smaller verified list over its biggest one
Real-time phishing & scam domain blocklist, 190k+ curated threats, 888K+ community, free API, multiple formats.
At a glance
- What is it?
- A phishing and scam domain blocklist that publishes seven feeds across six resolver formats, with a free API and an appeals process. The design decisions worth reading are the ones that argue against the obvious choice: the production recommendation is the verified list rather than the largest, the allowlist is maintained by hand, and every URL pins a moving branch.
- Who is it for?
- This is a well built blocklist, and the strongest signal is that it tells you to take a smaller list. If you are deploying this, start with the feed the page recommends for production rather than the one with the most entries, and pair it with the allowlist so a false positive on a partner domain does not cost you a service.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
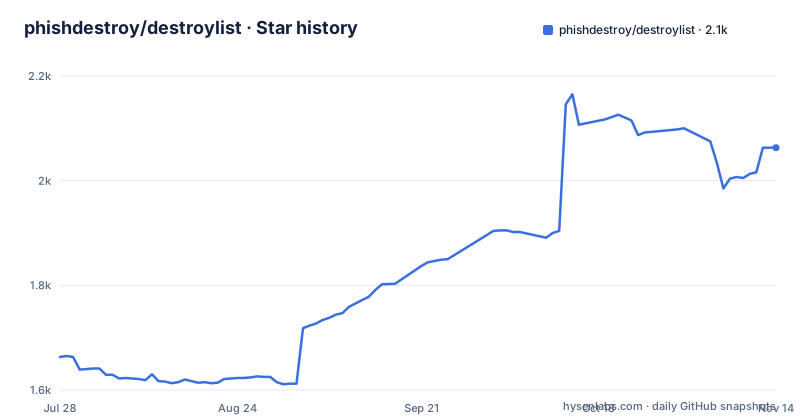
- phishdestroy/destroylist2,063 ★ · +400
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| phishdestroy/destroylist | 1.7k | 2.1k |
400 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Seven feeds are cut along three different axes
The feed table is the centre of the project and it is organised more carefully than most blocklists.
The first axis is provenance. The primary feed is described as curated, while the community feed is described as aggregated from more than a dozen sources. That is a difference in kind, not just in size.
The second axis is verification, and it is applied in stages. One feed is described as verified through DNS, which means each domain resolved when it was checked. Two more add HTTP content verification on top. So there is a curated set, a curated set that resolves, a curated set that resolves and responds, and an aggregated set with the same two verification stages applied.
The third axis is freshness, and it is inconsistent by design. One feed updates in real time, another every two hours, another every twelve, others every twenty four.
That gives seven feeds plus an allowlist. Anyone choosing one needs to decide whether they want breadth or certainty, and the table makes that a real choice rather than a default.
The production recommendation is the smaller list
The page gives a deployment tip that argues against the obvious choice.
It names two files for production use and describes one of them as a verified feed. It then offers a different file as maximum coverage, and points at the root lists for firewall and resolver use. The recommended production file is the DNS-verified one. The maximum coverage file is the aggregated one.
So the guidance is: take the list that was checked, not the list that is biggest.
That is a deliberate position and it has a cost. A curated and verified list will miss threats that an aggregate catches, which is the tradeoff the coverage option exists to serve. But a blocklist that blocks a domain which no longer resolves is blocking a name that an attacker may still register and use later, and false positives on a shared hosting domain are the failure mode that gets a list switched off.
The tip also says the comprehensive option is for maximum coverage rather than for production, which is an unusual thing for a list vendor to say about its own largest file.
Every feed URL pins a moving branch
The one click installation is a URL pasted into a resolver's blocklist settings.
That URL points at a content delivery network, and the page recommends it over the raw repository mirror with a specific reason: the mirror may return a rate limit error under load, while the CDN has no such limit. Sensible.
https://cdn.jsdelivr.net/gh/phishdestroy/destroylist@main/rootlist/formats/primary_active/hosts.txtWhat is worth pausing on is what the URL pins. It names a branch rather than a tag or a commit, and the raw mirror does the same. For a file a resolver re-fetches automatically every few minutes, a branch reference means the contents change underneath you with no version marker and no change you initiated.
That is a deliberate choice for a list that advertises real-time updates, and it means you cannot pin your resolver to a known state. It also means the only way to know what changed is to watch the repository, which is what the changes directory in the repository appears to be for.
For a consumer who wants reproducibility, that is the central operational fact about this project, and it is not stated as a caveat anywhere on the page.
Two counting methods, and the project says they disagree
The statistics section explains that the figures shown on badges are exact counts of entries in the feeds, and that the API reports normalised unique domains instead. It says the API numbers can therefore be lower, after normalisation of URLs, common prefixes and duplicates, and points at a machine-readable file that defines the metrics.
This is a small paragraph doing a lot of work. Almost every blocklist project reports a headline number, and almost none of them say which of two plausible counting methods produced it. Here there are two numbers for the same list, the reason for the gap is named, and the definitions live in a file a program can read rather than in prose.
So if you compare this project's count against another project's, you may be comparing normalised domains against raw feed entries and concluding that one list is larger than it is. The repository description itself carries two figures, one for curated and one for community, and the ratio between them is the clearest statement of how much of this project is curation and how much is aggregation.
False positives are handled by hand
The feed table includes an allowlist, described as false positive protection, and its update column is the only one not on a timer. Every other feed updates on a schedule. The allowlist is marked manual.
That single word describes the weakest link in the chain. Everything else in this project is automated: thirteen or more aggregate sources pulled in, DNS resolution checked, HTTP content fetched and verified, feeds regenerated and published through a CDN. The step that decides whether a wrongly blocked domain gets unbanned runs on a person.
The consequences follow from the shape of the data rather than from any policy. A phishing domain that is also a legitimate service, or a shared host serving both, is exactly the case an allowlist exists for. And the reverse also holds: an attacker who has registered a domain that a large site also uses is in a position to get a false positive reversed, which is a reason the manual step is worth taking seriously rather than treating as overhead.
The repository carries an appeals section as well, which suggests the two mechanisms are connected.
Neither release is a version of the data
The repository has two releases, and neither is a version of the blocklist.
One is titled as historical archives and carries no version number at all. The other is a version one release of something called a viewer, which is a separate application rather than the feed.
For a project whose central product is a continuously updated dataset, that is an odd release history. There is no version to pin, no changelog entry describing what changed, and no artefact corresponding to any point in time.
This follows from the branch-pinned URLs and the live generation model, and it is coherent with them. But it means the usual answers to three ordinary questions are unavailable: which version am I running, what changed between versions, and can I roll back. The change history directory in the repository appears to be the substitute for a changelog, and it is the only mechanism visible for understanding why a domain appeared or disappeared.
For anyone who needs to prove what their resolver was blocking on a given afternoon, that gap matters more than it would for a library.
The repository ships the feed as tracked files in six resolver formats
The root listing explains the shape of the project. The primary feed exists as tracked files at the top level in both a text and a structured form, alongside a count file. Directories cover the allowlist, historical archives, the change history, the community aggregation, the DNS verification results, the formatted root lists, the generation scripts, threat exchange format exports, and a tests directory.
The formatting step is what produces the widest surface. Six formats are published for each feed: plain domain lists, resolver host files, an ad blocking syntax, a lightweight resolver configuration, an unbound configuration, and a policy zone file. A seventh format for a key value store appears in the format table.
Each format is a separate generated file, so the same data exists many times over in the repository. That is why the primary language is recorded as markup rather than as a scripting language: the tracked artefacts dominate, and the scripts that generate them are a small minority of the bytes.
The requirements file for those scripts is four packages, all pinned to exact versions, including one for domain suffix extraction. Pinning a suffix parser matters more than it looks, since a change in how public suffixes are handled silently changes what counts as a registrable domain.
Editorial conclusion
This is a well built blocklist, and the strongest signal is that it tells you to take a smaller list. If you are deploying this, start with the feed the page recommends for production rather than the one with the most entries, and pair it with the allowlist so a false positive on a partner domain does not cost you a service. Two things to know before you automate it. The URLs pin a moving branch rather than a version, so your resolver will change contents without warning, and the project publishes no versioned release of the data itself, since its two tags are a historical archives bundle and a viewer application. Subscribe to the change history rather than assuming your feed is pinned.
Frequently asked questions
What is destroylist?
It is a phishing and scam domain blocklist that publishes seven feeds in six resolver formats plus a key value store format, for use in Pi-hole, AdGuard Home, unbound, dnsmasq and policy zone systems. It also publishes a free threat intelligence API and threat exchange format exports, and its repository carries the primary feed as tracked files.
Which destroylist feed should I use in production?
The page recommends the DNS-verified file rather than the largest one, and names a different file as the maximum coverage option. Its logic is that a curated list whose domains resolve is safer than an aggregate that catches more, since a blocked name that no longer resolves can still be registered later and false positives on shared hosts get lists switched off.
How do I add destroylist to my resolver?
Paste a URL into the blocklist settings of Pi-hole or AdGuard Home. The page recommends a content delivery network URL over the raw repository mirror because the mirror may return a rate limit error under load. Both URLs point at a branch rather than a tag, so the contents change without a version marker.
Why do destroylist's numbers differ between the badges and the API?
The badges report exact feed-entry counts while the API reports normalised unique domains, so the API value can be lower after normalising URLs, common prefixes and duplicates. The page points at a machine-readable metrics file that defines both, which matters when comparing counts against another project that uses the other method.
How does destroylist handle false positives?
It publishes an allowlist for that purpose, and it is the only feed not on an automatic update timer, since it is maintained by hand. The page also describes an appeals process, which suggests the two mechanisms are connected.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/phishdestroy-destroylist)Star history chart for your README
[](https://hysenlabs.com/projects/phishdestroy-destroylist)Was this useful?