AIRecon drives a Kali sandbox from a language model, and its per-target memory files record WAF bypasses in plain text
AIRecon is an autonomous cybersecurity agent that combines a self-hosted Large Language Model (Ollama) with a Kali Linux Docker sandbox and a Textual TUI. It is designed to automate security assessments, penetration testing, and bug bounty reconnaissance — without any API keys or cloud dependency.
At a glance
- What is it?
- AIRecon is a Python agent that drives a Kali Linux Docker sandbox and a Caido proxy through a four phase pipeline, against any OpenAI-compatible gateway, with a scope guard and an audit log as its stated safeguards. The parts worth reading are the phase enforcement described as soft, the on-disk per-target memory, and a sponsor block offering residential proxies.
- Who is it for?
- This fits a professional who already has written authorisation, a defined scope list, and a habit of reading agent command logs, because those three things are what the tool assumes. It does not fit anyone who wants to point an autonomous agent at a target and walk away, and the page's own wording is why.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 20, 2026, and from our analysis. They are not legal advice.
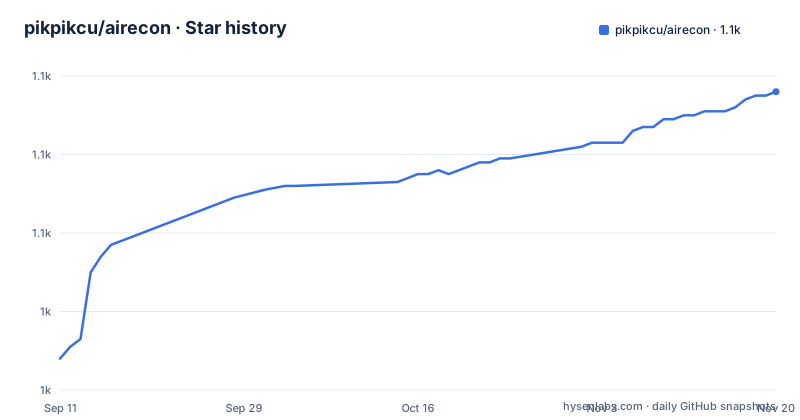
Star history
- pikpikcu/airecon1,096 ★ · +68
| Repository | 2026-09-11 | 2026-11-20 |
|---|---|---|
| pikpikcu/airecon | 1k | 1.1k |
68 Stars in the last 70 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The manifest says 1.7.1-beta and the release tags say 0.1.7-beta
Start with the version, because it is the first thing that will confuse you. The packaging manifest declares the version as `1.7.1-beta`. The three most recent release tags are `0.1.7-beta`, `v0.1.6-beta`, and `v0.1.5-beta`.
So the manifest and the tags disagree by a factor of ten, and the tag prefixes disagree with each other as well, since one of the three has no leading v. The releases run from March to April 2026 and the last commit to the default branch is dated 2026-09-11, so the tree has moved a long way past anything tagged.
The rest of the packaging is more settled. Python is pinned to a 3.12 minimum, the console entry point is a module in the package, and the distribution deliberately bundles four kinds of data alongside the code: the skill markdown files, the container definitions, the proxy data, and the prompt files. That last group explains how a self-contained install can carry both a Kali sandbox definition and a prompt set.
One more small mismatch: the licence badge in the header links to the licence file on a branch called master, while the repository's default branch is main.
Two dependency files, and the OpenAI SDK is deliberately missing
The project keeps both a packaging manifest and a requirements file, and they do not agree. The manifest declares a core set covering the terminal interface, an HTTP client, a web server with server-sent events, rich output, validation, browser automation, a vulnerability scoring library, a search library, an async HTTP client, and XML parsing. The requirements file carries the same names with slightly different floors and adds four that the manifest does not have: a YAML parser, a fast JSON library, a cache backend for the web layer, and the property testing library.
That last one is the interesting overlap. The property testing library is listed as a development dependency in the manifest and as a runtime requirement in the requirements file, so the two files disagree about whether a test tool ships.
The absence that is deliberate is worth quoting in substance. A comment in the manifest explains that the client speaks the OpenAI chat completions wire format directly over the HTTP library, so the vendor SDK is intentionally not a dependency, and that any OpenAI-compatible gateway works as a result. That is a defensible choice for a tool whose whole point is being backend-agnostic.
The development side adds property testing, coverage, timeouts, mocking, a terminal inspector, a formatter, a documentation theme, and a static type checker. The type checker is configured by a JSON file at the root of a Python project, which is either a leftover or a deliberate belt and braces.
Four phases, and the enforcement between them is soft
The pipeline is four named stages:
RECON → ANALYSIS → EXPLOIT → REPORTEach phase is supposed to have its own objectives, its own recommended tools, and automatic criteria for moving on. And then there is the sentence that matters more than the rest: phase enforcement is soft, the agent is guided but never blocked.
That is a design choice with consequences. An enforced pipeline would refuse to move from analysis into exploitation without a finding, and this one does not. A guided pipeline writes the expectation into the prompt and trusts the model, which means the thing standing between a reconnaissance result and an exploitation attempt is the model's judgement rather than a gate.
Alongside it there is a checkpoint schedule, and this part is precise: an evaluation every 5 iterations, a self evaluation every 10, and context compression every 15. So the agent is periodically asked to look at where it is, and periodically has its context compacted, on a fixed schedule rather than on a condition.
A scope guard and an audit log, next to an open-ended reconnaissance surface
Two safeguards are stated plainly in the feature table: a scope guard that refuses out-of-scope targets, and an audit log that records every command. For an autonomous agent those are the two that matter, and having them named is better than not.
The rest is more ambiguous, and the honest reading is that they guard the later phases better than the early ones. Reconnaissance inputs are open ended: a search engine library, browser automation against arbitrary targets, a proxy integration that can list, replay, and intercept traffic from a captured session, and a sitemap tool. A scope guard can refuse to act on a host you have not authorised, and the page says it does; what it does not say is how targets enter the picture in the first place, or whether a discovered subdomain or a linked host is treated as in scope by default.
There is no dry run in the description. The nearest thing is the audit log, which tells you what happened rather than showing you what would happen.
And the optional local knowledge base is worth reading carefully before you load it. It indexes about 1.09 million records into a local full text index, and the categories named include red team techniques, writeups, scanning templates, and third-party payloads. Nothing here describes a technique or a payload; the point is the size of the corpus the agent can search autonomously before trying something unfamiliar, which is a different question from whether a given command is authorised.
Per-target memory holds WAF bypasses and auth endpoints in plain files
The learning section is unusually specific about disk, which is the useful part, because it tells you what a second operator or a backup would find.
There is a SQLite database under the home directory storing sessions, findings, patterns, target intelligence, tool usage, model performance, skill usage, and attack chain discoveries. There is a learning state file beside it holding tool performance statistics, strategy patterns, an observation log, and distilled insights. And there are per-target memory files, created when a session is persisted, that contain endpoints, vulnerabilities, WAF bypasses, sensitive parameters, and authentication endpoints.
Read that list again. It is a per-target dossier of how a specific system was found to behave, including how its filtering was circumvented and where its authentication surface is, written to a plain file in a directory under your home path with no mention of encryption.
There is a fourth location, and it is the one to watch. Payload memory snapshots can be written into the workspace for a target, in a file named for the target, and the feature is described as skipping payloads that repeatedly failed for the same target and parameter.
On a single machine you control, that is a reasonable trade for the functionality. On a shared host, a synced home directory, or a laptop whose backups you do not control, it is a collection of findings about other people's systems sitting in your dotfiles.
The learning is a ranked tool list, not a model that improves
The section heading is phrased as a question and the first line answers it: this does not fine-tune the model. What it calls learning is local structured telemetry that guides tool choice and avoids repeating paths that already failed.
The mechanics are specific and worth knowing, because they set expectations. On session start, memory context is injected: target intelligence, similar findings, learned patterns, and tool reliability. On a cold start with no history for a detected stack, a knowledge brief from a static correlation dataset is injected instead, so the agent is never starting from nothing. Learned patterns are re-injected every 4 iterations by default and correlation runs every 6. Adaptive tool ranking orders tools by historical success and failure, and within-session learning starts after only 2 observations.
Only findings that were verified, or judged high confidence, are written to the cross-session brain, and that filter is on by default. That is the single most important line in the section, because it is what stops the agent from learning its own false positives back into its future behaviour.
So the honest description is: a tool ranking table, a findings database, and a periodic re-injection schedule. The model stays exactly as good as the model you supplied.
Skill routing is 289 keyword mappings
There are 57 built-in skill files and 289 mappings from keywords to skills, and the agent picks a skill by matching what it is doing against those keywords.
That is the whole selection mechanism as described, and it is worth naming as a mechanism rather than a feature. Keyword routing is fast, predictable, and free, and it fails in a specific way: when two skills share vocabulary, or when the agent describes a task in words the mapping does not cover, the wrong playbook gets loaded and nothing reports that the routing was ambiguous.
The same organisation publishes a community library that extends the set with 57 more CLI-based playbooks for capture-the-flag, bug bounty, and penetration testing work, and the page recommends pairing them.
So the total vocabulary an agent can reach is 114 playbooks selected by 289 keyword rules. That is a wide surface, and the failure mode of a wide surface chosen by keyword matching is a mis-route, not a crash.
A residential proxy sponsor with a discount code sits above the feature table
Before the feature table there is a sponsor section for a residential proxy service. It advertises a large pool of residential addresses across hundreds of locations, HTTP and SOCKS5 support, IP rotation, sticky sessions, and geographic targeting, framed as helping AI powered research reach sites reliably, and it carries a discount code.
A proxy is a normal part of a security toolchain, and the discount code is an ordinary commercial arrangement. The reason to note it is the capability it changes. Rotating residential addresses exist so that traffic looks like different people, and a target's own detection sees exactly that. An agent doing reconnaissance through a rotating residential pool is harder to distinguish from ordinary traffic than the same agent through a datacentre address, which cuts both ways: it is also harder for you to distinguish your own agent in a target's logs after the fact.
The rest of the configuration story is neat in a way that suggests testing. The model requirements section requires native tool calling, states that without it the agent cannot run any tool and is non-functional, and names a setting that should stay true. Reasoning support is auto-detected: in auto mode the agent sends the standard reasoning effort parameter, and if a backend rejects it with a 400 for an unsupported parameter, it strips the field and remembers that for that backend. Quality guidance is given by size, from a list of named strong models down to a threshold below which local models are not recommended for serious work.
Editorial conclusion
This fits a professional who already has written authorisation, a defined scope list, and a habit of reading agent command logs, because those three things are what the tool assumes. It does not fit anyone who wants to point an autonomous agent at a target and walk away, and the page's own wording is why. Four things to check first. Whether the scope guard covers the reconnaissance phase as well as the exploitation phase, since the guard is described as refusing out-of-scope targets while the phase enforcement is described as soft and the agent is never blocked. What ends up on disk, because per-target memory files hold endpoints, vulnerabilities, WAF bypasses, and auth endpoints in plain files under your home directory, and that is sensitive on a shared or backed-up machine. Which knowledge base you load, since the optional dataset indexes a large corpus that includes automated templates and third-party payloads. And whether the residential proxy sponsor belongs in your threat model, because a rotating residential address changes what a target sees when your agent visits it.
Frequently asked questions
What does AIRecon need to run?
Python 3.12, an OpenAI-compatible gateway, and a Kali Linux Docker sandbox, with a Caido proxy integration alongside them. The manifest requires native tool or function calling: without it the agent cannot run any tool and is non-functional, and a setting called openai_supports_native_tools is meant to stay true.
Can AIRecon run fully offline?
Yes, when the gateway is local. Pointing it at a local gateway such as vLLM, or a gateway proxying a local Ollama, is described as giving fully offline and private operation with no API keys, while a hosted endpoint is offered as the option for higher reasoning quality.
Does AIRecon block out-of-scope targets?
It ships a scope guard that refuses out-of-scope targets and an audit log that records every command. Phase enforcement, though, is described as soft: the agent is guided through recon, analysis, exploit, and report but is never blocked from moving on.
What does AIRecon store on disk?
A SQLite memory database under the home directory holding sessions, findings, patterns, target intelligence, tool usage, and skill usage, an adaptive learning state file, and per-target memory files containing endpoints, vulnerabilities, WAF bypasses, sensitive parameters, and authentication endpoints. Payload snapshots can also be written into a per-target workspace file.
Does AIRecon fine-tune the language model?
No, and the page says so directly. What it calls learning is local structured telemetry: verified or high-confidence findings are written to a cross-session brain, tool rankings adapt from success and failure, and a knowledge brief is injected on a cold start so the agent is never starting empty.
What is in the AIRecon security knowledge base?
An optional separate repository that indexes about 1.09 million security records, including CVEs, red team techniques, writeups, scanning templates, and bug bounty payloads, into a local SQLite full text index. The agent calls a dataset search tool on its own before attempting an unfamiliar technique.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Beyond ARTEX: 45 Agentic Attack Frameworks, What They Hunt For, and How to Find Themdev.to · Nov 17, 2026 · 2 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pikpikcu-airecon)Star history chart for your README
[](https://hysenlabs.com/projects/pikpikcu-airecon)Was this useful?