URLFinder: a page scraper that trades false positives for fewer missed links
A fast, comprehensive and easy-to-use page information extraction tool that quickly discovers and extracts JS files, URLs and sensitive information from web pages.
At a glance
- What is it?
- A Go tool that extracts the scripts and URLs a page loads and looks for hidden sensitive information or unauthorised endpoints, descended from a JavaScript tool that stopped being fixed. The documentation is unusually candid about what it misses and how its rules work.
- Who is it for?
- Use URLFinder on systems you are authorised to assess, and use it the way its author does: run it broadly, then filter. The tool gives up a low false positive rate on purpose, so a long result list is expected rather than a sign that something is wrong, and the documentation tells you not to read only the successful responses.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 151 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
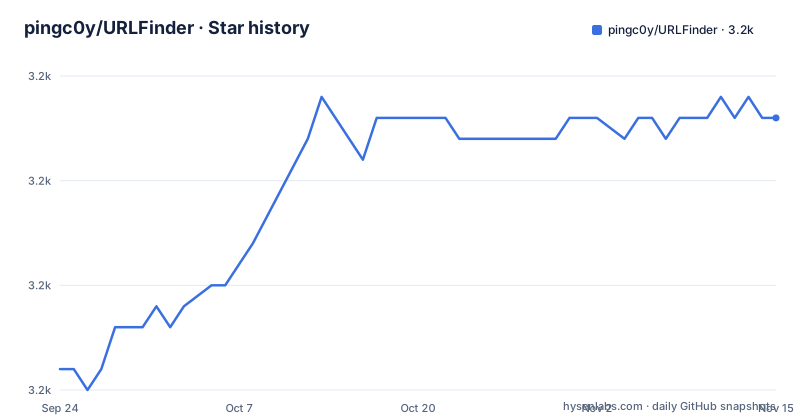
Star history
- pingc0y/URLFinder3,193 ★ · +12
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| pingc0y/URLFinder | 3.2k | 3.2k |
12 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It finds the scripts and URLs a page loads
The tool does one thing with a lot of options around it. It analyses the JavaScript and URLs inside a page, and looks for sensitive information hidden in them or for API endpoints that were never meant to be public.
The origin story is in the last section of the documentation and it explains the design. The author used a similar tool called JSFinder, found that it returned empty results or incomplete links, and noticed that its author had not updated or fixed bugs for a long time. So the tool was written to replace it.
That lineage shows in the output. The notes section says plainly that, in order to be more compatible and to avoid missing links, the tool gave up on a low false positive rate: wrong links increase, but the chance of missing a link falls. You can filter by status code to cut the noise, and the documentation explicitly advises against looking only at the successful responses.
So a first run is expected to be long. That is the trade, stated by the author rather than discovered by you.
Three crawl modes and keyword filtering
The mode flag is the most consequential thing you set, and it has three values.
Mode one is normal crawling and is the default. Mode two is deep crawling, described precisely: URLs are followed one level and JavaScript is followed three levels, with the stated reason of preventing the crawl from wandering off target. Mode three is safe deep crawling, which filters sensitive routes such as delete and remove before visiting them.
That third mode exists because this tool follows links automatically, and an automatic follower on a production system will eventually find a link whose name ends in delete. The mode filters configured keywords such as `delete` and `remove`, but cannot identify every state-changing endpoint. Obtain authorization, restrict scope and test in a controlled environment; the mode is not a guarantee of safety.
Two other flags shape the crawl rather than its depth. One limits the maximum number of links fetched, and one restricts which domains are fetched at all, and it accepts a regular expression rather than a suffix, so you can be precise about what belongs to the target.
Status codes are chosen by you, not detected
Earlier versions detected status codes automatically, and the changelog records the switch: obtaining the status code changed from automatic to manual, with the mode flag taking it over.
Today you pass a list. Passing all shows everything; passing a comma separated list such as two codes restricts the display to those. And since the June 2026 release that matching is exact rather than approximate, which is a small change that removes a class of surprise.
The ordering rules are documented too, and they are unusual enough to be worth knowing before you read a result. Results show the top level domain you gave as input first, and other domains are not distinguished from each other and appear under a separate heading. Successful responses come first, sorted from small to large, and the input domain has priority: even a not-found response on your own input domain sorts ahead of a successful response on someone else's subdomain.
That rule is deliberate. In a mixed result set it tells you where the interesting findings are.
A single target run looks like this:
URLFinder.exe -u http://www.baidu.com -s all -m 3Extraction rules need a capture group, filter rules do not
The configuration file is where the real control lives, and it is a YAML file loaded with the config flag. If it does not exist in the current directory, the program generates a default one and exits so you can edit it.
The fields cover the same ground as the command line: proxy address, request timeout, thread count, how deep to follow URLs and how deep to follow JavaScript, the maximum link count, and custom request headers. Three fields are regular expressions for extraction: one for JavaScript, one for URLs, and one for sensitive information. Two more are regular expressions for filtering, one for JavaScript and one for URLs. The last two are a list of dangerous path keywords used by the safe mode, and a dictionary for the fuzz mode.
The rule that catches people is documented explicitly. Each extraction regular expression must contain at least one capture group, and the program uses the first capture group as the result. The two filter regular expressions need no capture group, because they decide what to keep rather than what to return.
There is also a compatibility path: the documentation recommends the newer sensitive-information field for new configurations while the older name is still read from existing files.
Validation happens at startup. The thread count, the timeout and the maximum count must all be greater than zero, and the regular expressions are checked before any request goes out, so a bad configuration fails immediately instead of halfway through a crawl.
The fuzz mode turns its own 404s into a dictionary
One feature deserves its own explanation because the documentation is unusually clear about how it works.
The fuzz mode takes the directories and paths that returned not-found during the crawl, treats them as a dictionary, combines them randomly, and collides them against the target to find paths that do exist. The stated purpose is to solve path concatenation mistakes, which is the kind of bug where a script builds a URL wrong and nobody notices.
The constraints are written down next to the flag, and they matter. It only applies to links under the main domain, and it has to be used together with the status code flag rather than on its own.
Both conditions are sensible limits on a feature that generates requests nobody asked for by name. Treat it as the most invasive thing the tool does, keep it on the domain you are authorised to test, and read the mode documentation again before turning it on against anything you care about.
Two dependencies, and a module version older than the toolchain advice
The dependency list is short enough to read in one glance: a terminal colour library and a YAML library, plus two indirect dependencies for terminal capabilities and system calls.
There is nothing else. No HTTP framework, no scraping library, no regex engine beyond the standard library. For a tool that fetches pages, extracts URLs with regular expressions and writes coloured output, that is a defensible choice and it explains why the binaries are small.
There is one inconsistency worth flagging. The module declaration in the dependency file states a language version of 1.19, while the build documentation recommends a recent Go toolchain with a security patch or newer. Those are two different things: the language version the module compiles against, and the toolchain you are told to build it with. They can differ legitimately, but the gap here is wide enough that you should use a current toolchain rather than assuming the module file will protect you.
The source layout matches the pipeline: a command directory, a crawler directory, a directory for the crawl modes, one for results, one for utilities, and one for configuration, with a small entry point at the root.
Releases are built by CI on a tag and named by date
The release process is documented in the build section and it is unusually complete.
Release packages are built automatically by GitHub Actions when a tag is pushed, using GoReleaser, and the version number is taken from the tag and injected into the program's own update prompt. The manual path is given too: environment variables for cross-compilation with cgo disabled, pairs of target operating system and architecture, and linker flags that strip symbols and stamp the update variable with the literal string dev so a locally built binary does not claim to be a release.
The release names are dates. The newest is a June 2026 release, and before it sit two from September 2023, which tells you the tool sat unchanged for roughly three years and then had a burst of work in June 2026.
That burst is documented as a changelog, and it is where the engineering tells you what the maintainer thinks matters: a new CI pipeline covering tests, vetting, builds, the race detector and a vulnerability check; validation of capture groups and runtime parameters at startup; exact status code matching; protocol detection moved under timeout control; and two security-adjacent fixes, namely that the update check no longer skips TLS certificate verification and that the help flag no longer triggers a network call. There is also a response size limit added to reduce the memory risk from unusually large responses.
Editorial conclusion
Use URLFinder on systems you are authorised to assess, and use it the way its author does: run it broadly, then filter. The tool gives up a low false positive rate on purpose, so a long result list is expected rather than a sign that something is wrong, and the documentation tells you not to read only the successful responses. Three things to set before a run: the crawl mode, because safe deep mode filters configured risky path keywords but cannot guarantee that all state-changing routes are avoided; the status codes you want to see; and the extraction rules, which need a capture group each and are the difference between noise and signal. Do not point it at third-party infrastructure without permission, and review the tool's network behavior and scope before running it; the current changelog says the help flag no longer makes a network request.
Frequently asked questions
What does URLFinder do?
It analyses the JavaScript and URLs inside a web page and looks for sensitive information hidden in them or for API endpoints that were not meant to be public. The author wrote it after a similar tool kept returning empty or incomplete results and stopped being maintained.
Which crawl modes does URLFinder have?
Three. Normal crawling is the default, deep crawling follows URLs one level and JavaScript three levels to avoid wandering off target, and a safe deep mode filters sensitive routes such as delete and remove before visiting them.
How do I choose which status codes URLFinder displays?
With the status flag: all shows everything, or pass a comma separated list such as two codes. Matching became exact in the June 2026 release, and the documentation advises against reading only the successful responses.
What goes in the URLFinder configuration file?
A YAML file loaded with the config flag and generated in the current directory if missing. It holds the proxy, timeout, thread count, crawl depths, maximum link count, request headers, three extraction regular expressions that each need a capture group, two filter regular expressions, the dangerous path keywords used by the safe mode, and a fuzz dictionary.
How is URLFinder built and released?
GitHub Actions builds release packages when a tag is pushed, using GoReleaser, and injects the version from the tag into the update prompt. Local verification is a sequence of tidy, test, vet, build, race and vulnerability check commands, and the documentation recommends a current Go toolchain with security patches.
Which platforms does URLFinder ship binaries for?
The manual cross-compilation commands cover Windows on amd64 and on 386, Linux on amd64 and on arm64, all with cgo disabled and the update variable stamped as dev so a local build is not mistaken for a release.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pingc0y-urlfinder)Star history chart for your README
[](https://hysenlabs.com/projects/pingc0y-urlfinder)Was this useful?