Pinpoint APM: Dapper-style transaction tracing for Java services, and what sits behind the agent
APM, (Application Performance Management) tool for large-scale distributed systems.
At a glance
- What is it?
- Pinpoint traces transactions across distributed Java applications through agents that need no code changes, then draws the result as a ServerMap and call stacks. Version 4.0.0 shipped in October 2026; the catch is a sizeable server side and plugin-by-plugin version support.
- Who is it for?
- Pinpoint suits teams running many JVM services on the listed servers and frameworks who want call-level tracing and a topology map without editing application code, and who can operate the collector and storage side. Teams whose services are mostly outside Java, PHP and Python, or who want a hosted tracing service rather than infrastructure to run, should not start here.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
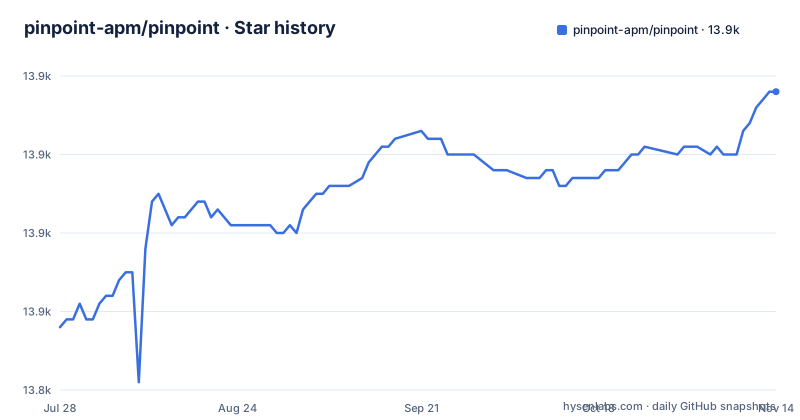
Star history
- pinpoint-apm/pinpoint13,878 ★ · +30
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| pinpoint-apm/pinpoint | 13.8k | 13.9k |
30 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Tracing modeled on Google's Dapper
Pinpoint is an application performance management tool for large distributed systems, and its design is openly inspired by Google's Dapper paper. The idea is to follow a single transaction as it crosses services, so you can see how components are connected and where time is spent, instead of treating each call between services as a black box.
The output is organized around a few views. ServerMap draws the topology of the system and lets you click a node to see its current status and transaction count. The Realtime Active Thread Chart shows active threads inside an application as they change. The Request/Response Scatter Chart plots request count and response patterns over time, and you drag over a region of the chart to pull out the transactions inside it. CallStack gives code-level visibility into each transaction, and Inspector shows CPU usage, memory and garbage collection, TPS and JVM arguments. URI metrics, infrastructure and error analysis views round out the list.
A public live demo of the ServerMap is linked from the project page, which is the fastest way to judge whether these views match how your team debugs latency.
Agents that attach without code changes
The selling point for application teams is that Pinpoint agents install without changing a single line of application code. Instrumentation is handled by the agent and its plugins rather than by calls you add to your services. That lowers the cost of rolling tracing out across many services, because nobody has to touch each codebase.
The project's own figure for overhead is approximately a 3% increase in resource usage. Treat that as the project's estimate, not a guarantee for your services: it is stated as approximate, and the actual cost depends on how much your traffic exercises the instrumented libraries. If you run latency-sensitive services, measure with and without the agent before enabling it everywhere.
The agent side supports JDK 8 and newer, which matters for organizations that still run older JVMs alongside current ones.
Support is decided plugin by plugin
Coverage depends on the plugins in agent-module/plugins, and the supported version range for each module is recorded with its plugin rather than as one global statement. The list is long. Servers include Tomcat, Jetty, JBoss EAP, Websphere, Vertx, Weblogic, Undertow, Akka HTTP and Pekko HTTP. On the framework side there are Spring, Spring Boot with embedded Tomcat, Jetty, Undertow or Reactor Netty, Spring WebFlux, Spring TX, Spring Cloud Sleuth, RestTemplate and Ktor. HTTP clients cover Apache HttpClient 3, 4 and 5, the JDK HttpConnector and HttpClient, GoogleHttpClient, OkHttpClient, NingAsyncHttpClient and Netty. RPC plugins cover Thrift, Dubbo, gRPC and Apache CXF, and messaging includes ActiveMQ and RabbitMQ.
The consequence is that a library appearing in that list does not mean every version of it is traced. If your service uses a framework release outside a plugin's range, or a library with no plugin at all, you cannot count on those calls appearing in the call stack. Check the plugin directory against your dependency versions before promising anyone end-to-end traces.
Only Java lives in this repository
The main repository is the Java implementation. PHP and Python applications are supported through a separate project, pinpoint-c-agent, with its own repository. Anything outside Java, PHP and Python is not covered by either.
For a mixed estate this has two effects. First, you track two codebases and two release streams for agents, so an upgrade of the Java side does not automatically bring the PHP or Python agent along. Second, services in other languages drop out of the trace entirely. A transaction that passes through such a service has an untraced hop in the middle, which undercuts the main reason to deploy distributed tracing in the first place.
A server side with many moving parts
Pinpoint is not a single binary. The repository root shows how much sits behind the agent: collector and collector-starter, batch and alarm modules, an alarm-batch-starter and batch-alarmsender, plus modules named hbase, pinot, redis, realtime, inspector-module, metric-module, exceptiontrace and applicationmap. There are also otlptrace, otlpmetric and otlplog modules, and a basic-login module.
The practical reading is that adopting Pinpoint means running and maintaining a set of backend services, not just dropping an agent onto applications. Capacity planning, upgrades and storage operations become your team's job. For teams that want to avoid that work, this is the main cost of choosing a self-hosted APM of this shape.
For Kubernetes, deployment material lives in a separate pinpoint-kubernetes repository rather than in the main tree.
Setup instructions live outside the repository
The README does not carry install commands. It points to two documents on the project's GitBook site: a quick-start guide for a simple test run, and an installation guide for further instructions. The repository itself includes a quickstart directory with its own README and a testapp, which is where a first local run starts.
For building from source, BUILD.md sits at the repository root next to the Maven wrapper scripts mvnw and mvnw.cmd and the top-level pom.xml. Contribution rules are in CONTRIBUTING.md.
The consequence of this split is that you read instructions on one site and code on another. When the guide and the repository disagree, the repository and the release note for your version are the safer reference.
Version 4.0.0 and the release cadence
The current stable version is v4.0.0, released on October 28, 2026. The two releases before it were v3.1.1 on October 2, 2026 and v3.1.0 on May 20, 2026. The default branch is master, and the last push landed on November 2, 2026, so the project is under active development.
A move from 3.x to 4.0.0 is a major version change. Pinpoint links its release note from the top of the README, and that note is what to read before upgrading agents or servers, because a deployment runs both agents and server modules. If you are starting fresh, begin on 4.0.0 rather than adopting 3.1.1 and facing the upgrade later. Build status runs on GitHub Actions with Maven, and coverage is reported through Codecov.
Editorial conclusion
Pinpoint suits teams running many JVM services on the listed servers and frameworks who want call-level tracing and a topology map without editing application code, and who can operate the collector and storage side. Teams whose services are mostly outside Java, PHP and Python, or who want a hosted tracing service rather than infrastructure to run, should not start here. Before deploying, check your exact framework versions in the agent plugin directory, read the v4.0.0 release note, and measure the agent's overhead on your own workload rather than relying on the approximate 3% figure.
Frequently asked questions
How do I install Pinpoint APM?
Pinpoint points to a quick-start guide and an installation guide on its GitBook site, and the repository includes a quickstart directory with a test app. Kubernetes deployments use the separate pinpoint-kubernetes repository.
How do I use Pinpoint APM once agents are running?
Use the ServerMap to see how components connect, the scatter chart to drag-select slow transactions, and CallStack to see code-level detail for each transaction. Inspector shows CPU, memory, garbage collection, TPS and JVM arguments.
Does Pinpoint APM support PHP and Python?
Yes, through the separate pinpoint-c-agent repository. The main Pinpoint repository covers Java on JDK 8 and newer.
How much overhead does the Pinpoint agent add?
Pinpoint states approximately a 3% increase in resource usage. That figure is the project's own estimate.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pinpoint-apm-pinpoint)Star history chart for your README
[](https://hysenlabs.com/projects/pinpoint-apm-pinpoint)Was this useful?