PipeCD publishes its core and its plugins on three different tag schemes, and the build only matches one of them
The One CD for All {applications, platforms, operations}. The tutorial shows how to run PipeCD locally for introduction.
At a glance
- What is it?
- A CNCF sandbox continuous delivery platform that deploys across Kubernetes, Terraform, Cloud Run, Lambda and ECS without custom resources and without credentials outside the cluster. The release list mixes plain v tags with full Go module path tags for plugins that sit far behind the core version, the Makefile derives its version from a pattern that only sees v tags, and the local tutorial lives in another repository.
- Who is it for?
- This fits a platform team running several clouds and application shapes and willing to put a controller inside each cluster, and it fits a small team that wants one deployment interface without writing custom resources. Check three things first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
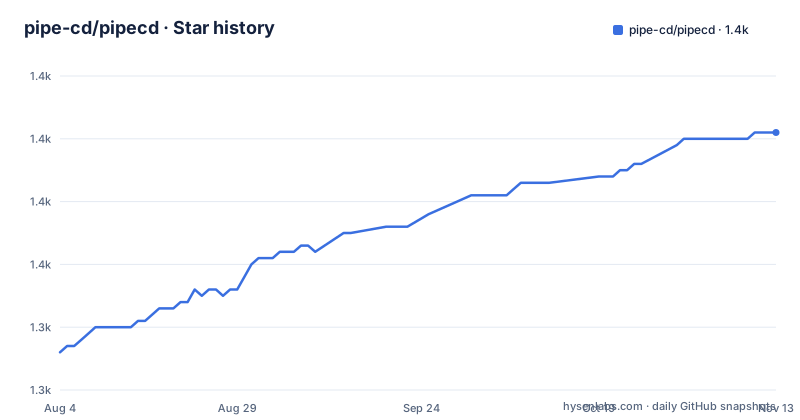
Star history
- pipe-cd/pipecd1,371 ★ · +35
| Repository | 2026-08-04 | 2026-11-13 |
|---|---|---|
| pipe-cd/pipecd | 1.3k | 1.4k |
35 Stars in the last 101 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The release list mixes plain tags with full module path tags
Three of the newest releases use three naming schemes. The core is `v0.58.0`, published 2026-08-23. A plugin is `pkg/app/pipedv1/plugin/kubernetes/v0.4.0`, published 2026-08-14. Another is `pkg/app/pipedv1/plugin/kubernetes_multicluster/v0.1.0`, published 2026-09-09. So a plugin release tag is its full Go module path with a version appended, which is the convention Go submodules need in order to be referenceable, while the core uses the ordinary short form. The numbers underneath are the interesting part. The core is in its fifty eighth release while the Kubernetes plugin is on 0.4.0 and the multicluster plugin is on its first. Plugins are versioned independently of the platform and are nowhere near its line, which means a plugin is not upgraded by upgrading PipeCD. Anything that assumes one version number describes the tree is wrong here, and pinning has to be done per plugin.
The build derives its version from a tag pattern that only matches the core
The Makefile names a convention where every target reads as action/target, with the actions being check, build, test, run, stop, lint, update, gen, release, push, up, and down, and the help target greps the `## ` comments out of the Makefile to print them. The version injection is where the tag scheme bites:
build/go: BUILD_VERSION ?= $(shell git describe --tags --always --dirty --abbrev=7 --match 'v[0-9]*.*')
build/go: BUILD_COMMIT ?= $(shell git rev-parse HEAD)
build/go: BUILD_DATE ?= $(shell date -u '+%Y%m%d-%H%M%S')
The `--match 'v[0-9]*.*'` pattern only selects tags that begin with v and a digit. The plugin tags begin with `pkg/`, so they are invisible to that filter, which is almost certainly the intent, since a plugin tag sitting on a commit would otherwise become the version of the core binary. The linker flags then write version, gitCommit, and buildDate into `github.com/pipe-cd/pipecd/pkg/version` with `-w -trimpath`. Two smaller details sit in the same block: the dirty flag comes from git describe, so an uncommitted build is marked, and the target and architecture are extracted out of the output of `go version` with two `cut` invocations rather than being asked for directly.
Examples ship a v0 and a v1 layout while plugins sit under a pipedv1 path
The tree carries an `examples/` directory with a `.pipe/` folder inside it, which is where the pipeline definition lives, and with two versioned subtrees: `examples/v0/` and `examples/v1/`. Alongside that there is a `README.remote.md` next to the main examples README. So the sample pipelines are published twice under two API generations, and a newcomer has to know which one the installed server expects. The plugin tags point the same way, since they read `pipedv1` in the module path, which suggests the plugin interface is versioned in step with the newer API while the core still carries both. None of this is explained on the project page. The practical effect is that the examples directory is a compatibility matrix rather than a tutorial, and picking the wrong subtree is a confusing first hour rather than an obvious error.
Two design claims do the heavy lifting, and both are about what you do not install
The first claim is that no CRD and no change to your application manifests is required, only a pipeline definition alongside the manifests you already have. That is a genuine architectural position: instead of installing custom resources into your cluster, PipeCD reads a description of the deployment and acts. The second claim is that no deployment credentials are exposed or required outside the application cluster. Together they describe a controller that authenticates with in cluster identity and reaches the platform from where the workload already lives, so there is no long lived cloud credential sitting in a CI secret store. Both claims also have edges worth naming. No CRDs means no admission level interception and no schema validation of your deployment intent from Kubernetes itself. Credentials staying inside the cluster means the compromise radius of the controller is the cluster it runs in, and it means the cluster needs whatever role the target platform requires.
Deployment analysis is inside the pipeline, and Insights reports delivery metrics
Two observability claims are stated in the feature list rather than demonstrated. The first is built in deployment analysis as part of the deployment pipeline, measuring impact based on metrics, logs, and emitted requests, which places the check between stages rather than in a separate dashboard you have to correlate back yourself. The second is the Insights view, reporting lead time, deployment frequency, MTTR, and change failure rate. Those four are the standard delivery performance measures, and the page gives no thresholds, no baselines, and no way to know what value counts as good for your team, so the numbers are only useful once you have your own history to compare them against. Both features need the platform to be emitting the underlying data, which means whatever metrics, log, and request sources the analysis consumes have to exist in the environment you point it at.
The local tutorial lives in another repository, and make up wants a kind cluster
Getting started offers three doors and only two of them are in this repository. The quickstart guide and the installation guide are documentation pages, while the tutorial that shows how to run PipeCD locally is a separate repository, pipe-cd/tutorial, linked from here. That matters for anyone auditing what they are about to install, since the walkthrough you will actually follow is not in the tree you cloned. The repository is not without local tooling of its own: there is a `local/` directory, a `hack/` directory, and `manifests/`, and the Makefile reserves two actions for environment work, `up` to prepare a local environment described as a registry and a kind cluster, and `down` to shut it down. So local runs go through a Kubernetes cluster and a container registry rather than a set of local processes, which is the same shape as production and also the reason the local path is heavier than a binary you start and stop.
A GitHub API client from v29 and a +incompatible Redis library sit in the same block
The dependency list is mostly current, with cloud.google.com/go for Firestore, Secret Manager, Storage, and the profiler, aws-sdk-go-v2 for ECS, Lambda, S3, Secrets Manager, SSM, and elastic load balancing, plus go-oidc for identity, go-jwt, slack-go for notifications, robfig/cron for scheduling, prometheus client, and hashicorp hcl for the Terraform side. Two entries stand out. The GitHub API client is `github.com/google/go-github/v29`, a major version behind the SDK generation everything around it sits in. The Redis client is `github.com/gomodule/redigo v2.0.0+incompatible`, where the suffix records that the module never adopted semantic import versioning, so it has no v2 major to move to. Both are load bearing for features the project advertises, since pull request driven deployment and Redis backed services both depend on them. Two test oriented libraries, a Docker test harness and a fake Google Cloud Storage server, also sit in the main require block rather than behind a separate test dependency set.
Editorial conclusion
This fits a platform team running several clouds and application shapes and willing to put a controller inside each cluster, and it fits a small team that wants one deployment interface without writing custom resources. Check three things first. The GitOps claim is specific, a pipeline definition plus your existing manifests and no CRD changes, so verify your platform is on the supported list before designing around it. The credential claim means the controller runs with in cluster identity and no external secrets, which is a real advantage and also a real blast radius inside that cluster. And the versioning tells you how to pin: the core is at v0.58.0 while the plugins carry their own much lower lines, so pin the core and each plugin separately rather than assuming one version covers the tree.
Frequently asked questions
What is pipecd?
PipeCD is a GitOps style continuous delivery platform that provides one deployment interface across application kinds and clouds, including Kubernetes, Terraform, GCP Cloud Run, AWS Lambda, and AWS ECS. It is a Cloud Native Computing Foundation Sandbox project.
Does PipeCD require custom resources in my Kubernetes cluster?
No. The project states that no CRD and no changes to your application manifests are required, only a pipeline definition alongside the manifests you already have. Credentials are also not required outside the application cluster.
How do I run PipeCD locally for a first look?
The tutorial that runs PipeCD locally lives in the separate pipe-cd/tutorial repository rather than in this one. The quickstart and installation guides are documentation pages, and the Makefile has up and down targets for a local environment made of a registry and a kind cluster.
How should I pin PipeCD versions, including plugins?
Separately. The core is tagged plainly, for example v0.58.0, while plugins are tagged with their full module path, for example pkg/app/pipedv1/plugin/kubernetes/v0.4.0, and the plugin lines sit well below the core line. The build's version match pattern only selects v prefixed tags.
What delivery metrics does PipeCD report?
Lead time, deployment frequency, MTTR, and change failure rate. It also describes deployment analysis built into the pipeline that measures impact from metrics, logs, and emitted requests.
Where does PipeCD put its pipeline definition?
In a .pipe directory inside the project, as the examples in this repository show. The examples directory publishes that layout twice, under examples/v0 and examples/v1, alongside a README.remote.md.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pipe-cd-pipecd)Star history chart for your README
[](https://hysenlabs.com/projects/pipe-cd-pipecd)Was this useful?