Pixie: eBPF capture kept in the cluster, PxL queries, and a release tag that names one component
Instant Kubernetes-Native Application Observability
At a glance
- What is it?
- Pixie is an open source observability tool for Kubernetes applications. It attaches with eBPF, keeps the collected telemetry inside the cluster instead of shipping it out, and exposes one query language across the web UI, the CLI and the client API. What that buys you, and what it costs, comes down to three things.
- Who is it for?
- Pixie suits teams debugging a live cluster who want request bodies and query text without installing an agent in every application, and who are willing to spend cluster CPU on it. It does not suit anyone needing retention beyond the cluster or a single version number to pin, because the components are versioned separately.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
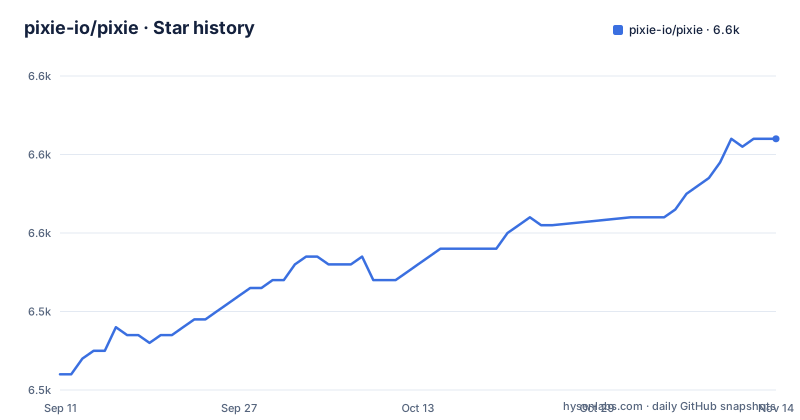
Star history
- pixie-io/pixie6,562 ★ · +30
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| pixie-io/pixie | 6.5k | 6.6k |
30 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
eBPF does the collecting and the cluster does the storing
Pixie is an open source observability tool for Kubernetes applications, meant for two levels of view: the high-level state of the cluster, covering service maps, cluster resources and application traffic, and the detailed views underneath it, covering pod state, flame graphs and individual full-body application requests. Collection is automatic and it happens with eBPF, gathering full-body requests, resource and network metrics and application profiles without an agent compiled into your application. Storage is the other half of the design. Pixie collects, stores and queries all telemetry data locally in the cluster, so nothing has to be shipped to a backend outside it. The cost of that choice is stated as a number: less than 5% of cluster CPU, and in most cases less than 2%. That figure is a claim in the project's own overview rather than a measurement published with it. The data sources list, held in the documentation rather than the README, is the place to check whether the protocol you need is captured at all.
PxL is the same language in the UI, the CLI and the API
Scriptability is the third pillar, and it is the one with the most reach. PxL is Pixie's flexible Pythonic query language, and it can be used across Pixie's UI, CLI and client APIs. That is the practical point: a query you build in the Live UI is not a different object from the one your client API call runs, so a dashboard built by hand in a browser can be turned into an automated check without translating the logic into another language. The root also carries .pxl.flake8rc, a flake8 configuration named for the language. The README links to the PxL reference in the documentation for the language itself.
Full-body capture is the feature and the exposure
The use cases are organised around what you can read, not around what you can install. Network monitoring covers the flow of network traffic and the flow of DNS requests within the cluster, individual full-body DNS requests and responses, and a map of TCP drops and TCP retransmits. Database query profiling traces several database protocols and gives latency, error and throughput rate for all pods, the same rate per normalized query, latency per individual full-body query, and individual full-body requests and responses. Request tracing gives full-body requests and responses for supported protocols plus error rate per service and pod. Service performance adds latency per service and endpoint and a sample of the slowest requests for an individual service, while continuous profiling looks inside application code and CPU flame graphs are broken down per pod and per node. Full-body means the request text and the response text are captured, and the latency figure per normalized query only exists because the query itself was read. The consequence is that this tool is a good fit for a cluster where seeing the request is the job, and a poor fit for one where payloads must never land in the cluster's own storage.
bpftrace and Go logging sit outside the built-in data model
Two of the documented capabilities are not protocol tracing at all. Distributed bpftrace deployment lets you deploy a bpftrace program to all of the nodes in your cluster; after deployment Pixie captures the output into a table and makes the data available to be queried and visualised in the Pixie UI, and TCP drops are the example given. Dynamic Go Logging is aimed at a narrower problem: debugging Go binaries deployed in production environments without needing to recompile and redeploy them. Both cases share a shape. Instead of asking a built-in data source about traffic, you bring your own probe and let Pixie carry the result into the same tables its own queries read, which is why the output can be visualised in the same UI rather than in a separate viewer. The cost is that neither path is self-contained. A bpftrace program has to be written, deployed to every node, and kept compatible with the kernels you run, and the visible release tags show that kernel work is still moving, with one of them named after updating kernel versions. Go logging narrows the blast radius to Go binaries and skips the rebuild step that a traditional profiler would ask for.
The overview prints no install command at all
Installation is the first thing a reader looks for and the README sends it elsewhere. It takes just a few minutes to install Pixie, and the Get Started section links to the install guides rather than showing a command. There is no manifest inline, no helm invocation and no copy-and-paste line anywhere in the overview. The tree does carry these top-level directories and files:
k8s/
skaffold/
docker.properties
ci/
tools/
src/
Once installed, the README names three ways in: a web-based Live UI, a CLI, and an API. That list matters more than it looks, because it is the same three surfaces PxL spans. For anyone building from the repository instead, the Go module header states the toolchain floor:
module px.dev/pixie
go 1.24.6
so a machine with an older Go cannot build the tree even if the platform itself is supported.
The latest release link only names one component
Versioning is where the README is most unusual, and the warning is its own: Pixie versions separate components separately, so what GitHub shows as the latest release will only be the latest for one of the components. It then maintains links to the latest releases for all components, and the visible entry in that list is CLI v0.8.8. The release tags themselves make the same point. The three most recent are all Vizier pre-releases: release/vizier/v0.14.16-pre-HEAD.40 on 2026-07-13, release/vizier/v0.14.16-pre-ddelnano-update-kernel-versions.38 on 2026-05-12 and release/vizier/v0.14.16-pre-ddelnano-fix-vizier-dns-parser-crash.39 on 2026-04-03. Two things follow for anyone pinning. The pre-HEAD suffix marks these as builds ahead of a release rather than releases themselves, and the branch name baked into each tag tells you which component and which change a build belongs to. A single version number for the whole product does not exist to pin.
The metadata says C++, the manifest says Go, the build says Bazel
The build story takes three forms at once. C++ is given as the primary language in the project metadata, and the tree carries .clang-format and .clang-tidy alongside it. The dependency manifest is Go, with go.mod, go.sum and go_deps.bzl at the root. The build itself is Bazel: BUILD.bazel, WORKSPACE, workspace.bzl, a pinned .bazelversion, plus .bazelrc, .bazelignore and .bazelproject. The root Makefile explains the division of labour, saying most of the actual build steps should be managed by Bazel, and its default target is a plain compile check:
CGO_ENABLED=0 go build ./...That target is invoked by CodeQL, which is why it is the first one in the file, and the same Makefile carries bazel clean for the build directories and bazel clean --exp to purge the build cache as well. Colour variables for the terminal output come from tput, made lazy so they are evaluated only on first use, with tput errors sent to /dev/null. The practical consequence for a reader is that a source checkout is not a self-contained build, since the Bazel workspace and its external dependencies have to be resolved before anything compiles.
Governance and lint configs sit next to the source
The root is unusually explicit about process, which tells you what a contribution has to satisfy. GOVERNANCE.md, MAINTAINERS, OWNERS and CODEOWNERS cover who decides and who reviews, CLA.md and CODE_OF_CONDUCT.md cover contributions and behaviour, SECURITY.md covers reporting, and CONTRIBUTING.md is the guide the README points at for code contributions. DEVELOPMENT.md sits beside them for anyone working on the tree itself. ADOPTERS.md and AUTHORS record who uses the project and who wrote it. Linting is configured per language rather than globally: .flake8rc, .golangci.yaml, .yamllint, .groovylintrc.json, .pxl.flake8rc and mypy.ini all sit at the root, and .fossa.yml, .snyk and codecov.yml cover dependency analysis, vulnerability scanning and coverage. prototool.yaml and .graphqlconfig handle the protobuf and GraphQL surfaces. On the community side the project calls itself community-driven, points at a Slack workspace, names its channel on the CNCF Slack, publishes a community meeting calendar and asks for feedback on the roadmap. That is a lot of process to read before a first patch, and none of it substitutes for the install guides.
Editorial conclusion
Pixie suits teams debugging a live cluster who want request bodies and query text without installing an agent in every application, and who are willing to spend cluster CPU on it. It does not suit anyone needing retention beyond the cluster or a single version number to pin, because the components are versioned separately. Before you deploy, read the install guides for your platform, decide whether full-body capture of your traffic is acceptable inside the cluster, and pick the component and tag you actually intend to pin rather than trusting whatever the latest release link shows.
Frequently asked questions
How do I install Pixie?
The README says it takes just a few minutes and links to the install guides on the documentation site without printing a command. Once it runs you interact through the web-based Live UI, the CLI or the API.
Does Pixie send cluster telemetry outside the cluster?
No. Pixie collects, stores and queries all telemetry data locally in the cluster. The cost it names is CPU: less than 5% of cluster CPU, and in most cases less than 2%.
What is PxL in Pixie?
PxL is Pixie's flexible Pythonic query language, and it can be used across Pixie's UI, CLI and client APIs. The repository root carries a .pxl.flake8rc configuration file.
What can Pixie capture that plain metrics miss?
Full-body requests and responses for supported protocols, individual full-body DNS requests and responses, latency per individual full-body query, error rate per service and pod, and latency, error and throughput rate per normalized query. Continuous profiling and CPU flame graphs per pod and node cover the code itself.
How do I debug a running Go binary with Pixie?
Dynamic Go Logging is the feature for it: debug Go binaries deployed in production environments without needing to recompile and redeploy. For other languages and kernel-level questions there is distributed bpftrace deployment, which sends a program to every node and captures its output into a table you can query in the UI.
Why does the latest release tag not tell me what to install?
Pixie versions separate components separately, so the latest release shown is the latest for one component only. The project keeps per-component links, currently listing CLI v0.8.8, and the recent tags are all Vizier pre-releases such as release/vizier/v0.14.16-pre-HEAD.40, so there is no single product version to pin.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pixie-io-pixie)Star history chart for your README
[](https://hysenlabs.com/projects/pixie-io-pixie)Was this useful?