PMD reads your code as a tree, and its language list promises more than its rules deliver
An extensible multilanguage static code analyzer.
At a glance
- What is it?
- PMD parses source into abstract syntax trees with JavaCC and Antlr and runs 400+ rules against them, with the CPD copy-paste detector in the same box. Coverage is uneven: Java and Apex carry the weight, Scala ships no rules at all, and more than half of the CPD language list has no rules behind it.
- Who is it for?
- PMD belongs in a Java or Apex build because its rules query the parsed tree instead of the text, and CPD adds duplication detection across a much wider set of languages. It is the wrong first choice for a Scala codebase, and for Go or Python work it delivers one half of its promise.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
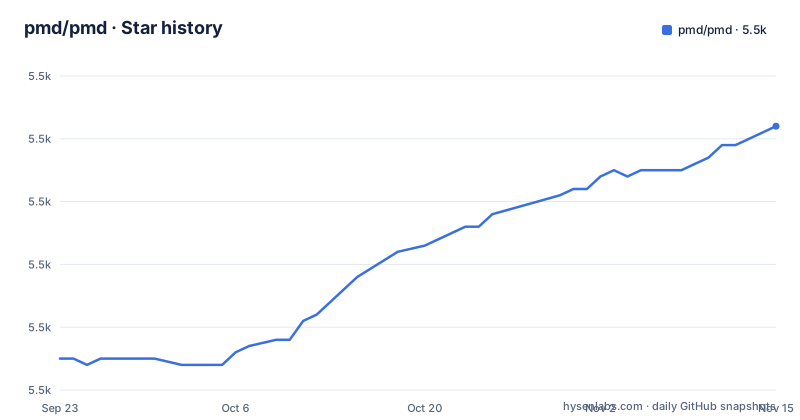
- pmd/pmd5,532 ★ · +37
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| pmd/pmd | 5.5k | 5.5k |
37 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
JavaCC and Antlr build the tree that every rule walks
PMD does not read source as text. It parses files into abstract syntax trees with JavaCC and Antlr, then runs rules against those trees. Two consequences follow. A rule can tell an empty catch block from a catch block that does work, and an unused variable from one that is read once, because it sees structure rather than spelling. And the rule vocabulary splits in two: a rule is either a Java class or an XPath query over the same tree, which is how the project accepts contributions from people who have no intention of writing a parser.
The flaw classes it targets are deliberately plain: unused variables, empty catch blocks, unnecessary object creation. The rule count is stated as 400+ built-in rules. The README states plainly that the tool is mainly concerned with Java and Apex, so those are the two trees where the count should be believable, and they are the honest place to start reading. What the repository text does not hand you is the reporting side. There is no documented severity scheme, no documented ruleset file format, and no documented output format. How a violation is ranked, rendered and turned into a build failure lives in the user documentation, not in the front page.
Scala is a parseable language with an empty rule set
The language list closes with a caveat that deserves more attention than it usually gets: Scala is supported, but there are currently no Scala rules available. Read precisely, that is not thin coverage. It is a language PMD can parse and then has nothing to say about, so a Scala file goes in and comes back without findings. That is a different outcome from having a weak ruleset, because a weak ruleset still flags something and gives you somewhere to start.
The repository layout makes this easier to misread than it needs to be. pmd-scala-modules/ sits at the top level next to pmd-java/, pmd-apex/, pmd-kotlin/ and pmd-swift/, and a directory named after a language reads like finished support. If you are rolling PMD across a mixed JVM estate, count Scala as uncovered for the version you install, and check the rule inventory for that version before promising anyone findings. A missing rule set is a fact about the release, not a bug you can file and wait on.
The documented command line is one subcommand and two launchers
Installation is one download and one command. Take the binary zip from the releases page at github.com/pmd/pmd/releases/latest, extract it, and the launcher lives at bin/pmd on Unix and bin\pmd.bat on Windows:
bin/pmd check
bin\pmd.bat check
The second line runs the same subcommand on Windows. That is the entire command line the repository documents, and the silence around it is wide. Nothing here explains how to select a ruleset, how to register a custom rule, how to choose an output format, how to read the exit code, or how to suppress one known violation in one file. Those answers sit behind the link to the user documentation. If you are putting PMD into a pipeline, treat the command above as the documented entry point, not as the interface you will configure. The only configuration visible in the repository itself is contributor tooling, in package.json:
{
  "devDependencies": {
    "all-contributors-cli": "^6.26.1"
  },
  "overrides": {
    "tmp": "^0.2.7"
  }
}
One dev dependency, the credits tool that writes the contributor list, and a pinned override on tmp. Nothing about analysis, which tells you where this repository's own front door ends.
CPD covers a far longer language list than the rules do
CPD, the copy-paste-detector, ships inside the same project and answers a different question, so it reaches a much wider set of files than the rule engine. Its list runs to Coco, C/C++, C#, CSS, Dart, Fortran, Gherkin, Go, Groovy, HTML, Java, JavaScript, JSP, Julia, Kotlin, Lua, Matlab, Modelica, Objective-C, Perl, PHP, PL/SQL, Python, Ruby, Salesforce.com Apex and Visualforce, Scala, Swift, T-SQL, TypeScript, Apache Velocity, WSDL, XML and XSL.
Put that beside the rule side, which names Java, JavaScript, Salesforce.com Apex and Visualforce, Kotlin, Swift, Modelica, PL/SQL, Apache Velocity, JSP, WSDL, Maven POM, HTML, XML and XSL, and the asymmetry is the whole story. Go, Python, Ruby, PHP, Perl, C#, C/C++, CSS, Dart and Fortran are duplication territory only: you get tokenised similarity detection and zero rules. The split is defensible on its own terms, since duplication is a property of text while a rule needs a language model and a maintained rule set. It is still the fastest way to overestimate this tool, because one name and one binary cover two very different maps. Read the longer list, assume it belongs to both halves, and you will budget for findings that never arrive.
There is a smaller counting problem in the same section. The overview claims support for 16 languages besides Java and Apex, while the sentence that follows names 15 including Java and Apex, with Scala mentioned separately. If language count drives your rollout plan, take the enumerated list and not the number in the overview.
Thirty-eight pmd-* modules, and two that promise a language
More than thirty pmd-* directories sit at the top level, and their names describe the build better than any overview would:
pmd-cli/
pmd-core/
pmd-dist/
pmd-java/
pmd-apex/
pmd-rust/
pmd-tsql/
pmd-dist/ is what you unzip, pmd-cli/ is the launcher behind bin/pmd, pmd-core/ holds the engine, pmd-doc/ the documentation, and pmd-test/ with pmd-lang-test/ are the harnesses that keep parsers honest. Alongside them sit mvnw and mvnw.cmd, the Maven wrapper, and javacc-wrapper.xml plus antlr4-wrapper.xml, which is the clearest sign that grammars are generated as part of a Maven build instead of being checked in. do-release.sh is how a release gets cut.
Two directories do not line up with either language list. pmd-tsql/ exists, and T-SQL appears in the CPD list but not in the rule-side list, so that module buys you duplication checks, nothing else. pmd-rust/ exists, and Rust appears in neither list, so nothing in the repository text claims you can point PMD at Rust code. A module directory is evidence of parser work, not of a language you can switch on. Count Rust as unsupported and T-SQL as duplication-only until the release you install says otherwise in writing.
Every integration decision is documented outside the repository
Everything past the launcher lives in documents you have to go and read. There are plugins for Maven and Gradle as well as for various IDEs, and the Tools / Integrations page is where their configuration is described. Rule authoring is split the same way: rules are written in Java or as an XPath query, and the designer for that work is a separate repository, pmd/pmd-designer, with its own developer documentation. The single worked example in the repository text is a demo run that analyses the openjdk/jdk source tree, which is the closest thing here to a sample violation report.
Support follows the same spread: Stack Overflow and GitHub Discussions for how-do-I questions and for why-did-this-error, the issue tracker for something believed to be a bug, a Gitter room for quick questions, and a Guru-based assistant linked from the front page. The cost is easy to underestimate. The repository readme answers what PMD is and how to start it, then leaves every decision that shapes your build (which ruleset, which suppression strategy, which plugin version to pin, what the exit code means) to external documentation. That is a normal arrangement for a project with this many modules, but it means the integration cost is a reading cost before it becomes a coding cost.
Monthly releases with a snapshot alongside, and rules that move
The release feed shows a monthly rhythm with a snapshot build riding next to it. 7.28.0 was published on 2026-09-25. 7.29.0 followed on 2026-10-30, and a 7.30.0-SNAPSHOT build was published the same day while carrying 01-November-2026 inside its own release name, which is how a snapshot gets dated here. The last push to the repository was 2026-11-01, so this is a working tree and not a preserved archive.
That is good news for parser coverage and a genuine cost for a rule-driven build. Rules get added and retuned, so a version bump can put fresh violations into a build that passed last week, and the reported count of 400+ is a moving target. Nothing in the repository text documents a deprecation path for an individual rule or a way to freeze rule behaviour across versions, so pin the version deliberately and read the release notes for rule changes rather than treating an upgrade as a patch bump. On terms, the README labels the licence BSD Style and links to the LICENSE file at the top level, next to a NOTICE file and a .all-contributorsrc. Read that LICENSE text before copying rule code into a closed source codebase, because a rule you fork becomes your code to maintain.
Editorial conclusion
PMD belongs in a Java or Apex build because its rules query the parsed tree instead of the text, and CPD adds duplication detection across a much wider set of languages. It is the wrong first choice for a Scala codebase, and for Go or Python work it delivers one half of its promise. Before adopting it, read the rule inventory for the exact version you will pin, open the LICENSE file rather than trusting a scanner's reading of it, and confirm that the subcommand you need is documented at all. Those three checks, not the 400+ rule count, decide whether it fits your pipeline.
Frequently asked questions
What does PMD stand for?
The repository never expands the acronym. It only describes PMD as an extensible multilanguage static code analyzer, mainly concerned with Java and Apex, shipping 400+ built-in rules and launched through the script bin/pmd.
What is PMD used for?
It finds common programming flaws such as unused variables, empty catch blocks and unnecessary object creation. It parses source into abstract syntax trees with JavaCC and Antlr, then runs rules against those trees, and a rule can be written in Java or as an XPath query.
How do I run PMD for the first time?
Download the binary zip from the releases page, extract it, and run bin/pmd check, or bin\pmd.bat check on Windows. The repository does not document the options for selecting a ruleset, choosing an output format or reading exit codes, so read the user documentation linked from the README before building a pipeline around it.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pmd-pmd)Star history chart for your README
[](https://hysenlabs.com/projects/pmd-pmd)Was this useful?