IoT DC3 decouples devices from applications through one bus, and refuses to start with default secrets
IoT DC3 is a multi-protocol, cloud-native, AI-powered, open-source industrial IoT platform evolving toward AI agents. A complete IoT system solution: device connectivity, data acquisition, edge-to-cloud delivery and intelligent operations.
At a glance
- What is it?
- An open-source industrial IoT runtime in Java, built as a six layer microservice system with 36 protocol drivers, a pluggable message broker, a PostgreSQL stack with time series, vector and graph extensions, and an MCP tool gateway that lets external agents query and write device points under per-tool authorization with an audit trail. The environment file documents why two secrets are deliberately absent from it.
- Who is it for?
- IoT DC3 is a fit when you have real field devices on real protocols and want one normalised stream that applications and agents can share without either side knowing about the other. Two things decide it for you.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
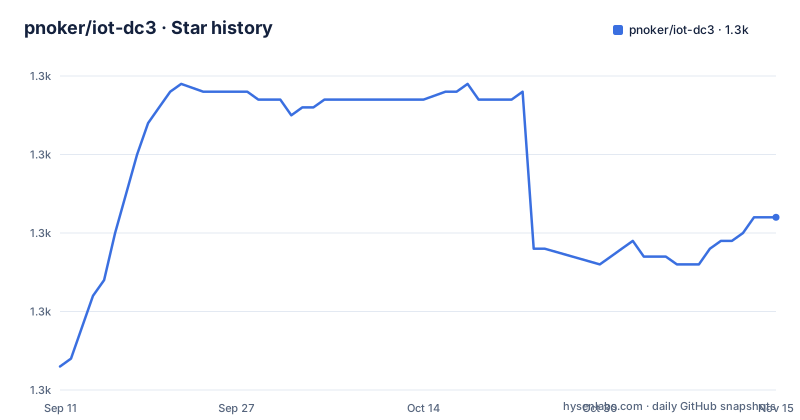
Star history
- pnoker/iot-dc31,272 ★ · +19
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| pnoker/iot-dc3 | 1.3k | 1.3k |
19 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The contract is one normalised point stream, and neither side knows the other exists
The architecture exists to make one sentence true: you can add or change devices without touching applications, and build new applications without touching devices.
The mechanism is a message bus in the middle. Drivers connect to field equipment, normalise what they read into point data, and push it into the bus. Applications consume from the bus through a single unified API. Neither side holds a reference to the other, so a driver for a protocol you did not have yesterday changes nothing above the bus, and an application written today does not care which protocol produced the points it reads.
That is the whole thesis of the project, and everything else in the repository is an implementation detail of it. The driver count, the four centre services, the time series storage and the agent gateway are all consequences of taking the decoupling seriously.
The cost of that choice is that point semantics become a platform-wide contract. If two drivers normalise the same physical quantity differently, every application above the bus inherits the ambiguity, and the fix is a platform change rather than a device change.
Six layers, four centre services, and an object model that keeps three shapes apart
The system is laid out as six layers, and the ordering is the dependency rule.
Clients call a gateway, the gateway fronts four centre services, the services talk over a message bus, the bus carries point data, 36 drivers sit below the bus, and field devices sit below the drivers. Everything above the drivers is one deployable set of services; everything below is one per protocol.
Two conventions hold the layering together. Cross-service calls always go through facade interfaces, which means a caller depends on an interface rather than on another service's internals. And a three-tier object model keeps persistence shapes, business shapes and API shapes strictly separated, so a schema change in storage does not propagate into the API contract.
Tenant isolation runs end to end across the database, the cache and the API paths, which is the only kind worth having. Isolating in the API but not in the cache is isolation with a hole, and this project lists all three paths together.
Persistence is PostgreSQL with three extensions: a time series extension for telemetry, a vector extension for embeddings, and a graph extension for relationship queries. That combination tells you the intended use of the agent layer before any feature list does it: time series for the data, vectors and graph for reasoning over it.
The agent gateway is the part with a governance story attached
The AI features are reached through a protocol boundary rather than through an internal API, and that choice is the interesting part.
The platform exposes a tool gateway speaking the Model Context Protocol, so external agents connect the same way any other tool-using agent would. Three things come with it. Agents register as OAuth clients, so identity is a standard mechanism rather than a bespoke token. Authorization is per tool, so an agent that can read a point is not thereby able to write one. And every tool call produces an audit trail entry.
That last combination is what makes an agent acceptable near a physical device. An agent that can write to a point on a production line is a different risk from one that can read, and per-tool authorization is the difference. The audit trail is what lets you reconstruct what the agent did at three in the morning.
Inside the platform, the agent centre is built on a Spring AI foundation and covers natural language operations through tool calling under access control, alarm analysis with root cause suggestions, natural language data queries that return charts, multi-turn conversation memory persisted to the database, and compatibility with any OpenAI API style provider.
The alarm analysis feature is the one to notice: it is the only listed capability that acts on something that already happened rather than on a query you asked.
Thirty-six drivers in five categories, plus an SDK for the ones that do not exist yet
The driver list is organised by what the thing on the other end is, not by vendor.
Industrial fieldbus and control protocols take the largest group: Modbus in both TCP and serial forms, OPC UA and the older OPC DA, Siemens S7, BACnet over IP, EtherNet/IP, two Mitsubishi families, Omron FINS, two IEC standards for power and substation automation, DNP3, two metering standards, KNX building automation, M-Bus, and a Chinese grid standard. Second group is IoT protocols: MQTT, CoAP, LwM2M, HTTP, Bluetooth Low Energy, Zigbee and LoRaWAN.
Then data bridging, which is the group people do not expect: MySQL, PostgreSQL, Oracle, SQL Server and Redis as data sources. Then basic communication and network management, covering raw TCP and UDP, serial, SNMP, CAN bus and Kafka. And finally two simulation drivers, one generating data and one listening for it.
The simulation pair is what makes the platform testable. Point data generated locally follows exactly the same path as point data from a meter on a bench, so an application can be developed and tested without any hardware at all.
On top of the catalogue there is a driver SDK for writing your own and registering it into the runtime. That matters because the 36 will never cover a site with a proprietary protocol, and the alternative is forking the platform.
The message broker is a variable, and the shipped ports are all non-standard
The internal asynchronous plane is pluggable, and the choice is a single setting.
RabbitMQ is the default. Kafka and Pulsar are named in the documentation, and any MQTT 5 broker is accepted, which is unusual for a platform whose primary job is industrial connectivity. The environment file widens the list further, adding RocketMQ and ActiveMQ, and every non-default choice carries its own connection variables.
Those variables are read conditionally: a broker specific address is only consulted when the broker type actually matches, so switching types cannot leave a stale address pointing at a host that is not running.
The port numbers are the other detail worth noticing. The example environment file moves the database to a port well above the default, and gives the broker three separate ports for its own traffic, its TLS traffic and its management interface. None of them are the conventional numbers. The stated purpose of the file is to be defaults for compose interpolation, so a plausible explanation is avoiding collisions with something already running on a developer machine, and either way it means the values in this file are not the values a reader would guess.
It also means a first deployment fails in a way that looks like a network problem rather than a configuration one.
Two secrets are left out of the example file on purpose, and production rejects known values
One comment block in the environment file is the most security-conscious thing in this repository.
Two variables are deliberately absent: a security key and an authentication HMAC secret. They are not set to placeholder values, they are not commented out with a suggestion, they are simply not there, and the comment explains that local runs take them from a separate file while production deployments must supply their own, with a command for generating a proper random value offered as an example.
Then the enforcement. Application, scale and swarm compose stacks refuse to start without them at all. The pre-production and production profiles go further and reject blank values or values that are publicly known, at startup.
That second check is the interesting one, because the local defaults in the same file include a database password that is the project name repeated three times. A developer who copies the example file, changes nothing, and deploys to production gets a container that will not boot rather than a container with a guessable credential. Failing closed is the right default and almost nobody does it.
The cost is that the first production deployment fails for a reason that has nothing to do with the deployment, so read the profiles before you plan the rollout.
The container build needs no JDK on your machine, and the Makefile has more targets than services
Two build systems coexist here, and each answers a different question.
The container file is unified and multi-target: one build, one per service, all from the same context. The comments at the top state the constraints that matter. The build context must be the repository root. Maven runs inside the builder stage, so no JDK or Maven is required on the host. And when the context and build arguments do not change, the builder stage cache is reused across service targets, so building ten service images does not run the dependency resolution ten times. There is also a documented override for building against a locally rebuilt runtime image, a compose path for building everything at once, and a multi-architecture example targeting both arm64 and amd64.
The Makefile is the developer interface, and its default goal prints help rather than building anything, which is the right choice for a target list this long. It resolves the environment file by preferring a real one and falling back to the example, points at a separate runtime environment file for local runs, and then fans out into per-service development targets, a set of validation targets for Java, web, command line and Python code as well as database initialisation, schema fingerprinting and reactive database migrations, plus deployment targets for compose stacks, Kubernetes and Helm.
The version numbering is calendar based, matching the image tag in the environment file, and two releases in one batch were published three seconds apart, which is what a re-tag looks like rather than two separate releases.
Editorial conclusion
IoT DC3 is a fit when you have real field devices on real protocols and want one normalised stream that applications and agents can share without either side knowing about the other. Two things decide it for you. If your estate is mostly MQTT or a database rather than industrial fieldbus, the driver count is less relevant than the bus and the agent gateway. And read the environment file before you deploy anything, because the project enforces secrets at startup in a way most platforms only document: two of them are left out on purpose, and the production profiles reject values that are blank or publicly known. The build is the easy part, since the container build needs no JDK or Maven on the host.
Frequently asked questions
What is IoT DC3?
An open-source industrial IoT runtime written in Java, positioned as a runtime for connecting physical devices to AI. It is a cloud-native microservice system built on Spring Boot 4 and Spring Cloud 2025 whose central design decision is that drivers push normalised point data into a message bus and applications consume it through one unified API, so devices and applications can be changed independently.
How many device protocols can IoT DC3 connect to?
It ships 36 access driver modules in five categories: industrial protocols such as Modbus TCP and RTU, OPC UA and DA, Siemens S7, BACnet over IP, EtherNet/IP, KNX, DNP3 and two IEC standards; IoT protocols including MQTT, CoAP, LwM2M, Bluetooth Low Energy, Zigbee and LoRaWAN; database bridging for MySQL, PostgreSQL, Oracle, SQL Server and Redis; basic communication and network management over TCP, UDP, serial, SNMP and CAN; and two simulation drivers. A driver SDK supports writing and registering your own.
How does IoT DC3 let AI agents control devices?
Through an MCP tool gateway that external agents connect to over the Model Context Protocol. Agents register as OAuth clients, authorization is per tool rather than per agent, and every tool call writes an audit trail entry. Internally the agent centre is built on Spring AI and covers tool calling under access control for querying devices and reading or writing points, alarm root cause analysis, natural language data queries, and multi-turn conversation memory persisted to the database.
Which database and message broker does IoT DC3 use?
PostgreSQL with three extensions: a time series extension for telemetry, a vector extension for embeddings and a graph extension for relationship queries. The internal message broker is pluggable per deployment, with RabbitMQ as the default and Kafka, Pulsar, any MQTT 5 broker, RocketMQ and ActiveMQ as alternatives, each with its own connection settings read only when that broker type is selected.
How is IoT DC3 deployed and how are its secrets handled?
A single multi-target container file builds every service from the repository root and runs Maven inside the builder stage, so no JDK or Maven is needed on the host, with a compose path for building everything and a multi-architecture example for arm64 and amd64. Two secrets are deliberately absent from the example environment file: the application, scale and swarm stacks refuse to start without them, and pre-production and production profiles additionally reject blank or publicly known values at startup.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pnoker-iot-dc3)Star history chart for your README
[](https://hysenlabs.com/projects/pnoker-iot-dc3)Was this useful?