postgrest puts your Postgres roles in charge of authorization, and its PUT is idempotent whether you like it or not
REST API for any Postgres database
At a glance
- What is it?
- PostgREST is an MIT-licensed Haskell server that exposes an existing PostgreSQL database as a REST API, handling authentication with JSON Web Tokens and delegating authorization to roles defined in the database. It also moves work into Postgres on purpose, serializing JSON in SQL and doing authorization there, versions APIs as database schemas, and generates its own OpenAPI description. What follows is what that design costs you.
- Who is it for?
- PostgREST suits a team whose data model is already in Postgres, whose access rules are already expressed as database roles, and who would rather ship a declarative API than maintain a hand-written service layer. It is a poor fit if your authorization has to live outside the database, because that delegation is the design rather than a feature you can switch off.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Haskell, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
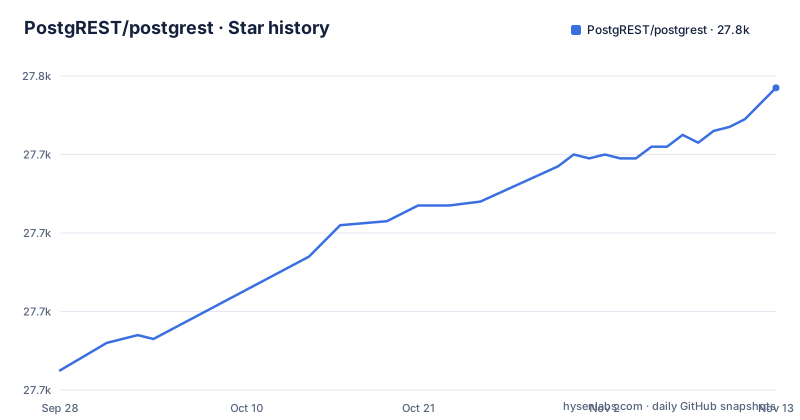
- PostgREST/postgrest27,757 ★ · +72
| Repository | 2026-09-28 | 2026-11-13 |
|---|---|---|
| PostgREST/postgrest | 27.7k | 27.8k |
72 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Authorization is the database's job, and the server connects as the caller
The security section states the arrangement plainly. PostgREST handles authentication via JSON Web Tokens and delegates authorization to the role information defined in the database, which the README calls a single declarative source of truth for security. When dealing with the database, the server assumes the identity of the currently authenticated user, and for the duration of the connection cannot do anything the user themselves could not. Two consequences follow from that sentence. First, there is no second authorization layer to fall back on, so a wrong grant in Postgres is a data exposure with nothing behind it. Second, you cannot move authorization into an external service without abandoning the model, because the privilege ceiling is enforced by Postgres itself. Other forms of authentication can be built on top of the JWT primitive, which means JWT is the mandatory foundation rather than one option among several. The only command the usage section prints is the help flag, so the binary itself tells you more than the README does:
postgrest --helpInstallation is handled elsewhere: the usage section sends you to the documentation page for installing PostgREST on your platform, and notes that you can also use Docker.
The database does the computing: JSON is serialized in SQL, counts come back in headers
The performance section explains the design by listing what is pushed into the database. Serializing JSON responses happens directly in SQL, as does data validation, authorization, combined row counting and retrieval, and posting data in a single command using returning *. On the client side the server keeps a pool of database connections, uses the PostgreSQL binary protocol, and is stateless so it can scale horizontally. The self-documentation section adds a detail that surprises people: the number of rows returned by an endpoint is reported by and limited with HTTP range headers, not in the response body. So a client that only parses JSON never learns the total row count, and paging logic has to read headers. The upside is that Postgres CPU becomes your scaling ceiling rather than the API server's, which is a good trade for read-heavy workloads and a bad one if you need the database free for other work.
API versions are database schemas, so versioning multiplies schemas
The versioning section describes a mechanism rather than a header. PostgREST does versioning through database schemas, which is what allows tables and views to be exposed without making the app brittle, and underlying tables can be superseded and hidden behind public facing views. That is a clean fit for a database-first team: a breaking change means creating a new schema, filling it with views over whatever the current tables are, and pointing a client at it. The cost is multiplicative and easy to underestimate. Every retained API version is a schema you must keep migrated as the underlying tables change, so a project with four supported versions carries four sets of views to maintain, and a view that drifts from its table reintroduces exactly the brittleness the mechanism was meant to remove. Schema sprawl also shows up in the generated OpenAPI description, since that is derived from what is exposed.
The OpenAPI description is generated, so it cannot drift but it also cannot be curated
PostgREST uses the OpenAPI standard to generate up-to-date documentation for APIs, and the README suggests a tool like Swagger-UI to render interactive documentation for demo requests against the live API server. The word that matters is generated. The description is derived from the live database, so it cannot go stale relative to the schema, which removes a whole category of documentation drift. Because it is generated, what it shows follows from what you expose in the database.
PUT is enforced as idempotent, so partial updates need another verb
The data integrity section is where the server's opinion of HTTP shows up. Rather than relying on an Object Relational Mapper and custom imperative coding, the system requires declarative constraints placed directly in the database, and the claim is that no application can corrupt your data, including the API server. The HTTP interface then carries safeguards to prevent surprises, and the one named is enforcing idempotent PUT requests. That is a real behavioural constraint rather than a style preference.
A v14 tag shipped in the same week as two v16 tags, so two lines get fixes
The three most recent releases are v16.5 on 2026-10-20, v16.4 on 2026-09-24, and v16.3 on 2026-09-11. The last push to the default branch, which is main, is dated 2026-10-30.
Three Haskell build systems coexist, each with its own lock file
The repository root carries the full set of Haskell toolchains side by side, which is unusual and worth knowing before you clone it. Cabal is there through Setup.hs, postgrest.cabal, cabal.project, and a frozen project file. Stack is there through stack.yaml and a lock file. Nix is there through flake.nix and flake.lock, plus default.nix, shell.nix, and a nix directory. A fourmolu configuration handles formatting, and a vendor directory sits at the root. Three build systems means three different dependency resolutions that can disagree, and a contributor has to pick one rather than discover the answer. Two other files are worth noting for what they say about distribution: a separate Docker Hub readme, which means the image's front page is a different document from the repository's, and a readthedocs configuration, since the README says the documentation lives in the docs directory inside this repository.
Editorial conclusion
PostgREST suits a team whose data model is already in Postgres, whose access rules are already expressed as database roles, and who would rather ship a declarative API than maintain a hand-written service layer. It is a poor fit if your authorization has to live outside the database, because that delegation is the design rather than a feature you can switch off. Before you commit, decide where your row-level rules will live, accept that the database becomes your compute and your scaling limit, and check which release you are on; the newest tag is v16.5.
Frequently asked questions
What is postgrest
It is a server written in Haskell that serves a fully RESTful API from any existing PostgreSQL database. The README describes it as providing a cleaner, more standards-compliant, faster API than you are likely to write from scratch, and it is MIT licensed.
What does PostgREST stand for and what is its purpose?
The README does not expand the name. Its stated purpose is to serve a fully RESTful API from any existing PostgreSQL database, handling authentication with JSON Web Tokens and delegating authorization to the roles defined in that database.
how to install postgrest
The README contains no install command. It points at the documentation for how to install PostgREST on your platform, and notes you can also use Docker. The only command it prints is the help flag, `postgrest --help`.
how to use postgrest
You point it at a database and it exposes whatever the schema makes reachable, with authorization coming from database roles. The row count for an endpoint comes back in HTTP range headers rather than the body, and API versions are handled through database schemas.
What are the key differences between Postgres and PostgREST?
They are layers rather than alternatives. Postgres is the database, and PostgREST is the API server that reads it, delegating authorization to roles defined there and pushing JSON serialization, validation, and row counting into SQL. The README describes PostgREST as serving a RESTful API from any existing PostgreSQL database.
postgrest vs graphql
The README makes no comparison with GraphQL or with any other API style. Its own position is a REST API over an existing PostgreSQL database, with work delegated to the database, versioning through database schemas, and an OpenAPI description generated from the live schema.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/postgrest-postgrest)Star history chart for your README
[](https://hysenlabs.com/projects/postgrest-postgrest)Was this useful?