projectdiscovery/httpx: a Go HTTP probing CLI, its default probes, and what breaks outside the terminal
httpx is a fast and multi-purpose HTTP toolkit that allows running multiple probes using the retryablehttp library.
At a glance
- What is it?
- projectdiscovery/httpx is a MIT-licensed Go command line toolkit that runs many HTTP probes against hosts, URLs and CIDR ranges. It is not the Python httpx client, it is built for one-shot CLI use, and several of its most useful probes are off until you ask for them.
- Who is it for?
- Pick httpx when you have a list of hosts, URLs or CIDR ranges and need status, title, TLS, CDN or similar facts in one pass from a terminal. Do not pick it as a Python HTTP client, and do not expose it as a long-running service.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
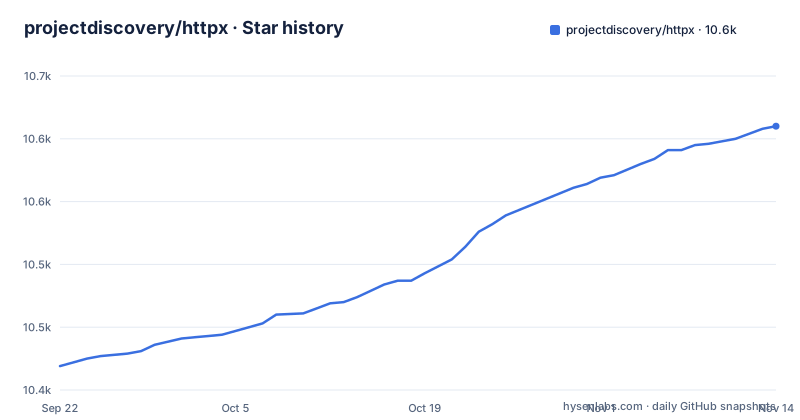
- projectdiscovery/httpx10,610 ★ · +191
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| projectdiscovery/httpx | 10.4k | 10.6k |
191 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
This is a Go reconnaissance CLI, not the Python httpx client
A lot of searches for httpx come from people who want the Python HTTP client, with questions about sync versus async use, AsyncClient and auth. This repository is a different program. It is written in Go, lives under the projectdiscovery organisation, is licensed MIT, and describes itself as a fast and multi-purpose HTTP toolkit that runs multiple probes using the retryablehttp library.
The practical consequence is that nothing here is installed with pip, and there is no import you can use from Python. The tool takes input, sends HTTP requests and prints facts about what answered. The other half of the description says it is designed to keep results reliable as the number of threads goes up, which is a statement about scanning many targets at once, not about making a single request from application code.
If you landed here wanting a Python client, this is the wrong project. If you wanted something that answers the question of what is listening at each of ten thousand hostnames, keep reading.
Thirty probes, and the expensive ones start switched off
The probe table lists default behaviour for each probe. These are on by default: URL, Title, Status Code, Content Length, TLS Certificate, CSP Header, Line Count, Location Header, Web Server, Web Socket, Response Time, Body Hash, IP, CNAME, Word Count, Request Method, Header Hash and URL Scheme.
These are off by default: Favicon Hash, Redirect chain, JARM Hash, Raw HTTP, HTTP2, HTTP Pipeline, Virtual host, CDN, Paths, Ports, Probe Status and ASN.
The consequence is easy to miss. A first run gives you status, title and server banner style data, and nothing about CDN presence, ASN, JARM fingerprints, favicon hashes or redirect chains. Each of those has its own switch, listed in the output of httpx -h, and you have to turn them on. If you compare two scans, make sure both used the same probe flags, or the output columns will not line up. Enabling every probe on a large input is a deliberate choice, since each extra probe adds work per target.
Input arrives as hosts, URLs, CIDR ranges, raw requests or a Burp file
The INPUT group of flags shows how targets get in. -l or -list reads a file of hosts, -u or -target takes one or more targets directly, -rr or -request reads a file containing a raw request, and -im or -input-mode sets the mode of the input file, with burp named as the value. The feature list adds that hosts, URLs and CIDR notation are all accepted.
Two behaviours shape what you get back. First, the tool falls back from https to http by default, so a host that does not answer on TLS is not simply reported as dead. Second, it does retries and backoffs aimed at handling WAFs, so a rate-limited or filtered target may take longer than a plain request but is less likely to be dropped on the first refusal.
The limit is that httpx probes over HTTP. A CIDR range expands into addresses, and any address that does not speak HTTP will produce nothing useful. It is a follow-up tool for a list of candidate web hosts, not a port scanner that discovers the list by itself, and the table lists Ports as a separate, disabled probe.
Installing needs a recent Go toolchain, and the stated floor disagrees with go.mod
The supported install path is a single Go command:
go install -v github.com/projectdiscovery/httpx/cmd/httpx@latestThe installation notes say httpx requires go >=1.26.10. The go.mod file in the repository declares go 1.27, so if your toolchain sits between those two numbers, expect the build to complain and check which one the compiler enforces. A distribution package with an old Go will not do.
Other routes exist in the repository layout. A Dockerfile builds an Alpine image that installs bind-tools, ca-certificates and chromium, copies a prebuilt httpx binary for the target platform into /usr/local/bin and uses httpx as the entrypoint. The image tag is alpine:latest, so the base moves under you. The repository also contains a Makefile whose build target compiles cmd/httpx/httpx.go, a .goreleaser.yml and a snapcraft.yaml. For anything beyond the go install line, the installation page at docs.projectdiscovery.io/tools/httpx/install is the place the project sends you, and the Docker Hub badge points to projectdiscovery/httpx.
After installing, check that the binary works:
httpx -hThe project warns of breaking changes and advises against running it as a service
The disclaimer is blunt on two points. The project is in active development and you should expect breaking changes with releases, so the changelog should be read before updating. It was also built primarily as a standalone CLI tool, and running it as a service may pose security risks, so it should be used with caution and additional security measures.
The release history backs up the first point. The tags v1.10.0 on 2026-07-09, v1.11.0 on 2026-08-31 and v1.12.0 on 2026-09-08 arrived close together, and the last push to the dev branch, which is the default, was on 2026-11-02. The repository is not archived. If you pin httpx inside a pipeline, pin an exact version and test the output format on each upgrade, because a script that parses a column can break between minor versions.
The service warning matters if you were thinking of wrapping httpx in a web endpoint that accepts target lists from users. The tool will send requests to whatever it is given, from inside your network. Nothing in the project material describes an access control layer, so that has to come from you.
Page classification needs a model file, and offline use means providing it yourself
Page type detection is opt-in, and by default the model is found and downloaded automatically from Hugging Face. For environments that cannot reach Hugging Face, you fetch the dit model.json on a machine that can, copy it across, and select it with -page-type-model or the short form -ptm:
httpx -l hosts.txt -kb -json -ptm /opt/httpx/model.json
httpx -l hosts.txt -fpt error,parked -ptm /opt/httpx/model.json
Setting -ptm alone does nothing. Classification only happens when you also use -kb or -fpt, and the older -fep is still accepted but deprecated. A local path bypasses discovery and download completely. If the file is missing, unreadable or invalid JSON, initialisation stops rather than falling back to a download.
Explicit models must pass a page and form classification check before scanning starts or any existing output index is changed. That check confirms the model can run, not that every part of its contents is sound. If classification fails on one response later, that response simply has no page type, and -debug shows the reason. Library users set Options.PageTypeModel next to KnowledgeBase or OutputFilterPageType. A scan that quietly lacks page types is therefore a sign to look at debug output.
Matching on body content uses -mdc, not -mr or -ms
The common recipes section shows a distinction that trips people up. -mr and -ms match against the full raw response. For structured fields such as content_type and body, use -mdc, which takes a DSL expression with helpers like contains and contains_any. The project says these recipes are validated in runner/wellknown_recipes_test.go.
Checking for a valid security.txt looks like this:
echo target.com | httpx -path '/.well-known/security.txt,/security.txt' -mc 200 -mdc 'contains(content_type, "text/plain") && contains(body, "Contact:") && contains_any(body, "mailto:", "https://")'-path tests custom paths, -mc 200 matches HTTP 200, and -mdc applies the expression to response fields. The robots.txt recipe is shorter:
echo target.com | httpx -path '/robots.txt' -mc 200 -mdc 'contains(content_type, "text/plain")'The content type check matters because many servers return a 200 page with HTML for any path. Without it, a soft 404 would pass as a hit. The expression is only as strict as what you write, so a recipe for a new file type needs its own content checks.
Using it as a Go library means building an Option struct and calling RunEnumeration
httpx can be embedded. You create an instance of the Option struct, fill it with the same settings you would pass on the command line, validate it, pass it to a runner instance that you close at the end of the program, and call the RunEnumeration method. The repository carries two examples, examples/simple and examples/speed_control, and the project points to the examples folder for a minimal working version.
The cost is that you take on the same moving target as the CLI. With breaking changes expected between releases, the struct fields you rely on can shift, so pin the module version. The dependency list in go.mod is also large: it pulls in projectdiscovery modules such as tlsx, cdncheck, asnmap, fastdialer, ratelimit and rawhttp, plus jarm-go, go-rod, goquery and the dit classifier. That is the footprint of the probe set. If you only need a status code, a plain net/http call is far smaller, and httpx earns its place only when you want many probes handled in one pass.
Editorial conclusion
Pick httpx when you have a list of hosts, URLs or CIDR ranges and need status, title, TLS, CDN or similar facts in one pass from a terminal. Do not pick it as a Python HTTP client, and do not expose it as a long-running service. Before relying on a result, check which probes are off by default and read the changelog before every upgrade, because the project warns about breaking changes.
Frequently asked questions
What does HTTPX do?
projectdiscovery/httpx is a fast and multi-purpose HTTP toolkit written in Go. It runs multiple probes such as status code, title, TLS certificate and web server against hosts, URLs and CIDR ranges using the retryablehttp library.
Is HTTPX a Python client?
Not this one. projectdiscovery/httpx is a Go command line tool installed with go install, and it is a different project from the Python HTTP client of the same name.
how to install httpx
Run go install -v github.com/projectdiscovery/httpx/cmd/httpx@latest. The project states it needs go >=1.26.10, and go.mod declares go 1.27.
how to use httpx tool
Run httpx -h to list every switch, then feed it targets with -l for a file of hosts or -u for direct targets. Probes that are off by default, such as ASN, CDN and JARM hash, need their own flags.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/projectdiscovery-httpx)Star history chart for your README
[](https://hysenlabs.com/projects/projectdiscovery-httpx)Was this useful?