Katana: a Go crawler with standard and headless modes, scope filters and a content-similarity budget
A next-generation crawling and spidering framework.
At a glance
- What is it?
- projectdiscovery/katana is an MIT-licensed Go crawling and spidering framework built for automation pipelines. It can fetch with the plain Go HTTP library or drive a headless browser, and it limits crawl effort with scope rules and page-similarity filtering.
- Who is it for?
- Katana suits security and automation engineers who need to enumerate endpoints on sites they are authorised to test, and who want to feed URL lists in from tools like httpx and read results as lines or JSON. It is a poor fit if you need a quick install without a recent Go toolchain or a browser, or if you expect standard mode to see endpoints that only appear after JavaScript renders the page.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
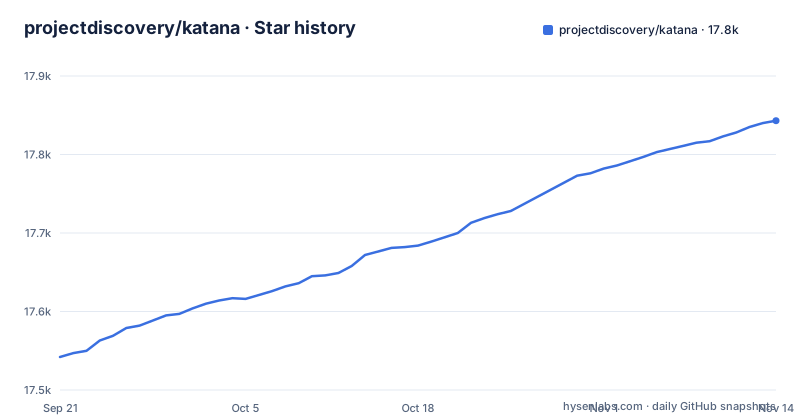
- projectdiscovery/katana17,843 ★ · +301
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| projectdiscovery/katana | 17.5k | 17.8k |
301 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Standard mode is fast because it never renders the page, and that is also its blind spot
Katana has two crawling modes. Standard mode uses the standard Go http library to handle requests and responses. It is much faster because there is no browser overhead, but it analyses the response body as is, without any JavaScript or DOM rendering. The README warns that this can miss post-DOM-rendered endpoints and asynchronous endpoint calls in complex web applications, for example those that depend on browser-specific events.
The consequence is straightforward. On a server-rendered site, standard mode may be all you need. On a single-page application, a crawl in standard mode can return a short list that looks complete but is not. If the number of endpoints seems too low for the size of the app, switch modes before concluding there is nothing more to find. Standard mode still has a use: it is the cheap first pass that tells you how large the site is before you pay for a browser.
Headless mode uses a real browser, so it needs Chrome or Chromium and costs speed
Headless mode hooks internal headless calls to handle requests and responses directly in the browser context. The README gives two advantages: the HTTP fingerprint, meaning TLS and user agent, identifies the client as a legitimate browser, and coverage is better because endpoints are discovered from both the raw response and the browser-rendered one.
The browser has to exist on the machine. The Docker image installs chromium through apk, and the Ubuntu instructions add the Google Chrome apt repository and install google-chrome-stable as a prerequisite. The Docker command for a headless run is:
docker run projectdiscovery/katana:latest -u https://tesla.com -system-chrome -headlessHeadless trades the speed of standard mode for coverage. Use it on targets where standard mode comes back thin, and expect a heavier run.
Installation needs Go 1.26.10 or newer and CGO enabled for the go install route
The README says katana requires Go 1.26.10 or newer to install, and go.mod declares go 1.26.10. It also advises trying the latest Go if you hit installation problems, because the minimum may have changed. The install line is:
CGO_ENABLED=1 go install github.com/projectdiscovery/katana/cmd/katana@latestA pre-compiled binary is available from the releases page, and a Docker image exists for people who do not want a Go toolchain. The Ubuntu route installs snap golang and Chrome first. The practical result is that a stale distro Go package will not do for the source install. If your CI image carries an older Go, use the binary or the container instead of upgrading the image just for this tool. The CGO_ENABLED=1 setting also means a C toolchain has to be available on the build machine, which matters on minimal images.
Input comes from a URL, a list or stdin, which is what makes it fit in pipelines
Katana requires a URL or endpoint to crawl and accepts one or many. The -u option takes a URL or comma-separated values, -list reads a file, and piped stdin also works. The README shows chaining it behind another ProjectDiscovery tool:
cat domains | httpx | katanaOutput goes to stdout, a file, or JSON. Other input flags include -resume, which resumes a scan using resume.cfg, and -e or -exclude, which excludes hosts matching a filter such as cdn, private-ips, a CIDR, an IP or a regex. The depth flag -d defaults to 3, and -jc enables JavaScript endpoint crawling. Because depth defaults to 3, a first run against a large site is bounded, and you should raise it deliberately instead of assuming the default is exhaustive.
Page content similarity filtering caps wasted crawling, with three selectable algorithms
An optional layer filters pages after exact MD5 content deduplication. Shared HTML normalisation strips chrome such as nav, header, footer and scripts, then one of three modes decides whether a page is similar enough to skip further parsing and enqueueing. The simhash mode, the default, is for near-duplicate and template clones and uses a Hamming distance set by -pcsd. The tfidf mode gives topical cosine similarity, and the bm25 mode adds length normalisation, both tuned with -pcst. URL-shape deduplication with -fsu remains independent. A tuned run looks like this:
katana -u https://shop.example.com -pcs -pcsm tfidf -pcst 0.85 -pcsn 2The README's sample output shows 103 pages processed, 30 accepted and 73 filtered, a 70.9 percent filter rate, with 21 endpoints found in 14 seconds. That is one example run, not a benchmark. The risk of similarity filtering is that it can skip a page that looks like its neighbours but carries a different parameter, so compare results with and without it on a target you know.
The knowledge base downloads a model on first use, and form filling is automatic
The feature list includes customizable automatic form filling and a knowledge base that does machine-learning page-type and form classification using an auto-downloaded model. Scope control works through preconfigured fields or regular expressions, and the output uses preconfigured fields.
Two cautions follow. Automatic form filling means the crawler submits data into forms it finds, so aim it only at systems where that is acceptable, and review the form-filling settings before a run against anything with side effects such as sign-up or checkout forms. The auto-downloaded model means a first run may fetch something over the network, which matters on an offline or locked-down build host. Check the project documentation before running in an air-gapped environment.
The tool prints a liability warning, and the default branch is dev
The sample output begins with two warnings: use with caution because you are responsible for your actions, and the developers assume no liability and are not responsible for misuse or damage. Keep the target list to systems you are authorised to scan, because the tool itself disclaims responsibility for what you do with it.
The recent releases are v1.8.0 on 2026-10-05, v1.7.0 on 2026-08-05 and v1.6.1 on 2026-05-05. The last push was on 2026-11-02, and the default branch is dev, not main or master. The sample banner in the README shows v0.0.1, which is example output and not the current version. The repository builds with a Makefile that links statically on non-darwin systems, and it keeps an integration_tests directory.
The container image bundles Chromium on Alpine, and the build links statically outside macOS
The Dockerfile starts from alpine:latest, adds bind-tools, ca-certificates and chromium through apk, copies in the katana binary for the target platform and sets katana as the entrypoint. That is why the Docker headless command above works without installing Chrome yourself, and why arguments you pass after the image name go straight to katana.
The go.mod file shows the building blocks: go-rod/rod for browser control, goquery for HTML parsing, jsluice from ProjectDiscovery for JavaScript analysis, wappalyzergo, simhash, ratelimit, retryablehttp-go, fastdialer and goflags. The Makefile builds cmd/katana/main.go with ldflags that link statically on every OS except darwin, and provides test, integration, tidy and lint targets. If you build from source on Linux, the static link flag is part of the standard make target.
Editorial conclusion
Katana suits security and automation engineers who need to enumerate endpoints on sites they are authorised to test, and who want to feed URL lists in from tools like httpx and read results as lines or JSON. It is a poor fit if you need a quick install without a recent Go toolchain or a browser, or if you expect standard mode to see endpoints that only appear after JavaScript renders the page. Before using it, choose standard or headless mode deliberately and set depth and scope on a small target first.
Frequently asked questions
How do I install Katana?
Katana needs Go 1.26.10 or newer for the source install, run with CGO_ENABLED=1 go install github.com/projectdiscovery/katana/cmd/katana@latest. You can also download a pre-compiled binary from the release page or pull the projectdiscovery/katana Docker image.
How do I use Katana?
Run katana -u with a URL, give it a file with -list, or pipe URLs in on stdin. Use katana -h to see all switches, and add -headless for headless mode.
What is the difference between Katana's standard and headless modes?
Standard mode uses the Go http library and is faster, but it does not render JavaScript or the DOM. Headless mode runs requests in a browser context, so it identifies as a legitimate browser and finds more endpoints.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/projectdiscovery-katana)Star history chart for your README
[](https://hysenlabs.com/projects/projectdiscovery-katana)Was this useful?