Prometheus Operator: ten CRDs, a bundle.yaml quickstart, and the v1alpha1 catch
Prometheus Operator creates/configures/manages Prometheus clusters atop Kubernetes
At a glance
- What is it?
- Prometheus Operator turns Kubernetes custom resources into Prometheus deployments, scrape configuration, and rules, across ten custom resources. The bundle.yaml quickstart installs a controller with no monitoring stack behind it, and agent mode and out-of-cluster scraping sit on an unstable API group.
- Who is it for?
- Prometheus Operator is the right pick when scrape configuration, alerting rules, and Alertmanager routing should live as versioned Kubernetes objects instead of hand-maintained configuration files, and when you accept that agent mode and out-of-cluster scraping arrive on an unstable v1alpha1 API.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
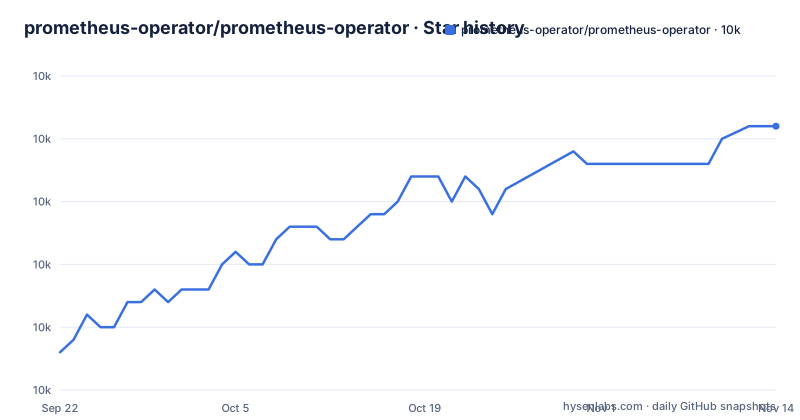
- prometheus-operator/prometheus-operator9,996 ★ · +18
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| prometheus-operator/prometheus-operator | 10k | 10k |
18 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The operator reconciles the API server, it never reads a config file
The Prometheus Operator's job is to monitor the Kubernetes API server for changes to specific objects and ensure the current Prometheus deployments match those objects. It acts on ten custom resources: Prometheus, PrometheusAgent, Alertmanager, ThanosRuler, ServiceMonitor, PodMonitor, Probe, ScrapeConfig, PrometheusRule, and AlertmanagerConfig. A Prometheus resource defines a desired deployment, so versions, persistence, retention policies, and replica counts come from a native Kubernetes object rather than a flags file. ServiceMonitor and PodMonitor exist to remove hand written target configuration: the operator automatically generates Prometheus scrape configuration based on the current state of the objects in the API server, which is why the stated purpose of the project is to simplify a Prometheus based monitoring stack without learning a Prometheus specific configuration language.
The flip side of that design is scope. The operator renders what your custom resources describe and nothing more. Alert rules you did not declare and Alertmanager routing you did not specify are outside what it will build for you. The design page at prometheus-operator.dev/docs/getting-started/design/ is where the individual CRDs are explained.
bundle.yaml deploys the controller into the default namespace and stops there
The quickstart is deliberately narrow, and the README opens it with a note that the quickstart does not provision an entire monitoring stack, pointing at kube-prometheus for that. To try out just the Prometheus Operator inside a cluster, you choose a release and run:
kubectl create -f bundle.yamlThat deploys the operator in the `default` namespace. The README says this quickstart does not provision an entire monitoring stack. The consequence worth planning for is that an operator watching an empty custom resource set has nothing to reconcile, so metrics for your own workloads stay absent until somebody authors ServiceMonitor or PodMonitor objects. That is not a broken install, it is an install with no work assigned to it.
If you already applied the bundle and now want the full stack, the same note tells you to delete the bundle first:
kubectl delete -f bundle.yamlOverlaying stack manifests on top of a bundle already sitting in the namespace is the exact situation that instruction exists for. Neither code path installs kube-prometheus for you.
ServiceMonitor and PodMonitor generate scrape configuration
Target discovery is the part people expect to be automatic, and it is the part that needs objects written by hand. A ServiceMonitor declaratively specifies how groups of Kubernetes services should be monitored, and the operator automatically generates Prometheus scrape configuration based on the current state of the objects in the API server. A PodMonitor does the same for groups of pods. A Probe declaratively specifies how groups of ingresses or static targets should be monitored, and a ScrapeConfig declaratively specifies scrape configurations to be added to Prometheus, which is the resource aimed at scraping resources outside the Kubernetes cluster.
Because the configuration is generated from the objects you submit, the result is only as good as the labels on your workloads, and the operator's contribution stops at rendering what your selectors match. Check the target list in Prometheus after creating a monitor rather than reading an empty graph as proof that the objects are correct. ScrapeConfig can describe targets outside the Kubernetes cluster and lives on the v1alpha1 surface described next. Prometheus also supports additional scrape configuration supplied through `additionalScrapeConfigs`, so monitor objects are not the only way to define targets.
Three API groups carry three different stability promises, and two of them are unstable
The project grades its own API surface. `monitoring.coreos.com/v1` is the stable group, where changes are made in a backward-compatible way. `monitoring.coreos.com/v1beta1` is unstable, changes can happen, and the team is focused on avoiding them, though production use is encouraged for people who accept the risk of breaking changes. `monitoring.coreos.com/v1alpha1` is unstable with changes happening frequently, and the guidance is to avoid it in mission-critical environments. The operator itself is called production ready, but the README routes you to the CRD versions for the status of each CRD rather than making a blanket claim about all of them.
The Makefile shows where that split lands in the tree. The v1 targets are types.go, alertmanager_types.go, podmonitor_types.go, probe_types.go, prometheus_types.go, servicemonitor_types.go, and thanos_types.go, while PrometheusAgent and ScrapeConfig exist only under pkg/apis/monitoring/v1alpha1, and AlertmanagerConfig ships in both v1alpha1 and v1beta1. So agent mode and scraping outside the cluster are the two capabilities you cannot deploy on a stable API. Treat a script that writes PrometheusAgent or ScrapeConfig manifests as version-coupled, and read the per-CRD version before a dependency on it hardens.
PrometheusRule gets an admission webhook, and the webhook is scoped to that one resource
An admission webhook is provided to validate PrometheusRule resources upon initial creation or update. The stated purpose is to prevent invalid Prometheus alerting and recording rules from causing failures in a deployed Prometheus instance, so a broken expression group is rejected at apply time instead of after Prometheus has started and reloaded it. The operator generates a rule file from each PrometheusRule, which is what makes validation at the API boundary worthwhile.
What the guard rail covers matters more than that it exists. The README names PrometheusRule as the resource the admission webhook validates. A reviewer should also keep expectations straight, since validation catches what Prometheus refuses to parse, not whether a valid expression matches anything worth waking someone for. The user guide at prometheus-operator.dev/docs/platform/webhook/ holds the deployment details.
The build publishes three images, and a self build is not labeled with the release you are matching
Installing from a release means applying a bundle. Building from source is a different shape of job, and the Dockerfile is explicit about it: ARG ARCH=amd64, ARG OS=linux, ARG GOLANG_BUILDER=1.26, a builder stage on quay.io/prometheus/golang-builder:${GOLANG_BUILDER}-base, and a final image of quay.io/prometheus/busybox-${OS}-${ARCH}:latest carrying the binary at /bin/operator under USER 65534 with ENTRYPOINT ["/bin/operator"]. go.mod declares go 1.26.10, so a local build needs that toolchain before anything else.
The Makefile names the images involved:
IMAGE_OPERATOR?=quay.io/prometheus-operator/prometheus-operator
IMAGE_RELOADER?=quay.io/prometheus-operator/prometheus-config-reloader
IMAGE_WEBHOOK?=quay.io/prometheus-operator/admission-webhook
That is three image repositories, not one. Note also that TAG defaults to the short git SHA, so a locally built image tag is a commit hash rather than a release tag. CRD_OPTIONS ?= "crd:crdVersions=v1" is the knob that decides which CRD API versions the generated manifests carry, and it is worth setting deliberately when you regenerate.
kube-prometheus and the community chart are the layers that actually assemble a stack
Three deliverables get confused here. The Prometheus Operator is the controller that uses custom resources to simplify deployment and configuration of Prometheus, Alertmanager, and related components. kube-prometheus provides example configurations for a complete cluster monitoring stack based on Prometheus and the Prometheus Operator, which includes deployment of multiple Prometheus and Alertmanager instances, metrics exporters such as the node_exporter for gathering node metrics, scrape target configuration linking Prometheus to various metrics endpoints, and example alerting rules for notification of potential issues in the cluster. The prometheus-community/kube-prometheus-stack Helm chart provides a similar feature set to kube-prometheus and is maintained by the Prometheus community rather than here.
The practical consequence is that the bundle layers carry a Prometheus version this repository does not pin for you. At v0.94.2 the module requires prometheus/prometheus v0.315.1, alertmanager v0.34.2, thanos v0.42.5, and k8s.io/api v0.37.2, while the operator's own pkg/apis/monitoring and pkg/client modules are pinned at v0.94.2. Check which Prometheus version your chosen bundle ships before assuming the newest CRD fields will take effect. The v0.94.2 tag was cut on 2026-10-22, v0.94.1 on 2026-09-23, v0.94.0 on 2026-09-09, and the last push to the repository landed on 2026-11-02.
Editorial conclusion
Prometheus Operator is the right pick when scrape configuration, alerting rules, and Alertmanager routing should live as versioned Kubernetes objects instead of hand-maintained configuration files, and when you accept that agent mode and out-of-cluster scraping arrive on an unstable v1alpha1 API. Skip it, or start from kube-prometheus, if you want a working monitoring stack in a single apply, because the bundle.yaml quickstart leaves every ServiceMonitor, PrometheusRule, and AlertmanagerConfig object for you to write. Before committing, check that the cluster runs Kubernetes 1.16.0 or newer, confirm the CRD version for each resource you plan to use against prometheus-operator.dev, and verify the Prometheus version your chosen bundle ships against the operator release you install.
Frequently asked questions
what is prometheus operator
It provides Kubernetes native deployment and management of Prometheus and related monitoring components, using custom resources to deploy and manage Prometheus, Alertmanager, and related components without hand written target configuration.
how to install prometheus operator on kubernetes
Kubernetes 1.16.0 or newer is required. Choose a release and run `kubectl create -f bundle.yaml`, which deploys the operator in the `default` namespace, and note that the quickstart intentionally does not provision a full monitoring stack.
prometheus operator servicemonitor vs podmonitor
A ServiceMonitor declaratively specifies how groups of Kubernetes services should be monitored, while a PodMonitor does the same for groups of pods. For both, the operator automatically generates Prometheus scrape configuration from the current state of the objects in the API server.
prometheus operator vs kube prometheus stack
The operator is the controller that manages Prometheus through custom resources. kube-prometheus supplies example configurations for a complete cluster monitoring stack, and the prometheus-community/kube-prometheus-stack chart offers a similar feature set maintained by the Prometheus community.
prometheus operator vs prometheus
Prometheus is the monitoring system itself, and the operator is the Kubernetes controller that deploys and configures it. A Prometheus resource defines a desired deployment, while ServiceMonitor, PodMonitor, Probe, and ScrapeConfig objects drive the generated scrape configuration.
what does prometheus operator do
It monitors the Kubernetes API server for changes to its custom resources and ensures that matching deployments and configurations are kept in sync, covering Prometheus, PrometheusAgent, Alertmanager, ThanosRuler, ServiceMonitor, PodMonitor, Probe, ScrapeConfig, PrometheusRule, and AlertmanagerConfig.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/prometheus-operator-prometheus-operator)Star history chart for your README
[](https://hysenlabs.com/projects/prometheus-operator-prometheus-operator)Was this useful?