protobuf.js: .proto in the browser without protoc, and what that costs
High-performance Protocol Buffers for JavaScript and TypeScript. Conformant through Edition 2026, and unusually versatile. No protoc required.
At a glance
- What is it?
- protobuf.js loads .proto schemas at runtime and generates static code and TypeScript declarations through a separate CLI package, with no protoc in either path. The reflection side adopts in minutes and then makes you pay in memory overhead, discarded unknown fields and an explicit 64-bit conversion decision.
- Who is it for?
- Adopt protobuf.js when .proto files come from another team and you need to parse them without a compiler on the machine, or when a browser build has to ship the schema rather than generated output. Do not adopt it if your payloads are large enough that a fully decoded message tree is a memory concern, or if you need 64-bit integers to survive a round trip without checking every conversion call.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
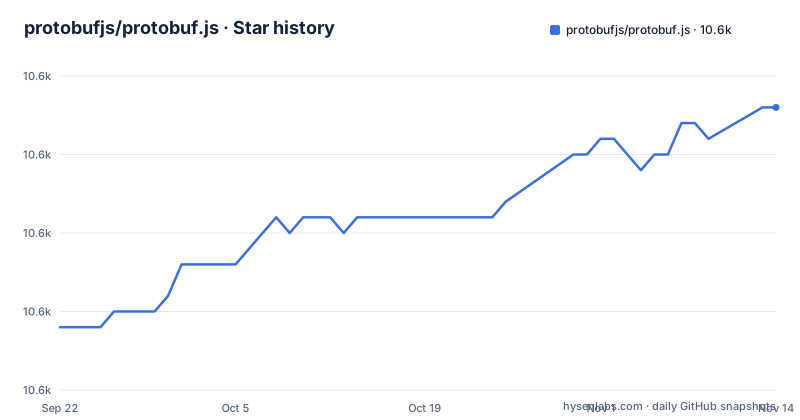
- protobufjs/protobuf.js10,608 ★ · +14
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| protobufjs/protobuf.js | 10.6k | 10.6k |
14 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The 7.x and 8.x npm lines both released on 2026-08-27
Two npm release lines are live at once. protobufjs 8.8.1 was published on 2026-10-11, protobufjs 7.6.6 on 2026-08-27 at 10:12:51Z, and protobufjs-cli 2.7.1 on 2026-10-11. The package.json on master reads 8.8.1, so the 8.x line is where changes land and 7.x is still being cut. Pinning a version is therefore an explicit choice between two supported lines.
The last push to master was on 2026-11-01 and the repository is not archived, so recent activity is not the question here. The single runtime constraint declared in package.json is "engines": { "node": ">=12.0.0" }, with no browser matrix or platform list next to it. Releases come from release-please, configured in release-please-config.json with its manifest at .release-please-manifest.json, which is why the tag names carry the protobufjs-v prefix. Renovate is configured too.
load() resolves imports against the importing file
Parsing happens at runtime. You hand load() a file, it returns a Root, and lookupType() walks that tree by fully qualified name. The example schema declares package awesomepackage with one string field numbered 1, and protobuf.js rewrites awesome_field to awesomeField in JavaScript unless you pass the keepCase option when loading or parsing.
syntax = "proto3";

package awesomepackage;

message AwesomeMessage {
  string awesome_field = 1;
}
Imports resolve relative to the importing file by default, so a schema that imports a second schema does not spell out that path. When that default does not match your layout, the documented fix is to construct a Root yourself, override root.resolvePath, and then call root.load(). A callback form of load() is available, and loadSync() gives synchronous loading on Node.js.
encode() trusts whatever object you hand it
The runtime refuses to guess. encode() accepts a message instance or an equivalent plain object and does not verify input implicitly, so a wrong field type becomes a wrong buffer rather than an error. Four separate entry points exist for that reason: create() for data already known to be valid, verify(), which returns null or an error string, fromObject() for broader JavaScript input, and toObject() for controlling the output shape.
const payload = { awesomeField: "hello" };

// Optionally create a message instance from already valid data
const message = AwesomeMessage.create(payload);

const encoded = AwesomeMessage.encode(message).finish();
const decoded = AwesomeMessage.decode(encoded);
The plain object contract is narrow. Numbers for 32-bit numeric fields, booleans for bool, strings for string, a Uint8Array or Buffer for bytes, arrays for repeated fields, plain objects for maps. Map keys are the part worth reading twice: they are the string representation of the value, or an 8-character hash string when the key is 64-bit. Since encode() does not verify input implicitly, a key that does not meet that rule is not rejected at the call site.
Unknown fields are discarded before you ever see them
Forward compatibility runs one way by default. Unknown fields present on the wire are intentionally discarded, which the README calls the safer default, and the stated reason is that decoded structures already carry runtime memory overhead beyond their encoded representation. Two escape hatches exist: reader.discardUnknown = false on an individual reader, or Reader.discardUnknown = false to change the default for readers created afterwards. Anything kept that way is dropped explicitly with delete message.$unknowns.
For a gateway that has to round-trip messages it does not fully understand, that default costs you data on the first hop. An intermediary built against an older schema decodes a message that carries a newer field, and re-encoding it sends the message on with that field gone. Turning it off moves the cost to memory on every message you decode. The mitigation the README gives for untrusted input is to apply input-size and concurrency limits to bound memory use, which tells you the shape of the exposure: a stream of length-delimited messages is a memory sizing decision before it is a parsing one.
longs: Number is the option that loses your integers
Conversion is where 64-bit values quietly break in JavaScript, and protobuf.js makes the choice explicit instead of hiding it. fromObject accepts enum values by name, base64 bytes, decimal 64-bit strings, Long, and BigInt. toObject takes a ConversionOptions object in which longs: BigInt produces bigints, longs: String produces decimal strings, and longs: Number produces JavaScript numbers that may lose precision. enums: String returns names instead of numbers, bytes: String returns base64. defaults: true includes unset fields, arrays: true adds empty arrays for repeated fields, objects: true adds empty objects for maps, oneofs: true adds virtual discriminator properties.
const message = AwesomeMessage.fromObject({ awesomeField: 42 });
const object = AwesomeMessage.toObject(message, {
  longs: String,
  enums: String,
  bytes: String
});
Two consequences follow. Convert with longs: Number, serialize, and 64-bit integers that JavaScript cannot represent exactly are already altered before anything leaves your process. And the output shape moves with the options object, so toObject without options does not produce the same JSON as toObject with defaults: true, which matters to anything that hashes or snapshots that object. message.toJSON() takes the default path and accepts none of these switches.
The CLI is a second package, and it still skips protoc
Runtime reflection is only half the surface. The generator ships separately as an add-on so production installs do not carry it:
npm install protobufjsnpm install --save-dev protobufjs-cliThe split is deliberate and matches the flags above: protobufjs belongs in dependencies, protobufjs-cli in devDependencies. That package is a JS-native toolchain which does not require setting up protoc, and it generates reflection bundles, static code and TypeScript declarations. If you prefer a protoc-based workflow, the same package provides protoc-gen-pbjs as an option, so returning to generated code does not mean adopting a foreign toolchain. For browsers, canonical builds come from the jsDelivr CDN in CommonJS, AMD and a global window.protobuf form, and the production instruction is to pin an exact version rather than follow the 8.X.X path.
Three entry points at the root, and no note on which to load
The repository exposes three runtime builds: index.js, light.js and minimal.js, each with a matching declaration file, index.d.ts, light.d.ts, minimal.d.ts. package.json points "main" at index.js and "types" at index.d.ts, and marks "type" as commonjs. The browser field sets fs to false, which is how the same source avoids pulling the Node filesystem module into a bundle.
The ext/ directory holds descriptor, textformat and protojson, each with a generated declaration file whose names are fixed by the build:types script, and the main declaration file is produced by running node cli/bin/pbts --main --global protobuf --out index.d.ts src/. Documentation is generated through jsdoc -c config/jsdoc.json -R README.md --verbose --pedantic. The repository also keeps tsconfig.json and tsconfig.test-types.json for types, eslint.config.cjs for sources, and a tslint configuration in config/ that lint:types still applies to every .d.ts file. Two linters over one codebase is an inherited inconsistency worth knowing before you wire the repo into your own checks.
A live Root against protoc-generated code
The meaningful alternative is not another JavaScript library, it is the protoc-based workflow this project already accommodates. protoc is the upstream compiler: install the toolchain, it reads .proto files, it emits language-specific code, and nothing needs a schema at runtime. protobuf.js inverts that arrangement. The Root is a live object graph, lookupType() is a function call, and a message can be built from a schema that arrived with the request.
That inversion buys a few things the generated path does not offer: one .proto file instead of generated output per language, no regeneration step after a schema edit, and the ability to load a schema in a browser from a bundle served off a CDN. It costs a runtime that has to be present and correct in every environment you deploy to, plus the memory overhead the README warns about. protoc-gen-pbjs exists for teams that want static output from the same toolchain. The repository also ships examples named custom-get-set.js, grpc-service.js, reader-writer.js, streaming-rpc.js and traverse-types.js.
Editorial conclusion
Adopt protobuf.js when .proto files come from another team and you need to parse them without a compiler on the machine, or when a browser build has to ship the schema rather than generated output. Do not adopt it if your payloads are large enough that a fully decoded message tree is a memory concern, or if you need 64-bit integers to survive a round trip without checking every conversion call. Before the first request arrives, run a round trip on your widest message with longs: String and with longs: Number and compare, because the README states that the Number option may lose precision.
Frequently asked questions
what is protobuf.js
protobuf.js is an implementation of Protocol Buffers for JavaScript and TypeScript that works with .proto schemas without requiring protoc, for Node.js and browsers. It supports runtime reflection, and specialized code generation with matching TypeScript declarations through the separate protobufjs-cli package.
What is Protobuf and what is it used for?
Protocol Buffers is the schema-driven binary format protobuf.js implements, and the project states that it is conformant through Edition 2026. On this implementation a message goes out with encode(message).finish() and comes back with decode(reader), or through the length-delimited variants of both.
Is Protobuf better than JSON?
In protobuf.js, JSON is a conversion target rather than the wire format. toObject lets a caller choose the output their application or transport expects, and message.toJSON() produces JSON-compatible output using the default conversion options, while the encoded bytes stay binary.
What are the downsides of using Protobuf?
The costs the documentation names are memory and precision. Decoded structures incur runtime memory overhead beyond their encoded representation, unknown wire fields are discarded by default, longs: Number converts 64-bit values to JavaScript numbers that may lose precision, and encode does not verify its input implicitly, so verify or fromObject are the explicit steps.
Is Protobuf still used?
protobufjs 8.8.1 and protobufjs-cli 2.7.1 were published on 2026-10-11, protobufjs 7.6.6 on 2026-08-27, and the last push to master was on 2026-11-01. The project is independently maintained with contributions from the upstream Protocol Buffers project.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/protobufjs-protobuf-js)Star history chart for your README
[](https://hysenlabs.com/projects/protobufjs-protobuf-js)Was this useful?