prowler's container pins its init image by digest and its own images by a floating tag
Prowler is the world’s most widely used open-source cloud security platform that automates security and compliance across any cloud environment.
At a glance
- What is it?
- Prowler scans cloud accounts against hundreds of checks and dozens of compliance frameworks, as a command line tool, a self-hosted web application, or a hosted service. It is Apache-2.0 licensed, releases frequently (5.45.0, 5.46.0 and 5.47.0 between 15 and 29 October 2026), and its default branch was pushed to on 2026-11-02. The container files are where this project is most instructive, because they show a security tool holding itself to a standard its own configuration does not fully meet.
- Who is it for?
- This is the tool to reach for when you need a defensible answer to whether a cloud account matches a named framework, because the check counts per provider are published, the frameworks are the ones auditors actually ask about, and the licence permits commercial use without a conversation. The self-hosted stack is a real deployment rather than a demo, with a database, a cache, a graph store and a message worker that you have to run and patch yourself.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
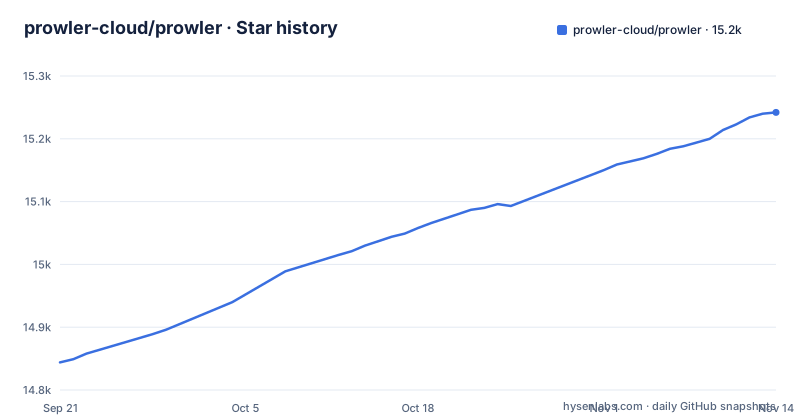
Star history
- prowler-cloud/prowler15,242 ★ · +398
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| prowler-cloud/prowler | 14.8k | 15.2k |
398 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One image is pinned by digest and the two that matter are pinned by a floating tag
The production compose file is careful in one place and loose in another, and the contrast tells you what the project prioritises.
The first service in the file is a one-shot initialisation container that fixes ownership on a mounted data directory. Its image is referenced by a full cryptographic digest, not a tag. There is no tag component at all, only the hash. That means the image cannot change underneath you even if someone republishes the tag upstream.
Then the two services that actually run the application. Both reference pre-built images by a version variable that defaults to the word stable. So the API image and the user interface image resolve to whatever the publisher most recently pushed under that label.
So the strictest pinning in the file is applied to a container that runs a single chown command and exits, and the loose pinning is applied to the two long-running services that hold your database connection and serve your interface.
That is not a criticism so much as a description of where effort went. The initialisation container is the one thing that must be idempotent and identical on every run, or the ownership fix is not reproducible. The application images are expected to move.
The consequence for you is that you cannot say what you were running six months ago from this file alone. If you need that, resolve the digests at deploy time and record them, or pin the version variables to specific releases rather than letting them default.
The build file lists the known vulnerabilities in its own base image
There is a comment block in the container build file that documents unfixed vulnerabilities in the base image, and it is the most striking thing in this repository.
The base image is pinned to an exact digest of a specific point release of a slim Debian derivative. The comment then enumerates high-severity issues that are fixed in a later publish of that same distribution but not yet present in the pinned digest, listed by package and by version.
The list covers the TLS library with a long run of identifiers, a database library, the compression tool, the Perl base package, the SSH library, a regular expression library and a compression library. Ten identifiers for the TLS library alone.
Then the reasoning. The comment says the approach taken was a targeted --only-upgrade of those packages.
So the project keeps the pinned base image and upgrades those specific packages on top of it, with the comment recording which vulnerabilities the upgrade is meant to close.
The consequence is that you can make an informed decision about this container's exposure, and you know exactly what to upgrade when the newer base lands. Almost no project gives you that list.
Third-party binaries are checksummed in the build file rather than alongside the download
The build file fetches three external tools, and the way it verifies them is worth copying.
The three are a vulnerability scanner for images, a workflow security analyser, and a PowerShell distribution. Each is fetched during the build, and each has its own architecture-specific checksum declared in the build file, for both the common processor architecture and the 64-bit ARM one.
Then the comment that explains why, and it is a good one: the checksums are pinned in the build file rather than fetched with the artefact, because a compromised release ships its own checksum.
The checksum comment explains the reasoning:
# Pinned here, not fetched with the artefact: a compromised release ships its own checksum.That is the whole supply-chain argument in one sentence. If you download a binary and verify it against a checksum that came from the same place as the binary, you have verified nothing. The checksum has to be somewhere the attacker does not control, and for a build file under your own review that is the right place.
Exact hashes for exact architectures, which means adding a third architecture means a new set of hashes rather than a wildcard.
There is one more small signal in the same file. An environment variable opts out of PowerShell telemetry, with a comment naming the destination host. A build that installs PowerShell to run checks turns off that PowerShell's analytics before it ever executes.
So the consequence is that you can build this container and know the three downloaded binaries are the ones a reviewer read. That is a stronger guarantee than most projects offer for the same three downloads.
The graph feature is AWS-only and still requires a graph database you were trying to avoid
One feature has an architectural constraint that the documentation states clearly and that is easy to skim past.
The graph feature automatically extends each completed AWS scan with a graph that combines a cloud inventory tool's output with the scan's findings. It runs in a worker after each scan.
Two long-term storage backends are supported. One is a self-hosted graph database, which is the default, and the compose files already ship a service for it. The other is a managed graph service from one cloud provider, which is opt-in.
Now the constraint. The inventory ingestion always uses a temporary self-hosted graph database regardless of which backend you configured. The documentation says the connection variables for that database must remain set even when you have selected the managed one.
So choosing the managed service does not remove the self-hosted one from your architecture. It is still there, still needs its connection details, still runs during ingestion. What the setting changes is where the long-lived graph ends up.
The second constraint is scope. Every AWS scan enqueues this job automatically. Other providers will be added in future iterations.
So the consequence is that if you are not scanning AWS, you gain nothing from either backend. If you are, and you already run a managed graph service in that cloud, you are still deploying and operating a second graph database for the ingestion step.
Two of the check rows in the provider table defer to other projects' documentation
The provider table is the most useful table in the front page, and it has three rows that are not really rows.
The first column is the provider. Then check counts, service counts, framework counts, category counts, a support column and an interface column. Every cloud provider has numbers in every column.
Then the infrastructure-as-code row. Its check count is a link to another project's documentation, and the service, framework and category columns all read as not applicable.
The large-language-model row does the same thing, pointing at a different project's documentation, and its interface column lists the command line alone. Everything else offers the interface, an API and the command line.
The container image row has no numbers at all: every count column reads N/A.
So three of the table's rows (at least sixteen) are not measured by this project. Two of them point at tools that do the scanning and are counted elsewhere, and one reads N/A throughout.
That is honest in the sense that nobody is claiming credit, and unhelpful in the sense that the row you want to size may not have a number in it.
The consequence is to read the check counts as covering cloud configuration only, and to go to the linked documentation for the two delegated categories rather than assuming coverage. And if you are evaluating the container image scanning specifically, there is no figure here to evaluate it against.
Every runtime dependency is pinned to an exact version, and there are dozens of them
The dependency list is the clearest signal of what this tool actually does, and of the cost of keeping up with cloud providers.
Every runtime dependency carries an exact version, not a range. There is one dependency block for the command line tool and library itself, and separate management packages for one cloud provider number in the dozens, one per service area: compute, container registry, container service, databases, databricks, key vault, monitoring, networking, recovery services, search, security, storage, subscriptions, API management and more.
Each of those is a separately versioned client library for one product area, pinned to one release.
So this tool's dependency maintenance is not a chore someone does quarterly. When a cloud provider ships a breaking change in one of twenty service clients, the pinned set needs updating, and a scan of that service area needs re-testing. And the exact pinning means there is no mechanism by which a compatible patch arrives without a release of this project.
There is a companion observation about the front page's claim of being the most widely used open-source platform of its kind. That claim is unverifiable from the repository, and the front page does not attempt to support it with a number. What the repository does support is the check counts per provider, and those are large and specific.
So the consequence is that you can trust the check counts because they are itemised, and you should discount the superlative because it is not.
Two linters run over the same repository with different rule sets
There is a comment in the build file explaining the linting arrangement, and it is the kind of internal note that usually gets deleted before publishing.
The claim is that one command is the single entry point and mirrors continuous integration exactly, including how tools are invoked and which flags are passed.
Then the split. One part of the codebase, the library and utilities, is checked by one linter, a formatter, and a third static analyser. The other two parts, the API and the server component, are checked by a different, much faster linter whose rules live in each project's own configuration file.
So a project with a Python library, a web API and a server component runs two different linting stacks with two different rule sets and two different configuration locations.
That is not unusual in a large Python monorepo and it is usually the result of a tool being replaced gradually. What is unusual is documenting it in the build file with the reasoning, and pointing out which command actually gates a change.
The testing story is similarly explicit. One target runs the test suite across the library with coverage and parallelism and produces a coverage report. A second target changes directory into the server component and runs its own suite, described as mirroring what continuous integration does. A third target measures coverage with skipping of already-covered files and then opens an HTML report on a desktop.
The consequence is that a contributor following the build file will match continuous integration, which is the point of writing it down. It also tells you the codebase has at least three separately versioned testing configurations.
Editorial conclusion
This is the tool to reach for when you need a defensible answer to whether a cloud account matches a named framework, because the check counts per provider are published, the frameworks are the ones auditors actually ask about, and the licence permits commercial use without a conversation. The self-hosted stack is a real deployment rather than a demo, with a database, a cache, a graph store and a message worker that you have to run and patch yourself. Two things to weigh before you commit. That the images are not digest-pinned at the application level, so what you run can change under you without a repository change. And that the graph feature is AWS-only and needs a graph database running even when you configure a managed one, which is real infrastructure for a feature you may not use.
Frequently asked questions
What is Prowler?
An open-source cloud security platform that automates security and compliance across cloud environments. It ships hundreds of built-in checks, remediation guidance and compliance frameworks, and runs as a command line tool, as a self-hosted local server with a web interface, or as a hosted service. The interface supports taking a provider as an argument, or launching the local dashboard. The project is Apache-2.0 licensed and released 5.45.0, 5.46.0 and 5.47.0 between 15 and 29 October 2026.
how to use prowler
From the command line, by passing a cloud provider as the argument, which runs the checks for that provider. For the self-hosted application, the production compose file brings up an API service on a configurable port, a user interface on another, and supporting services for the database, a cache, a graph database and a worker, each with health checks and startup ordering. The local dashboard is launched with its own command. Provider-specific configuration and credentials are documented separately.
Which compliance frameworks does Prowler support?
A long list covering industry standards including CIS, two NIST publications, a US agency catalogue and an adversary tactics framework; regulatory schemes including a banking regulator's guidance, a US government programme, a payment card standard and a European directive; data protection and privacy schemes; organisational governance and quality schemes; cloud vendor frameworks for two of them; and national schemes for Spain and Korea. The front page counts framework coverage per provider in a table, and a hosted hub is recommended as the authoritative place to check current coverage.
Is Prowler safe to run against my cloud account?
It is a scanning tool: it reads your account configuration and reports findings, and the graph feature builds a picture of your inventory. That means it needs credentials with broad read access across every service area it checks, which the dependency list shows is extensive. The container files show a security-conscious project, including a base image pinned by digest and external binaries verified against checksums held in the build file rather than fetched with the download.
Does Prowler support non-AWS clouds?
Yes, with published check counts per provider. The table lists coverage for AWS, Azure and GCP plus Kubernetes, GitHub, M365, OCI, Alibaba Cloud, Cloudflare, MongoDB Atlas, Google Workspace, OpenStack and Vercel. Two further rows delegate to other projects' documentation for infrastructure-as-code and for language model scanning, and one row for container images carries no counts.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/prowler-cloud-prowler)Star history chart for your README
[](https://hysenlabs.com/projects/prowler-cloud-prowler)Was this useful?