Pulumi: four SDKs in the build, and plugin downloads switched off
Pulumi - Infrastructure as Code in any programming language 🚀
At a glance
- What is it?
- Pulumi's pitch is that infrastructure is code in a language you already use, and the repository backs that up in a specific way rather than a general one. The build enumerates four SDKs including a configuration language, exports a flag that disables automatic plugin acquisition, and keeps every provider in a different repository.
- Who is it for?
- Pulumi suits a team that already writes in TypeScript, Python or Go and wants loops, functions and package management in its infrastructure definitions rather than a separate declarative language. It is a poor fit if you need the resource catalogue to live in one repository, since every provider is its own project.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
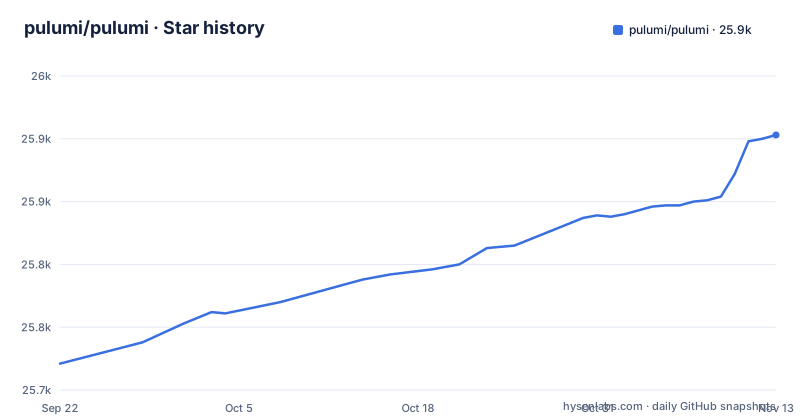
- pulumi/pulumi25,903 ★ · +182
| Repository | 2026-09-22 | 2026-11-13 |
|---|---|---|
| pulumi/pulumi | 25.7k | 25.9k |
182 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The build exports a flag that turns off plugin downloads
One line near the top of the Makefile is worth more attention than it looks:
PULUMI_DISABLE_AUTOMATIC_PLUGIN_ACQUISITION ?= trueThe variable is assigned and then exported, so it reaches every process the build starts. With it set, the tool does not go out and acquire language plugins while building. The build uses what is in the tree.
That is a deliberate choice and it explains several other things in the same file. The SDK list is a variable with an explicit default rather than a discovery step, and the sub-projects are derived from it mechanically, one directory per SDK under the sdk tree. Nothing has to be found at build time because everything is already there.
Both SDKS and PULUMI_DISABLE_AUTOMATIC_PLUGIN_ACQUISITION are assigned with ?=, so either default can be overridden from the environment or the make command line.
The setting is a default in the repository's own Makefile; nothing in the repository shown says it changes how an installed pulumi CLI acquires plugins at run time.
Four SDKs, and one of them is a configuration language
The SDK list is four entries long:
SDKS ?= nodejs python go pclThree are general-purpose languages a team would already be using, and the fourth, abbreviated pcl, is a configuration language rather than a programming language.
The language support has a structural cost that the Makefile makes visible. Each language needs a host binary, and the lint list names them explicitly, one for Go, two under Node (pulumi-language-nodejs and pulumi-language-bun), one for Python, plus the sdk/pcl directory. So a language is not just a client library; it is a process that the engine launches, and it is wired into the build, the lint set and the test set separately.
The repository is correspondingly large on the tooling side. There is a protobuf directory for the wire format, a codegen package whose Go, Node and Python parts are excluded from the default package list, a conformance test package that is filtered out of the fast test run, and separate integration and performance test packages, each excluded from the default test selection.
So the cost of a language is a directory, a host binary, generated code and a place in three separate build variables. Adding one is a real project, not a plugin install.
This repository is the engine and the CLI, and no provider lives here
The licensing paragraph in the README draws a boundary that is easy to miss. It says this repository is open source under the Apache 2.0 licence, and then specifies what it contains: the command line tool, the language SDKs, and the core engine. Individual libraries are in their own repositories.
That is the single most useful sentence for an evaluator, because it defines where your work happens. If you are writing infrastructure, you are using a provider package. If you are adding a resource type to a cloud that is not covered yet, you are in a different repository from this one.
The registry is described as the place to find a package with the resources you need, to install it directly into your project, browse its API documentation and start building. The scale is given as more than three hundred providers, alongside named support for the major public clouds, Azure, Google Cloud Platform, Kubernetes, and AWS.
The consequence is that the blast radius of a provider bug is contained, since a bad resource definition affects one package rather than the engine, and the engine is the thing you pin. It also means your infrastructure project's dependency list is a list of provider packages, each with its own version, which is the same shape of problem as any other package-managed toolchain.
pulumi up computes a diff, so what the program declares is what exists
The getting-started walkthrough is worth reading as a description of the mental model rather than as a tutorial. It installs the tool, creates a project from a template, deploys, reads an output, reads logs, and finally destroys everything.
The deploy step is where the design shows. Running the program makes all the cloud resources needed to run your code, and then the README says that if you make edits, subsequent runs compute the minimal diff to deploy your changes. So the unit of deployment is the difference between the desired state your program describes and the state the tool believes exists.
The commands around it follow from that. Reading an output is a stack operation, and the destroy step removes all resources created by your program, with a flag to skip the confirmation prompt.
The consequence is that the declared program is the whole truth. Anything your infrastructure depends on which the program does not declare is outside the diff, so a resource created by hand or by another tool is invisible to it and will not be cleaned up. And because the state that records what exists lives in a stack rather than in the code, that state is the thing to protect, back up and version alongside your program.
pulumi new is the on-ramp, and templates are the unit of reuse
The command that gets a new user from nothing to a deployable project is worth separating out, because it shapes how people start.
You create a directory and change into it, then run the new command with a template name:
mkdir pulumi-demo && cd pulumi-demo
pulumi new serverless-aws-typescript
That template argument is what the README uses, and the command is described as offering templates for all languages and clouds. Run it with no argument and it prompts with the available projects, which means the set of templates is discoverable without reading documentation.
The second command in the walkthrough is the one that does the work, and its output is the model's whole behaviour in miniature:
pulumi upAnd the two at the end define the lifecycle. Logs for containers and functions come from one command, and cleanup removes everything the program created:
pulumi destroy -yThe destroy flag skips a confirmation, which is exactly why it is worth understanding the lifecycle before using it on a stack you have not yet seen a diff for. Treat the interactive path as the one to learn first.
The documentation is prose-linted and the changelog is assembled by a tool
The supporting tooling in this repository is unusually complete, and three pieces of it change how you contribute.
Documentation is linted as prose. There is a configuration file for a prose linter and a directory of its rules, sitting alongside a Markdown linter configuration. That means documentation changes are checked for writing style in the same way code is checked for correctness, which is a real constraint on anyone submitting a docs change.
The changelog is generated. There is a configuration file for a changelog tool, a directory of changelog fragments, and a checked-in changelog file. The pattern is that a change adds a structured fragment and the release process assembles them, rather than someone writing release notes at tag time. It is a better process than editing a changelog by hand, and it does mean a contributor has to learn the fragment format.
Around those: a release tool configuration for building binaries, a dependency update configuration, a tool version manager file, a directory environment template, a custom golangci-lint configuration, a coverage configuration and a coverage directory, a development container definition, and a documentation build configuration.
The practical upshot is to read the contribution guide and the configured linters before opening a pull request.
The heading says Humans and Agents, and agent files are checked in
The README's main heading is Infrastructure as Code for Humans and Agents, which is a deliberate pairing rather than a slogan about automation.
Two things in the repository support the claim. There is an agent instruction file and a Claude instruction file at the top level, alongside a directory named for that assistant, so the project is set up to be worked on by automated agents as well as by people. And the README describes an Automation API for embedding infrastructure as code into other systems, which is the programmatic counterpart to the interactive command line.
The examples in the README make the same point from the other direction. The first is a TypeScript program that creates three web servers using a loop, which is a thing you can only write because the configuration language is a programming language. The second wires a scheduled job to a DynamoDB table using the AWS SDK's own client libraries inside the handler, which is a program rather than a template.
So the claim reduces to something checkable. The provider definitions are typed SDKs you import, the resources are objects you construct, and control flow is available because it is your language's control flow.
The resources described are the same ones a person would create.
Editorial conclusion
Pulumi suits a team that already writes in TypeScript, Python or Go and wants loops, functions and package management in its infrastructure definitions rather than a separate declarative language. It is a poor fit if you need the resource catalogue to live in one repository, since every provider is its own project. Before adopting, check three things: which SDK covers the language you intend to use, how you will version a stack's state so that destroy still works later, and how the engine resolves the providers your program declares.
Frequently asked questions
what is pulumi
Pulumi is an infrastructure-as-code tool for building and deploying infrastructure on any cloud, in any of several programming languages. The README positions it as the easiest way to build and deploy infrastructure using languages you already know, and says to skip the YAML and use standard features like loops, functions, classes and package management. It supports AWS, Azure, Google Cloud Platform, Kubernetes and more than 300 providers, and is open source under the Apache 2.0 licence.
what is pulumi used for
Pulumi is used to provision and manage infrastructure as code, and to embed that capability in other systems through the Automation API. The walkthrough in the README shows the cycle: create a project from a template, run `pulumi up` to create the resources your code needs, read outputs and logs, and run `pulumi destroy -y` to remove everything the program created. Each `pulumi up` computes the minimal diff to deploy changes.
how to install pulumi
The README gives a single command for the latest release, `curl -fsSL https://get.pulumi.com/ | sh`, and points at fuller installation instructions for other options. After installing you create a project directory and run `pulumi new`, which offers templates for all languages and clouds, prompting you with the available projects if you give it no argument.
Is Pulumi free or paid?
The engine and the tool are open source under the Apache 2.0 licence, and the README says so directly. The README also links to Pulumi ESC for secrets management, described as taming secrets sprawl and configuration complexity across cloud infrastructure and applications; it does not state pricing.
what is pulumi esc
Pulumi ESC is the project's secrets and configuration product, described in the README as taming secrets sprawl and configuration complexity securely across all your cloud infrastructure and applications. It appears as a separate link in the README's Welcome list, not as part of what this repository contains.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pulumi-pulumi)Star history chart for your README
[](https://hysenlabs.com/projects/pulumi-pulumi)Was this useful?