EconML estimates treatment effects from observational data, and its lower bounds are deliberately conservative
ALICE (Automated Learning and Intelligence for Causation and Economics) is a Microsoft Research project aimed at applying Artificial Intelligence concepts to economic decision making. One of its goals is to build a toolkit that combines state-of-the-art machine learning techniques with econometrics in order to bring automation to complex causal inference problems. To date, the ALICE Python SDK (econml) implements orthogonal machine learning algorithms such as the double machine learning work of Chernozhukov et al. This toolkit is designed to measure the causal effect of some treatment variable(s) t on an outcome variable y, controlling for a set of features x.
At a glance
- What is it?
- EconML is a PyWhy Python package for heterogeneous treatment effect estimation, built as part of the ALICE project at Microsoft Research and implementing orthogonal machine learning methods such as double machine learning. What is most instructive in the repository is not the API but the dependency pins and the C extension build, both of which explain how installation behaves.
- Who is it for?
- Use EconML when you need an effect that varies with features, you have observational data, and you can state your identification assumption, either no unobserved confounders or access to an instrument. Before installing into an existing environment, read the dependency floors in pyproject.toml, since they are intentionally set high and capped by what the oldest supported interpreter is tested against.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
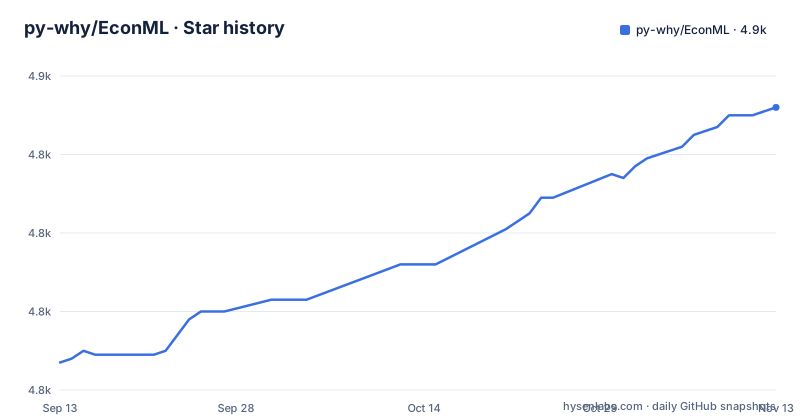
- py-why/EconML4,852 ★ · +65
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| py-why/EconML | 4.8k | 4.9k |
65 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The estimand is T on Y, with heterogeneity as a function of X
The problem the package is built around is stated precisely. The toolkit measures the causal effect of treatment variables `T` on an outcome variable `Y`, controlling for a set of features `X, W`, and how that effect varies as a function of `X`. That variation is the heterogeneous part. It was designed and built as part of the ALICE project at Microsoft Research, whose goal is to combine state of the art machine learning techniques with econometrics to bring automation to complex causal inference problems. The methods apply even with observational, non experimental or historical datasets, which is the practical difference from a randomized trial. Four promises frame the design: implement recent techniques at the econometrics and machine learning intersection, keep flexibility in modeling effect heterogeneity through random forests, boosting, lasso and neural nets while preserving causal interpretation and often offering valid confidence intervals, expose a unified API, and build on standard Python machine learning and data analysis packages.
Causal interpretation rests on a condition you have to supply
The identification assumptions are named, and they are not optional details. Some methods assume no unobserved confounders, meaning there is no unobserved variable outside `X, W` that simultaneously affects both `T` and `Y`. Others assume access to an instrument `Z`, an observed variable with an effect on the treatment `T` but no direct effect on the outcome `Y`. That second form is a different research design, not a flag to flip. Most methods do provide confidence intervals and inference results, which is where the cost of an unmet assumption shows up: an interval computed under the wrong assumption is still printed with a confidence level, so nothing in the output warns you that your design does not support it. Documentation for the package and its background reading sit at https://www.pywhy.org/EconML/ and on the Microsoft Research EconML page, with the ALICE project page as the origin story.
Dependency floors are set high on purpose, with a stated reason
The declared runtime dependencies in `pyproject.toml` are lower bounds with a cap and a comment explaining the policy:
dependencies = [
    "numpy >= 2.0.2",
    "numba >= 0.60.0",
    "scipy >= 1.13.1",
    "scikit-learn >= 1.6.0, < 1.10",
    "sparse >= 0.15.4",
    "joblib >= 1.4.2",
    "statsmodels >= 0.14.4",
    "pandas >= 2.2.3",
    "shap >= 0.46.0",
The comment says the lower bounds are deliberately conservative, roughly the newest release available at the end of 2024, capped so they never exceed the version actually exercised on the oldest supported interpreter, Python 3.9, in `lkg.txt`. The stated reason is to stop resolvers from silently back tracking into ancient releases when a new conflict appears: an unbounded `scipy > 1.4.0` once let a resolver pick scipy 1.6.1, which has no wheels for modern Pythons and fails to build. numba is given a lower bound even though the comment calls it only a transitive dependency, to avoid very old incompatible versions landing alongside numpy 2.4.x.
Python 3.9 through 3.14, and a version read from a source file
`requires-python = ">=3.9"`, and the classifiers name Python 3.9, 3.10, 3.11, 3.12, 3.13 and 3.14, plus MacOS, Windows and Linux. Package metadata is declared in `pyproject.toml` with `dynamic = ["version"]`, and the actual number is read at build time by `setup.py`, which opens `econml/_version.py` and matches a line of the form `__version__ = '...'` with a regular expression. So the version you see on the package index is generated from a Python source file, not typed into the manifest. The project metadata lists PyWhy contributors as authors, MIT as the license, README.md as the readme, `treatment-effect` as the single keyword, and the package description as several methods for calculating Conditional Average Treatment Effects.
C and Cython extensions are compiled only when they are stale
The build script collects `econml/**/*.pyx` and `econml/**/*.c` with a recursive glob, then drops any `.pyx` whose sibling `.c` already exists, on the assumption that the generated C is current and a recompile should not be forced. The remaining C files become numpy extensions, each built with `include_dirs=[np.get_include()]` and the macro `NPY_NO_DEPRECATED_API` set to `NPY_1_7_API_VERSION`. If any `.pyx` remains, Cython is imported, `Options.warning_errors` is set to true so Cython warnings become errors, and the sources are cythonized with `language_level="3"`. `setup` is then called with `ext_modules` combining both sets, `zip_safe=False`, and the version parsed from `_version.py`. Practical consequence: a source install needs a compiler toolchain, and if your checkout has stale generated C, your edits to a `.pyx` may be ignored.
What lives beside the package: notebooks, prototypes, and test split
The top level tells you how the project separates research from shipping code. `econml/` is the package itself. `doc/` is documentation, `notebooks/` holds Jupyter notebooks, and `images/` holds figures, which fits a repository whose primary language is recorded as Jupyter Notebook. `prototypes/` suggests experimental implementations, and `monte_carlo_tests/` is separate from the plain `test/` directory, so Monte Carlo checks are kept distinct from unit tests. `lkg.txt` and `lkg-notebook.txt` sit at the root, and `lkg.txt` is the file the dependency policy comment points at for what is exercised on the oldest interpreter. Supporting files include `setup.py`, `pyproject.toml`, `LICENSE`, `SECURITY.md`, a `.pre-commit-config.yaml`, and a `.github/` directory. Documentation generation and running the tests are both documented as separate sections, each linked from the table of contents.
Usage is grouped by task, not by estimator
The documented usage sections are organised by what you are trying to do rather than by algorithm: estimation methods, interpretability, causal model selection and cross validation, inference, and policy learning. That structure is the API promise in practice. Estimation covers the fitting step, inference is where confidence intervals come from, model selection and cross validation tell you how you are choosing among estimators, and policy learning is the step that turns an estimated effect into a decision. Interpretability sits beside them because heterogeneity models produce per sample effects that need reading. Documentation also covers generating the documentation and running the tests for developers, and points at a Help Wanted section for contributors and a citation section, so published work is expected to reference the package.
Editorial conclusion
Use EconML when you need an effect that varies with features, you have observational data, and you can state your identification assumption, either no unobserved confounders or access to an instrument. Before installing into an existing environment, read the dependency floors in pyproject.toml, since they are intentionally set high and capped by what the oldest supported interpreter is tested against. And decide which assumption each method needs before you trust a confidence interval.
Frequently asked questions
what is econml
EconML is a Python package for estimating heterogeneous treatment effects from observational data via machine learning, designed and built as part of the ALICE project at Microsoft Research. It measures the causal effect of treatment variables T on an outcome Y, controlling for features X, W, and how that effect varies with X.
how to install econml
The repository declares `requires-python = ">=3.9"` and MIT licensing in pyproject.toml, with the version read from `econml/_version.py` by setup.py. setup.py also compiles C and Cython extensions, so a source install needs a compiler toolchain.
econml vs doubleml
EconML implements orthogonal machine learning algorithms such as the double machine learning work of Chernozhukov et al.
econml vs dowhy
What is documented is that EconML applies to observational datasets under a stated condition: either no unobserved confounders, or access to an instrument Z that affects T but not Y.
What is heterogeneous treatment effect estimation and how is it performed?
It is estimating how the causal effect of an intervention on an outcome varies across samples with different feature values. In EconML this is the effect of T on Y while controlling for X, W, with effect heterogeneity modeled through random forests, boosting, lasso and neural nets while preserving causal interpretation.
How does double machine learning contribute to causal inference?
Double machine learning is listed among the orthogonal machine learning algorithms EconML implements, credited to Chernozhukov et al. The package frames this as implementing recent techniques from the econometrics and machine learning literature while offering valid confidence intervals in many cases.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/py-why-econml)Star history chart for your README
[](https://hysenlabs.com/projects/py-why-econml)Was this useful?