PyMC, the PyTensor pin below 3.4, and a README example that invents its own data instead of reading yours
Bayesian Modeling and Probabilistic Programming in Python
At a glance
- What is it?
- PyMC is a Python package for Bayesian statistical modeling built on PyTensor, and its feature surface is narrower than its reputation suggests: two algorithm families, one data-quality feature, and a compiler backend you inherit rather than choose freely. The worked example in the project page is a generative do-and-observe loop, which teaches the counterfactual workflow rather than data ingestion.
- Who is it for?
- PyMC suits a team that already thinks in distributions and wants posterior predictive checks, do-scenarios, and transparent missing-value handling rather than a black-box fit, and it is the right size for models with thousands of parameters where you do not want to hand-tune a fitting algorithm.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
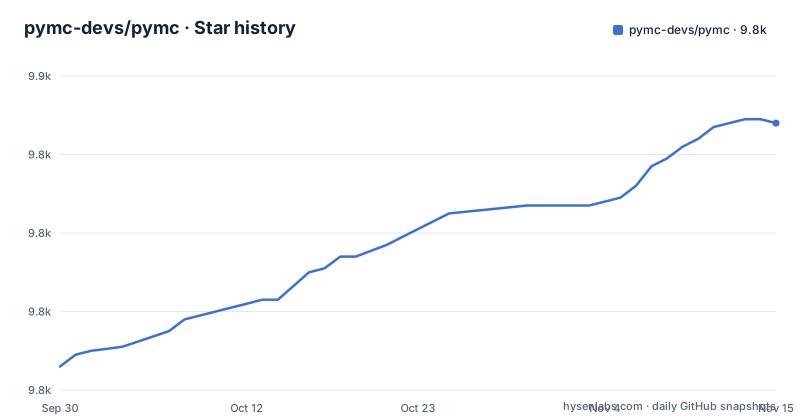
Star history
- pymc-devs/pymc9,848 ★ · +62
| Repository | 2026-09-30 | 2026-11-15 |
|---|---|---|
| pymc-devs/pymc | 9.8k | 9.8k |
62 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One line of syntax, two algorithm families, one data feature
The model specification syntax is the entry point, and the translation is explicit. A statement written as x ~ N(0,1) becomes a call equivalent to:
x = Normal('x',0,1)Underneath that, the feature list names exactly two algorithm families. On the sampling side, the No U-Turn Sampler is what allows complex models with thousands of parameters to be fitted with little specialized knowledge of fitting algorithms. On the approximation side, ADVI gives fast approximate posterior estimation, and mini-batch ADVI exists for large data sets. Everything else in the list is plumbing: computation from PyTensor, and transparent support for missing value imputation. That is a short list, and the omission is informative. Nothing in the feature list covers model selection, hierarchical shrinkage priors, time series, or survival analysis as first-class features, so if your method of choice depends on those being built in, you are writing them yourself. The clear implication for a reader is that the difference between MCMC and VI here is accuracy versus speed, with ADVI as the escape hatch when a full sample is too slow, and missing data as the one piece of data plumbing you get for free.
The example invents its observations instead of reading a file
The worked example is a plant growth regression, and the first thing it does is manufacture the covariates rather than load them:
   import pymc as pm

   # Taking draws from a normal distribution
   seed = 42
   x_dist = pm.Normal.dist(shape=(100, 3))
   x_data = pm.draw(x_dist, random_seed=seed)
The dist method gives a distribution outside any model, draw pulls samples from it, and pm.Data then registers those values as data with named dimensions. Only after that does the model get built inside a pm.Model context with coords covering trial and features, and the answer is extracted by conditioning on synthetic observations:
   # Infer parameters conditioned on observed data
   with pm.observe(generative_model, {"plant growth": synthetic_y}) as inference_model:
      idata = pm.sample(random_seed=seed)

      summary = pm.stats.summary(idata, var_names=["betas", "sigma"])
      print(summary)
This is a deliberate teaching choice, and it is also a real gap for a newcomer. Nothing in this path shows how to get a DataFrame into PyMC, so the first thing you write in your own project is the part the project page never demonstrated. The upside is that you learn the do and observe mechanics before you meet a messy CSV.
Out-of-sample prediction is a coords edit, and a shape without coords breaks indexing
Predicting on new inputs works by swapping the data variable and the coordinates together. A three-row prediction set means replacing the trial coordinate as well as the array:
   # Simulate new data conditioned on inferred parameters
   new_x_data = pm.draw(
      pm.Normal.dist(shape=(3, 3)),
      random_seed=seed,
   )
   new_coords = coords | {"trial": [0, 1, 2]}

   with inference_model:
      pm.set_data({"x": new_x_data}, coords=new_coords)
      pm.sample_posterior_predictive(
         idata,
         predictions=True,
         extend_inferencedata=True,
         random_seed=seed,
      )

   pm.stats.summary(idata.predictions, kind="stats")
The same mechanism produces the counterfactual case, which is the real reason to learn it, since overriding a parameter inside pm.do turns the posterior into a simulator for a what-if:
   with pm.do(
    inference_model,
    {inference_model["betas"]: inference_model["betas"] * [0, 1, 1]},
   ) as plant_growth_model:
Zeroing the sunlight coefficient and resampling answers a policy question without refitting anything.
PyTensor is capped below 3.4, and the compiler choice rides on that pin
PyMC does not compute anything itself; it delegates to PyTensor, and the dependency range is narrow. pyproject.toml asks for pytensor>=3.3.6,<3.4, which is a window rather than a floor. That matters because PyTensor is where the execution strategy is decided. The listed responsibilities are computation optimization and dynamic C or JAX compilation, NumPy broadcasting and advanced indexing, linear algebra operators, and simple extensibility. Two of those are the interesting ones. Dynamic compilation means your model graph is compiled at runtime rather than ahead of time, which is what makes a model built inside a Python block run at all, and it also means the first call pays a cost the second call does not. The C or JAX choice is a backend decision exposed through the same dependency, so pinning PyTensor below 3.4 pins your backend options along with it. The consequence is upgrade sequencing rather than day-to-day friction: you cannot take the newest PyTensor for its improvements without also checking that PyMC's declared range admits it, and a resolver that silently picks something newer is not what the project asked for.
arviz is capped below 2.0 and threadpoolctl below 4.0.0
The runtime dependency list is where environment divergence starts. pyproject.toml declares arviz>=1.1.0,<2.0, better-optimize>=0.5.1,<0.6, cachetools>=4.2.1,<7, cloudpickle, numpy>=1.25.0, pandas>=0.24.0, pytensor>=3.3.6,<3.4, rich>=13.7.1, scipy>=1.4.1, threadpoolctl>=3.1.0,<4.0.0, and typing-extensions>=3.7.4. Five of those carry upper bounds, and that is the part worth noticing: ArviZ is the posterior diagnostics and plotting layer you will reach for the moment you finish sampling, and its 2.0 line is explicitly outside the range. The consequence for you is that a colleague whose environment already has a newer ArviZ cannot simply merge, and a base image rebuilt six months from now resolves to a different patch release than yours did. Pinning your whole environment, not just PyMC, is the only way the summary tables stay comparable across machines.
The Makefile builds docs only, and it refuses to start without Sphinx
The repository Makefile is a Sphinx documentation Makefile and nothing else. It sets SPHINXBUILD to sphinx-build, SOURCEDIR to docs/source, and BUILDDIR to docs/build, then does a shell check on whether sphinx-build is findable and raises an error if it is not, with a message telling you to install Sphinx or put the executable on your PATH. The targets are html, rtd, clean, and view, where rtd exports READTHEDOCS=true and builds with -E for a fresh environment. The clean target is more aggressive than it sounds, because it removes the generated API directories under docs/source/api. Two consequences follow. There is no make target that runs the test suite, so contributors invoke pytest directly, and the configuration for that lives in pyproject.toml: testpaths set to tests, minversion 6.0, and xfail_strict enabled, which turns an unexpectedly passing expected-failure test into an error rather than a quiet win. And because the clean target deletes generated API documentation, you cannot hand-edit anything under those directories and expect it to survive. Everything about building and testing is configured in files you read, not in a script you run.
mypy checks as Python 3.12 while ruff targets 3.11 and classifiers claim 3.14
The package metadata in pyproject.toml requires Python >=3.12,<3.15 and carries classifiers for Python 3.12, 3.13 and 3.14, Development Status 5 - Production/Stable, Intended Audience Science/Research and Operating System OS Independent. If your patch relies on a newer interpreter feature, check it against that supported range.
setup.py says Apache 2.0 while the packaged license field says NOASSERTION
The licensing information is consistent inside the repository and inconsistent outside it. The setup.py file carries the Apache License 2.0 header, and pyproject.toml declares license = "Apache-2.0" with LICENSE as the license file. A LICENSE file sits at the repository root. But GitHub's repository metadata reports the licence as NOASSERTION rather than an SPDX identifier. For an Apache 2.0 project that is a metadata gap, not a legal conflict, and the fix lives in whichever field your scanner trusts. The repository does carry the documents a reviewer would want, with GOVERNANCE.md for how decisions get made, ARCHITECTURE.md for the system layout, and CITATION.cff for citation metadata, plus a Discourse forum linked from the project page as the place to ask questions.
Editorial conclusion
PyMC suits a team that already thinks in distributions and wants posterior predictive checks, do-scenarios, and transparent missing-value handling rather than a black-box fit, and it is the right size for models with thousands of parameters where you do not want to hand-tune a fitting algorithm. It is a poor fit if you need Bayesian optimization rather than Bayesian inference, or if you need a supported data-loading path you can copy, because the documented example synthesizes its own observations. Before adopting, check two things: that your ArviZ and PyTensor versions fall inside the declared ranges, and that you are on a Python the project claims to support, which is 3.12 through 3.14. Version 6.4.0 shipped on 2026-11-01 and the last push was 2026-11-02.
Frequently asked questions
What does PyMC stand for and what is it used for?
PyMC, formerly PyMC3, is a Python package for Bayesian statistical modeling that focuses on advanced Markov chain Monte Carlo and variational inference algorithms. Its model syntax turns a statement like x ~ N(0,1) into the equivalent of x = Normal('x',0,1), and it is distributed under the Apache License, Version 2.0.
What is Bayesian probabilistic modeling and how is PyMC used for it?
In PyMC you describe a model by its distributions, fit it with one of two algorithm families, the No U-Turn Sampler for full MCMC or ADVI for a fast approximate posterior, and then check the fit by generating data from it. The example project page samples a prior predictive distribution, fixes parameters to generate synthetic observations, and re-observes those observations to infer the parameters.
Is PyMC the Python package for Bayesian optimization?
No, and the distinction matters for search results. PyMC's stated focus is Bayesian statistical modeling with MCMC and variational inference, and neither Bayesian optimization nor surrogate-based search appears in its feature list. If you want that, this is the wrong package and mistaking one for the other costs you a dependency.
How can I use a Bayesian model in Python with PyMC?
Import the package as pymc as pm, build the graph inside a pm.Model context with coordinates, and call pm.sample to fit it, then pm.stats.summary to print the table of mean, sd, hdi bounds, mcse, ess_bulk, ess_tail, and r_hat. Out-of-sample prediction uses pm.set_data with a matching coords dictionary before pm.sample_posterior_predictive.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pymc-devs-pymc)Star history chart for your README
[](https://hysenlabs.com/projects/pymc-devs-pymc)Was this useful?