Warehouse is the Python Package Index, and its compose file publishes three entrypoints on localhost
The Python Package Index
At a glance
- What is it?
- The repository behind the Python Package Index ships a readme of roughly two hundred words that is almost entirely links, which is reasonable for software whose canonical deployment is a public website. The engineering detail lives in the configuration files: a router with separate entrypoints for the site, an image proxy and a file server, a development database running with trust authentication and writes unsynchronised, and a coverage configuration that documents why each exclusion is there.
- Who is it for?
- Warehouse is a repository to read rather than to run, because the canonical deployment is the public index and there is nothing to install locally that would resemble it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
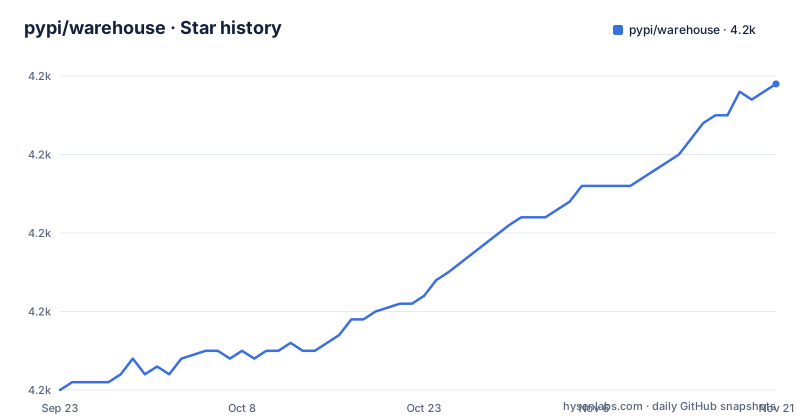
- pypi/warehouse4,199 ★ · +39
| Repository | 2026-09-23 | 2026-11-21 |
|---|---|---|
| pypi/warehouse | 4.2k | 4.2k |
39 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A two-hundred-word readme that is almost entirely links
The readme is written in reStructuredText, not Markdown, and its file name says so. It is about two hundred words. Its first line says that Warehouse is the software that powers the Python Package Index, and the rest is navigation: a development roadmap, documentation, an architectural overview, and a getting started page.
What it does say is worth reading carefully rather than quickly. You can run Warehouse locally in a development environment using Docker, with the setup instructions in the getting started documentation. The canonical deployment of Warehouse is in production at the public index itself.
That single sentence sets the frame for everything else in the repository. This is not a library you depend on, and it is not a product you install. It is the source of a website, and the documentation deliberately lives on its own site, which means the readme is a signpost rather than a manual. Anyone arriving expecting to read how the index works will find that the answer is three links away and nothing more.
Traefik fronts three entrypoints: the site, an image proxy and a file server
The compose file is where the shape of the deployment becomes visible, and the router is the first thing configured. A Traefik instance runs with its own API marked insecure, which the compose file explains enables a dashboard with no routing rules, and with the Docker provider enabled while exposed-by-default is turned off, so only containers that ask to be routed are.
Three entrypoints are declared. The web application listens on port 80. A second is labelled as a camo image proxy, which is the service that re-serves third-party images referenced from package documentation. A third is a file server. In development all three are published to the host, along with the dashboard on its own port.
That is the detail that matters for anyone building a local setup: the application is not the only thing listening. An image proxy that fetches URLs on behalf of rendered documentation and a plain file server are both part of the development environment, and both are reachable from the host in the default configuration. There is also an unanswered question left in a comment next to the access log lines, asking whether logging at the router would be too noisy and duplicate what the web application already logs.
The development database trusts every connection and turns off fsync, and says so
The database service is configured for speed, and the compose file is honest about it. Authentication is set to trust, with a comment reading never do this in production. The initialisation arguments disable synchronous writes, turn off full page writes, and skip the initial sync.
For a throwaway development database that is the correct trade, and the comment is the reason to trust it. The port mapping is the other thoughtful touch: the database publishes on host port 5433 rather than 5432, with a comment explaining that 5432 may already be taken by another PostgreSQL on the same machine, which is the single most common way a local setup fails for an unrelated reason.
The rest of the service is careful in the way infrastructure code usually is when someone has been on call. A readiness probe runs every second with a ten-second grace period, and the initialisation mounts three separate files: a directory of scripts that run when the database first starts, a compressed example SQL file, and a post-migration script, plus a helper script copied into the image that the setup waits on.
The volume list tells you what else the stack keeps: package files and an archive of them, logos for sponsors, caches, a Redis data volume, node modules, a volume for mail caught during testing, and one named for repository signing metadata.
requirements.txt exists only so a dependency bot updates seven split files
The top-level requirements file is six lines long, and the first of them is a comment saying it is only used for the dependency update bot. What follows is nothing but references to seven other files: the main requirements, deployment, three separate documentation sets for developers, users and the blog, linting, and tests.
That is a deliberate structure. Splitting requirements by purpose is what lets a documentation-only change bump a documentation tool without touching the production dependency set, and it is also what makes the dependency bot's job tractable, since each file has a coherent purpose. The cost is that a newcomer reading the repository root sees no dependencies at all and has to know to follow the references.
The same discipline shows up elsewhere at the root. There is a separate configuration file per concern, a Python version file, an editor configuration, a translation platform configuration for Weblate, a configuration for a structural search tool, a file that teaches Git to ignore specific commits when blaming, and a Procfile alongside a Makefile, which suggests the application has been run on more than one kind of hosting platform over its life.
Coverage omits migrations and three shims, with a comment for each
The Python project configuration opens with spelling-checker settings rather than build metadata, and the skip list is selective: translation catalogues, coverage output, development scripts, built documentation for three separate sites, HTML coverage, node modules, the JavaScript lockfile, and the two built static asset directories.
The coverage configuration is the interesting part because every exclusion has a sentence explaining it. Migrations are omitted because coverage information for them is not wanted. Three specific modules are omitted, and each comment says the same thing in slightly different words: the module is a tiny shim, it is hard to cover, it does not really do anything, and testing it would get in the way.
Branch coverage is enabled, the dynamic context is set per test function rather than per file, and parallel writing is turned on with a comment explaining that the test suite runs multiple processes at once and two of them must not write the same file. The report configuration adds exclusions for interface classes, type-checking branches, main blocks, and two patterns for deliberate test failures, one of which carries a comment saying to remove it once the upstream issue is resolved.
A spelling checker is configured too, with a word to ignore and a mechanism for ignoring regions marked by comment pairs, which is what you need in a codebase that discusses misspellings on purpose.
The Simple API templates are excluded from the template linter on purpose
The template linter configuration is four settings and one exclusion, and the exclusion has a comment attached that explains it better than most linter suppressions do: the Simple API templates have structures that are relied upon.
That is the whole story. The legacy simple repository endpoints are excluded from formatting rules because reformatting them would change output other systems depend on. There is also a note about which image tags could gain height and width attributes, and an open task to evaluate that and remove a particular rule.
This is worth noticing as a pattern. A linter that reformats templates in a package index can change what a package's documentation page looks like to every tool that consumes the simple API, so the exclusion is protecting an interface rather than hiding sloppy code. The indentation is fixed at two spaces, the profile is set for the template language in use, and the linter is told to respect the ignore file, so new work still gets checked.
The JavaScript side is configured with the same attention. Stylelinting covers stylesheets with a cache, linting covers the frontend source directories and the webpack configuration files specifically, and the test runner is set up with a DOM environment and a filename convention rather than a directory convention.
Two gunicorn configurations, one for the site and one for uploads
Two WSGI configuration files sit at the repository root, and the difference in their names is the whole story: one is for production, the other for uploads. A package index receives two very different kinds of request, and giving them separate server configurations is the kind of decision that only appears after someone profiled both.
Serving a package file is a long, slow transfer with almost no compute. Serving an API request or a page is the reverse. Sharing one worker configuration between them means tuning for whichever is noisier, and the wrong choice shows up as slow downloads or slow pages depending on the day.
The rest of the root explains the rest of the stack. There is a site customisation file, Babel configuration for translations in both the Python and JavaScript toolchains, a webpack configuration with a localisation plugin beside it, an ESLint configuration in the flat format, a documentation directory with its own build configuration, a development directory holding the database scripts the compose file mounts, and a sample compose override file that developers copy rather than edit in place.
None of this is in the readme. All of it is in the repository, which is the right way round for a project whose users are its contributors.
Editorial conclusion
Warehouse is a repository to read rather than to run, because the canonical deployment is the public index and there is nothing to install locally that would resemble it. What it is genuinely good for is showing how a public package index is put together: the routing layer that separates the web application from its image proxy and file server, the split of Python requirements into seven files purely so a dependency bot can update them, and a coverage configuration that explains in comments why migrations and three shim modules are left out. Two cautions for anyone tempted to treat it as a starting point. The development database is configured in a way the compose file itself marks as never for production, and all of the real documentation, from the roadmap to the architecture overview, lives on a separate site rather than in the repository.
Frequently asked questions
What is a warehouse?
In this repository it is the application that runs the Python Package Index. The readme is written in reStructuredText, runs to about two hundred words, and consists almost entirely of links to a development roadmap, documentation and an architectural overview on a separate site. It states that the canonical deployment runs in production at the public index and that local development runs in Docker.
How do I set up Warehouse locally?
With Docker, following the getting started documentation the readme points to. The compose file routes through a Traefik instance with three entrypoints: the web application on port 80, a camo image proxy on port 9000 and a file server on port 9001, plus a dashboard on port 8080. The development database publishes on host port 5433 so it does not collide with another PostgreSQL.
What database settings does the Warehouse development environment use?
A PostgreSQL 17 image with authentication set to trust, which the compose file annotates as never for production, and initialisation arguments that disable synchronous writes, turn off full page writes and skip the initial sync. Readiness is probed every second with a ten-second grace period, and the initialisation mounts a directory of first-run scripts, a compressed example SQL file and a post-migration script.
How does Warehouse run its tests?
The readme points at the running tests and linters section of the documentation. The repository's own configuration shows Python tests running with branch coverage enabled, a dynamic context per test function, parallel coverage data collection because several processes write at once, and deliberate exclusions for migrations and three shim modules, each with a comment explaining the reason. The frontend tests run under Jest with a DOM environment and Babel transforms.
Where can I ask questions about Warehouse?
The readme lists a GitHub issue tracker for reporting issues, an IRC network with one channel for general packaging discussion and user support and another for development of packaging tools, a Discord server for live discussion, and a Packaging category on a Discourse forum for new ideas. Everyone interacting in the project's codebases, issue trackers, chat rooms and mailing lists is expected to follow the Python Software Foundation's code of conduct.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- LiteLLM 1.107.0 Was Built From a Lookalike Fork: What PyPI Provenance Can and Cannot Tell Youdev.to · Oct 27, 2026 · 5 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pypi-warehouse)Star history chart for your README
[](https://hysenlabs.com/projects/pypi-warehouse)Was this useful?