PyPortfolioOpt turns a price CSV into weights, then into whole shares
Financial portfolio optimization in python, including classical efficient frontier, Black-Litterman, Hierarchical Risk Parity
At a glance
- What is it?
- PyPortfolioOpt is an MIT licensed Python library for classical mean-variance optimization, Black-Litterman allocation, shrinkage and Hierarchical Risk Parity. The solver work is settled; the friction sits in the dependency floors, the release history, and the gap between continuous weights and shares you can actually buy.
- Who is it for?
- PyPortfolioOpt fits a quant who already has price data and wants an efficient frontier, a Black-Litterman blend or an HRP allocation without writing a convex program by hand. It is not a data source, an order router or a backtest engine, and the documented path starts from a CSV you supply.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 131 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
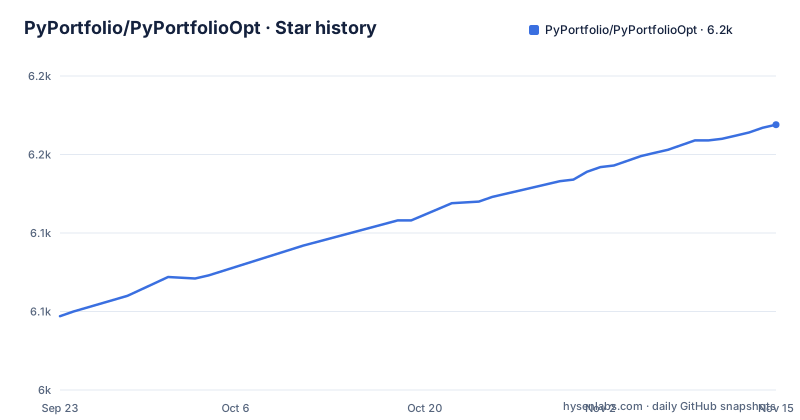
- PyPortfolio/PyPortfolioOpt6,169 ★ · +122
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| PyPortfolio/PyPortfolioOpt | 6k | 6.2k |
122 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
max_sharpe returns continuous weights and nothing else
Everything starts with two estimates and one optimizer call. `expected_returns.mean_historical_return(df)` and `risk_models.sample_cov(df)` turn a price table into mu and S, `EfficientFrontier(mu, S)` wraps them, and `ef.max_sharpe()` hands back raw weights. `clean_weights()` rounds them for reading, and `save_weights_to_file` writes them out.
mu = expected_returns.mean_historical_return(df)
S = risk_models.sample_cov(df)

ef = EfficientFrontier(mu, S)
raw_weights = ef.max_sharpe()
cleaned_weights = ef.clean_weights()
ef.save_weights_to_file("weights.csv")  # saves to file
The sample output makes the shape obvious: twenty tickers go in, most come back at 0.0000, while MA takes 0.3287, PFE 0.2039 and FB 0.2008. Raw weights and cleaned weights are the same solution at two precisions, so the file you save is a rounded copy of what the solver returned rather than the solution itself. `portfolio_performance(verbose=True)` then reports Expected annual return: 29.9%, Annual volatility: 21.8% and Sharpe Ratio: 1.38 for that fixture. Those are the project's own numbers on its own test data, printed by the example, not a result your own price history will hand you.
greedy_portfolio rounds to whole shares and returns leftover cash
Weights are fractions of a portfolio, not shares, and the project says so plainly: the max Sharpe result is interesting but not useful in itself. The step that makes it buyable takes the most recent prices and a target portfolio value.
from pypfopt.discrete_allocation import DiscreteAllocation, get_latest_prices

latest_prices = get_latest_prices(df)

da = DiscreteAllocation(cleaned_weights, latest_prices, total_portfolio_value=10000)
allocation, leftover = da.greedy_portfolio()
On the ten thousand dollar example the greedy pass buys MA: 19, PFE: 57, FB: 12, BABA: 4, AAPL: 4, GOOG: 1, SBUX: 2 and BBY: 2, then prints Funds remaining: $17.46. That is the contract, stated by the output: whole shares, leftover cash handed back rather than deployed. The method name is the algorithm. If your mandate needs exact index weights or fractional shares, this step is the one to look at first.
Historical estimates stand in for returns nobody can forecast
The estimation step is where the library makes its central assumption, and the project's overview of classical methods is blunt about it: mean-variance theory needs expected returns and future covariance, and stock returns are notoriously hard to forecast. Historical estimates are the substitute, and the theoretical guarantees are what you give up.
df = pd.read_csv("tests/resources/stock_prices.csv", parse_dates=True, index_col="date")Reporting is one call. portfolio_performance(verbose=True) returns the expected return, the volatility and the Sharpe ratio as three values, and the quick example rounds each to four decimals before printing.
exp_return, volatility, sharpe=ef.portfolio_performance(verbose=True)

round(exp_return, 4), round(volatility, 4), round(sharpe, 4)
Around that sit four functional groups: estimates of expected return, risk models for covariance, objective functions, and Black-Litterman allocation, plus sections on constraints, different objectives and other optimizers including Hierarchical Risk Parity. Per-model parameters live on the ReadTheDocs site and in the cookbook rather than in the overview. Nothing in this path improves your data: `mean_historical_return` uses the price history you hand it, so the closer that history sits to the period you care about, the more the output is worth.
Two dependency files disagree on the numpy and pandas floors
The repository ships two dependency lists and they do not agree. pyproject.toml, the one pip resolves when you install the package, sets numpy>=1.26.0,<3.0.0 and pandas>=1.0.0,<4.0.0.
dependencies = [
    "cvxpy>=1.1.19",
    "numpy>=1.26.0,<3.0.0",
    "pandas>=1.0.0,<4.0.0",
    "scikit-base<0.14.0",
    "scikit-learn>=0.24.1",
    "scipy>=1.3.0",
]
requirements.txt is looser, and much older, at the bottom of its range.
cvxpy>=1.1.19
numpy>=1.0.0
pandas>=0.19
scikit-base<0.14.0
scikit-learn>=0.24.1
scipy>=1.3.0
For a solver library that gap is not cosmetic. A floor of pandas 0.19 describes a DataFrame API from years before the one this code is written against, and a numpy floor of 1.0.0 allows installs nobody would test. The other four entries match exactly, cvxpy at 1.1.19, scipy at 1.3.0, scikit-learn at 0.24.1, and scikit-base held below 0.14.0, so the drift is confined to the two libraries the solver leans on hardest. Resolve from pyproject.toml and treat requirements.txt as an artifact rather than a second source of truth.
make install builds a Python 3.12 virtualenv with uv in ./bin
Contributor setup is a Makefile with four phony targets and a default goal of help. `install-uv` puts uv and uvx under ./bin when they are not already executable there, and `install` builds the environment afterwards.
make install-uv
make install
make test
make fmt./bin/uv venv --python 3.12Two things there are worth arguing with. The package declares requires-python >=3.10,<3.15 and its classifiers name 3.10 through 3.14, while the contributor virtualenv is pinned to a single interpreter, so the 3.10 floor is not what daily development runs on. And uv arrives as a piped installer into a directory inside the clone, while the file itself carries a TODO saying uv belongs on the user's global path instead. That TODO is unresolved in the file as it stands, so a fresh clone downloads a second package manager into ./bin before it builds anything.
pip install pyportfolioopt, and the extras you can skip
There are two documented install paths. PyPI first:
pip install pyportfoliooptOr from a clone, where pip still does the dependency resolution:
git clone https://github.com/PyPortfolio/PyPortfolioOpt.git
cd PyPortfolioOpt
pip install .
The package is version 1.6.0, MIT licensed, and classified as Development Status :: 4 - Beta. The project metadata names one person, Robert Andrew Martin, as both author and maintainer, which matters when a solver returns an unexpected answer. The core set is short on purpose, cvxpy, numpy, pandas, scikit-base, scikit-learn and scipy, next to a comment saying this set should be kept minimal. Everything else is soft. The all_extras group starts with matplotlib>=3.2.0 and more beside it, and a separate dev group exists for contributors. Reach for `pip install pyportfolioopt[all_extras]` when you want the plotting helpers, and leave it off when you want a smaller environment. The bare install pulls in neither group.
cookbook/ and tests/ hold the workflow the overview skips
The repository splits worked examples from library code. cookbook/ holds the example notebooks, docs/ and readthedocs.yml build the manual, example/examples.py is one runnable script, and tests/ carries the fixture CSV that the quick example reads. At the root you also get .pre-commit-config.yaml, .editorconfig and CONTRIBUTING.md.
Release history is uneven. The published list holds v1.4.1 from 2021-05-06 and v1.6.0 from 2026-02-26, five years apart, and pyproject.toml carries that 1.6.0. The last push to the default branch was on 2026-07-07, so the tree is moving even though the release tags are sparse.
The project's own disclaimer settles the scope: nothing here constitutes investment advice, and the author bears no responsibility for your subsequent investment decisions. The library computes allocations from inputs you provide. What you do with them, and whether a covariance estimate survives contact with a live market, is not something this repository can check for you.
Editorial conclusion
PyPortfolioOpt fits a quant who already has price data and wants an efficient frontier, a Black-Litterman blend or an HRP allocation without writing a convex program by hand. It is not a data source, an order router or a backtest engine, and the documented path starts from a CSV you supply. Before building on it, compare the numpy and pandas floors in requirements.txt with pyproject.toml, run the repo's own tests/resources/stock_prices.csv example to see whether the solver on your machine returns that 1.38 Sharpe ratio, and read the disclaimer before treating any output as advice.
Frequently asked questions
Can Python be used for portfolio optimization with PyPortfolioOpt?
Yes. PyPortfolioOpt is a Python library implementing classical mean-variance optimization, Black-Litterman allocation, shrinkage and Hierarchical Risk Parity, installable with `pip install pyportfolioopt` and declaring requires-python >=3.10,<3.15.
What is Hierarchical Risk Parity in PyPortfolioOpt?
Hierarchical Risk Parity is one of the allocation methods the library implements, named in the project description alongside classical mean-variance optimization, Black-Litterman allocation and shrinkage. It appears in the section on other optimizers, next to the objective functions and constraint sections.
What is mean-variance optimization in PyPortfolioOpt and how does it work?
It allocates across assets so that risk is minimised for a target return, following Markowitz's 1952 work, and the set of such portfolios is the efficient frontier. In the library you build expected returns and a covariance estimate, pass them to EfficientFrontier, and choose an objective such as max_sharpe(). The theory needs expected returns, which are hard to forecast, so the quick example substitutes historical estimates.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pyportfolio-pyportfolioopt)Star history chart for your README
[](https://hysenlabs.com/projects/pyportfolio-pyportfolioopt)Was this useful?