Adaptive spends evaluations where the function is interesting, and its install section names the wrong Python version
:chart_with_upwards_trend: Adaptive: parallel active learning of mathematical functions
At a glance
- What is it?
- A BSD licensed Python library for parallel active learning of mathematical functions, where a learner object decides which points are worth evaluating and a runner decides when to stop. The example is eleven lines long, the cost rule is a 50 millisecond floor per evaluation, and the install section contradicts the packaging metadata about which Python versions work.
- Who is it for?
- Use this library when your function is expensive to evaluate, you already have bounds, and you can describe what a good sample looks like. The learners and the parallel backends are the reason to pick it over a fixed grid.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
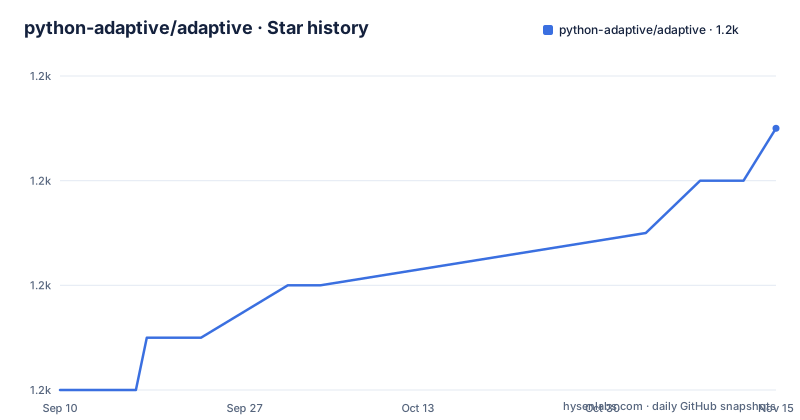
- python-adaptive/adaptive1,233 ★ · +5
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| python-adaptive/adaptive | 1.2k | 1.2k |
5 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A learner decides where to sample and a runner decides when to stop
The whole library is two objects and one idea: instead of evaluating a function on a dense grid, keep a running model of it and spend evaluations on the regions that seem worth looking at.
The learner holds that model. It samples at the locations it currently considers most interesting inside its parameter space, and each new evaluation changes which locations those are. What counts as interesting depends on your problem, and the defaults are only defaults: the sampling process is documented as fully customisable.
The runner sits on top and owns the stopping rule. In the shortest example in the project, a one dimensional learner over bounds of minus one to one is handed to a runner with a loss goal of 0.01, and the runner is told to publish a live plot and a live info widget. Everything the learner spends is spent trying to reach that goal, so the number you put there is the budget for the whole run.
Seven learners cover integrating, averaging and racing
The catalogue is organised by the shape of the function, not by dimension alone.
Three learners handle geometry. Learner1D takes a one dimensional function whose output is a vector, Learner2D the same in two dimensions, and LearnerND the general case with any number of inputs and outputs. Three handle statistics rather than shape. AverageLearner is for random variables and averages results over repeated evaluations, AverageLearner1D estimates the mean value at each point of a stochastic one dimensional function, and IntegratorLearner exists to integrate a one dimensional function.
Then two entries that behave differently. BalancingLearner appears twice in the documentation, once as an ordinary learner and once as a meta learner, because its job is to run several learners at once and pick the most optimal one as points accumulate. DataSaver is the other meta learner, and its purpose is narrow and practical: functions that return neither a scalar nor a vector.
The 50 millisecond floor decides whether this library is worth using
One sentence in the overview carries more sizing information than any feature list, and it is a constraint rather than a promise.
Adaptive is described as most efficient for computations where each function evaluation takes at least about 50 milliseconds, and the reason given is overhead: selecting potentially interesting points is itself work. Every candidate point you evaluate costs a decision on top of the evaluation.
That sets a clear boundary. If your function returns in microseconds, the bookkeeping wins and you have built a slower version of a grid. If a single call takes a second, a few hundred evaluations cost minutes of compute and buy you a model instead of a sparse set of points. The number is a rule of thumb stated by the project, not a measurement, and it is the first thing to check against your own function.
The loss function that drives the selection is replaceable, so the definition of a good point is yours to set rather than the library's to guess.
conda is the recommended path, PyPI needs the extra spelled out
Two installation channels are documented, and they do not give you the same thing out of the box.
The recommended way is conda:
conda install -c conda-forge adaptiveThe PyPI route needs the extras named explicitly:
pip install "adaptive[notebook]"The notebook extra exists so the Jupyter pieces arrive with the package, since notebook support is optional rather than bundled. Without it you get the learners and the runners and none of the plotting.
A second optional extra swaps one internal implementation for another. Installing adaptive-triangulation replaces the pure Python triangulation behind LearnerND with a Rust implementation, which the documentation describes as making that learner significantly faster. The dependency list pins the version floor at 0.3.1 of that package. So the choice is between a pure Python install that works anywhere, and a compiled backend you take on trust for the ND case.
The install section promises Python 3.7 and the metadata refuses anything below 3.11
The two places that state a supported Python version do not agree, and the packaging metadata is the stricter one.
The installation section says adaptive works with Python 3.7 and higher on Linux, Windows or Mac. The project file says requires-python of 3.11 or higher, and its classifiers stop at 3.11, 3.12, 3.13 and 3.14. Nothing in the classifiers covers 3.7 through 3.10.
The practical effect is that the sentence a newcomer reads first is stale. On Python 3.8, 3.9 or 3.10 the install instructions describe a combination the package metadata will refuse at install time, and the failure arrives late enough that you will have already chosen a channel. The same file carries the runtime dependencies, which include scipy, two sorted container packages, cloudpickle, loky from 2.9 and versioningit, so a clean environment on a current interpreter is a reasonable assumption and an old interpreter is not.
Operating system support is stated once, as Linux, Windows and Mac, with no separate caveat for any of them.
Five parallel backends are supported, and only two ship as extras
Parallel sampling is a first class part of the design rather than an add on, and the library advertises built in support for five execution backends: concurrent.futures, mpi4py, loky, ipyparallel and distributed.
What you actually get from an install varies. loky at 2.9 or newer is a hard runtime dependency, so a process pool is always available. ipyparallel at 6.2.5 or newer and distributed are declared in an extra group rather than the core list, which means a multi machine or notebook cluster path needs an explicit install. mpi4py is named in the supported list but appears nowhere in the dependency or extra lists, so the cluster route is entirely yours to provide.
The same extra group also carries the terminal automation pair, with pexpect on everything that is not Windows and wexpect on Windows, both pinned to the platform through environment markers rather than being installed twice. That pairing exists so interactive subprocess calls behave the same on either platform, which matters for a library whose whole purpose is running your expensive function many times.
Export is two methods, and the notebook stack is nine packages
Getting learned data out is two calls, and the conditional one is the only conditional in the API surface worth memorising.
A learner converts to a NumPy array with to_numpy(). If Pandas is present, the same learner also converts with to_dataframe(). There is no export path for the runner, no partial export for a subset of points, and no documented serialisation of the learner's internal state, which means a run you want to resume or compare later belongs in your own storage rather than in the library's.
The notebook side is heavier than the learning side. The notebook extra lists ipython, ipykernel, jupyter_client, holoviews, ipywidgets, bokeh, pandas, matplotlib and plotly. That is three plotting libraries plus the widget stack, for one live plot and one live info widget, and holoviews is the piece that sits between them. Installing the extra therefore commits you to a plotting stack whether or not you use the widgets, and the core dependency list has none of it.
Data export is listed as a headline capability, which is fair: two methods, both one line, both returning the ordinary scientific Python containers.
Three releases in one evening, then three months of commits with no new tag
The tag history is short and oddly shaped, which tells you something about the release cadence.
Three versions were published on a single evening in June: 1.5.0 in the afternoon, 1.5.1 about an hour later, and 1.5.2 shortly after that, all on the same calendar day. Then the last push to the main branch landed at the end of September, three months after the newest tag, with no fourth release following it. So the project is being changed faster than it is being versioned, and the version you install from a channel is a snapshot rather than the current state of the branch.
The repository layout supports that reading. Alongside the package sit a benchmarks directory, a docs tree, an example notebook, a continuous integration definition for Azure Pipelines, a nox file for driving test sessions, a pre-commit configuration, a Zenodo record with a DOI, a Read the Docs configuration, and both a project file and a setup.cfg. The version itself is declared dynamic and filled in by versioningit at build time, which is why the tags and the metadata can drift apart without anything failing loudly.
Editorial conclusion
Use this library when your function is expensive to evaluate, you already have bounds, and you can describe what a good sample looks like. The learners and the parallel backends are the reason to pick it over a fixed grid. Two things to check before you start. The install section claims Python 3.7 and higher while the packaging metadata requires 3.11 and classifies up to 3.14, so trust the metadata. And decide your stopping rule first, because loss_goal is where a run ends and everything the learner does is spent trying to reach it.
Frequently asked questions
What is the adaptive library for in Python?
It performs adaptive parallel function evaluations. Instead of computing a dense grid, a learner object picks the points in the parameter space that look most worth evaluating given the function and the bounds you supply, and the library is designed to run those evaluations on a cluster, plot the learning live, and let you tune the sampling algorithm itself.
When is adaptive faster than a grid search?
The documentation says adaptive is most efficient when each function evaluation takes at least about 50 milliseconds, because selecting interesting points carries its own overhead. Below that floor the decision cost outweighs the evaluation, so the library is aimed at expensive functions rather than cheap ones.
Which learners does adaptive ship with?
Learner1D, Learner2D and LearnerND for functions of one, two and any number of dimensions with vector outputs; AverageLearner and AverageLearner1D for random variables and stochastic functions; IntegratorLearner for integrating a one dimensional function; BalancingLearner to race several learners and keep the best; and DataSaver as a meta learner for functions that return neither a scalar nor a vector.
How do I export learned data from adaptive?
Call to_numpy() on the learner for an array. If Pandas is installed, to_dataframe() returns the same learned data as a DataFrame. Both are single calls on the learner object.
Which Python versions can install adaptive?
The installation section claims Python 3.7 and higher on Linux, Windows and Mac, but the project file requires 3.11 or higher and its classifiers cover 3.11 through 3.14. The metadata is the binding constraint, so treat 3.11 as the real floor.
How does adaptive run function evaluations in parallel?
It advertises built in support for concurrent.futures, mpi4py, loky, ipyparallel and distributed. loky 2.9 or newer is a required runtime dependency, ipyparallel and distributed sit in an optional extra group, and mpi4py is listed as supported without appearing in the dependency or extra lists, so that backend has to be installed by you.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/python-adaptive-adaptive)Star history chart for your README
[](https://hysenlabs.com/projects/python-adaptive-adaptive)Was this useful?