One concurrency number is both the admission limit and the batch width
Local-first speech-to-text: no cloud, no telemetry, fail-closed by design. One CLI, seven model families, signed model catalog, OpenAI-compatible local API.
At a glance
- What is it?
- openasr is a Rust speech-to-text stack whose interesting design is in its refusals: the CUDA container will not fall back to CPU, the server will not auto-download a model, and unauthenticated transcription calls return 401 until a device is paired. The single knob most likely to surprise an operator, --max-native-sessions-per-model, is simultaneously the admission limit and the source for the internal batch width.
- Who is it for?
- openasr fits an organisation that cannot send audio off its own hardware and needs something drop-in behind an existing OpenAI client, since the local endpoint takes the same calls and the pairing model is stricter than most local servers ship. It does not fit a team that wants automatic model download on first request, because the server refuses to fetch a pack for you, and it does not fit a cluster without NVIDIA hardware where you expected the CUDA image to degrade.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 16 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
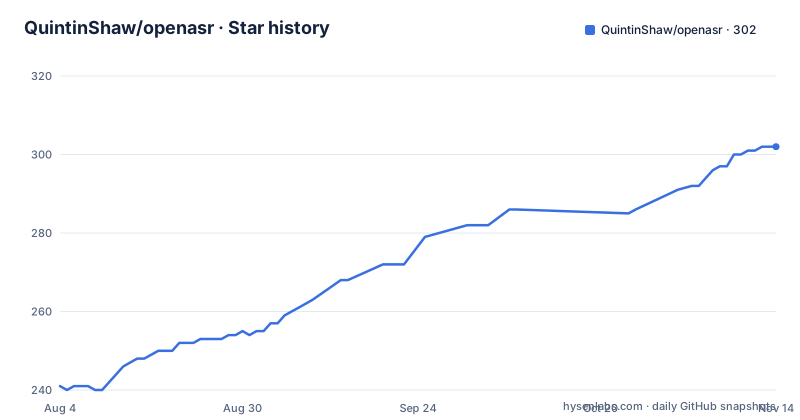
- QuintinShaw/openasr302 ★ · +61
| Repository | 2026-08-04 | 2026-11-14 |
|---|---|---|
| QuintinShaw/openasr | 241 | 302 |
61 Stars in the last 102 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One number does two jobs, and four model paths ignore it
The concurrency setting is the detail to understand before you size anything. The documentation says offline native requests are serial by default, and that operators can set a limit which is both the admission limit and, for eligible direct-GPU jobs on four named model families, the source for an internal batch width capped at eight. So one integer controls how many requests the scheduler admits and how wide the batches are, and only for the direct-GPU paths on those models. The CPU path, the scheduler, the adapter path, the realtime path, and two named model paths all stay serial regardless, and translations follow the offline policy rather than the batched one. The practical consequence is that raising the number on a CPU host does almost nothing, because you are widening a batch that never forms. Read the eligibility list before you tune it, not the flag name.
The admin token is printed once and never reprinted, so the volume matters
First-start token behaviour is the kind of thing that pages someone at 2am if it is not documented carefully, and here it is. If the admin token environment variable is unset, the server generates a random one, writes it owner-only to a file under the data directory, and prints it to stdout exactly once, on the first generate. Later starts read the file and do not reprint the secret. So the recovery path when you have lost the token is to supply your own through the environment rather than to look in the logs. The documentation also tells you to reuse a volume at the data path, and the reason is that both the generated token and the pairing registry live there. Lose the volume and you lose the pairing state, which means every client that was approved has to be approved again. The container example makes this visible by naming the mounted volume explicitly rather than leaving it to the default anonymous behaviour.
The CUDA image refuses to start without a GPU, and names the error
The GPU path is built around a refusal, which is unusual and easy to get wrong in your own deployment. The container entrypoint runs a diagnostic command before serving, and if no GPU device is visible inside the container it exits rather than starting on the processor. The compose file says this in as many words: it will not silently fall back to CPU. The failure mode is therefore explicit rather than a mysterious slow transcription, and the documentation names the exact error text to look for when startup fails, along with the usual cause, which is that the device reservation block did not actually grant a GPU. It also names the two things to check on the host, the tool that lists devices and the runtime information the engine reports. The image tag table follows the same philosophy, describing the CUDA variants as fail-closed if no GPU is visible, and the CPU variants as covering both processor architectures. Anyone porting this pattern to their own inference server should copy the refusal, not the fallback.
The server will not fetch a model for you, and the image ships no weights
Two related decisions keep the container from reaching the network behind your back. The HTTP server never auto-downloads a model pack; you install one first, and the container example shows the whole sequence, including the pull command that carries a yes flag to skip the confirmation the CLI would otherwise ask for:
docker pull quintinshaw/openasr:latest
docker run --rm -d --name openasr \
  -p 8080:8080 -v openasr-data:/data quintinshaw/openasr:latest
docker logs openasr
# pairing admin token: <token> (saved at /data/pairing-admin-token)
docker exec openasr openasr pull whisper-small --yes
The published images contain the runtime binary and the model registry metadata and nothing more, with models pulled at runtime into the mounted data volume. The same restraint shows up in what is excluded: the images do not carry the benchmarking fixtures or the committed baselines, so the benchmark suite has to be run from a git checkout rather than from the container. The registry is what makes that workable without trusting the download. Every model download is verified against a signed catalog before it runs, and each pack carries its own upstream license recorded in both the registry and the pack metadata, so a model with terms you have not agreed to is visible as such before you pull it.
Health checks pass while transcription returns 401, by design
The server's default posture is to bind on all interfaces with a self-signed certificate and require device pairing, and the split between the liveness endpoint and the work endpoints is the part to know when you write monitoring. The health endpoint stays a liveness probe, so an orchestrator will consider the service up. Unauthenticated calls to the versioned endpoints return 401 until a client is paired, so the service can be healthy and completely unusable at the same time. That is the correct trade for a health check, and the wrong surprise if you wrote your readiness probe against a transcription call. Pairing is two requests: post a pairing request with a device name, then approve it with the admin token as a bearer credential. Once approved, transcription uses the issued device credential rather than the admin token, which means the admin token is not something you want in your application code. The desktop app takes the same path, adding the server as a remote and approving it in the interface.
One endpoint is deliberately not OpenAI-compatible, and the environment variable that waives TLS does not waive pairing
The compatibility claim has one deliberate exception, and it is the interesting one. Transcription is drop-in: point an existing OpenAI client at the local base URL and the calls work, including the multipart form with a model name. Forced alignment of a manuscript you already have is not, and the documentation says so rather than leaving you to discover it. That capability lives on a native path taking both the audio file and the transcript, and it is explicitly not an OpenAI endpoint, so no amount of client configuration will find it. The second detail is the escape hatch. Behind a TLS-terminating reverse proxy you can drop the self-signed flag and set an environment variable that permits a non-loopback bind without TLS. The documentation is careful about its scope: that variable waives TLS only, only on a trusted boundary, and device pairing stays mandatory regardless. It also says not to set it on an untrusted network. That is the correct shape for such a flag, since the thing it disables and the thing it leaves alone are named separately.
Seven crates, path-only dependencies, and one version field to bump
The workspace layout is tidy in a way that tells you what the boundaries are. Seven member crates cover the command line, the client, the core, a foreign function interface, the server, system audio capture, and a task runner. The manifest comments explain the dependency policy directly: inter-crate dependencies are path-only, there is no registry publish, and there is no version pin to maintain, so every member inherits its version from one workspace field and a release bump touches that single line, with a script and a release document backing it up. The external dependencies describe the actual work. A web framework with multipart and websocket features, a derive-based argument parser with environment support, audio input without default features, matrix multiplication and a real-valued transform library for the signal path, a Metal binding, a certificate generator for the self-signed case, an Ed25519 implementation for the signed catalog, memory mapping, and a work-stealing pool. A fuzzing directory, a performance directory, a deny configuration for dependency policy, and a pinned toolchain file sit alongside them, which is what a security-sensitive inference project looks like when it takes its own supply chain seriously.
Editorial conclusion
openasr fits an organisation that cannot send audio off its own hardware and needs something drop-in behind an existing OpenAI client, since the local endpoint takes the same calls and the pairing model is stricter than most local servers ship. It does not fit a team that wants automatic model download on first request, because the server refuses to fetch a pack for you, and it does not fit a cluster without NVIDIA hardware where you expected the CUDA image to degrade. Before you deploy the server, mount a volume at /data and keep it: the generated pairing token and the pairing registry both live there, and losing that volume means re-pairing every client.
Frequently asked questions
How do I install the openasr CLI?
Three documented routes: `brew install quintinshaw/tap/openasr` on macOS or Linux, the one-line installer `curl -fsSL https://dl.openasr.org/install.sh | sh`, or a prebuilt binary from the releases page. The first transcription run offers to download a model and asks you to confirm before it does.
What does --max-native-sessions-per-model control in openasr?
It is both the admission limit for offline native requests, which are serial by default, and, for eligible direct-GPU jobs on Cohere, Moonshine, Qwen and Whisper, the source for an internal batch width capped at eight. The CPU, scheduler, adapter, realtime and two named model paths stay serial regardless, and translations follow the offline policy.
Does the openasr server download a model automatically?
No. The HTTP server never auto-downloads a pack; you install one first, which in a container means running an explicit pull command. The published images carry the runtime binary and model registry metadata only, with models pulled at runtime into the volume mounted at the data path.
How do I pair a client with the openasr server?
Post a pairing request with a device name, then approve it with the admin token as a bearer credential. Transcription afterwards uses the issued device credential rather than the admin token. Unauthenticated calls to the versioned endpoints return 401 until a client is paired, while the health endpoint stays open as a liveness probe.
Is every openasr API endpoint OpenAI-compatible?
Transcription is. The local server exposes an OpenAI-compatible transcription path, and existing clients work by pointing their base URL at it. Forced alignment of a manuscript you supply is not: it lives on a native path taking both the audio file and the transcript, and is explicitly not an OpenAI endpoint.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/quintinshaw-openasr)Star history chart for your README
[](https://hysenlabs.com/projects/quintinshaw-openasr)Was this useful?