QuPath: a research-only bioimage tool whose newest tag sits seven months behind its branch
QuPath - Open-source bioimage analysis for research
At a glance
- What is it?
- QuPath is a Java application for whole slide and microscopy image analysis, built as a set of Gradle modules with extension slots for image readers and scripting. The repository records its own history unusually well, and that record is where the useful detail lives: dated funding ranges, a research-only notice, and an AI policy file the README never mentions.
- Who is it for?
- QuPath is a defensible choice for research work on slides and microscopy images, provided you accept the terms it states for itself. Two of those terms matter more than the feature list: the project describes itself as intended for research use only, and it asks to be cited in published work, which is a reasonable request rather than a license restriction.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
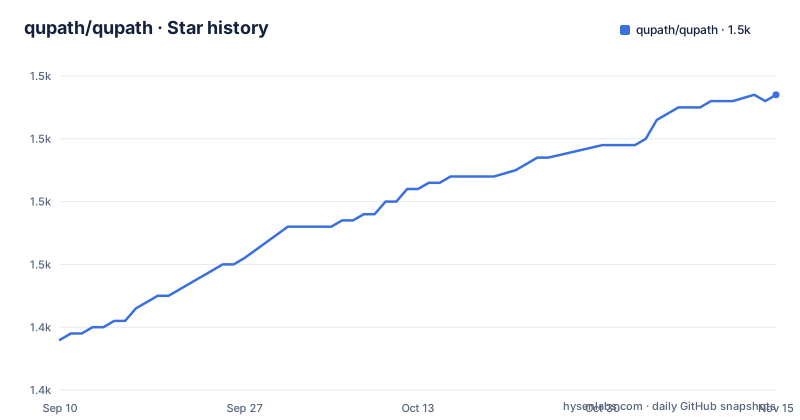
- qupath/qupath1,477 ★ · +39
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| qupath/qupath | 1.4k | 1.5k |
39 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The newest release predates the last push by about seven months
The download link in the README points at the latest releases page, so the version most people install is decided by the tag list rather than by the branch. That list reads: a release candidate at v0.7.0-rc1 dated 2026-02-17, the final v0.7.0 dated 2026-03-02, and before that v0.6.0 dated 2025-06-27. The most recent push is dated 2026-09-23 and the repository is not archived.
So roughly seven months of commits sit outside the tag a new user downloads, and the project is still on a zero major version, which by its own numbering means the authors do not treat the interface as settled. The gap between the candidate and the final release was two weeks, and the gap between the two finals was over eight months, so the cadence is irregular rather than fast or slow.
For a laboratory tool that has to be reproducible, that distinction matters more than it would for a library: a paper written against v0.7.0 and a colleague installing today are not necessarily running the same code.
An AI policy sits at the root and the README never mentions it
Among the top level entries is a file named `AI_POLICY.md`. Nothing in the README refers to it, no section explains it, and no configuration step involves it. A reader looking for what the project permits or expects around machine learning has to open the file directly.
The feature list itself says comparatively little. It names interactive machine learning for object and pixel classification, and new algorithms for common tasks, with cell segmentation and tissue microarray dearraying given as the two examples. That is the whole of what the README claims, and it is a claim about interactive classification rather than about training or inference pipelines.
The gap between a policy file at the root and one sentence in the feature list is the kind of thing worth resolving before adopting the tool under institutional review, since the policy is the document that would say who is responsible for a model's output.
Whole slide support lives in extension modules named after their readers
The repository is a multi module Gradle build, and the module names carry the format story. Two extensions are named after image sources, one for OpenSlide and one for Bio-Formats, and they sit beside the core module, a separate core processing module, an application module, and a GUI module named for JavaFX, which is consistent with the project's primary language of Java.
Three more extensions point at the parts of the workflow the README advertises: one named for the script editor, one for SVG, and one named for processing. So the claim about scripting for batch processing and data interrogation has a module of its own, and so does vector output.
The README also states easy integration with other tools, naming ImageJ. No module in the listing is named for that integration, which suggests it is handled inside the scripting layer rather than as a separate reader. Readers who work across tools should check the documentation for how that boundary is drawn rather than assuming a plugin directory exists.
The README gives no build command, only a link to one
Building from source is handled by a single line that points at a page in the documentation, and no Gradle invocation appears anywhere in the README. That is the whole of the build instruction, so anyone working offline or automating a build has to leave the repository to find out what to type.
What the root does show is the shape of the build. Two Kotlin DSL scripts sit at the top, a buildSrc directory holds shared build logic, a config directory holds configuration, and a VERSION file sits beside them. The Gradle wrapper is checked in twice, once as a Unix script and once as a Windows batch file, so a clone is buildable on either platform without installing Gradle.
A jpackage directory is also present, which is the packaging tool for desktop applications. Its presence, together with the dual wrapper, says the intended artifact is an installed desktop application rather than a library consumed by a build script, which is the expectation to carry into a deployment.
Research use only, a citation request, and two previous copyright holders
The licensing paragraph is unusually direct. The project states that it is an academic project intended for research use only, that the software is freely available under GPLv3 in the hope it is useful for that purpose, and that the aim is to make analysis methods open and transparent.
Above that sits a request rather than a term: if the software is useful in work that gets published, the README asks you to cite the publication, and a DOI link to a 2017 publication is among the badges at the top of the file. A citing page in the documentation is linked from that sentence.
The Background section then records where the code came from. QuPath was first designed, implemented and documented by its creator while at Queen's University Belfast, with additional code and testing by one other person named there. Versions up to v0.1.2 are stated to be copyright 2014 to 2016 Queen's University of Belfast. So the copyright has moved between institutions, and the README preserves both ends of that history rather than presenting a single current holder.
The funding list is a timeline with one line still open
Four funding entries are given, and three of them have closed ranges. A Wellcome Trust technology development grant runs from 2022 and is marked as present. A Chan Zuckerberg Initiative open source grant for cycle 4 runs 2022 to 2025, and the cycle 1 grant runs 2020 to 2022. A Wellcome Trust and University of Edinburgh institutional strategic support fund covers 2019 to 2020.
The earlier funding sits in the Background section instead, attached to the original code: an Invest Northern Ireland award with its reference number and a Cancer Research UK accelerator award with its reference number, both funding the work done between 2014 and 2016.
Read in order, the list is a project timeline rather than a sponsor wall, and it is the kind of record that tells you how long the work has been continuous and how it was sustained between grants. The two reference numbers on the oldest entries are also the only machine traceable link between the early Belfast code and its current home at the University of Edinburgh.
Three named maintainers, four named predecessors, and a forum tag
The maintenance section names the people rather than implying a team. It states that QuPath is being actively developed at the University of Edinburgh, lists its creator first, then two further developers, and then names four past team members individually. A contributors graph link follows for everyone else.
Support is routed through two places, both external to the repository: a forum tag on image.sc for help, and a help page in the documentation that collects further links. Neither is an issue tracker, so the repository itself is not where a usage question is expected to be answered.
The repository does carry the governance files you would expect to find, a code of conduct, a contributing guide, a changelog and a technical notes document, alongside a curious root entry named `unknown-license-details.txt` whose purpose the README does not explain. That filename is a reasonable thing to open before deploying, since it sits next to the license file and is the only root document without a stated meaning.
Editorial conclusion
QuPath is a defensible choice for research work on slides and microscopy images, provided you accept the terms it states for itself. Two of those terms matter more than the feature list: the project describes itself as intended for research use only, and it asks to be cited in published work, which is a reasonable request rather than a license restriction. Before committing, check which build you would actually get, since the download link points at the newest release while the branch has moved well past it, and read the build page rather than the README, which gives no build command at all. If you need a supported tool with a commercial license behind it, this is not that.
Frequently asked questions
What is QuPath used for?
Bioimage analysis. The feature list covers annotating and viewing whole slide and microscopy images, workflows for brightfield and fluorescence images, algorithms including cell segmentation and tissue microarray dearraying, interactive machine learning for object and pixel classification, and scripting for customization and batch processing, with integration including ImageJ.
Is QuPath software free?
Yes. It is described as freely available under GPLv3, in the hope it is useful for its stated purpose of making analysis methods open and transparent. The same statement also says the project is an academic one intended for research use only.
Is QuPath an AI system?
The README describes interactive machine learning for object and pixel classification, and new algorithms such as cell segmentation, but documents no model, training or inference setup. An AI policy file is present at the repository root without being referenced from the README.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qupath-qupath)Star history chart for your README
[](https://hysenlabs.com/projects/qupath-qupath)Was this useful?