quantstats counts winning periods, not winning trades
Portfolio analytics for quants, written in Python
At a glance
- What is it?
- A Python library for portfolio analytics with three modules for metrics, plots and HTML tear sheets, built around one assumption it states plainly: it analyses return series rather than trade records. That distinction changes what win rate, consecutive wins and profit factor mean, and the readme spells out how.
- Who is it for?
- quantstats fits systematic strategies with regular rebalancing, benchmark comparisons and anything where you want the same metric definitions across a set of return series. It does not fit a discretionary trade blotter, because the readme is explicit that a five-day trade spanning three up days and two down days counts as three wins and two losses.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 20 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
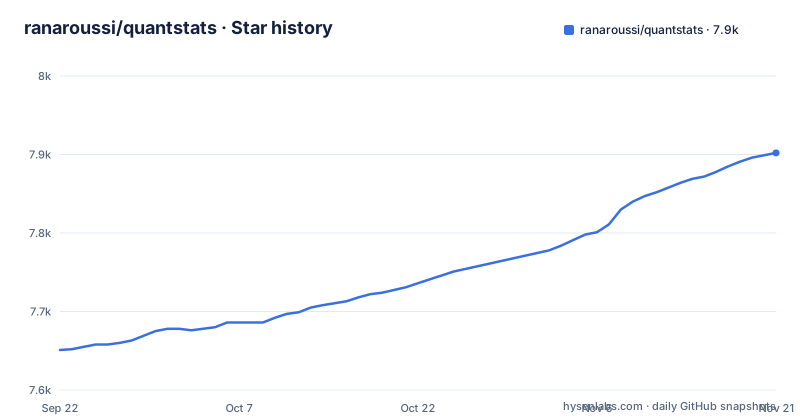
- ranaroussi/quantstats7,902 ★ · +251
| Repository | 2026-09-22 | 2026-11-21 |
|---|---|---|
| ranaroussi/quantstats | 7.7k | 7.9k |
251 Stars in the last 60 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Win rate counts periods, and the readme says so outright
The most important section in the readme is a caveat, and it is unusually well argued. QuantStats analyzes return series, meaning daily, weekly or monthly returns, and not discrete trade data. Every period-based metric follows from that:
- Win Rate is the percentage of periods with positive returns. - Consecutive Wins and Losses count consecutive positive or negative return periods. - Payoff Ratio is the average winning period return divided by the average losing period return. - Profit Factor is the sum of positive returns over the sum of negative returns.
Its author describes these as valid and useful for systematic or algorithmic strategies with regular rebalancing, for analysing return-series behaviour over time, and for comparing strategies period by period. For discretionary traders with multi-day trades they may differ from trade-level statistics, because a single five-day trade might span three positive days and two negative days, and QuantStats counts those as three wins and two losses at the daily level.
extend_pandas changes how the library feels to use
The quick start calls one line a feature, and it is the one people copy first:
%matplotlib inline
import quantstats as qs

# extend pandas functionality with metrics, etc.
qs.extend_pandas()
After that call, a pandas Series of returns has the metrics as methods. The readme shows the same quantity twice, once through the module and once through the object:
# fetch the daily returns for a stock
stock = qs.utils.download_returns('META')

# show sharpe ratio
qs.stats.sharpe(stock)

# or using extend_pandas() :)
stock.sharpe()
Both return the same number, 0.7604779884378278 in the example. So the extension is a convenience layer rather than a second implementation, which matters because it means you can keep a returns frame and ask questions of it directly instead of routing every metric through the library's namespace.
Five report entry points, advertised as seven tear sheets
The reporting chapter says you can create seven different report tear sheets and then lists five entry points, which is worth noting as a documentation detail rather than a missing feature. The five are metrics with a basic or full mode, plots with a basic or full mode, basic, full, and html.
The html one is the interesting case because a benchmark can be either a pandas Series or a ticker:
# benchmark can be a pandas Series or ticker
qs.reports.html(stock, "SPY")
So the library can fetch the benchmark itself, which is why yfinance is a hard dependency rather than an extra. The output is a self-contained HTML tear sheet, and the readme links a generated example of one.
Batch plotting is handled in the same module, which is what makes this usable for a batch evaluation rather than a single portfolio.
The readme and the manifest disagree about pandas
The requirements section lists pandas 1.5.0 or newer. The build manifest lists pandas 2.0.0 or newer. The rest of the floors agree across both documents: Python 3.10, numpy 1.24.0, scipy 1.11.0, matplotlib 3.7.0, seaborn 0.13.0, tabulate 0.9.0 and yfinance 0.2.40.
The manifest is the one your installer reads, so the effective floor is pandas 2.0. That is a meaningful difference for anyone on an older data stack, and it is a good example of why the manifest rather than the readme is the document to trust.
One dependency in the readme is genuinely optional: plotly 5.0.0 or newer, needed only for plots.to_plotly(). The manifest expresses it as an optional dependency group rather than a hard requirement, along with a dev group holding pytest, pytest-cov, pyright and ruff. A separate requirements.txt is kept for backwards compatibility with pip install -r, and it duplicates the core list with pandas already updated to 2.0.0.
Monte Carlo returns bust and goal probabilities
The probabilistic module returns an object rather than a tuple of numbers, which is what the call signature suggests:
mc = qs.stats.montecarlo(returns, sims=1000, bust=-0.20, goal=0.50)
print(f"Bust probability: {mc.bust_probability:.1%}")
print(f"Goal probability: {mc.goal_probability:.1%}")
mc.plot()
Two thresholds, expressed as returns: bust at minus twenty percent and goal at fifty percent in the example, and a simulation count of one thousand. The results come back as attributes formatted as percentages, and the object plots itself.
Monte Carlo appears three more times in the stats namespace, as montecarlo_cagr, montecarlo_drawdown and montecarlo_sharpe, so the same machinery is applied to compound annual growth rate, drawdown and the Sharpe ratio rather than only to terminal outcomes. The plots module has montecarlo and montecarlo_distribution alongside them.
Documentation is a promise, plus Python's help()
Full documentation is coming soon, according to the project, and in the meantime it points you at Python's own help function for each method's optional parameters. The example it gives is instructive because the signature is dense:
help(qs.stats.conditional_value_at_risk)which reports the signature as conditional_value_at_risk with sigma, confidence defaulting to 0.95, prepare_returns, and a method parameter defaulting to parametric, followed by a two-line explanation of what Conditional Value at Risk measures and why it is more comprehensive than Value at Risk alone.
The alternative source of reference is introspection. The readme shows how to list the whole public surface of either module with a directory comprehension filtered on names not starting with an underscore, and then prints both lists: a long list of names in stats and seventeen in plots, from avg_loss through outlier metrics in one and from daily_returns through yearly_returns in the other.
The monthly returns heatmap appears even when you only save
There is one known issue and it is stated with the specificity you would want from a bug report rather than a complaint. The author could not find a way to tell seaborn not to return the monthly returns heatmap when instructed to save, so even if you save the plot by passing savefig, it will still show the plot.
That is a real workflow consequence. In a headless environment, or in a report generation script that runs unattended, a plotting call that must open a display is a failure even though the file was written. The workaround is not documented, which means the practical answer is to run report generation somewhere a display exists, or to accept the side effect.
It is also a hint about the plotting layer: the figures go through seaborn, which is why that dependency is mandatory rather than optional, and why the plotly path exists as an alternative for plots.to_plotly().
v0.0.85 and v0.0.86 landed a day apart
The release history is three patch releases in two days: v0.0.84 on 26 September 2026, v0.0.85 on 26 September 2026, and v0.0.86 on 27 September 2026. The last push to main is dated 2 November 2026.
The version number is the thing to notice. The package is still on 0.0.x, which under the usual convention means no stability promise at all, and the readme describes itself as a new library and directs questions to the issue tracker.
That is consistent with the rest of the project's posture. The manifest classifies it as Development Status 5 - Production/Stable and licenses it Apache-2.0 with a single author, Ran Aroussi, while the documentation section of the readme is a placeholder. The repository carries a CHANGELOG.md, a CONTRIBUTORS.txt, a .deepsource.toml and a .flake8 alongside setup.cfg, so the tooling is conventional even though the version line is not.
Editorial conclusion
quantstats fits systematic strategies with regular rebalancing, benchmark comparisons and anything where you want the same metric definitions across a set of return series. It does not fit a discretionary trade blotter, because the readme is explicit that a five-day trade spanning three up days and two down days counts as three wins and two losses. Before adopting, resolve the pandas floor for yourself, since the readme and the manifest disagree, and read the known issue about the monthly returns heatmap appearing when you only wanted to save a figure.
Frequently asked questions
How do I install quantstats?
With pip: pip install quantstats --upgrade --no-cache-dir. Or with conda: conda install -c ranaroussi quantstats. You need Python 3.10 or newer, plus numpy 1.24.0, scipy 1.11.0, matplotlib 3.7.0, seaborn 0.13.0, tabulate 0.9.0 and yfinance 0.2.40. plotly is optional and only needed for plots.to_plotly().
What is QuantStats?
It is a Python library for portfolio profiling, intended for quants and portfolio managers, made of three modules: quantstats.stats for performance and risk metrics such as Sharpe ratio, win rate and volatility, quantstats.plots for visualizing performance, drawdowns, rolling statistics and monthly returns, and quantstats.reports for metric reports, batch plotting and HTML tear sheets.
Does quantstats work for discretionary traders?
Not as a trade blotter. The readme states it analyzes return series rather than discrete trade data, so win rate is the percentage of periods with positive returns, and a single five-day trade spanning three up days and two down days counts as three wins and two losses. The metrics are described as valid for systematic strategies with regular rebalancing.
What does quantstats depend on?
pandas 2.0.0 or newer, numpy 1.24.0, scipy 1.11.0, matplotlib 3.7.0, seaborn 0.13.0, tabulate 0.9.0, yfinance 0.2.40 and python-dateutil 2.8.0, with Python 3.10 or newer. The readme's requirements section lists pandas 1.5.0, which is lower than the manifest that installers actually read.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ranaroussi-quantstats)Star history chart for your README
[](https://hysenlabs.com/projects/ranaroussi-quantstats)Was this useful?