ripwire installs instructions for your coding agent as well as a binary, and its own README says the deepest bugs in its field report were not found with it
The ripgrep of AI context: a zero-dependency C++23 CLI + MCP server for coding agents. Find what you want without reading the repo, then check you built what you meant — blast radius, tests-to-run, quality deltas. Signatures at 74.7% fewer bytes than bodies; every guess labelled, every loss published. Paddle out with a map.
At a glance
- What is it?
- redhat-et/ripwire is a C++23 command line tool and model-context-protocol server that gives a coding agent a ranked call graph before it reads a repository and a set of checks after it edits one, where the page's headline evidence is a report authored by a model that describes itself as the orchestrator of twenty agents, where the institutional memory it credits is two dot-files committed in the repository, and where the tool documents a false-positive mode in which eighteen reported incompatibilities were all fine.
- Who is it for?
- This is worth trying if you run agents over an unfamiliar codebase, because the orientation half is a deterministic call graph rather than a guess, and the write half is the part most workflows skip entirely. The persistent notes and the acknowledgments ledger are the sleeper feature: they turn code review into something an agent inherits rather than something each session rediscovers.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
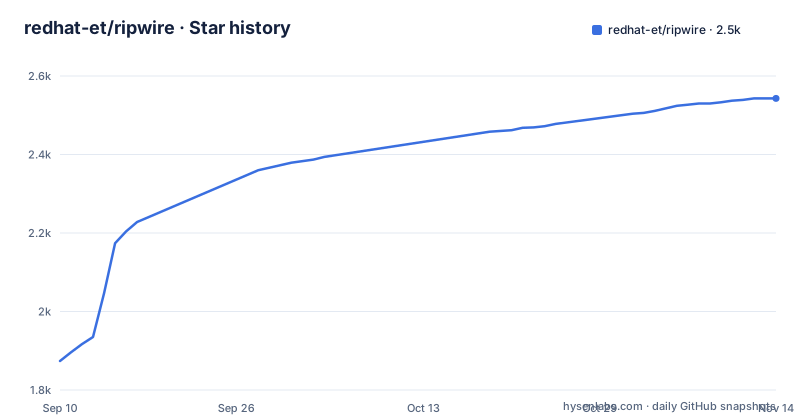
- redhat-et/ripwire2,543 ★ · +669
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| redhat-et/ripwire | 1.9k | 2.5k |
669 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The install writes instructions for the agent as well as the binary
The page has two audiences and gives the first one a one-line start.
The short path is a single install command, after which you are told to open each coding session by saying one sentence to your agent. The page's own phrasing is that the install also teaches the agent when to reach for each command, and that this is all most people need.
That sentence is the mechanism. This is not a tool you invoke and then re-invoke by remembering its name; the installer leaves behind instructions that make the agent decide to invoke it, and the human's only job is to say the project name once.
The repository tree shows how much surface that implies. There is a directory for one agent vendor's configuration and a plugin directory for another's, a model-context-protocol server configuration file, an agents instructions file, a vendor instructions file, and four separate directories named for hooks, prompts, queries and skills. That is seven distinct integration points, which is what it costs to be usable from more than one coding agent.
The long path exists for anyone who wants it and is a reference guide near the bottom of the page covering install, commands, output format, exit codes and limits. The page is explicit that you do not need it to get started, which is a reasonable thing to say about a tool whose main argument is that it is cheap to use.
The headline evidence is a report written by the model that ran the session
The most prominent thing on the page is a report, collapsed behind a summary line, and the summary line is about provenance.
It says the report was written by a model that describes itself as the frontier model orchestrating around twenty coding agents over two days on a codebase of roughly fifteen hundred C++ and shader source files. So the case study on this page was written by the thing that was running the session, reporting on its own agents.
That is worth holding in mind while reading the numbers, and the report itself does some of that work. Its biggest claim is that roughly half the total token spend of the research phase was saved, and the text immediately pre-empts the obvious objection by saying this is the operator's whole-phase estimate, that it includes everything the research agents did including ordinary file reads, and that this makes it conservative rather than selected.
Underneath that are per-call figures with their denominators attached. One recall call served the relevant sections of a 164KB planning document in about six thousand tokens, which the report puts at roughly twenty-five times. Agents that led with the tool ran between thirty and forty percent leaner on tool-call counts than agents doing raw reads.
The behavioural numbers are more interesting than the token ones. One call returned zero production callers and redirected a whole task away from a behaviour the team believed was already shipped. Another flagged five of six call sites as incompatible on a refactor, sites a text search had missed, which the report says would otherwise have diverged silently and surfaced months later as an unexplainable visual bug.
The README says the real bugs came from somewhere else
The section that follows the case study is the most valuable part of the page, and it is a list of the tool's limits.
Its first bullet says the engagement's deepest findings did not come from the tool. Four are named: a structural capacity ceiling, a mis-derived constant, a floating-point re-association drift of one unit in the last place, and a seed-keying bug. All four were found by measurement the agents built themselves, described as baseline worktree diffs over full data fills, multi-arm attribution sweeps and funnels.
The summary of that section is a sentence worth repeating to anyone evaluating this class of tool: it is a floor for honesty and orientation, not a substitute for measurement design.
The third bullet is narrower and more useful. For broad, conceptual queries phrased in common words, plain search and reading still occasionally won. The report calls this consistent with the tool's own guidance that it shines on specific technical questions.
So the tool is positioned for the lookup and the mechanical review, and explicitly not for the finding. A static analyser that told you it found the floating-point bug would be a different and much more expensive claim.
A false-positive mode is documented with a count and a mitigation
The second limit bullet names the specific way this tool gets things wrong.
The contract checker's arity heuristic over-counts when a function has defaulted trailing parameters. One task saw eighteen reported incompatibilities that were all, in the report's words, fine.
What makes this worth a section is that the project does three things about it. It states the mechanism, so you know when to expect it. It states the count, so you can recognise the pattern. And it points at its own trust-calibration notes, which say to verify by compiling in exactly this case, and the report adds that agents which followed that instruction lost nothing.
So the mitigation is not a threshold you tune. It is that you already have a compiler, and the tool tells you when its answer is worth checking. That is a smaller promise than the token-savings headline and a much more believable one.
The write-side checks are described in the same register at the top of the page: blast radius, which tests reach the edit, eleven quality kinds that report only what got worse, forgotten co-changes, fields read and written, and names that resolve more than one way. The last three are the ones a text search cannot do at all.
The institutional memory is two dot-files committed in the repository
The report's most transferable idea is not a check. It is that fifteen agents who shared no context converged on the same discipline, and that it survived across tasks.
Two mechanisms are credited. The first is an acknowledgments ledger: when the quality gate flags something, the agent either fixes it or justifies it in writing, and the written reasons persist. The report is explicit that the measurable effect was not any single catch but that the discipline was uniform across agents that never met.
The second is persistent notes. Agents left notes pinned to symbols mid-task, a caller-wiring law and an arming-rule invariant, and later agents' lookups surfaced those notes automatically. The report calls it cheap institutional memory between contexts that never met.
Both are visible in the repository tree, and that is the part that matters for judging whether this is reproducible or anecdotal. There is a dot-directory for the notes and a second dot-file for the acknowledgments, both committed at the top level. So the memory is not a side effect of one machine or one session; it is a pair of files in the tree that the next agent reads.
That is also the honest limitation of the idea. A note is only useful if the lookup that needs it actually reaches the symbol it is pinned to, which is the same dependency the rest of the tool has.
A dozen defects that no test would have caught
The quality findings in the report are listed with enough specificity to be useful, and they cluster in one category.
All of them were caught by the delta check at the moment each agent thought it was finished, across roughly fifteen implementing agents, and the report's phrase is that they were fixed rather than waived. The examples are a 480-token duplicated routine, a fourth private copy of a shared random-number utility, a hand-duplicated cost function, test-fixture duplication across sibling suites, and functions that had quietly taken on a second job.
The best of them is a pair of near-identical functions with a flipped sign, described as correct at one boundary and quietly wrong at the other. That is the exact failure mode a reviewer misses when reading two similar-looking functions, and it is the kind of thing that produces a wrong number in production with no test failure.
The report's framing of these is worth quoting in substance: none of them would have failed a test, and they are the sediment that rots a codebase under high-velocity multi-agent development.
That is the argument for a mechanical gate rather than a review prompt. The gate makes removing them routine instead of heroic, which is a claim about process rather than about detection, and it is the claim this tool has the best evidence for.
grep still wins, and the evidence is one engagement
Two limits of the page's own case study are worth naming together, because they are the same limit.
The first is that there is exactly one engagement, and the tool was used the way its authors intended throughout it. Every agent was instructed to lead with the tool for orientation and to close with its quality gates. There is no comparison arm, no session where the tool was not used and the outcome measured, and the report is candid rather than evasive about that.
The numbers are internally consistent and the report pre-empts the selection objection, which is a good sign about the authors. But one engagement with a twenty-agent fleet on a fifteen-hundred-file codebase, written up by its own orchestrator, is a case study and not a benchmark.
The second is the grep admission, which the report makes twice: once in the limits and once in its own guidance that the tool shines on specific technical questions rather than broad ones. A tool that is worse than plain search on conceptual questions and better on specific ones is a tool with a real use, and a README that says so is worth more than one that does not.
So the honest summary is that this is a lookup accelerator with a review gate attached, strongest when you already know what you are looking for.
Editorial conclusion
This is worth trying if you run agents over an unfamiliar codebase, because the orientation half is a deterministic call graph rather than a guess, and the write half is the part most workflows skip entirely. The persistent notes and the acknowledgments ledger are the sleeper feature: they turn code review into something an agent inherits rather than something each session rediscovers. Two things to weigh first. The evidence on the page comes from a single engagement written up by its own orchestrating model, with the numbers described as operator estimates rather than measured trials, so read them as one team's experience. And the README is unusually candid that the real bugs came from bespoke measurement and that a plain text search still wins on broad questions, which is the more useful signal here than the headline multiple.
Frequently asked questions
What does ripwire do for a coding agent?
It gives a ranked, deterministic call graph before the agent reads a repository, so it knows what to touch and what that breaks, and after an edit it reports blast radius, which tests reach the change, and eleven kinds of quality regression. It ships as a C++23 command line tool and a model-context-protocol server.
How do I install ripwire?
With one command. The install also writes instructions telling the coding agent when to reach for each command, so the human only has to say the project's name once at the start of a session. A reference guide near the bottom of the page covers the commands, output format, exit codes and limits.
When does ripwire give the wrong answer?
Its contract checker's arity heuristic over-counts on functions with defaulted trailing parameters; one task saw eighteen reported incompatibilities that were all fine. The project's own trust-calibration notes say to verify by compiling in that case.
Does ripwire replace code review?
No. Its own report says the deepest findings in the engagement it describes were not found with the tool, but by measurement the agents built themselves, and that the tool is a floor for honesty and orientation rather than a substitute for measurement design.
How does ripwire persist notes between coding sessions?
Notes are pinned to symbols and acknowledgments for waived quality findings are written into files committed at the top of the repository. Later agents' lookups surface the notes automatically, which is how the report describes cheap institutional memory between sessions that never met.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/redhat-et-ripwire)Star history chart for your README
[](https://hysenlabs.com/projects/redhat-et-ripwire)Was this useful?