connect's Linux install fetches a different project's CLI, and its build tag is announced as unstable
Fancy stream processing made operationally mundane
At a glance
- What is it?
- Redpanda Connect is a stream processor with a large connector catalog, a YAML pipeline format and a mapping language of its own, aimed at databases, brokers and cloud services. Its own mechanics are more interesting than the feature list: on Linux you install Redpanda's own command-line tool and then run a Connect subcommand from it, the build tag that unlocks extra connectors is named after the project's former name and is documented as liable to change, the build produces four binaries rather than the one the readme describes, and the default test target skips most integration tests because they spin up Docker containers.
- Who is it for?
- connect fits a team moving records between databases, brokers and object storage with change-data capture as the source, who want a topology declared in one file and a stateless process they can scale horizontally. It does not fit a pipeline that needs exactly-once semantics, because at-least-once is the default and the mechanism that buys durability is holding no durable state, which means every consumer has to be idempotent.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
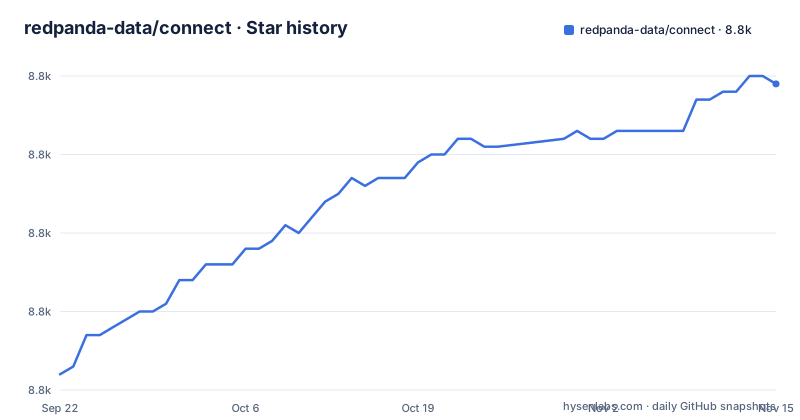
- redpanda-data/connect8,799 ★ · +37
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| redpanda-data/connect | 8.8k | 8.8k |
37 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
On Linux you install a different project's command and run a subcommand of it
The install section offers three routes. The macOS one is a single Homebrew command for the Redpanda tap, and the Docker one pulls the Connect image from the vendor's registry. The Linux one is two lines:
curl -LO https://github.com/redpanda-data/redpanda/releases/latest/download/rpk-linux-amd64.zip
unzip rpk-linux-amd64.zip -d ~/.local/bin/
The run command that follows is a subcommand of the tool that download installs:
rpk connect run ./config.yamlConsequence: a Linux user ends up with Redpanda's own command-line tool on their path in order to run Connect. The Homebrew tap has the same shape, since it is the Redpanda tap. It is a sensible packaging decision for a project that ships alongside a broker, and it means the Linux quickstart installs the CLI that wraps Connect rather than Connect alone; the build-from-source section also gives a go install command for the redpanda-connect binary.
The build tag that unlocks extra connectors is documented as liable to change
Components that link against external C libraries are excluded from the default build, and one tag turns them on. The tag is named after the project's former name rather than its current one, and it can be set two ways, through a tagged install or through a variable passed to the task runner. Then comes the sentence that matters:
> This tag may change or be split into more granular tags in future releases.
Consequence: the documented mechanism for including a connector that talks to an external native library is one the project has told you in advance not to rely on. Any automation that sets it may need updating if the tag changes or is split. And when a required system library is missing, the build fails with a linker error naming a library you did not know the connector needed, which is a confusing first experience for a plugin that looks optional.
The build produces four binaries and the readme describes one
The readme says the tool runs as a single static binary or container image. The build file lists four application targets: the main one, and three more carrying cloud, community and AI in their names. Consequence: the README's install and build sections do not mention this choice or explain the distinction between the four.
The plugin API is split between an open licence and an enterprise one
The badges at the top of the readme are two documentation links side by side, one labelled with the Apache version 2.0 licence and one labelled enterprise. Further down, the public Go API is linked as the surface for building custom plugins, and the path in that link still carries the project's former name in it. Consequence: there are two public API surfaces and the readme distinguishes them only by badge text, so whether a given capability is available to you depends on which one the documentation link points at.
At-least-once delivery is achieved by keeping no state on disk
The delivery section opens by calling the subject tricky and then explains the mechanism. Messages are processed and acknowledged with an in-process transaction model and no disk-persisted state, which means that when the sources and sinks are themselves at-least-once the guarantee holds even through crashes, disk corruption or other server faults. It adds that this is the default with no caveats, which is what keeps deployment and scaling straightforward. Consequence: duplicates are possible by construction, and the durability comes from having nothing durable to lose rather than from a write-ahead log. That is the right trade for a process you want to scale horizontally without coordination, and it means every consumer downstream has to tolerate being handed the same record twice. The readme does not say that, and it is the assumption most likely to be got wrong by an integrator.
The default test target skips every test that talks to a connector
The contributing section lists three requirements before a pull request, and all three are commands from the task runner. Then it says that most integration tests spin up containers and are therefore skipped by the test command, and gives the command to run them individually, which selects test names by a regular expression and a directory. Consequence: the gate your change has to pass skips most integration tests, so a change to a connector's configuration or its behaviour can pass it without being exercised against a real system unless you run the integration command yourself. It also means the unit tests that do run are the ones that can be written without a live system, which is a much narrower view of a connector than the feature list suggests.
The build runner points elsewhere and the deprecated file documents the version scheme
Nearly every instruction in the readme for building, formatting, linting and testing is a task-runner command; the exceptions are a go install command and the go test command for integration tests. The repository's Makefile opens by emitting a deprecation warning on every target that names the task runner as the replacement. It is still the file that shows how the version is derived, from a description of the tags with a literal fallback, how the build date is stamped, and which applications get built. It also contains a target whose entire job is updating the dependency on the project's former upstream. Consequence: the file you are told not to use still documents how a release is versioned, and it retains a live target for tracking an upstream that the module path no longer mentions.
The flagship example stops mid-line
The worked example on the readme pipes database changes into a table format on object storage, one table per source table, with a cloud catalogue, schema evolution switched on, and the table name interpolated from message metadata. It ends here:
table_location: s3://my-icebConsequence: the most interesting example on the page, the one that combines change-data capture with schema evolution and a catalogue, is truncated before it finishes, and the part that is missing is the part configuring where the tables physically live. It means the example you would most want to copy is the one you cannot copy, so you will end up reconstructing the last few lines from the reference documentation.
Editorial conclusion
connect fits a team moving records between databases, brokers and object storage with change-data capture as the source, who want a topology declared in one file and a stateless process they can scale horizontally. It does not fit a pipeline that needs exactly-once semantics, because at-least-once is the default and the mechanism that buys durability is holding no durable state, which means every consumer has to be idempotent. It also needs care if your build relies on the x_benthos_extra build tag, which the readme says may change or be split in future releases. Before deploying, run the integration tests yourself, since the default gate does not, and decide which of the four binaries the Makefile builds you actually need.
Frequently asked questions
What is Redpanda Connect?
A stream processor written in Go that moves data between a wide range of sources and sinks, with hydration, enrichment, transformation and filtering along the way. Its pipeline topology is declared in a single YAML file, it has a mapping language of its own, and it runs as a static binary or a container image with no state held on disk.
How do I run Redpanda Connect?
On Linux the documented route downloads a zip from the Redpanda project's releases and unpacks it into a local binary directory, then you run the Connect subcommand of that tool against your configuration file. On macOS there is a Homebrew command, and there is also a container image you can run with a configuration file mounted in, or with inline configuration overrides.
Does Redpanda Connect guarantee exactly-once delivery?
Not by default. It processes and acknowledges messages with an in-process transaction model and no disk-persisted state, and it describes the default as at-least-once with no caveats. The readme explains that the guarantee holds when the sources and sinks are themselves at-least-once, which means duplicate records are possible by construction and consumers have to tolerate them.
How do I write a custom plugin for Redpanda Connect?
In Go, against a public API that the readme links to for building custom plugins, with an example plugin repository provided as a reference. Note that the documentation badge for that API is labelled with the open-source licence while a second badge points at an enterprise API.
How do I run Redpanda Connect's integration tests?
Not with the default test command. The readme states that most integration tests start containers and are skipped by it, and gives a command that selects them by name and restricts the run to one connector's directory. That means the checks required before opening a pull request skip most integration tests.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/redpanda-data-connect)Star history chart for your README
[](https://hysenlabs.com/projects/redpanda-data-connect)Was this useful?