resilience4j: one instance per remote service, retry defaults of 3 attempts at 500ms, and a Java 21 line with no tag
Resilience4j is a fault tolerance library designed for Java8 and functional programming
At a glance
- What is it?
- The library adds circuit breaker, rate limiter, bulkhead, retry, timeout, and cache decorators to any functional interface, and it insists on a unique instance per remote backend. The details worth reading are the defaults you inherit, the scheduler you have to supply for timeouts, and the gap between the Java 21 text on master and the newest published tag.
- Who is it for?
- Use resilience4j when you want fault tolerance as a decorator around a Supplier rather than a separate service, and when you can follow its rule of one instance per remote backend.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 15 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
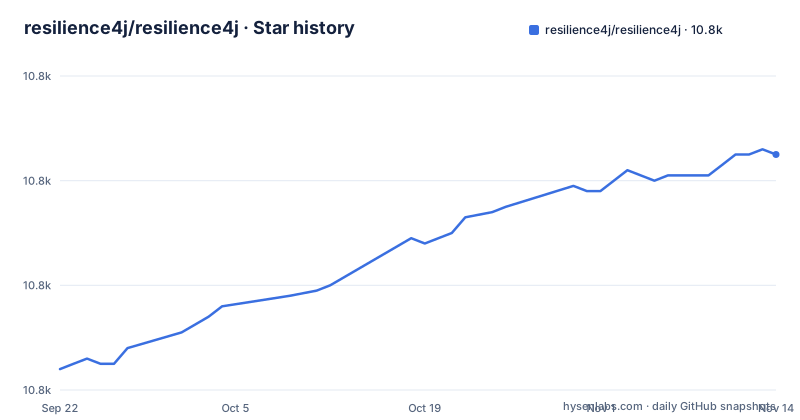
- resilience4j/resilience4j10,805 ★ · +41
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| resilience4j/resilience4j | 10.8k | 10.8k |
41 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One instance per remote backend, or your metrics and thresholds merge
The rule the documentation puts first is instance management: create a unique instance with a unique ID for each protected remote service or backend you communicate with. The stated reasons are that each instance tracks its own metrics so you can watch one service's health, that a failure in Service A does not affect the patterns protecting Service B, and that different backends can carry different thresholds, concurrency limits, rate limits, or retry policies. The documentation also draws a distinction between instance-aware and non-instance-aware patterns, which is where newcomers get it wrong. Consequence of ignoring the rule: a shared breaker folds two backends' failure counts into one state, so a healthy service stops being called because a flaky one tripped the breaker. Register instances by name per call target, not one per class or per application.
Retry.ofDefaults means 3 attempts, a fixed 500ms gap, and no backoff
The defaults are written into the sample itself:
// Create a CircuitBreaker with default configuration
CircuitBreaker circuitBreaker = CircuitBreaker.ofDefaults("backendService");

// Create a Retry with default configuration
// 3 retry attempts and a fixed time interval between retries of 500ms
Retry retry = Retry.ofDefaults("backendService");
Three attempts on a fixed interval is the floor behavior, not a tuning suggestion, and the snippet sets no backoff, no jitter, and no maximum elapsed time. The same library tells you that decorators can be stacked, and the example stacks a bulkhead, a circuit breaker, and a retry on one supplier, so nothing stops you from placing a retry outside a breaker and sending more traffic to a service that is already failing. That is the mechanism by which a retry policy becomes an outage amplifier. Write down which layers retry before you ship, and treat the 500ms default as something to configure rather than inherit.
A TimeLimiter cannot schedule anything until you hand it a scheduler
Timeout handling is the one decorator that does not run itself. The example is explicit:
// The Scheduler is needed to schedule a timeout on a non-blocking CompletableFuture
ScheduledExecutorService scheduler = Executors.newScheduledThreadPool(3);
TimeLimiter timeLimiter = TimeLimiter.of(Duration.ofSeconds(1));
The comment gives the reason: the timeout has to be scheduled on a non-blocking CompletableFuture, so the scheduling thread is supplied by you, not by the library. That pool of three is a sample value. Practical consequence: a shared under-sized scheduler turns timeouts into queued work, and your timeout stops being a bound on latency. Size it deliberately, and remember you own its shutdown. The same ownership applies to the async path, which pairs a ThreadPoolBulkhead with the limiter.
Master says Java 21 for version 3, the newest tag is v2.4.0, and the image installs Java 11
The prose on the default branch states that Resilience4j 3 requires Java 21. The visible release history does not include a version 3: v2.2.0 on 2023-12-17, v2.3.0 on 2025-01-03, and v2.4.0 on 2026-03-14. The repository's Dockerfile points at a third answer:
FROM gitpod/workspace-full

RUN bash -c ". /home/gitpod/.sdkman/bin/sdkman-init.sh && sdk install java 11.0.23-tem"
So the development image installs Java 11.0.23 while the branch text targets Java 21 for a release that is not visible in the tags. Do not read the runtime requirement from the image, and do not read it from the branch prose either. Confirm which major your artifact coordinates resolve to and which JVM it demands, because a mismatch here surfaces as a class file version error at build time rather than as a helpful message. This is also the single most useful thing to check before you adopt the library on a long-lived service.
Three Spring generations sit in the same source tree as separate modules
The module directories make the integration surface obvious: resilience4j-spring6, resilience4j-spring-boot3, and resilience4j-spring-boot4 are distinct artifacts, so adding Spring support is a choice about which generation you are on rather than a single dependency. The core set is smaller and stable: resilience4j-circuitbreaker, resilience4j-ratelimiter, resilience4j-bulkhead, resilience4j-retry, resilience4j-timelimiter, and resilience4j-cache, with add-on modules for metrics, Feign, Kotlin, Ratpack, Vertx, and RxJava2 among others. Consequence for a team: your Spring Boot major decides the module. Pin the module to your Boot line and verify it resolves.
The Decorators builder is the one API that needs resilience4j-all
The project tells you to pick only the modules you need from Maven Central, and then the flagship example carries a note that you will need the resilience4j-all dependency for this:
Supplier<String> decoratedSupplier = Decorators.ofSupplier(supplier)
  .withCircuitBreaker(circuitBreaker)
  .withBulkhead(bulkhead)
  .withRetry(retry)
  .decorate();
There is a second route for the same goal:
// When you don't want to decorate your lambda expression,
// but just execute it and protect the call by a CircuitBreaker.
String result = circuitBreaker
  .executeSupplier(backendService::doSomething);
So the tidy module-by-module advice and the builder API pull in opposite directions. Teams whose constraint is a small dependency list have to write the per-pattern execute calls instead of the fluent chain, which is more code but the same behavior. Decide this at the start of the integration, because retrofitting away from resilience4j-all after ten services already use Decorators is a much larger change than choosing the per-pattern style on day one.
Recovery is a lambda, so an exception type you did not enumerate escapes to the caller
Recovery is where the contract lives, and the contract is written out by hand:
// Execute the decorated supplier and recover from any exception
String result = Try.ofSupplier(decoratedSupplier)
  .recover(throwable -> "Hello from Recovery").get();
The async version is narrower and more revealing, because it names the exception types it handles:
    .withFallback(asList(TimeoutException.class, CallNotPermittedException.class, BulkheadFullException.class),
      throwable -> "Hello from Recovery")
    .get().toCompletableFuture();
TimeoutException, CallNotPermittedException, and BulkheadFullException are the exception types the fallback in the example handles; the example does not say what happens to other exception types. Build the list from the decorators you actually registered on that call, keep it next to the code that registers them, and expect to update it the day someone adds a retry or a rate limiter.
Master has moved six months past the newest tag
The gaps between releases are wide: v2.2.0 shipped on 2023-12-17, v2.3.0 on 2025-01-03, v2.4.0 on 2026-03-14, and the last push to the default branch master is dated 2026-10-30. The repository is not archived, and RELEASENOTES.adoc sits at the root if you want the detail between tags. What this means for a consumer is straightforward. Anything you read on master, including the Java 21 sentence, is ahead of v2.4.0, which was published on 2026-03-14. Pin a tag for production and treat the branch as documentation in progress. The repository also ships a grafana_dashboard.json at the root.
Editorial conclusion
Use resilience4j when you want fault tolerance as a decorator around a Supplier rather than a separate service, and when you can follow its rule of one instance per remote backend. Check three things before you commit: which major version you are pinning, since master talks about Resilience4j 3 on Java 21 while the newest tag is v2.4.0; whether you can supply the scheduler a TimeLimiter needs; and which Spring integration matches your Boot generation, since spring6, spring-boot3, and spring-boot4 are separate modules.
Frequently asked questions
What is Resilience4j used for?
It is a fault tolerance library that decorates any functional interface, lambda expression, or method reference with a Circuit Breaker, Rate Limiter, Retry, or Bulkhead. Decorators can be stacked, so one call can carry a bulkhead, a circuit breaker, and a retry at once, and you select only the modules you need.
What is bulkhead in Resilience4j?
Bulkhead is one of the core modules, resilience4j-bulkhead, and it comes in two forms: a Bulkhead created from defaults, and a ThreadPoolBulkhead used on the asynchronous path. The bulkhead module limits how much concurrency one backend can absorb, and a full bulkhead raises BulkheadFullException, which is one of the types the fallback list in the example handles.
how to use resilience4j retry
Create it with a name for the backend you protect, as in Retry.ofDefaults("backendService"), which gives 3 retry attempts with a fixed 500ms interval between them. Stack it on a call through Decorators.ofSupplier(supplier).withRetry(retry).decorate(), and remember the Golden Rule: one instance with a unique ID per remote service.
What is the difference between Resilience4j and Hystrix?
Resilience4j's own documentation describes a decorator based design for Java and functional programming, a Java 21 requirement for version 3, a Golden Rule of one instance per remote backend, and core modules for circuit breaking, rate limiting, bulkheading, retry, timeouts, and result caching.
how to use resilience4j in spring boot
Pick the module that matches your Boot generation, since resilience4j-spring6, resilience4j-spring-boot3, and resilience4j-spring-boot4 are separate artifacts. Setup and usage live in the User Guide at resilience4j.readme.io/docs, and metrics and Micrometer integration exist as their own modules rather than being bundled.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/resilience4j-resilience4j)Star history chart for your README
[](https://hysenlabs.com/projects/resilience4j-resilience4j)Was this useful?