earlyoom: the OOM daemon that kills before the kernel's oom-killer would
earlyoom - Early OOM Daemon for Linux
At a glance
- What is it?
- earlyoom samples available memory and free swap up to ten times a second and kills the highest scoring process while the machine is still recoverable. Its documentation explains the trigger precisely.
- Who is it for?
- earlyoom earns its place on a single Linux host that swaps itself into a stall, because its poll loop, its two stage signals and its 2 MiB footprint fit on one screen of C. It is the wrong tool for per cgroup limits or a fleet of machines. Before leaving it unattended, read the shipped default file, check your kernel version before using --kernel-oom, and accept that one memory episode can take several processes.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
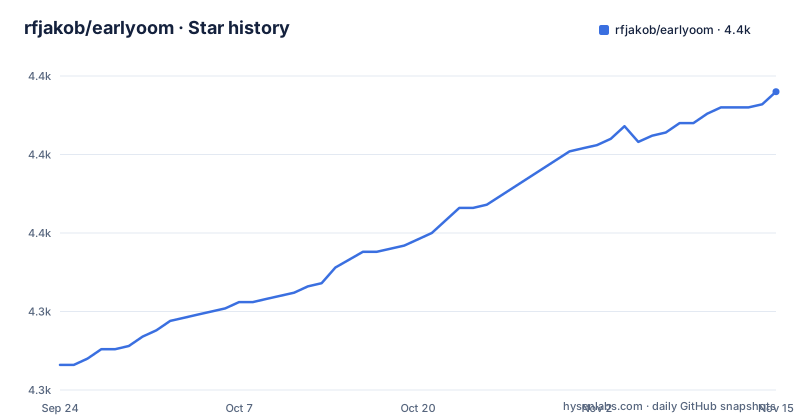
Star history
- rfjakob/earlyoom4,395 ★ · +87
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| rfjakob/earlyoom | 4.3k | 4.4k |
87 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Available memory and free swap, both under ten percent
earlyoom checks available memory and free swap up to 10 times a second, sampling less often while plenty of memory is free. Nothing is killed on memory alone: the trigger is both readings dropping below 10 percent of the total memory available to userspace processes, which the startup banner prints as a user mem total, 23890 MiB of physical memory shown as 21701 MiB once shared memory is subtracted.
The choice of available over free is the part that decides whether the daemon is quiet on a healthy box. Linux spends physical memory on page cache, so free memory sits near zero by design, and the available column sums everything that is unused or can be released immediately. In the sample reading below, free is 137 MiB while available is 2170 MiB, and swap has 231 MiB free of 1023.
                  total        used        free      shared  buff/cache   available
    Mem:           7842        4523         137         841        3182        2170
    Swap:          1023         792         231
Seeing that column needs Linux kernel 3.14 or newer plus a recent version of `free`. Pair a new kernel with an old `free` and the value comes from `grep MemAvailable /proc/meminfo` instead, which is the fallback the documentation names rather than a setting you can change.
One threshold in the prose, two in the sample output
The prose describes a single trigger, SIGTERM once memory and swap are both below 10 percent. The sample output two paragraphs later shows two thresholds, with SIGKILL at half the value, and nothing in between explains the second line. That mismatch is the single most useful thing in the documentation, because it tells you a process that traps SIGTERM survives the first threshold and dies at the second.
./earlyoom
eearlyoom v1.8
mem total: 23890 MiB, user mem total: 21701 MiB, swap total: 8191 MiB
sending SIGTERM when mem avail <= 10.00% and swap free <= 10.00%,
        SIGKILL when mem avail <=  5.00% and swap free <=  5.00%
mem avail: 20012 of 21701 MiB (92.22%), swap free: 5251 of 8191 MiB (64.11%)
Killing is not a single event either. Once the readings sit under the minimum, processes are killed until they are back above it, so a workload that respawns a leaking child can lose several processes during one memory crunch, and the status line repeats as it polls, which the README says happens less often when plenty of memory is free.
One more detail to copy into any log scraper: the banner prints `eearlyoom v1.8`, with the first letter doubled.
The victim is whatever the kernel already scores highest
earlyoom does no ranking of its own. It walks `/proc/*/oom_score` the way the kernel does and takes the highest score, which means `oom_score_adj` decides more than real memory use does. A small process carrying a raised adjustment value can be killed before a large one.
Each kill is logged with enough fields to audit that reasoning.
Feb 20 10:59:34 debian earlyoom[10231]: sending SIGTERM to process 7378 uid 1000 "tail": oom_score 156, oom_score_adj 0, VmRSS 4962 MiB, cmdline "tail /dev/zero"That line carries `oom_score` 156, `oom_score_adj` 0 and 4962 MiB resident for a `tail` process, and it also gives you the uid and the full `cmdline`, so an alerting rule can key on the command line instead of on a pid that changes on every run.
A Makefile target also produces a separate binary called `earlyoom.profile`, compiled with `PROFILE_FIND_LARGEST_PROCESS` defined, and the clean target deletes it again.
The --kernel-oom flag reaches a path that did nothing on v4.0.5
Passing `--kernel-oom` hands the decision back to the kernel by writing `echo f > /proc/sysrq-trigger` instead of choosing a victim from `oom_score`. The documentation attaches a serious warning to that flag: on some kernel versions, tested on v4.0.5, triggering the kernel killer manually does not work at all. It may free some graphics memory, which gets allocated again immediately, and kill no process whatsoever.
That gap was fixed in Linux v5.17, in commit f530243a. On an affected older kernel, enabling the flag can leave a machine in exactly the state it was meant to escape, with nothing terminated. On a newer kernel the flag trades earlyoom's logged, ordered kills for the kernel's own choice, which is the behaviour the project was written to step in front of.
Check the kernel version before enabling that flag rather than after the first memory emergency.
Two mebibytes resident, most of it shared libc
The footprint is given as numbers. Resident size is about `2 MiB` by `VmRSS`, of which only `220 kiB` is private under `RssAnon`, and the remainder is libc counted in `RssFile` and shared with every other process on the machine. Every page is locked with `mlockall()`, so the watchdog cannot be the thing the kernel evicts while memory is short.
The build is plain by choice. The Makefile compiles every C file in the directory with `-std=gnu99`, adds `-Wall -Wextra -Wformat-security`, `-Wconversion` and `-fstack-protector-all`, and bakes the version in from `git describe --tags --dirty`. A tree without that metadata falls back to the literal string `(unknown version)` and prints a make warning, which is what a distribution rebuild from a tarball sees.
The `Dockerfile` sets `CFLAGS` to `-static`, runs make in a gcc stage, then copies only the binary into an image built `FROM scratch` with `/earlyoom` as its entrypoint. No shell, no service unit and no config file ride along, so whether that image works at all comes down to what the container runtime exposes at `/proc`, the daemon's only input.
make install writes a unit and ignores a failed chcon
Two install targets cover both init systems.
sudo make install              # systemd
sudo make install-initscript   # non-systemd
The systemd target creates the unit directory, copies the generated unit with mode 644, tries a `chcon` to `systemd_unit_file_t` and enables the service. Both of those shell calls carry a leading dash, so a failure in either does not stop the install. That is deliberate: on systems with SELinux disabled, Ubuntu 19.04 and Debian 9 among them, the documentation says the warnings about failing to set the context can be ignored.
The non-systemd target writes an init.d script under `SYSCONFDIR` and registers runlevels with `update-rc.d`, starting at 18 in runlevels 2 3 4 5 and stopping at 20 in runlevels 0 1 6. Paths stay overridable at make time, with `PREFIX` defaulting to `/usr/local`, `SYSCONFDIR` to `/etc` and `SYSTEMDUNITDIR` to `/etc/systemd/system`, and a comment in the Makefile notes that systemd hardcodes its own unit path list.
`make test` runs the self tests first, and that is the step to keep before installing on a machine where you also work, given that the daemon's purpose is killing processes. One dependency is soft: the manpage is generated from `MANPAGE.md` with pandoc, and where pandoc is absent the build prints that generation is skipped and carries on without it.
The build ships earlyoom.default without naming one key
The repository root carries `earlyoom.default` next to `earlyoom.service.in` and `earlyoom.initscript.in`, and the Makefile rewrites the template files with sed before installing anything. A default file that ships in the tree is a configuration surface; the README's opening section names command line arguments as the way to set the percentage.
The rest of the tree shows the split between daemon and tests. The daemon is six C files, `globals.c`, `kill.c`, `main.c`, `meminfo.c`, `msg.c` and `proc_pid.c`, all but `main.c` with a matching header, which matches the two inputs it reads: `meminfo.c` for memory and swap, `proc_pid.c` for the scoring walk, `kill.c` for the signals. Tests are Go: `go.mod` declares module github.com/rfjakob/earlyoom at go 1.16 with `golang.org/x/sys v0.6.0`, and `testsuite_unit_test.go`, `testsuite_cli_test.go`, `testsuite_helpers.go` and `testsuite_c_wrappers.go` hold the unit and integration coverage.
git clone https://github.com/rfjakob/earlyoom.git
cd earlyoom
make
The tree carries an MIT licence and a last push on 2026-10-26, so the code is recent, although nothing in it records when flags appeared.
journalctl and grep are the whole integration surface
Every action is logged to stderr, which under systemd means the last 10 lines are visible with `systemctl status earlyoom`. For anything automated, the recipe is to filter the unit for kill lines.
sudo journalctl -u earlyoom | grep sendingThe kill lines carry the signal, the pid, the uid, `oom_score`, `oom_score_adj`, `VmRSS` and the `cmdline`, so a notification system built on this recipe parses text.
To watch it work, the documentation makes the leak on purpose:
tail /dev/zeroTwo related projects sit in the see also list: nohang, described as similar but written in Python with additional features and configuration options, and Facebook's pressure stall information kernel patches, merged in Linux 4.20, with the accompanying `oomd` userspace helper. The documentation links all three without comparing them, so a machine that needs per cgroup limits is not settled by anything here.
Editorial conclusion
earlyoom earns its place on a single Linux host that swaps itself into a stall, because its poll loop, its two stage signals and its 2 MiB footprint fit on one screen of C. It is the wrong tool for per cgroup limits or a fleet of machines. Before leaving it unattended, read the shipped default file, check your kernel version before using --kernel-oom, and accept that one memory episode can take several processes.
Frequently asked questions
What does earlyoom do?
It checks available memory and free swap up to 10 times a second, and when both fall below 10 percent it sends SIGTERM to the process with the highest value in /proc/*/oom_score. Its startup banner shows a second stage that sends SIGKILL at 5 percent, and processes are killed until the readings are back above the minimum.
How do I install earlyoom?
Build from a clone with make, then run sudo make install for a systemd unit or sudo make install-initscript for init.d, where update-rc.d registers the runlevels for you. Distribution packages cover Debian 10 and Ubuntu 18.04 or newer, Fedora and RHEL 8 with EPEL, and Arch Linux.
How do I use earlyoom once it is running?
Start the executable directly and it reports total memory, user memory total, total swap, the minimum it waits for, available memory and free swap on every poll. To watch it act, run tail /dev/zero so that a process leaks memory on purpose.
Is earlyoom safe to leave running?
It kills whatever the kernel scores highest, so raising oom_score_adj on a service moves that service up the kill order regardless of its real memory use. Every kill is logged to stderr with the pid, uid, oom_score, oom_score_adj, VmRSS and cmdline.
What are the differences between systemd-oomd and earlyoom?
The README points at Facebook's pressure stall information kernel patches, merged in Linux 4.20, and the accompanying oomd userspace helper as a see also entry, next to nohang. It sets out no behavioural difference between oomd and earlyoom, so the README does not settle that comparison.
What is an earlyoom alternative?
The documentation names nohang, a similar project written in Python with additional features and configuration options. It also links the pressure stall information patches merged in Linux 4.20 and the oomd userspace helper that accompanies them, without a comparison.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rfjakob-earlyoom)Star history chart for your README
[](https://hysenlabs.com/projects/rfjakob-earlyoom)Was this useful?