AuditPilot runs with no model key, refuses to publish an accuracy number, and ships no licence file
AuditPilot: auditable enterprise AI agents for evidence-grounded workflows, governed tools, evaluation harnesses, human review, and remediation delivery.
At a glance
- What is it?
- AuditPilot is an agent workbench aimed at enterprise audit delivery, written as a Chinese-first README with English section headings, where the interesting engineering is governance rather than generation. Retrieval defaults to keyword ranking rather than embeddings, the evaluation harness gates releases on assertions rather than scores, and the project states outright that it will not claim hours saved or accuracy without customer measurement. The repository also has no licence file and ships its default branch under an agent-shaped name.
- Who is it for?
- Judge this on its governance claims rather than its model output, because that is where the effort went. Evidence lineage, fail-closed retrieval, signed checkpoints, a release gate that blocks on failed assertions and an explicit refusal to publish unmeasured numbers are all the right instincts for audit work, and the fact that it runs with no API key at all means you can evaluate the workflow before you spend anything.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
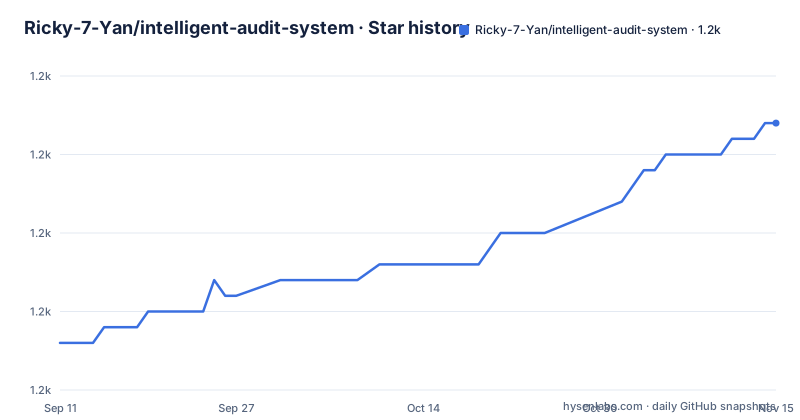
- Ricky-7-Yan/intelligent-audit-system1,182 ★ · +14
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Ricky-7-Yan/intelligent-audit-system | 1.2k | 1.2k |
14 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It runs with no model key at all
The most useful line in the file is in the quick start: the project supports running with no model key configured, and when no large model is set it enters a deterministic fallback mode where the audit workflow, retrieval, evaluation and interface can all still be experienced. That single decision changes how you would evaluate the thing. You are not signing up for a hosted dependency to find out whether the control matrix and evidence request flow suit you. The start sequence is deliberately plain, a virtual environment, the requirements file, a copy of the example configuration, then the launcher, with separate blocks for Windows and for macOS and Linux because the copy command differs:
python3 -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
cp config.env.example config.env
python start.py
The stated requirement is Python 3.10 or newer, and the project configuration narrows that to anything below 3.13. Three launchers sit at the repository root for the three platforms, so nothing about the entry point is clever.
The project refuses to publish an accuracy number
After listing the four audit problems it addresses, the file makes a promise about what it will not claim. It states that the project does not assert a fixed hours saved or accuracy figure without customer testing, and that business value should instead be measured continuously in pilot projects through four named rates: the evidence cycle time, the first-pass review rate for working papers, the evidence sufficiency rate, and the rate at which remediation closes on time. That is a more useful position than a benchmark, because it names the four numbers a buyer would actually ask about and commits to publishing them from real deployments. The rest of the design follows the same logic. A bounded plan, execute and reflect loop with a human review exit. Low-confidence or missing-evidence results routed to review rather than delivered. Failures that become reusable experience only after regression evaluation and human approval.
Retrieval defaults to keyword ranking, not embeddings
The retrieval module is described as multi-path recall with a term-frequency inverse-document-frequency scorer plus keyword matching, fused and reranked, with metadata filtering, page and section level sources, conflicting-evidence detection and missing-evidence prompts. Semantic vectors are named as an optional enhancement, and the configuration section says so plainly: the default install does not include the deep learning framework or the transformer library, you install a separate embeddings requirements file and set a flag if you genuinely need local vectors, because the default hybrid retrieval does not depend on a local model. That is a defensible default for audit evidence, which is full of control identifiers and exact strings where lexical matching beats semantics. It is a bad default if your evidence is mostly prose in scanned documents, where you will want to turn embeddings on and re-measure rather than assume.
Compose makes two secrets mandatory and refuses to start without them
The compose file is thirteen lines and does the security-relevant things properly. The service builds from the repository, publishes one port, loads the local configuration file, and then sets enforced security mode and a bind address of all interfaces. The two credential variables are written with an expansion that makes them required, so the file fails immediately with a message rather than starting an unauthenticated service on a network interface. Two host directories are mounted for data and logs, and the container restarts unless stopped. The image matches that posture: a two stage build that compiles wheels separately, a system user with no login shell, everything copied with explicit ownership, the port exposed, and a health check that calls a readiness endpoint which the documentation says fails when security or the persistent stores are unusable.
The lint baseline is one ruleset, and the exclude list names an old environment
The project configuration is short and worth reading for what it leaves out. The linter targets Python 3.10, sets a line length of 120, and selects exactly one ruleset, the pyflakes group, which catches undefined names and unused imports and nothing else: no import ordering, no naming conventions, no bug-pattern checks. The same file excludes a directory whose name suggests a previous virtual environment was renamed rather than deleted, alongside the data and model directories. The documentation's own validation block is broader than the configuration, running the linter, a separate static security scanner over the four main packages with tests excluded, a dependency vulnerability audit against the requirements file, a byte-compile pass, the test suite, and a coverage run with a floor of seventy-five percent enforced across five named modules:
ruff check agents services rag web tests
bandit -q -ll -r agents services rag web -x tests
pip-audit -r requirements.txt
The coverage command is the one that matters most for a project whose selling point is governance, because it names the five modules it will not let silently rot: the record store, the security module, the agent runtime, the conversation memory and the retrieval layer.
The public scope list rules out job applications and interview write-ups
There is a section stating what will never enter the repository, and it is more specific than most such lists. Excluded are credentials and personal configuration, then local run records, session memory, evaluation results, uploads and generated retrieval stores, then, in its own line, job-seeking job descriptions, interview write-ups, internal design documents and complete archives, and finally local models, editor configuration, logs and temporary files. That tells you what this repository is: work that was cleaned for publication rather than written for publication, which also explains the default branch name, which is a slash-separated branch referring to enterprise agent optimisation rather than a release line. The included list is correspondingly narrow, runnable product code, the public seed data needed to boot, regression tests, screenshots, the readme and the startup configuration.
Six templates, three standards, and no licence
The coverage table is honest about its own limits. Six ready-to-start audit templates are built in, which the file says come from de-duplicated statistics over the versioned templates in one module: four reference standards, thirty-four control topics, thirty-six evidence input types and twenty-five deliverable types. Reading the table, one standard covers financial systems controls, an information security standard covers three separate templates on permissions and segregation of duties, backup and business continuity, and third-party security, a data security statute covers one, and an IT governance framework covers change and release management. The text says these numbers describe the out-of-the-box scope rather than full industry coverage, and that organisations can plug in their own standards, controls and evidence sources. The repository has no licence file and its licence metadata is empty, so there is nothing to copy from.
Editorial conclusion
Judge this on its governance claims rather than its model output, because that is where the effort went. Evidence lineage, fail-closed retrieval, signed checkpoints, a release gate that blocks on failed assertions and an explicit refusal to publish unmeasured numbers are all the right instincts for audit work, and the fact that it runs with no API key at all means you can evaluate the workflow before you spend anything. Two things to settle first. The licence is absent from both the repository and its metadata, so get that answered before you build on it. And the default retrieval is lexical, with semantic vectors behind a separate optional install, so if your evidence is mostly prose in scanned PDFs you will want to turn that on and re-measure.
Frequently asked questions
What does AuditPilot do?
It is an agent workbench for enterprise audit delivery. It organises the repeated work of gathering evidence, mapping controls, testing, chasing missing evidence and delivering into a governed workflow with an audit workspace, a bounded agent runtime, governed tools, an evidence graph and a human review exit, rather than replacing the auditor.
Does AuditPilot need a model API key to run?
No. The project supports running with no model key configured, entering a deterministic fallback mode where the audit workflow, retrieval, evaluation and interface can still be used. Model enhancement is configured through an optional key variable for one provider or a compatible alternative.
How does AuditPilot decide whether something is good enough to ship?
Through an evaluation harness that scores task results, execution traces, tool calls, evidence basis, permissions, context and robustness, producing calibrated scores with confidence lower bounds, and a release gate that blocks directly when a key assertion fails. Failures become reusable experience candidates only after regression evaluation and human approval.
Which audit standards do the built-in templates cover?
Six templates spanning four reference standards, thirty-four control topics, thirty-six evidence input types and twenty-five deliverable types: financial systems controls under one standard, information security under another for permissions, backup continuity and third-party security, a data security statute, and an IT governance framework for change and release management. The file says these numbers describe out-of-the-box scope and that organisations can supply their own standards library.
What licence is AuditPilot released under?
None is declared. There is no licence file among the repository's root entries and the licence metadata is empty, so there is no stated permission to copy, modify or redistribute the code until the author says so.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ricky-7-yan-intelligent-audit-system)Star history chart for your README
[](https://hysenlabs.com/projects/ricky-7-yan-intelligent-audit-system)Was this useful?