regex's newest GitHub tag is 1.0.0 from 2018 while its manifest reads 1.13.1
An implementation of regular expressions for Rust. This implementation uses finite automata and guarantees linear time matching on all inputs.
At a glance
- What is it?
- A finite-automata regex engine for Rust whose documentation is careful enough to admit that its list of unsupported syntax is open-ended, whose recommended lazy-compilation pattern needs a newer compiler than its own declared minimum, and whose packaging list names a licence file the repository does not contain.
- Who is it for?
- The regex crate suits almost any Rust project that needs pattern matching with a worst-case time guarantee, and it is the default choice precisely because it refuses features it cannot support efficiently. Check five things before you rely on a specific behaviour.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
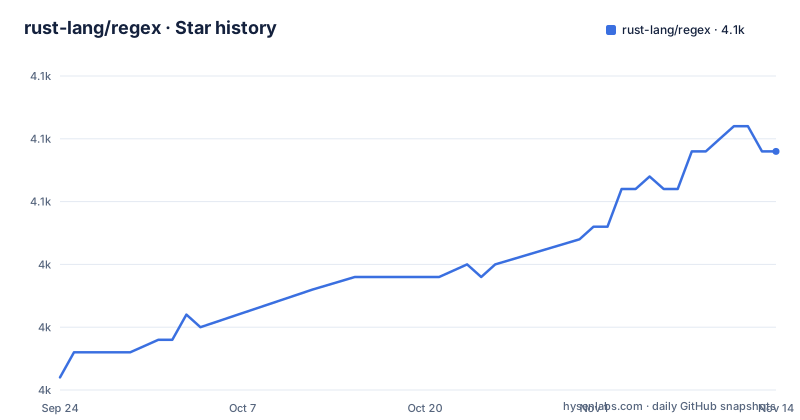
- rust-lang/regex4,054 ★ · +18
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| rust-lang/regex | 4k | 4.1k |
18 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The tag record and the manifest version are eight years apart
The version field in the manifest reads 1.13.1. The newest GitHub release tag is 1.0.0, published in May 2018, with the two before it from March 2018 and May 2017. So every published version from 1.0.1 through 1.13.1 has no corresponding tag, and the releases list a maintainer would land on from the repository page describes a build from 2018. The manifest gives the reason. The version line carries a trailing comment marker that looks like a slot for release tooling to rewrite, which is the pattern used by scripts that bump a version in place and push, and a push of that shape does not need a tag. For a library distributed through a package registry that reads the manifest rather than the tag list, this is a normal arrangement. It has one consequence worth stating plainly: for this crate the releases list is not a version history, and the branch itself is the only place to look for what is current. The branch was last pushed on 10 August 2026, about two months ago, so code is moving while the tag list stands still.
The one-line description says linear and the readme says the product of two sizes
The crate's description, which appears both in the manifest and on the repository page, says the implementation uses finite automata and guarantees linear time matching on all inputs. The readme says something more precise and, read literally, different: all searches in the crate have worst case time complexity equal to the product of the size of the pattern and the size of the string being searched. Those two statements are reconcilable, but only under an assumption the readme makes explicit and the description leaves implicit. Growing the input with a fixed pattern is linear, which satisfies the description. Growing the pattern as well is not. So the guarantee is linear in the thing you usually care about, and quadratic in the combined size of pattern and input, and a reader who takes the one-line description at face value will believe the first where the second is what is actually promised. Both the manifest and the readme also carry the same deliberate omission list, so the two documents agree on what is missing even where they phrase the cost differently.
The packaging list names a licence file the tree does not contain
The manifest declares a dual licence, the permissive pair, and the repository root holds two files matching that, one for each licence. The packaging list at the workspace level then names a third: a licence file for Unicode data, listed alongside the other two and with the other documentation files. No such file is among the top level entries of the repository. So the allowlist that decides what ends up in the published tarball refers to a path that is either generated during packaging or absent, and nothing in the file explains which. Alongside it sits a separate document about Unicode data, which is the more interesting half of the story for anyone trying to work out what obligations attach to shipping this crate, because a regex engine embeds Unicode tables and the licence covering those tables is a different question from the licence covering the code. The rest of the allowlist is unusually broad for a library: it names benchmark sources, benchmark data directories, integration test sources, and the test data itself as toml files, with a single explicit exclusion carved out of the test tree.
The recommended lazy pattern needs a newer compiler than the declared floor
The manifest declares a minimum compiler version of 1.65 on the 2021 edition. The readme's guidance on avoiding repeated compilation recommends a synchronisation type from the standard library, which was stabilised well after 1.65, and links to its documentation. So a project pinned to the declared minimum can depend on the crate and cannot use the pattern the readme leads with. The readme does anticipate the problem, offering an external cell type as the fallback for anyone who cannot use the standard library. What it does not do is rank the third option it mentions. A macro is offered as another way to get the same lazy behaviour, described in one sentence with a link and no example, while the standard library type gets a complete worked program:
use std::sync::LazyLock;

use regex::Regex;

fn some_helper_function(haystack: &str) -> bool {
    static RE: LazyLock<Regex> = LazyLock::new(|| Regex::new(r"...").unwrap());
    RE.is_match(haystack)
}

fn main() {
    assert!(some_helper_function("abc"));
    assert!(!some_helper_function("ac"));
}
So for a project on the minimum version, the macro is the one option that needs neither a newer compiler nor an extra dependency, and it is the one with no code. The stated reason to hoist compilation is also worth repeating, because it is not only the compile: it also prevents the matching engines from reusing allocations internally.
The standard library feature cannot be turned off and half its list is optional
One default feature carries a comment that says it permits the crate to use the standard library, that this is intended to support future cases where the crate could compile without it, and that this is not currently supported and removing the feature will prevent the crate from compiling. So the feature is in the default set, cannot be disabled, and exists for a future that has not arrived. The list under it does not match the comment's tone. Two of its four entries use the weak dependency syntax, which means enable that dependency's own standard-library feature if it is present at all, and neither of those two dependencies is a default. The other two are unconditional, forwarding to workspace members. So the feature is a fan-out of which two entries may do nothing, sitting directly beneath a comment asserting it is load bearing. The answer to wanting a build without the standard library is not this flag but a different crate: the workspace contains a second, smaller engine alongside this one, and the file as shown does not connect the two facts.
The same character class means different things in the two interfaces
This is the most practically useful section in the file, and it is about a trap rather than a feature. The main interface takes a string slice, which in Rust must be valid UTF-8, so it cannot search arbitrary bytes. The byte interface is identical apart from taking a byte slice, and it additionally allows Unicode mode to be switched off even where the pattern would match invalid UTF-8. The consequences are spelled out. Disabling Unicode mode for a sub-expression is not permitted in the main interface at all, while the same construct is accepted in the byte one, where a dot matches any byte except a newline instead of the encoding of a Unicode scalar value. And a negated character class excluding the null byte matches any byte in the byte interface, including bytes that are not valid UTF-8, where in the main interface the same class matches only valid UTF-8 sequences. So a pattern can port between the two interfaces, compile in both, and quietly match a different set of strings. The example shows the whole-pattern form of the mode flag in use:
use regex::bytes::Regex;

let re = Regex::new(r"(?-u)(?<cstr>[^\x00]+)\x00").unwrap();
let text = b"foo\xFFbar\x00baz\x00";

// Extract all of the strings without the null terminator from each match.
// The unwrap is OK here since a match requires the `cstr` capture to match.
let cstrs: Vec<&[u8]> =
    re.captures_iter(text)
      .map(|c| c.name("cstr").unwrap().as_bytes())
      .collect();
assert_eq!(vec![&b"foo\xFFbar"[..], &b"baz"[..]], cstrs);
The file does not say what happens if you leave the flag off in the byte interface, which is the case most readers arrive with.
The list of unsupported syntax is open-ended by its own admission
The readme states up front that the syntax is similar to other engines but lacks features that are not known how to implement efficiently, and names look-around and backreferences, with a qualifier that the list includes but is not limited to those. That qualifier is the important part. It means the two named omissions are examples rather than the complete set, so there is no way to read this file and conclude that a pattern is safe to port. A user arriving from an engine with backreferences and look-around will find both rejected, and then has no list to work down. The escape hatches are documented, and there are three. The byte interface exists for binary searching. A second crate in the same repository exposes the internal matching engines, framed as the simple crate covering the large majority of use cases against this one offering a much larger set of configurable behaviours. And a third crate provides a parser, an abstract syntax tree and a high-level intermediate representation, with the explicit note that it provides no compilation or execution facilities and is not recommended for general use. That last framing is a signal: it is an analysis tool for people building engines, not a fallback for people whose patterns do not compile.
Seven crates, and the C interface is not among the ones the file explains
The workspace has six members alongside the crate you depend on, and they cover a lot more ground than the readme leads you to expect. The readme explains two of them in its own sections: the internals crate, and the parser crate. Two more appear in the manifest without explanation, one of which is a C interface to the engine. A C binding is a real published surface with its own consumers and its own stability considerations, and the readme's narrative, which is entirely Rust, does not mention it. The remaining members are a lighter engine, a command line tool and a test crate. Alongside them the root holds a directory for fuzzing, one for recorded material, a directory of test data as toml files, a separate file for cross-compilation configuration, a formatting configuration, a second ignore file, a Vim directory, and a policy file about AI contributions. One structural oddity is worth flagging: there is a top level entry named test with no file extension sitting beside the conventional tests directory, and the packaging allowlist names the tests tree and not that one. The manifest also disables automatic test discovery, so the test targets are declared by hand rather than found by convention.
Editorial conclusion
The regex crate suits almost any Rust project that needs pattern matching with a worst-case time guarantee, and it is the default choice precisely because it refuses features it cannot support efficiently. Check five things before you rely on a specific behaviour. Its list of unsupported syntax is explicitly non-exhaustive, so porting a pattern from another engine means testing rather than reading. The same character class means something different in the byte API, so a pattern moved between the two interfaces can silently change what it matches. The lazy-compilation pattern the readme recommends needs a newer compiler than the manifest's declared minimum, and the option available on the minimum is the one with no example. The standard library feature cannot actually be turned off. And if you need the internals, they live in a second crate rather than behind a feature of this one.
Frequently asked questions
What does the Rust regex crate not support?
Look-around and backreferences, because they are not known how to implement efficiently while keeping the linear time guarantee. The readme says the list includes but is not limited to those two, so the readme is not a complete list of what will fail to compile.
Is the Rust regex crate linear time?
The one-line description says it guarantees linear time matching on all inputs, while the readme gives a worst case bound of the product of the pattern size and the size of the string searched. The two agree only if the pattern size is treated as a constant.
What Rust version does the regex crate need?
The manifest declares a minimum of 1.65 on the 2021 edition. The lazy-compilation pattern the readme leads with uses a standard library synchronisation type stabilised after that, with an external cell type offered as the fallback for projects that cannot use the standard library.
How do I search bytes with the Rust regex crate?
Use the byte interface, which is otherwise identical but takes a byte slice and allows Unicode mode to be disabled even where the pattern would match invalid UTF-8. The readme warns that the same negated character class matches any byte in that interface and only valid UTF-8 sequences in the main one.
What is the newest release of the Rust regex crate?
The manifest reads 1.13.1 while the newest GitHub release tag is 1.0.0 from May 2018, so the tag list does not track published versions. The version line carries a marker that suggests release tooling rewrites it in place, and the branch was last pushed on 10 August 2026.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rust-lang-regex)Star history chart for your README
[](https://hysenlabs.com/projects/rust-lang-regex)Was this useful?