A factory for agent harnesses, with claim gates written as build steps
🛠️ The meta-harness for AI agents — scaffold your own focused, branded agent harness with its own npx CLI, MCP server, memory, learning loop, and witness-signed releases. Works with Claude Code, Codex, pi.dev, Hermes, OpenClaw, and RVM (hardware-isolated sandbox).
At a glance
- What is it?
- MetaHarness generates a branded agent harness for any repository in about a minute, producing a publishable archive with its own npx command, memory scoped to the project, skills derived from the actual file layout and adapters for ten agent hosts, and its most distinctive feature is not the generation but the apparatus around claims: an npm script whose job is to enforce that a performance claim is not published until a pre-registered evaluation passes, checked against the exact tag and the published tarball.
- Who is it for?
- It fits a team that wants an agent tuned to one repository rather than a general-purpose tool, since the generated skills are derived from your file layout and the memory namespace is scoped to the project. Two things to weigh before you rely on any of its numbers.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
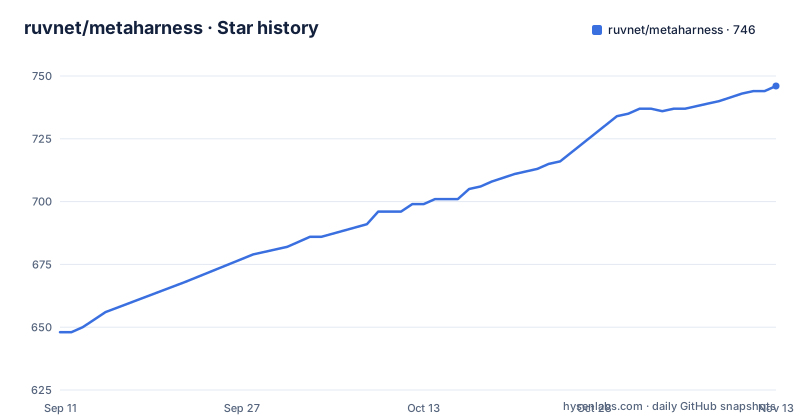
Star history
- ruvnet/metaharness746 ★ · +98
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| ruvnet/metaharness | 648 | 746 |
98 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It is a factory, and three different names are in play
The positioning is stated in one line that is doing a lot of work: this is not another agent framework, it is a factory for agent frameworks. The model is described as replaceable, and the harness as the product.
The generator takes a GitHub URL or a blank slate and produces, in the documentation's words, under sixty seconds, in a browser, with nothing leaving your machine: recommended agents, skills, slash commands and MCP tools, a memory namespace scoped to the project, a governance policy, witness-signed provenance and release gates.
What comes out is described as an archive you could publish to a package registry, with your name on it, your branding, and a command of your own naming under npx. So the unit of output is not a configuration file, it is a distributable product.
The three names are worth noting because they will confuse you on day one. The repository, the command line tool and the library are all named differently, and the workspace root package is named after the library while being marked private, which means what you read at the root of the repository is not the thing you install.
The generated harness is also not locked to one assistant. The documentation lists several compatible hosts and says to pick one or all of them, which is the practical difference between a scaffold and a framework: the framework decides where your tools live, the scaffold lets you emit them in several dialects.
One host has no MCP, and cannot enforce a deny-list either
The most recent host added is described with its limitations rather than around them, and that is the section worth reading.
The new host has no MCP support at all. So the generator emits your tools as project-scoped, Python-backed skills in the host's own directory layout, and ships an install runbook alongside them. That is the generator doing what a framework would have prevented: translating a capability description into whatever shape the target actually understands.
Then the security consequence, which is the part that matters. The host cannot enforce a deny-list itself. Rather than silently dropping the rules you configured, the generator treats it as fail-closed: if your deny-list is not empty, it ships a prominent file telling you a sandbox is required. Your posture is not weakened quietly, and the artefact that would have weakened it is replaced by a document that says so.
That pattern appears elsewhere in the project too. A field memory adapter is described as failing closed unless a specific corrected wrapper is used. A field memory layer refuses to open storage until the deployment supplies three things.
For a tool that generates code which will run with your repository access, fail-closed is the only defensible default, and the fact that it is applied to an integration gap rather than hidden is the reason this host is worth reading about.
The section also notes where an idea was borrowed from: a mutation-proposal component from another package requires the agent to cite the failing traces behind each edit, or propose nothing.
Darwin Mode evolves the harness and freezes the model
Every generated harness ships with a self-improvement loop already wired in, and it is one command.
Running the evolution script makes the harness modify its own configuration, test each change in a sandbox, and keep only what measurably improves. The distinction the documentation insists on is that the model stays frozen while the harness evolves.
That is the interesting constraint. An agent framework that rewrites its own prompts and tool descriptions can be tuned against a fixed model, which makes the improvement measurable. Let the model change and the measurement becomes meaningless.
The safety story is stated in the same paragraph and is unusually specific: safe by default, with no network access and no API key, and the changes confined to refactoring and tuning behind a safety gate. So the loop runs offline against local tests. That is a meaningful constraint, because a sandbox that needs to call a model to evaluate a change cannot run without credentials.
Validation is claimed on a real bug-fixing benchmark at its Lite scale, and there is a flag to skip the whole thing.
The naming is worth noting too. The fast path for ordinary work has its own name, and the heavyweight governed variation package is a different name. So a generated harness has a default loop for cheap edits and an optional, heavily governed loop for hard problems, and they are not the same mechanism.
A build script whose job is to refuse a claim
The most unusual thing in this repository is that publishing a performance claim is treated as a build failure.
There is a script in the workspace root whose name is a claim gate. Running it enforces a boundary that the documentation states as a rule: no capability claim may be published until a pre-registered evaluation has passed. The check runs against the exact tag commit and the published package archive, and it covers protected claim semantics, measured cost, lineage roots, and two independent graders.
Two separate evaluation records are described as the gates. One is a hundred-task unseen benchmark suite that a stronger claim is blocked on. The other is a frozen controlled-ablation requirement referenced by a numbered decision record, without which no claim about the experimental game-environment work may be made.
And the honesty is complete in a way that is rare. A single-game smoke result is reported with its numbers, and immediately marked as not claim-eligible because it is not a competition result. The packages are described as private and experimental. A capability claim is described as honestly deferred behind a pre-registered comparison in an evaluation suite.
So a reader learns three separate times that the strongest statements are not yet supported. That is the opposite of how capability claims usually get written, and it is why the rest of the feature list can be taken at face value.
Hash-chained receipts, and two runtimes that must agree
Auditability runs through the architecture rather than sitting in a logging library, and there are two mechanisms.
The first is hash chaining. The experimental game-environment controller is described as owning hash-chained receipts, so any record in the chain can be verified against the one before it. The governed variation runtime keeps signed replay receipts, meaning a run can be replayed and checked rather than trusted.
The second is a cross-implementation agreement, and it is the more interesting one. There is an opt-in session log written as JSONL that survives a crash. Replaying that log in the native runtime and replaying it in the compiled-to-browser runtime must produce identical state hashes.
That constraint explains the repository's shape. There is a Rust workspace with a core kernel, a WebAssembly build of it, and a native-module binding for Node, and the root package has scripts to build both the browser and native targets. Two implementations, one state, verified by hash.
The Rust release profile is tuned for size rather than speed, with the smallest optimisation level, link-time optimisation enabled, a single codegen unit, symbols stripped and panics aborting rather than unwinding. For a component that ships to both a native host and a browser, and that has to produce bit-identical state in both, trading speed for reproducibility is the correct trade.
There is also a dependency policy file at the root, which is how a project with a Rust workspace keeps its licences checked.
Score a repository without running it
There is a command that answers the question every scaffolder eventually has to: should you do this at all.
Scoring a repository reads it and never runs it, then prints a one-screen report card. Four things are on it: how well a harness fits, how likely it is to build, how safe the tools are, and a rough cost per run.
The never-runs constraint is the important part. A scoring tool that executes the target it is scoring has already done the dangerous thing, and on an unfamiliar repository that is arbitrary code. Reading only is safe, and it also means the score is available before you have configured anything.
Cost per run on the card is the other interesting item. The whole premise is that a repository-specific harness beats a general one, and the question a sceptical reader asks is what that costs in tokens. Putting the estimate on the same card as the fit and the safety is a fair way to present it.
A separate package handles the other half of the cost problem. The router sends each request to a model chosen from your own recorded results, which is the same idea as the rest of the project applied to model selection: replaceable parts, tuned on your data. It works with no native dependencies, and an optional native trainer is described as taking the same training data with no API change.
Field memory will not open storage until you give it three things
The memory subsystem is experimental, and its refusal conditions are the most specific in the documentation.
The layer is a packed-attractor design, single-process by default, with verified outcome caps, quarantine for support, decay, and cost-aware selection. It exposes no raw-episode interface at all, which is a deliberate constraint: if you cannot read the raw episodes, you cannot build a prompt-injection surface out of them.
Then three preconditions before it will open storage or accept shared updates. The deployment has to supply an absolute storage path, a compatible adapter, and a principal verifier backed by deployment authentication.
The third one is the load-bearing. A principal verifier means the identity that authorises a write is derived by a verifier rather than asserted by the caller, and requiring deployment authentication underneath means the verifier itself is anchored to something real. Support is handled by three distinct verifier-derived principals, with no hysteresis and a bounded drift window, and the documentation is candid that the independence of those principals depends on the verifier's identity system being sound.
There is a fourth fail-closed rule elsewhere: the vector-store adapter refuses to work unless a specific corrected wrapper is in place.
So for the memory layer specifically, the default is inert. Nothing moves until you satisfy three conditions, and where the identity system is weakest the project says so.
Editorial conclusion
It fits a team that wants an agent tuned to one repository rather than a general-purpose tool, since the generated skills are derived from your file layout and the memory namespace is scoped to the project. Two things to weigh before you rely on any of its numbers. The strongest capability claims are described as blocked on pre-registered evaluations that have not run, and the one experimental result that did run is explicitly marked as not eligible to be claimed, so read the capability descriptions as intent rather than capability. And one host cannot enforce a deny-list, in which case the generator ships a file saying so instead of quietly weakening your posture, which is the right behaviour and worth checking for in any tool you point at a repository. Also note the naming: three different names for one project, and the root package is private.
Frequently asked questions
What is a meta-harness?
In this project it is a factory for agent harnesses rather than an agent framework. From a GitHub URL or a blank slate, MetaHarness generates a repository-specific harness in about sixty seconds in the browser, with skills derived from the actual file layout, a project-scoped memory namespace, a governance policy, and adapters for ten agent hosts. The output is a publishable archive with your own name and command.
What does the generated MetaHarness output contain?
Recommended agents, skills, slash commands and MCP tools derived from the repository, a memory namespace scoped to the project, a governance policy, and witness-signed provenance with release gates. It ships as an archive you can publish to a package registry, exposing a command line tool under your own name, and it can target several agent hosts at once.
What is Darwin Mode in metaharness?
A self-improvement loop wired into every generated harness. Running the evolution script makes the harness mutate its own configuration, test each change in a sandbox, and keep only what measurably improves. The model is deliberately left frozen while the harness evolves, it runs with no network access and no API key, and there is a flag to skip it.
How does MetaHarness handle hosts that cannot enforce a deny-list?
It fails closed. The newest host has no MCP support, so tools are emitted as project-scoped Python-backed skills in that host's own layout. Because the host cannot enforce a deny-list itself, a non-empty deny-list causes the generator to ship a prominent file stating that a sandbox is required, rather than silently dropping the security posture you configured.
Why are most metaharness capability claims described as blocked?
Because the project enforces a rule that no capability claim may be published until a pre-registered evaluation passes, checked by a claim-gate script against the exact tag and the published package archive with two independent graders. The stronger claims are documented as blocked on named evaluation suites, and the one experimental result that did run is explicitly marked as not claim-eligible.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ruvnet-metaharness)Star history chart for your README
[](https://hysenlabs.com/projects/ruvnet-metaharness)Was this useful?