Photon Crawls for Recon and Tags Releases From 2019
Incredibly fast crawler designed for OSINT.
At a glance
- What is it?
- Photon is a Python crawler aimed at OSINT that harvests URLs, subdomains, emails, secret keys and JavaScript endpoints from a seed domain. Its dependency list is four lines long, its Docker image rebuilds from master instead of your checkout, and its newest release tag is dated 2019-04-05 even though the repository was pushed to on 2026-10-17.
- Who is it for?
- Photon suits a researcher who already knows what the wiki Usage page says about a given flag, who can supply their own scoping and exclusion rules, and who will run it from source rather than from PyPI. It does not suit an auditor who needs a pinned, dated release or who expects the README to describe the legal and rate boundaries of a crawl, because neither exists in this repository.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 27 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
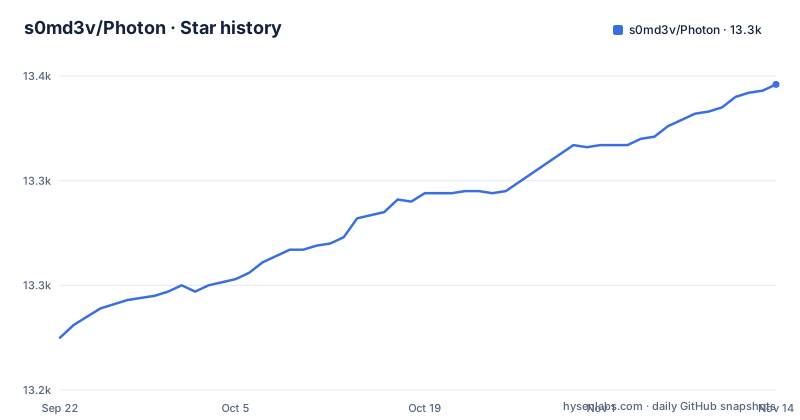
- s0md3v/Photon13,346 ★ · +121
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| s0md3v/Photon | 13.2k | 13.3k |
121 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One entry point, four dependencies, one plugins directory
The repository is laid out flat: photon.py at the root, a core directory, a plugins directory, requirements.txt, Dockerfile, MANIFEST.in, CHANGELOG.md, LICENSE.md, a .travis.yml and a .whitesource config. The entire declared dependency list is four lines:
requests
requests[socks]
urllib3
tld
That is worth pausing on. The feature list promises DNS related data, JavaScript endpoint extraction and secret key matching. None of those needs is reflected in a declared dependency beyond requests, urllib3 and tld. The Compatibility and Dependencies page on the wiki is where the real dependency story has to be, which means the repository alone cannot tell you whether your Python version will work.
The newest tag is from 2019 while the last push is from 2026
Here is the gap that matters most for anyone deciding what they are running. Three release tags are visible: v1.1.6 on 2019-01-25, v1.2.1 on 2019-01-26, and v1.3.0 on 2019-04-05. The last push to the repository is dated 2026-10-17 and the project is not archived. Between those two facts sits a page that announces Photon is under heavy development, that updates for bugs and performance are rolled regularly, and that an --update option installs updates without losing saved data. None of that is wrong as an intention, but the newest release tag is still the 2019 one. Treat the version string as evidence of age rather than of currency, and if you need to know exactly what code produced a set of findings, read the commit out of the tree yourself instead of trusting the tag.
The image clones master instead of copying your checkout
The Dockerfile is nine meaningful lines and three of them decide what you actually run:
FROM python:3-alpine
RUN apk add git && git clone https://github.com/s0md3v/Photon.git Photon
WORKDIR Photon
RUN pip install -r requirements.txt
VOLUME [ "/Photon" ]
ENTRYPOINT [ "python", "photon.py" ]
CMD ["--help"]
Two consequences follow directly. The clone happens inside the build, so the image is whatever master looked like at build time rather than whatever you have checked out locally, and two people building from the same local commit can end up with different images if a push lands in between. The base image is the floating tag python:3-alpine, so the build is not reproducible over time either. And because CMD is --help, a bare docker run prints usage and exits instead of starting a crawl, which is a small thing that surprises people the first time.
Results land in a directory named after your seed
The documented first run builds the image and points it at a domain:
$ git clone https://github.com/s0md3v/Photon.git
$ cd Photon
$ docker build -t photon .
$ docker run -it --name photon photon:latest -u google.com
Getting the output back out is the part people trip over. The page says you can head to the local docker volume, which you find by running docker inspect photon, or mount the target folder yourself:
$ docker run -it --name photon -v "$PWD:/Photon/google.com" photon:latest -u google.comNote that the mount path ends in the seed domain. The output directory is derived from the -u argument, so for any run other than a single seed you have to work out the directory naming yourself, and if you skip the -v form and the container is removed, the findings go with the volume you never inspected.
Extraction is one flat list with no scope or robots guard
The extraction section is eight bullets with no priority order: URLs both in-scope and out-of-scope, URLs carrying parameters such as example.com/gallery.php?id=2, intel covering emails and social media accounts and amazon buckets, files such as pdf and png and xml, secret keys described as auth and API keys and hashes, JavaScript files and the endpoints inside them, strings matching a custom regex, and subdomains with DNS related data. Everything the crawler touches gets written down, in scope or not. The controls offered are timeout, delay, extra seeds and excluding URLs by regex, and the extension point for more extraction is described as adding more APIs for ninja mode. What is absent is as important: the README does not mention robots.txt, states no rate limit ceiling, and defines no scope file. The scoping decision is yours, made before the run. The saved output is described as organized, or exportable as json through a wiki anchor, but no output format other than that json link is named, and no sample result file ships in the repository, so a first-time user has to guess the directory layout from the mount path alone. Treat the first run against a domain you own as the way to learn that layout, rather than the way to learn the tool.
Three plugins, and only one has a flag named in the page
Three plugins are listed: wayback, dnsdumpster and Exporter. Only the first one is reachable from anything written on this page. Its behaviour appears twice, once as a named option and once as a plugin link, and it is the one genuinely useful trick described: --wayback pulls URLs archived by archive.org and uses them as seeds, which turns a dead or thin subdomain into a crawl target. dnsdumpster and Exporter have no invocation shown at all. Export is described twice as well, once as a plugin and once as a link to a wiki anchor about exporting formatted results as json. If you are wiring output into a pipeline, find out which of those two you are actually calling before you build around it.
The page repeats itself and carries text from somewhere else
Two things about the README itself are worth knowing before you treat it as a specification. The whole Key Features block, from Data Extraction through the Docker section, appears twice, in full, back to back. And the update section, between the sentence about checking for updates and the closing footer, contains instructions for a web form rather than a crawler: use Control plus Shift plus m to toggle the tab key moving focus, alternatively use esc then tab to reach the next interactive element, and attach files by dragging and dropping, selecting or pasting them. Those lines are followed by a link to thordata.com. None of that describes anything Photon does. It is a signal about where the real documentation lives, which is the wiki, and about how much care the page has had.
Editorial conclusion
Photon suits a researcher who already knows what the wiki Usage page says about a given flag, who can supply their own scoping and exclusion rules, and who will run it from source rather than from PyPI. It does not suit an auditor who needs a pinned, dated release or who expects the README to describe the legal and rate boundaries of a crawl, because neither exists in this repository. Before trusting output, confirm the dependency story on the Compatibility and Dependencies wiki page, decide your own scope rules, and check whether the copy you installed is newer than 2019 before you report anything it found.
Frequently asked questions
What does s0md3v Photon extract while crawling?
Eight categories: URLs in scope and out of scope, URLs with parameters, intel such as emails and social media accounts and amazon buckets, files such as pdf and png and xml, secret keys including auth and API keys and hashes, JavaScript files and their endpoints, strings matching a custom regex, and subdomains with DNS related data.
How do I run Photon in Docker?
Build it and point it at a seed with `docker run -it --name photon photon:latest -u google.com`. To read results out, either inspect the local volume with `docker inspect photon` or bind-mount the seed folder with `-v "$PWD:/Photon/google.com"`.
Which Python packages does Photon declare?
requirements.txt contains four entries and nothing else: requests, requests[socks], urllib3 and tld. The Dockerfile installs them with pip install -r requirements.txt.
Can Photon use archive.org URLs as crawl seeds?
Yes. The --wayback option fetches URLs archived by archive.org and uses them as seeds. It is also listed as a plugin named wayback.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/s0md3v-photon)Star history chart for your README
[](https://hysenlabs.com/projects/s0md3v-photon)Was this useful?