nanoAgent puts a whole function-calling loop in one file, and names one tool twice
If you can read ~100 lines of Python, you understand agents.
At a glance
- What is it?
- nanoAgent is a Python agent built on OpenAI function calling with three tools: run a bash command, read a file, write a file. The whole loop is about a hundred lines and the front page prints its shape verbatim. The prose names the first tool bash while the capability list names it execute_bash, and the loop snippet uses args without ever showing where it comes from.
- Who is it for?
- Treat nanoAgent as reading material first and a tool second. What it offers is that the entire loop fits in about a hundred lines and the front page prints its shape, which is the shortest way to understand what function calling actually costs you in code.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
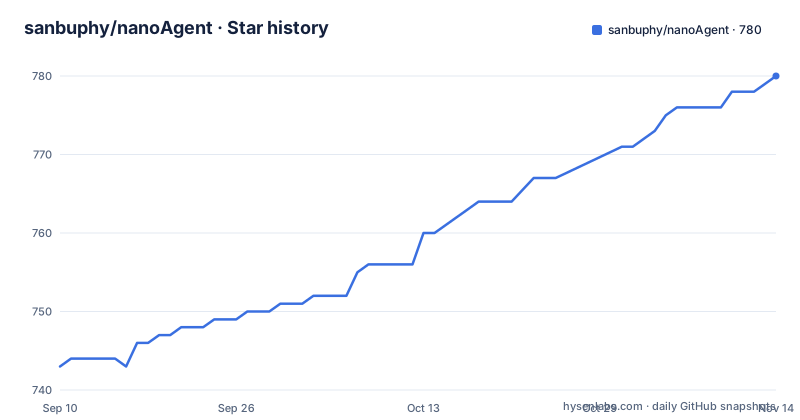
- sanbuphy/nanoAgent780 ★ · +37
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| sanbuphy/nanoAgent | 743 | 780 |
37 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The tool is called bash in one section and execute_bash in another
The front page names the tools twice and only one of the two lists matches itself. The how-it-works section describes the agent deciding which tools to use and lists them as bash, read_file, and write_file. The capabilities section further down lists them as `execute_bash`, `read_file`, and `write_file`. Only the first name differs, and it is the identifier that matters, because the loop dispatches through a mapping keyed on the name the model sends back. If you follow the earlier phrasing and register a tool called bash, the lookup the loop performs is against a key the capabilities list never mentions. Nothing in the loop renames anything on the way through. The other two entries are spelled identically in both places, which is what makes the drift easy to skim past.
The loop snippet uses args without ever creating it
The code block prints the whole shape in a dozen lines:
# Define tools
tools = [{"type": "function", "function": {...}}]

# Agent loop
for _ in range(max_iterations):
    response = client.chat.completions.create(model=model, messages=messages, tools=tools)
    if not response.choices[0].message.tool_calls:
        return response.choices[0].message.content

    # Execute tool calls
    for tool_call in response.choices[0].message.tool_calls:
        result = available_functions[tool_call.function.name](**args)
        messages.append({"role": "tool", "content": result})
What the block never shows is where `args` comes from. A tool call carries its arguments as a JSON string inside the function object, and the unpacking between reading that string and calling the function by keyword is exactly the line left out. That is the same boundary the paragraph below the block describes, since malformed JSON arguments are what arrives there.
Two hardened failure cases are described and neither appears in the snippet
The page states that recent hardening keeps the loop running even when a tool call contains malformed JSON arguments or references an unknown tool, and that those cases are returned to the model as explicit tool errors instead of crashing the agent. Two properties follow. A tool name the agent has never heard of becomes a message sent back into the conversation rather than an exception raised in the dispatch loop. A malformed argument string likewise becomes a message, so the model is given the chance to correct itself on the next turn instead of the process ending. Neither branch is in the block above, and neither is the value of `max_iterations`, which bounds the loop but is not given a number anywhere on the page. What is described and what is shown are two different shapes of the same function.
The dependency list is one line with no version on it
requirements.txt holds a single entry, `openai`, with no version constraint and no comment beside it. The entire runtime surface is therefore whatever the current release of that one package resolves to on the day you install, which is the opposite of the pinning discipline the MimikaStudio and pandas materials elsewhere in this ecosystem use. Three environment variables do the rest of the configuration. `OPENAI_API_KEY` is the only one without a default and the only one you must set. `OPENAI_BASE_URL` defaults to `https://api.openai.com/v1` and is marked optional, which means the same loop can be pointed at any endpoint that speaks that protocol rather than at OpenAI. `OPENAI_MODEL` defaults to `gpt-4o-mini` and is also optional, so the model is chosen at run time from the environment instead of being pinned in code.
Three shells are documented and the third one drops the annotations
The setup step is written three times so the same three variables land correctly per platform:
export OPENAI_API_KEY='your-key-here'
export OPENAI_BASE_URL='https://api.openai.com/v1'  # optional
export OPENAI_MODEL='gpt-4o-mini'  # optional
for macOS and Linux, then a PowerShell block using `$env:` prefixes, then a Windows CMD block using `set`. The CMD variant is the odd one out: it carries neither the single quotes around the values nor the two `# optional` markers, and its key line reads without quotes where the other two quote the placeholder. That is a small difference in a copy-paste block, but it is the one place where the three blocks stop being line-for-line the same three statements.
Three entry points sit in the tree and one of them is documented
The front page names exactly one file. Every command in the quick start and every example runs `agent.py`, and the whole walkthrough assumes that entry point. The tree also holds `agent-plus.py` and `agent-claudecode.py`, and neither name appears anywhere on the page, along with a `tests/` directory that the page never tells you how to run. The rest of the top level is small and unremarkable: requirements.txt, LICENSE carrying the MIT terms, and .gitignore. One more file matters for readers arriving from a non-English search. README_CN.md holds a Chinese edition of the same page, and the header links the two side by side, so the Chinese version is a translation of this text rather than a separate document with its own scope.
The quick start hands over three prompts and nothing else
Every command on the page has the same shape: a script name and a sentence in quotes. The quick start gives three of them.
python agent.py "list all python files in current directory"
python agent.py "create a file called hello.txt with 'Hello World'"
python agent.py "read the contents of README.md"
The second prompt nests single quotes inside a double-quoted shell argument, so those quotes become part of the text the agent receives rather than shell syntax, which is the detail that makes the write_file case land. The examples block adds three more, grouped by inline comments as system operations, file operations, and combined tasks: asking what the current directory is and what files it holds, asking for a python script that prints hello world, and asking for every `.py` file with a total line count. Six prompts, one script, and the only thing that changes between runs is the English.
execute_bash is described as running any bash command
The capability list is three entries long. `read_file` reads file contents, `write_file` writes content to files, and `execute_bash` runs any bash command. Set that beside the loop described a few paragraphs earlier, which receives a task, decides which tools to use, executes them, returns results to the model, and repeats until the task is complete, and the documented design has no step between the model choosing a command and that command running. There is no approval prompt, no allowlist of permitted commands, no path restriction on read or write, and no mention of a container, a sandbox, or a confined working directory. The examples make the shape concrete: one asks the agent to create a python script, another to find all `.py` files and count total lines of code. Every one of those is a command the agent composes itself rather than one you wrote.
Editorial conclusion
Treat nanoAgent as reading material first and a tool second. What it offers is that the entire loop fits in about a hundred lines and the front page prints its shape, which is the shortest way to understand what function calling actually costs you in code. That same simplicity is why it is not something to point at a machine you care about. execute_bash is described as running any bash command, write_file writes where it is told, and the documented loop has no approval step, no allowlist, and no dry-run between the model choosing a command and that command running. Before you run anything, note three things. The dependency list is a single unpinned package, so what installs is whatever the current release resolves to. The two hardened failure cases are described but not shown, including the argument parsing step the snippet omits. And the last push on this repository is dated 2026-03-13. If you want a modern tool-fetching layer instead of three hardcoded functions, the author points you at a separate project for exactly that.
Frequently asked questions
How do I install nanoAgent and configure it?
requirements.txt holds a single unpinned entry, openai, installed with pip install -r requirements.txt. Three environment variables configure a run: OPENAI_API_KEY is the only one with no default, OPENAI_BASE_URL defaults to https://api.openai.com/v1, and OPENAI_MODEL defaults to gpt-4o-mini. Separate blocks are given for macOS and Linux, Windows PowerShell, and Windows CMD.
What tools can nanoAgent call?
Three. execute_bash runs any bash command, read_file reads file contents, and write_file writes content to files. The earlier narrative on the page calls the first one bash while the capability list calls it execute_bash, so the name that reaches the model is the second one.
Does nanoAgent handle malformed or unknown tool calls?
The page states that recent hardening keeps the loop running when a tool call contains malformed JSON arguments or references an unknown tool, and that both are returned to the model as explicit tool errors rather than crashing the agent. Neither branch appears in the loop snippet printed above that paragraph, and the argument parsing step is omitted from the block entirely.
Does nanoAgent support MCP or fetch tools dynamically?
Not in this repository. The front page points at a separate project by the same author, nanoMCP, and describes it as the place to learn what MCP is and how to fetch tools in a more modern way.
Is nanoAgent still being worked on?
The repository is not archived and its last push is dated 2026-03-13. It publishes no GitHub releases and gives no version string on the page. The tree contains agent.py, agent-plus.py, and agent-claudecode.py, but only agent.py is named in the quick start or the examples.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sanbuphy-nanoagent)Star history chart for your README
[](https://hysenlabs.com/projects/sanbuphy-nanoagent)Was this useful?