SchemaSpy: reads structure only, so an empty replica is enough
Database documentation built easy
At a glance
- What is it?
- A standalone Java analyzer that turns database metadata into a browsable HTML report. The distribution is three ways (JAR, Docker, Maven with an `app` classifier), the docs example still pins 6.2.4, and the branch last moved on 2026-03-05.
- Who is it for?
- Take SchemaSpy when you need browsable documentation of a schema you do not want to expose data from, since it reads structure only and works against an empty replica, and when a generated ER diagram in CI is an acceptable substitute for one a human drew. Check three things first.
- Can I use it commercially?
- Yes, with conditions. LGPL-3.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
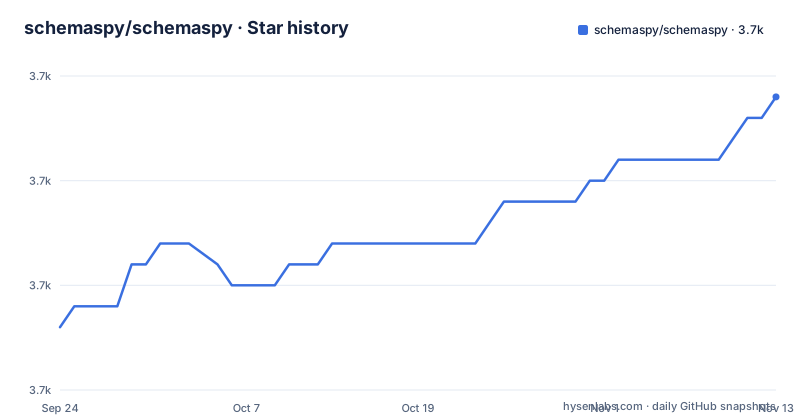
Star history
- schemaspy/schemaspy3,739 ★ · +11
| Repository | 2026-09-24 | 2026-11-13 |
|---|---|---|
| schemaspy/schemaspy | 3.7k | 3.7k |
11 Stars in the last 50 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The download command pins 6.2.4 while the newest tag is 7.0.2
The installation section hands you a curl command with a version substituted into the URL and a comment telling you to replace it:
# replace '6.2.4' with latest version
curl -L https://github.com/schemaspy/schemaspy/releases/download/v6.2.4/schemaspy-6.2.4.jar \
    --output ~/Downloads/schemaspy.jar
The instruction is correct and the literal value is stale. The most recent release is v7.0.2, published 2025-09-20, and before that came v6.2.4 from 2023-07-21 and v6.2.3 from 2023-06-20. So the gap between the second newest and newest tags is over two years, while the gap between the third and second is about a month. Anyone following the page literally downloads a build two major versions behind. There is also a separate channel for work that has not been released: a snapshot JAR hosted on the project's own download page, or the Docker image tagged `snapshot`, both aimed at unreleased bug fixes and features in progress. The default branch last moved on 2026-03-05, which is the date to weigh against the age of the newest tag when you decide between them.
Two Maven artifacts differ by one classifier: app
The Maven route publishes two artifacts from the same build and the only difference is a classifier, which is easy to get wrong when you add the dependency. The bare-bone JAR is `org.schemaspy:schemaspy:<version>` and the fat JAR, which bundles all dependencies, is `org.schemaspy:schemaspy:<version>:app`, with the page pointing at the `app` classifier explicitly. Both go to Maven Central, and the fat JAR is additionally attached to the GitHub releases, which is why the standalone download and the Maven dependency can resolve to the same artifact. The bare-bone variant exists for environments where you supply the JDBC drivers yourself, which connects to how the quick start works: the driver is downloaded separately and passed on the command line rather than being shaded in. The README points the Maven Central badge at the latest published version, so the version you resolve from the index may differ from the one in the curl example on the same page. That is the single most likely source of confusion for a new user.
The Docker image vendors four drivers and needs graphviz
The image is a two stage build and the first stage exists only to fetch drivers. It starts from `curlimages/curl:8.2.1` and pulls four jars by URL from search.maven.org, each version pinned as an environment variable: MySQL connector 8.4.0, MariaDB client 1.1.10, PostgreSQL 42.7.2, and jTDS 1.3.1. Those four are baked in, which is a smaller set than the dozen-plus database types the tool claims to support out of the box, so anything outside MySQL, MariaDB, PostgreSQL and SQL Server needs a driver supplied from outside. The runtime stage is `eclipse-temurin:17.0.9_9-jre-jammy`, which fixes the Java baseline at 17 for the container path. It installs graphviz with suggestions and recommends disabled, since the ER diagrams need it, and it adds a bundled Open Sans font archive. The image creates an unprivileged user named java, hands it `/output`, switches to it, and exposes two environment variables, `SCHEMASPY_DRIVERS` pointing at `/drivers` and `SCHEMASPY_OUTPUT` pointing at `/output`, with the entrypoint set to the `schemaspy` script rather than the jar directly. Note the pinned PostgreSQL driver is 42.7.2 while the quick start example downloads 42.5.4.
Any database with a JDBC driver works, and -dbhelp lists them
Coverage is handled by the JDBC layer rather than by a plugin system, which is the simplest thing that could work and also the reason the list of databases is long. The page claims support for over a dozen database types out of the box, with `-dbhelp` printing them, and states that as long as your database has a JDBC driver you can plug it into the tool, linking to a databaseType configuration page in the documentation. The quick start is written against PostgreSQL 11 or later and shows the driver being fetched first:
curl -L https://jdbc.postgresql.org/download/postgresql-42.5.4.jar \
    --output ~/Downloads/jdbc-driver.jar
Then the analyzer itself runs as a plain Java invocation with the database type token, the driver path, credentials, and an output directory:
java -jar ~/Downloads/schemaspy.jar \
    -t pgsql11 \
    -dp ~/Downloads/jdbc-driver.jar \
    -db DATABASE \
    -host SERVER \
    -port 5432 \
    -u USER \
    -p PASSWORD \
    -o DIRECTORY
The result lands in `DIRECTORY/index.html`. Password on the command line is how the documented path works; a properties template sits at the repository root for keeping configuration elsewhere.
Reading structure only is what makes the report shareable
The confidentiality claim is structural rather than a promise about filtering. Since the analyzer reads only structural information, it works just as well on an empty database replica, which means the generated report can be handed to a third party for analysis without exposing rows. That is the argument for putting SchemaSpy in a pipeline: no data has to leave the environment where the replica already sits. The other two main use cases lean on the same read. Entity-relationship diagrams, which are the preferred form for documenting a data model, are normally hand drawn, slow, error prone, and out of date shortly after drawing; generating them in a CI or CD workflow makes staying current a property of the build rather than of someone's diligence. And the tool carries knowledge of database design practice, so it reports anomalies such as missing indexes, implied relationships, and orphan tables, with statistics on the shape of the schema that can be drilled into in the report or exported to Excel or CSV for QA work.
Two license files, a bower manifest, and a Lift config in the tree
The licensing is LGPL-3.0 and it is expressed twice in the repository, as `COPYING` and `COPYING.LESSER` at the root, which is the usual pairing for that license. Nothing in the project page explains which obligations attach to a report you generate versus the tool itself, so if you intend to publish generated documentation as part of a product rather than as an internal artifact, that is a question to answer before you rely on it. The tree also carries artifacts from several eras of tooling. There is a `bower.json`, the frontend package manager that has been largely superseded, and a `.lift.toml`, a configuration file for the Lift long-running process manager, neither of which is mentioned in the project page. A `snap/` directory sits alongside the Dockerfile and a `docker-bake.hcl` used to build images across platforms, and the documentation site is built from `docs/` through `.readthedocs.yaml` with the Maven wrapper committed as `mvnw` and `mvnw.cmd`. `CITATION.cff` and `TESTING.md` are there as well.
Editorial conclusion
Take SchemaSpy when you need browsable documentation of a schema you do not want to expose data from, since it reads structure only and works against an empty replica, and when a generated ER diagram in CI is an acceptable substitute for one a human drew. Check three things first. The download command on the project page still pins 6.2.4 while the newest release is 7.0.2, so copy the command and check the version rather than trusting both. The branch last moved on 2026-03-05 and the newest tag is v7.0.2 from 2025-09-20, so weigh an unreleased `snapshot` JAR against a gap of over a year in tagged releases. And note the license is LGPL-3.0 with two license files at the root, which matters if you intend to redistribute anything built with it.
Frequently asked questions
What is SchemaSpy?
A database metadata analyzer that helps administrators and developers visualize, navigate and understand a data model, producing an HTML-based report where traversing the entity-relationship diagram is the main activity. It is a standalone application with no GUI.
How do you install SchemaSpy?
Download the latest JAR file or Docker image. The page's curl example pins 6.2.4 with a comment telling you to replace it, the newest release is v7.0.2, and for unreleased work there is a snapshot JAR or the Docker tag `snapshot`.
How do you run SchemaSpy against a database?
Download the JDBC driver for your database, then run the jar with `-t` for the database type, `-dp` for the driver path, `-db`, `-host`, `-port`, `-u`, `-p`, and `-o` for the output directory. Use `-dbhelp` to list the over a dozen supported database types.
Is SchemaSpy open source?
Yes. It is licensed under LGPL-3.0, with both `COPYING` and `COPYING.LESSER` at the repository root, and the code, issue tracker, and CI workflow are all in the public repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/schemaspy-schemaspy)Star history chart for your README
[](https://hysenlabs.com/projects/schemaspy-schemaspy)Was this useful?