Huatuo-Llama-Med-Chinese: four base models, LoRA adapters, and a training set you cannot rebuild
Repo for BenCao [original name: HuaTuo], Instruction-tuning Large Language Models with Chinese Medical Knowledge.
At a glance
- What is it?
- The BenCao project publishes LoRA adapters and roughly eight thousand GPT-3.5 written medical question pairs for four Chinese capable base models, but the code that built the data is still unpublished.
- Who is it for?
- Adopt the adapters if you already hold LLaMA-7B, Bloom-7B, Alpaca-Chinese-7B or Huozi weights and want Chinese medical question answering that runs offline through peft 0.3.0. Skip it if you need an auditable training corpus, a knowledge retrieval stack, or any disease beyond liver cancer, because none of those ship in the repository.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 134 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
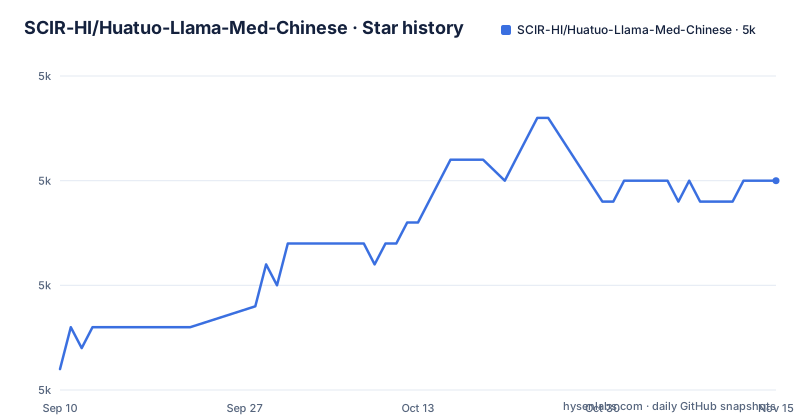
- SCIR-HI/Huatuo-Llama-Med-Chinese5,000 ★ · +9
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| SCIR-HI/Huatuo-Llama-Med-Chinese | 5k | 5k |
9 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four base models, two adapter files, no merged checkpoint
Every download expands to the same two files: adapter_config.json for the LoRA configuration and adapter_model.bin for the weights. That means the base model is yours to supply, and none of the four is bundled. The bases are Huozi 1.0 from Harbin Institute of Technology, developed on top of Bloom-7B; Bloom-7B; Alpaca-Chinese-7B; and LLaMA-7B. Each was tuned with half precision LoRA, described in the project as a trade-off between compute and model quality.
Weights arrive through Baidu netdisk links, and five of the six sets are mirrored on Hugging Face, which matters if your network cannot reach the Chinese host. The mirror coverage is uneven: the Huozi adapter is Baidu only. Two export scripts sit at the repository root, export_hf_checkpoint.py and export_state_dict_checkpoint.py, for anyone who would rather merge the adapter into a standalone checkpoint first. Nothing merged is published here, so the first run always needs two sets of weights on disk.
ChatGLM-6B-Med reuses the same data on a different base family
The same training data produced a second model line, ChatGLM-6B-Med, which lives in the separate SCIR-HI/Med-ChatGLM repository. The difference is the base family, not the data: this repository pairs its adapters with LLaMA, Bloom, Alpaca-Chinese and Huozi, while the medical ChatGLM sits on ChatGLM-6B.
That single difference decides most upgrade paths. A LoRA adapter is bound to the base it was trained against, so moving between the two lines means running bash ./scripts/finetune.sh again rather than reloading a file. Anyone already holding ChatGLM weights would read that as the cheaper start; anyone holding LLaMA-7B does not. The file layout at the repository root offers finetune.py and export scripts but no converter.
One requirements file, exact pins, and no torch line
Installation is a single pinned file, with Python 3.9 or newer suggested:
pip install -r requirements.txtThe pins are exact rather than floors, and a handful of them decide what a fine-tune produces:
accelerate==0.20.1
bitsandbytes==0.37.2
datasets==2.11.0
peft==0.3.0
transformers==4.30.1
sentencepiece==0.1.97
peft==0.3.0 and transformers==4.30.1 govern how the adapter is loaded, and bitsandbytes==0.37.2 is pinned alongside them. One entry is unpinned, wandb, and nothing in the file names torch or a CUDA build, so those two choices are yours. The remainder are development tools: black==23.3.0, black[jupyter]==23.3.0, gradio==3.33.1, scipy==1.10.1, appdirs==1.4.4 and fire==0.5.0. Installing into an environment that already carries a different transformers will not resolve cleanly, so a fresh virtualenv saves an afternoon.
infer.sh needs a prompt template chosen for the base model
Test cases sit in ./data/infer.json and can be replaced as long as the format holds. Three scripts cover the documented paths:
#基于医学知识库
bash ./scripts/infer.sh

#基于医学文献
#单轮
bash ./scripts/infer-literature-single.sh

#多轮
bash ./scripts/infer-literature-multi.sh
The knowledge base script hands off to infer.py, which takes four placeholder values you replace by hand:
python infer.py \
    --base_model 'BASE_MODEL_PATH' \
    --lora_weights 'LORA_WEIGHTS_PATH' \
    --use_lora True \
    --instruct_dir 'INFER_DATA_PATH' \
    --prompt_template 'TEMPLATE_PATH'
--prompt_template needs care, because the template is chosen per base model:
| 活字&Bloom | LLaMA&Alpaca | |:---|:---| | `templates/bloom_deploy.json` | 基于医学知识库`templates/med_template.json` <br> 基于医学文献`templates/literature_template.json` |
./scripts/test.sh, which the README also points to, is the fourth script worth reading.
Eight thousand pairs from GPT-3.5, and the builder code is still unpublished
The instruction training set runs to more than eight thousand pairs, generated by prompting the GPT-3.5 interface over a Chinese medical knowledge base that takes cMeKG as its main reference. Records hang off a centre term and carry fields for related diseases, symptoms, department, site of onset, complications, risk factors, histology, clinical symptoms, drug treatment and adjuvant therapy. One entry looks like this:
{"中心词": "偏头痛", "相关疾病": ["妊娠合并偏头痛", "恶寒发热"], "相关症状": ["皮肤变硬", "头部及眼后部疼痛并能听到连续不断的隆隆声", "晨起头痛加重"], "所属科室": ["中西医结合科", "内科"], "发病部位": ["头部"]}Several prompt forms were used to draw knowledge out of those records, and GPT-3.5 wrote the answers rather than a clinician. That provenance is the weakness to weigh. The project states that the pairs still contain errors and gaps, and that the knowledge base and dataset construction code are still being organised and have not been released. You can read the data and fine-tune on it; you cannot rebuild it or trace one answer back to the record behind it.
A second, thinner corpus exists for liver cancer: 1k multi-turn examples built from the conclusions of 2023 Chinese medical literature on that disease, offered at ./data_literature/liver_cancer.json, while the repository root lists a directory named data-literature. Check which path resolves before you build a loader around it.
Knowledge tuning inserts a lookup between question and answer
Ordinary instruction tuning in this project runs from knowledge to question and answer pairs: the knowledge base is flattened into supervised examples, and the adapter learns to answer straight from parameters. The knowledge tuning variant reverses the direction of the mapping. It trains the model to go from question to knowledge, and it adds a lookup at inference time across three stages. First, fill in the retrieval parameters for the question, which are the centre term and its attributes. Second, query the knowledge base with those filled parameters. Third, generate the answer from the knowledge that came back. A sample of that data sits at data/knowledge_tuning_data_sample.txt, and the method was accepted by ACM TKDD on 2024-07-25.
For a reader, the practical split is this: the published adapters answer from weights alone, while a knowledge-tuned adapter expects the retrieval stage wired in front of it. No retrieval module appears in the repository layout, so the three stages are a design you implement yourself before the model gains anything from them.
One A100 for 2h17m, and the 24GB estimate stays an estimate
The compute numbers come from the LLaMA run: one A100-SXM-80GB, 10 epochs, about 2 hours 17 minutes, with batch_size=128 sitting near 40G of memory. Cards with 24GB, named as the 3090 and 4090, are expected to work once batch_size comes down, and that expectation is a projection rather than a measurement. Two hours buys an adapter, not a model: the 7B base weights still have to be resident before the LoRA layers attach. Hyperparameters and the run itself are recorded on a wandb page the README links.
Nothing here is versioned. The repository has no GitHub releases, so no tag ties an adapter to a base revision, and the last push was on 2026-07-04. The published comparison table is older still, measured in March 2023 against Llama and Alpaca outputs, where LLaMA tends to echo the question back and the BenTsao column answers it. The repository is Apache-2.0.
Editorial conclusion
Adopt the adapters if you already hold LLaMA-7B, Bloom-7B, Alpaca-Chinese-7B or Huozi weights and want Chinese medical question answering that runs offline through peft 0.3.0. Skip it if you need an auditable training corpus, a knowledge retrieval stack, or any disease beyond liver cancer, because none of those ship in the repository. Before anything else, drop your own cases into ./data/infer.json and check that they parse: every adapter pairs with exactly one prompt template.
Frequently asked questions
Which base models do the Huatuo-Llama-Med-Chinese adapters cover?
Huozi 1.0, a Chinese general question answering model from Harbin Institute of Technology built on Bloom-7B, plus Bloom-7B, Alpaca-Chinese-7B and LLaMA-7B. Every one was instruction tuned with half precision LoRA, and the weights are published as adapter_config.json and adapter_model.bin rather than merged checkpoints.
Which prompt template does infer.py need for an Alpaca or LLaMA adapter?
templates/med_template.json when the adapter was trained on the medical knowledge base, and templates/literature_template.json for the literature adapters. Huozi and Bloom adapters use templates/bloom_deploy.json instead. The choice depends on the base model, so copy the path that matches your adapter.
Can I fine-tune BenCao on my own medical dataset?
Build your data in the format of ./data/llama_data.json, then run bash ./scripts/finetune.sh. The knowledge base and dataset construction code is still being organised, so the original eight thousand pairs cannot be regenerated from this repository.
How much GPU memory does fine-tuning the Huatuo adapters need?
The LLaMA fine-tune ran on one A100-SXM-80GB for 10 epochs in about 2h17m, with batch_size=128 using roughly 40G. Cards with 24GB, such as the 3090 and 4090, are expected to work after batch_size is lowered.
Does the literature branch of Huatuo-Llama-Med-Chinese cover more than liver cancer?
No. Only the liver cancer model parameters are released, with 1k training examples offered at ./data_literature/liver_cancer.json. Training for 16 diseases of the liver, gallbladder and pancreas is described as a plan for later.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/scir-hi-huatuo-llama-med-chinese)Star history chart for your README
[](https://hysenlabs.com/projects/scir-hi-huatuo-llama-med-chinese)Was this useful?